Die Microsoft AI-200 Zertifizierungsprüfung ist eine wichtige Microsoft Zertifizierungsprüfung. Aber es ist nicht einfach, die Microsoft AI-200 Zertifizierungsprüfung zu bestehen. Um den Druck der Kandidaten zu entlasten und Zeit und Energie zu ersparen hat Pass4Test viele Prüfungsmaterialien entwickelt. So können Sie im Pass4Test die geeignete und effziente Trainingsmethode wählen, um die AI-200 Prüfung zu bestehen.
| Section | Objectives |
|---|---|
| Develop AI solutions by using Azure data management services | - Work with Azure data platforms for AI workloads
|
| Connect to and consume Azure services | - Integrate Azure services
|
| Secure, monitor, troubleshoot Azure solutions | - Operate AI cloud solutions
|
| Develop containerized solutions on Azure | - Implement containerized applications
|
>> Microsoft AI-200 Ausbildungsressourcen <<
Bemühen Sie sich noch um die Microsoft AI-200 Zertifizierungsprüfung? Wollen Sie schneller Ihren Traum verwirklichen? Bitte wählen Sie die AI-200 Schulungsmaterialien von Pass4Test. Wenn Sie Pass4Test wählen, ist es kein Traum mehr, das Microsoft AI-200 Zertifikat zu erhalten.
63. Frage
Hotspot Question
You are building a semantic search feature for a chatbot. You store document embeddings in Redis.
You review the following Python code that connects to Redis and stores an embedding value: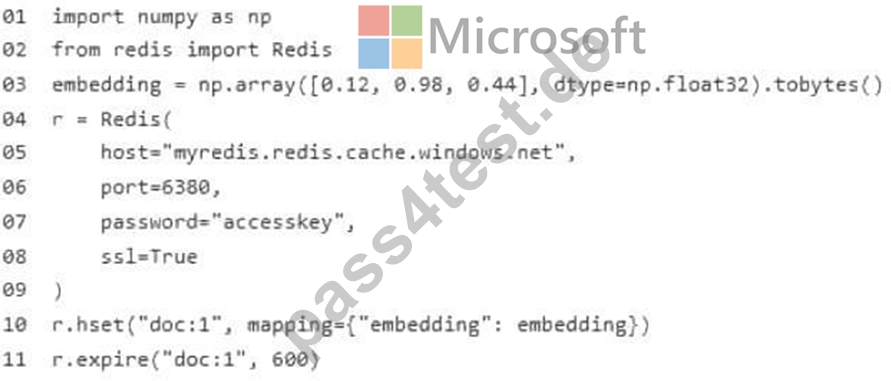
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.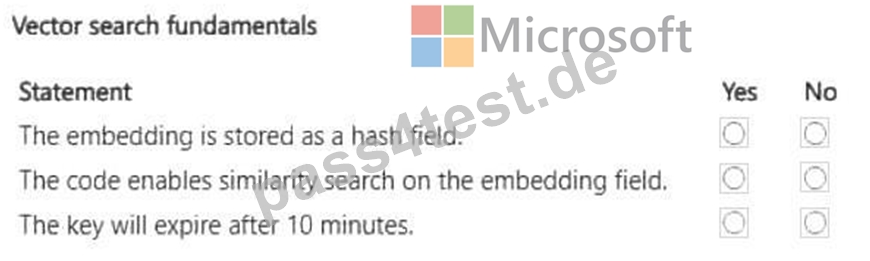
Antwort:
Begründung: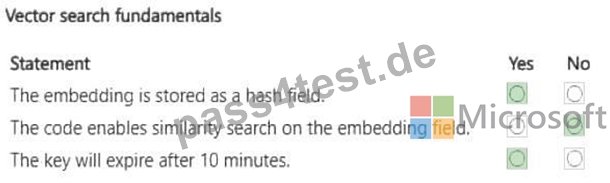
Explanation:
Box 1: Yes
The line r.hset("doc:1", mapping={"embedding": embedding}) will store the embedding as a field within a Redis Hash.
Box 2: No
Box 3: Yes
Reference:
https://redis.io/docs/latest/commands/expire/
64. Frage
You store embeddings in Redis by using keys formatted as doc:(id). Some embeddings are accessed frequently. Others are rarely used.
You need to implement a caching strategy that keeps only frequently accessed embeddings in memory.
What should you use?
Antwort: D
Begründung:
To implement this strategy, you should use allkeys-lru combined with the EXPIRE command as a secondary fallback.
Primary Mechanism: Configure your Redis maxmemory-policy to allkeys-lru.
Secondary Mechanism: Apply the EXPIRE command to your keys as a safety net.
Why allkeys-lru is the Best Choice
Memory Management: It automatically evicts the Least Recently Used (LRU) keys across your entire dataset when Redis hits its memory limit.
Frequent Access: It guarantees that frequently accessed embeddings stay in memory, regardless of when they were created.Prefix Independent: It scans all keys, making it perfect for your doc:(id) format Reference:
https://rahulchowdhury.in/blog/redis-caching-patterns-every-mern-dev
65. Frage
Case Study 2 - Proseware Inc.
Background
Proseware Inc. develops AI-powered knowledge management solutions for enterprise customers.
The company is modernizing its platform to support semantic search, intelligent document retrieval, and real-time partner integrations.
The engineering team uses Python and Azure SDKs. The architecture is being redesigned to support containerized microservices, vector search workloads, and serverless backend processing.
Planned Application Architecture
Microservices are containerized by using Docker.
Code for containerized microservices and Azure Function apps is developed locally but stored in a GitHub repository.
Custom images for containerized microservices are stored in Azure Container Registry (ACR).
Base images are stored in Docker Hub. Custom images must be rebuilt automatically whenever their base images are updated.
Azure Cosmos DB for NoSQL stores documents, metadata, and vector embeddings.
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Azure Container Apps (ACA) apps host backend API services that provide semantic search across Azure Cosmos DB for NoSQL documents. API services process Service Bus messages and update search indexes.
Azure Kubernetes Service (AKS) processes batch vector embedding regeneration for existing Azure Cosmos DB for NoSQL documents (whenever the embedding model is changed).
An extranet-facing containerized webhook allows business partners to submit documents to be processed by internal AI workflows for semantic search and retrieval.
Monitoring
Telemetry generated by Azure resources is sent to Azure Monitor.
A Log Analytics workspace is used to collect ACA apps logs, AKS container logs, and Azure Functions apps logs.
Monitoring of Azure Functions is currently implemented by using Azure Application Insights SDK instrumentation.
Business Requirements
Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Backend API services must scale automatically during business hours.
Cold start delay of backend APIs must be minimized.
Secrets must be stored outside of container images.
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Azure Cosmos DB for NoSQL RU consumption must be minimized.
Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
The partner-facing containerized webhook service must run on Azure App Service.
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
Azure App Service must supply secrets at runtime without relying on external services.
Resources and workloads must be deployed by using Bicep templates through an automated, version-controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Known Issues
RU consumption spikes during vector similarity queries.
Hotspot Question
You need to configure vector embedding updates according to the business and technical requirements.
Which configurations should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.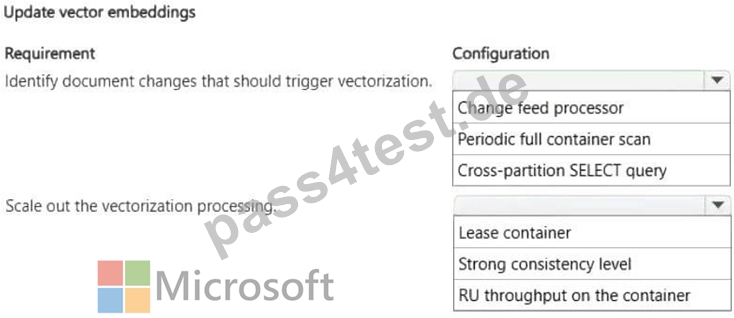
Antwort:
Begründung: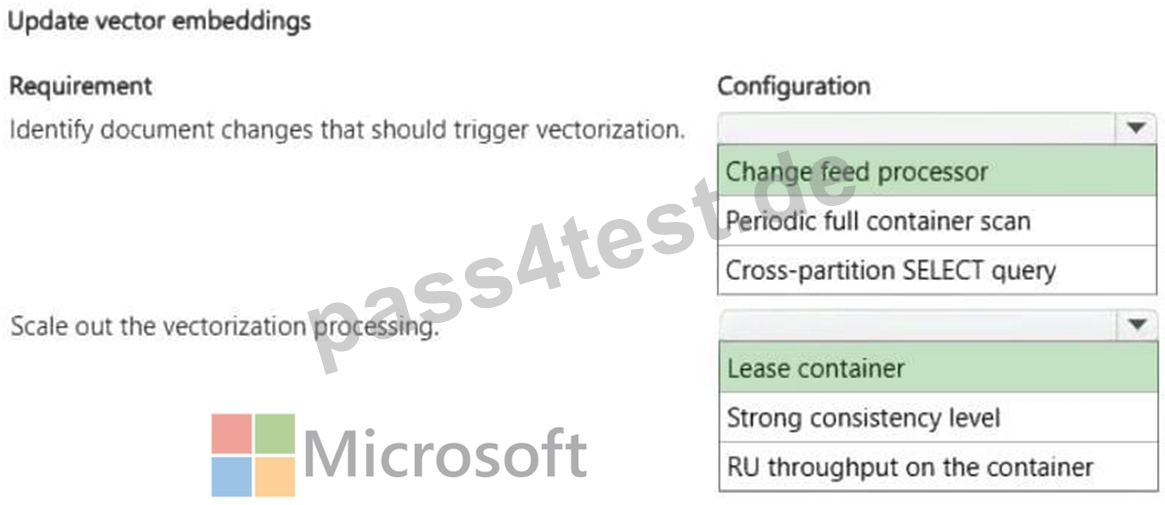
Explanation:
Business Requirements: Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Technical Requirements: Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
Box 1: Change feed processor
The Change feed processor is the correct component to configure for identifying document changes that should trigger vectorization.
This feature in Azure Cosmos DB provides a reliable, distributed, and scalable way to listen to a constant stream of changes (inserts and updates) within a container. It allows you to process these modifications in real-time, making it the perfect trigger for automated workflows like sending new text to an embedding model.
Box 2: Lease Container
The lease container is the component you configure to coordinate and horizontally scale out the change feed-driven vectorization processing across multiple workers or compute instances.
The Lease Container acts as state storage, tracks checkpoints, and distributes partition keys across parallel compute workers (such as Azure Functions or custom change feed processors) to scale out throughput processing safely without duplicate work.
Incorrect:
RU Throughput: Dictates the maximum performance limit, but provisioning RUs alone does not orchestrate or scale out multiple processing workers.
Consistency Level: Affects data replication guarantees and read/write ordering, not parallel processing distribution.
Reference:
https://blog.nashtechglobal.com/managing-record-changes-with-change-feed-in-azure-cosmos-db/
66. Frage
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure.
The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security.
The solution must meet strict performance, scalability, and security requirements.
Current environment
Application architecture
The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
Semantic retrieval uses metadata filtering combined with vector similarity search.
Azure Managed Redis is used as a caching layer.
Front-end and API workloads are deployed to Azure Container Apps (ACA).
Batch model retraining workloads run in Azure Kubernetes Service (AKS).
Container and CI/CD
Container images are stored in Azure Container Registry (ACR).
CI/CD uses ACR Tasks to build images on commit.
ACA environments support revision management.
AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring
Logs are collected in Azure Monitor.
Teams inspect container logs and Kubernetes events when troubleshooting.
Developers write KQL queries to analyze latency spikes.
Business requirements
Customer experience: Maintain a seamless, low-latency recommendation experience for end- users, even during unpredictable seasonal traffic spikes.
Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs.
Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction.
Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets.
Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers.
Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization.
Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates.
Identity: Use managed identities for all service-to-service and service-to-database authentication.
Plain-text credentials in configuration files are strictly prohibited.
Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy.
Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero.
CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
You need to configure image builds for a new service to meet the technical requirements.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Antwort: D,E
Begründung:
Technical requirements, CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
The two best actions to meet the requirements are to create and configure an ACR Task with a source repository context and then push updated code to the source repository.
The core constraint explicitly dictates using ACR Tasks to automate image builds triggered by source code commits.
[D] Create and configure an ACR Task with a source repository context: This step directly establishes the automation hook. By defining the repository context (such as GitHub or Azure Repos) during task creation, Azure Container Registry is instructed exactly where to watch for code modifications.
[F] Push updated code to the source repository: Once the ACR Task is configured with the source repository context, pushing new commits acts as the native trigger. ACR automatically intercepts the commit webhook, spins up a transient cloud agent, builds the Python container image via the Dockerfile, and pushes it directly into your registry.
Reference:
https://learn.microsoft.com/en-us/azure/container-registry/container-registry-tasks-overview
67. Frage
You have two Azure Container Registry (ACR) instances: ACR01 and ACR02.
You plan to implement a containerized application named APP1 that will use a base image named BASE1.
The image for APP1 will be stored in ACR01. The image BASE1 will be stored in ACR02.
You need to automate the planned implementation by using a sequence of five Azure command-line interface (Azure CLI) commands. Your solution must ensure that the APP1 image stored in ACR01 will be automatically updated when the BASE1 image is updated.
In which order should you arrange the commands to develop the solution? To answer, move all commands from the list of commands to the answer area and arrange them in the correct order.
NOTE: More than one order of answer choices is correct. You will receive credit for any of the correct orders you select.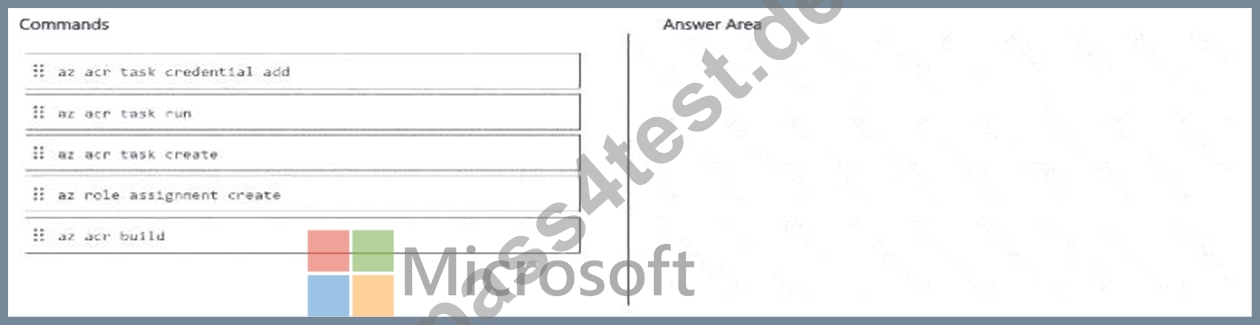
Antwort:
Begründung: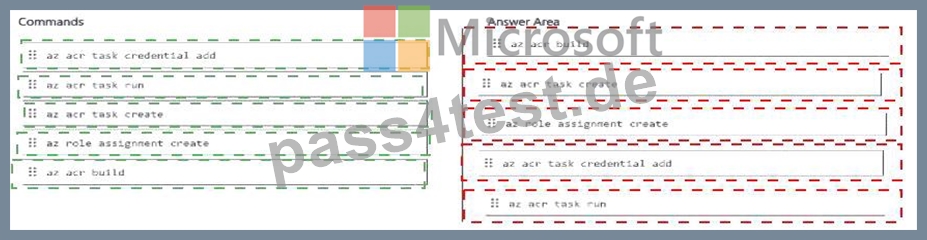
Explanation: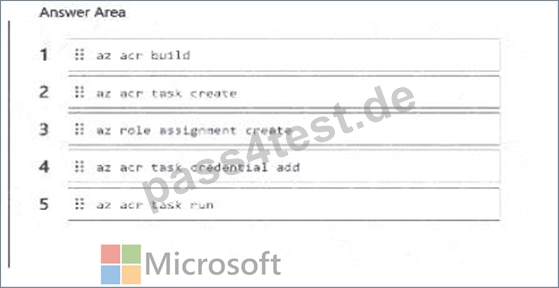
68. Frage
......
Die Microsoft AI-200 Prüfungsfragen und Antworten (AI-200) von Pass4Test ist eine Garantie für eine erfolgreiche Prüfung! Bisher fällt noch keiner unserer Kandidaten durch! Falls jemand bei der Zertifizierungsprüfung durchfallen sollte, zahlen wir 100% Material-Gebühr zurück. Wir übernehmen die volle Geld-zurück-Garantie auf Ihre Zertifizierungsprüfungen! Unsere AI-200 Fragen und Antoworten (Developing AI Cloud Solutions on Azure) sind aus dem Fragenpool, alle sind echt und original.
AI-200 German: https://www.pass4test.de/AI-200.html