지금21세기 IT업계가 주목 받고 있는 시대에 그 경쟁 또한 상상할만하죠, 당연히 it업계 중Microsoft AI-200인증시험도 아주 인기가 많은 시험입니다. 응시자는 매일매일 많아지고 있으며, 패스하는 분들은 관련it업계에서 많은 지식과 내공을 지닌 분들뿐입니다.
| Section | Objectives |
|---|---|
| Topic 1: Connect to and consume Azure services | - Integrate Azure services
|
| Topic 2: Develop AI solutions by using Azure data management services | - Work with Azure data platforms for AI workloads
|
| Topic 3: Secure, monitor, troubleshoot Azure solutions | - Operate AI cloud solutions
|
| Topic 4: Develop containerized solutions on Azure | - Implement containerized applications
|
Microsoft AI-200인증시험이 이토록 인기가 많으니 우리Fast2test에서는 모든 힘을 다하여 여러분이 응시에 도움을 드리겠으며 또 일년무료 업뎃서비스를 제공하며, Fast2test 선택으로 여러분은 자신의 꿈과 더 가까워질 수 있습니다. 희망찬 내일을 위하여 Fast2test선택은 정답입니다. Fast2test선택함으로 당신이 바로 진정한IT인사입니다.
질문 # 122
You are using Azure Monitor Application Insights to collect dependency data.
You must be able to:
* Correlate failed requests with dependency calls during the last hour.
* Calculate the average dependency duration per operation.
You need to construct the KQL query by using the minimum number of statements.
Which three operators should you use? Each correct answer presents part of the solution.
정답:A,C,D
설명:
Use where , join , and summarize .
The where operator filters telemetry to the required scope, including records from the last hour and failed requests. For example, a predicate can restrict timestamp > ago(1h) and request success status in the same filtering expression.
Next, use join to correlate request telemetry with dependency telemetry. Application Insights assigns related telemetry a common operation_Id , and Microsoft specifically demonstrates joining the dependencies and requests tables on operation_Id to identify dependency calls associated with requests.
Finally, use summarize with avg(duration) grouped by the appropriate operation identifier or operation name.
summarize performs aggregation over groups and is therefore the required operator for calculating average dependency duration. Microsoft documents dependency duration as supporting an Avg aggregation.
extend is unnecessary because no derived column is required, while distinct merely removes duplicate rows and cannot calculate averages or correlate two telemetry tables.
A representative structure is:
requests
| where timestamp > ago(1h) and success == false
| join (dependencies | where timestamp > ago(1h)) on operation_Id
| summarize avg_dependency_duration = avg(duration1) by operation_Name
Study Guide references: Azure Monitor Application Insights; KQL where; telemetry correlation using operation_Id; join; summarize; dependency duration analysis.
질문 # 123
You plan to deploy an Azure Container app.
You need to configure the container app to support session affinity.
Which ingress type and revision mode should you assign to the container app?
정답:C
설명:
HTTP ingress type and single revision mode must be assigned. Session affinity (sticky sessions) requires an HTTP-based proxy layer to track and route client requests to the same replica, which is incompatible with raw TCP ingress. Single revision mode ensures standard traffic flow without multi-revision splitting complexity.
Reference:
https://learn.microsoft.com/en-us/azure/container-apps/ingress-environment-configuration
질문 # 124
Hotspot Question
You are developing a Retrieval-Augmented Generation (RAG) solution for a company.
AI responses and embedding vectors are cached in Redis.
The solution must meet the following requirements:
- AI responses must expire exactly 24 hours after they are cached.
- Cached embeddings must always reflect the current source data.
You need to configure Redis to meet the requirements.
NOTE: Each correct selection is worth one point.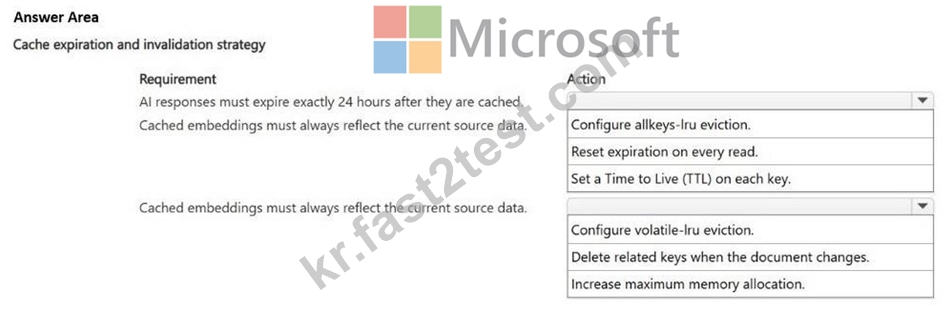
정답:
설명: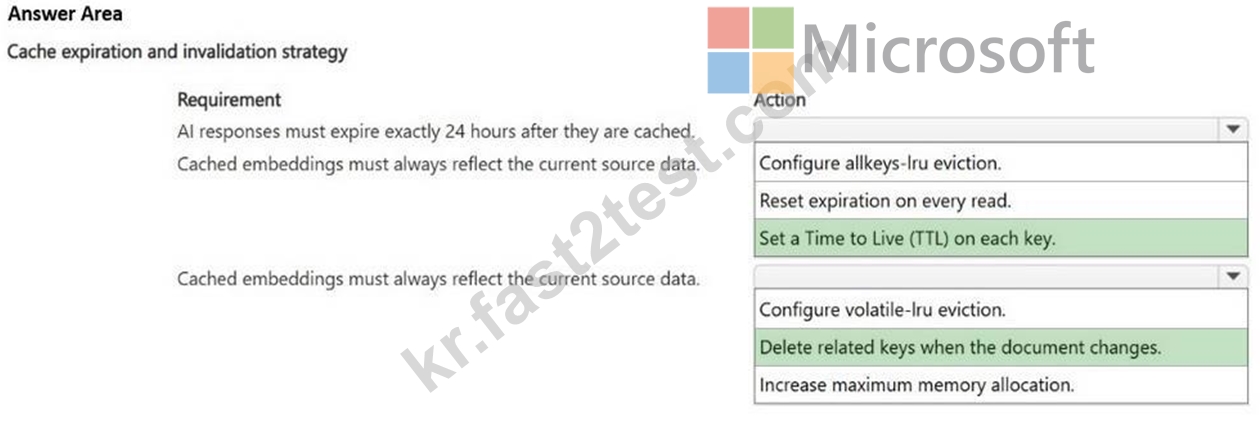
Explanation:
Box 1: Set a Time for Live (TTL) on each key.
To configure Redis to expire your AI responses exactly 24 hours after caching, you must apply a Time-To-Live (TTL) of 86,400 seconds to the specific keys holding those responses.
Box 2: Delete related keys when the document changes
You must invalidate or update those cached keys when source data changes to prevent your RAG system from retrieving stale information.
Incorrect:
Configuring allkeys-lru (Least Recently Used) is not recommended to ensure your cached embeddings or AI responses reflect current source data.allkeys-lru is an eviction policy. It only deletes data when Redis reaches its maximum memory limit, and it targets keys that haven't been accessed recently. It does not verify if the underlying source data has changed, meaning users will get dangerously outdated (hallucinated) AI responses if the source document is updated but the cached response remains in memory.
Reference:
https://zenvanriel.com/ai-engineer-blog/ai-caching-strategies/
질문 # 125
You need to troubleshoot connectivity failures between microservices running in AKS.
Which troubleshooting actions should you perform? To answer, move the appropriate action to the correct troubleshooting scenario. You may use each action once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.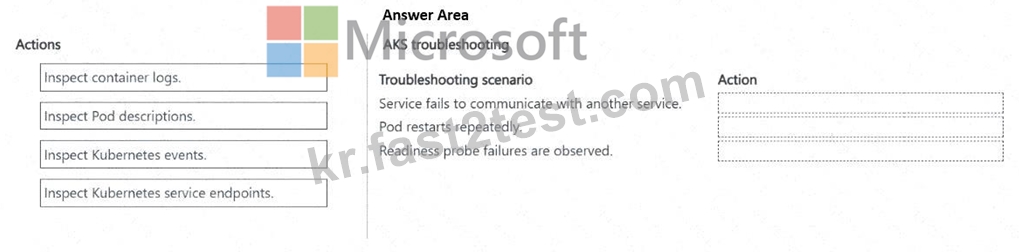
정답:
설명: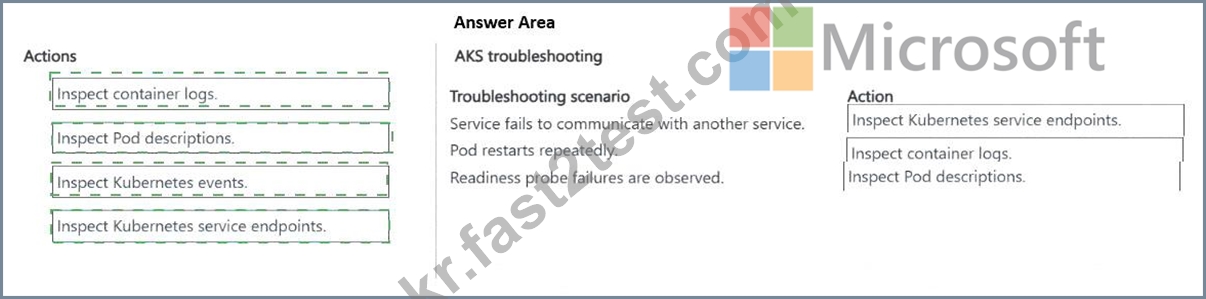
Explanation:
* Service fails to communicate with another service: Inspect Kubernetes service endpoints.
* Pod restarts repeatedly: Inspect container logs.
* Readiness probe failures are observed: Inspect Pod descriptions.
For a service-to-service communication failure , first inspect the Kubernetes service endpoints . Microsoft' s AKS troubleshooting guidance recommends verifying that the destination pod IP address and application port appear as endpoints for the Kubernetes Service. An empty or incorrect endpoint list commonly indicates a selector/label mismatch, incorrect port configuration, or unavailable backend pods.
For a pod that restarts repeatedly , inspect the container logs , including the previous container instance when necessary. Microsoft specifically recommends kubectl logs < pod > --previous for workloads that repeatedly restart because it exposes application errors and termination messages from the container immediately before the restart.
For readiness probe failures , inspect the Pod description by using kubectl describe pod. The description exposes the configured health probes, pod conditions, container state, and associated probe-failure events, allowing you to determine whether the probe path, port, timing, or application readiness behavior is incorrect.
Microsoft recommends reviewing kubectl describe output when pods are not Ready or health probes are failing.
Therefore, the correct mapping is service endpoints # container logs # Pod descriptions .
Study Guide references: AKS troubleshooting; Kubernetes Services and endpoints; container logging; Pod health; readiness/liveness probes; kubectl describe and kubectl logs.
질문 # 126
You are evaluating a fine-tuned Azure OpenAI model against the base model before promoting it to production.
Which Azure AI Foundry capability should you use?
정답:A
설명:
Use Azure AI Foundry evaluation with a representative evaluation dataset and quality metrics to compare the fine-tuned model against the base model before production promotion. Among the available options, this corresponds to Prompt flow bulk testing / evaluation . Foundry evaluation supports systematic testing of model or application outputs across many test records rather than relying on manual inspection of isolated prompts. Microsoft provides built-in evaluators including Groundedness, Coherence, Relevance, Fluency, and Response Completeness , allowing teams to quantify quality consistently across candidate implementations.
For a valid comparison, run the same representative dataset against both the base and fine-tuned deployments and compare the resulting evaluation metrics. This creates objective evidence about whether fine-tuning improves the targeted behavior without materially degrading relevance, coherence, grounding, or other required quality dimensions. Prompt flow evaluation workflows also support batch execution, per-record scores, and aggregated metrics for comparing variants.
Application Insights is essential for production telemetry such as latency, failures, and usage, but it is not by itself a model-quality comparison framework. Content Safety configuration evaluates or controls harmful content rather than comparative model quality. Azure AI Search indexer scheduling manages search-index ingestion and is unrelated to model evaluation.
Therefore, A is the correct capability.
Study Guide references: Microsoft Foundry # evaluations; evaluation datasets; bulk/batch testing; Groundedness; Coherence; Relevance; comparative model assessment.
질문 # 127
......
Fast2test의 Microsoft인증 AI-200덤프로 시험공부를 하신다면 고객님의 시간은 물론이고 거금을 들여 학원등록하지 않아도 되기에 금전상에서도 많은 절약을 해드리게 됩니다. Microsoft인증 AI-200덤프 구매의향이 있으시면 무료샘플을 우선 체험해보세요.
AI-200최신버전 시험공부: https://kr.fast2test.com/AI-200-premium-file.html