Certified-Data-Engineer-Professional Fragen & Antworten & Certified-Data-Engineer-Professional Studienführer & Certified-Data-Engineer-Professional Prüfungsvorbereitung

Certified-Data-Engineer-Professional ist eine der Databricks Zertifizierungsprüfungen. IT-Fachmann mit Databricks Zertifikat sind sehr beliebt in der IT-Branche. Deshalb legen imme mehr Leute die Certified-Data-Engineer-Professional Zertifizierungsprüfung. Jedoch ist es nicht so einfach, die Databricks Certified-Data-Engineer-Professional Zertifizierungsprüfung zu bestehen. Wenn Sie nicht an den entprechenden Kursen teilnehmen, brauchen Sie viel Zeit und Energie, sich auf die Prüfung vorzubereiten. Nun kann EchteFrage Ihnen viel Zeit und Energie ersparen.
Databricks Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Topic 1: Debugging and Deploying | - Debugging and Troubleshooting
- 1. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 2. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 3. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
|
| Topic 2: Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
| Topic 3: Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Implement compliant batch and streaming pipelines that detect and mask PII
- 2. Develop data purging solutions that comply with data retention policies
- Applying Data Security Mechanisms
- 1. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 2. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 3. Use row filters and column masks to protect sensitive table data
|
| Topic 4: Developing Code for Data Processing using Python and SQL | - Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 2. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 3. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 4. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 5. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 6. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 7. Create pipeline components using control flow operators such as if/else and foreach
- 8. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- Using Python and Tools for Development
- 1. Develop User-Defined Functions using Pandas/Python UDF
- 2. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 3. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
|
| Topic 5: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
| Topic 6: Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
| Topic 7: Data Modeling | - Design and optimize data models
- 1. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 2. Design dimensional models for analytical workloads with efficient querying and aggregation
- 3. Design and implement scalable data models using Delta Lake to manage large datasets
- 4. Simplify data layout decisions and optimize query performance using liquid clustering
|
| Topic 8: Data Sharing and Federation | - Share and federate data
- 1. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 2. Configure Lakehouse Federation with appropriate governance across supported source systems
- 3. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
|
| Topic 9: Monitoring and Alerting | - Alerting
- 1. Use SQL Alerts to monitor data quality
- 2. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- Monitoring
- 1. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 2. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 3. Use Query Profile and Spark UI to monitor workloads
- 4. Use system tables for observability of resource utilization, cost, auditing, and workloads
|
| Topic 10: Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 2. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 3. Apply Change Data Feed to address streaming table limitations and improve latency
- 4. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 5. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
|
>> Certified-Data-Engineer-Professional Zertifizierungsprüfung <<
Certified-Data-Engineer-Professional Testfagen, Certified-Data-Engineer-Professional Simulationsfragen
Es gibt viele Methoden, die Databricks Certified-Data-Engineer-Professional Zertifizierungsprüfung zu bestehen. Einerseits kann man viel Zeit und Energie auf die Databricks Certified-Data-Engineer-Professional Zertifizierungsprüfung aufwenden, um die Fachkenntnisse zu konsolidieren. Andererseits kann man mit weniger Zeit und Geld die zielgerichteten Databricks Certified-Data-Engineer-Professional Prüfungsfragen von EchteFrage benutzen.
Databricks Certified Data Engineer Professional Certified-Data-Engineer-Professional Prüfungsfragen mit Lösungen (Q134-Q139):
134. Frage
Which statement describes integration testing?
- A. Validates behavior of individual elements of your application
- B. Validates interactions between subsystems of your application
- C. Validates an application use case
- D. Requires an automated testing framework
- E. Requires manual intervention
Antwort: B
Begründung:
Integration testing is a type of software testing where components of the software are gradually integrated and then tested as a unified group.
135. Frage
The data engineering team maintains the following code:
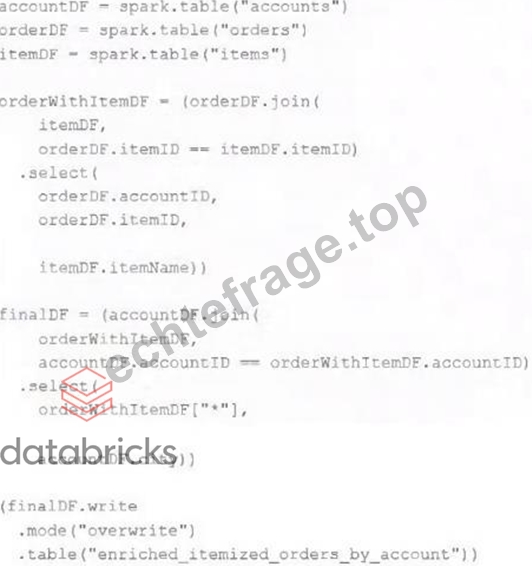
Assuming that this code produces logically correct results and the data in the source tables has been de-duplicated and validated, which statement describes what will occur when this code is executed?
- A. No computation will occur until enriched_itemized_orders_by_account is queried; upon query materialization, results will be calculated using the current valid version of data in each of the three tables referenced in the join logic.
- B. An incremental job will detect if new rows have been written to any of the source tables; if new rows are detected, all results will be recalculated and used to overwrite the enriched_itemized_orders_by_account table.
- C. The enriched_itemized_orders_by_account table will be overwritten using the current valid version of data in each of the three tables referenced in the join logic.
- D. A batch job will update the enriched_itemized_orders_by_account table, replacing only those rows that have different values than the current version of the table, using accountID as the primary key.
- E. An incremental job will leverage information in the state store to identify unjoined rows in the source tables and write these rows to the enriched_iteinized_orders_by_account table.
Antwort: C
Begründung:
This is the correct answer because it describes what will occur when this code is executed. The code uses three Delta Lake tables as input sources: accounts, orders, and order_items. These tables are joined together using SQL queries to create a view called new_enriched_itemized_orders_by_account, which contains information about each order item and its associated account details. Then, the code uses write.format("delta").mode("overwrite") to overwrite a target table called enriched_itemized_orders_by_account using the data from the view. This means that every time this code is executed, it will replace all existing data in the target table with new data based on the current valid version of data in each of the three input tables.
136. Frage
A data engineer is using Structured Streaming to read in transaction data from a bronze Delta table. It was discovered that the data has quality issues where sometimes the transaction value is negative, and when that occurs, the rows need to be routed to a separate quarantine table. They have low latency requirements for the good data since it is used by downstream systems, but the bad data will only be analyzed periodically and has no production dependencies. The quarantine job needs to be implemented so that it cannot affect the production processes that depend on the good data, and the cost of the job needs to be minimized. How should the quarantine process be implemented in order to satisfy these requirements?
- A. The existing streaming job for the good data should be updated to incorporate the quarantining of the bad data. Inside a foreachBatch function, the dataframe should be filtered so that records with a transaction value greater than or equal to 0 are written to the good data table and records with a transaction value less than 0 are written to a quarantine table. Try/Catch can be added around the writes in the foreachBatch function so that the stream can't fail.
- B. The streaming job for the good data needs to be modified to filter out records with a transaction value less than 0 before writing, and should not share compute with other processes. The streaming job for the quarantine data needs to filter out records with a transaction value greater than or equal to 0 before writing, and should be implemented on a separate small cluster and only run once a day to minimize cost.
- C. The streaming job for the good data needs to be modified to filter out records with a transaction value less than 0 before writing. The streaming job for the quarantine data needs to filter out records with a transaction value greater than or equal to 0 before writing. Both should run as separate streams on the same cluster to minimize cost.
- D. The existing streaming job for the good data should be updated to incorporate the quarantining of the bad data. A new boolean column called "quarantine" should be added to the dataframe, and its value should be set to true if the transaction value is less than 0 and false if the transaction value is greater than or equal to 0. Processing and storing all the data together will save costs.
Antwort: B
Begründung:
Separating the quarantine processing from the low-latency production stream ensures the good- data pipeline cannot be slowed down or destabilized by quarantine writes or failures. Filtering out negative values in the production stream preserves latency and reliability for downstream systems. Running the quarantine stream on a small, independent cluster on a daily schedule minimizes cost while still capturing the bad records for periodic analysis, and it fully isolates quarantine operations from production dependencies.
137. Frage
A production cluster has 3 executor nodes and uses the same virtual machine type for the driver and executor.
When evaluating the Ganglia Metrics for this cluster, which indicator would signal a bottleneck caused by code executing on the driver?
- A. Network I/O never spikes
- B. Bytes Received never exceeds 80 million bytes per second
- C. Overall cluster CPU utilization is around 25%
- D. Total Disk Space remains constant
- E. The five Minute Load Average remains consistent/flat
Antwort: C
Begründung:
This is the correct answer because it indicates a bottleneck caused by code executing on the driver. A bottleneck is a situation where the performance or capacity of a system is limited by a single component or resource. A bottleneck can cause slow execution, high latency, or low throughput. A production cluster has 3 executor nodes and uses the same virtual machine type for the driver and executor. When evaluating the Ganglia Metrics for this cluster, one can look for indicators that show how the cluster resources are being utilized, such as CPU, memory, disk, or network. If the overall cluster CPU utilization is around 25%, it means that only one out of the four nodes (driver + 3 executors) is using its full CPU capacity, while the other three nodes are idle or underutilized. This suggests that the code executing on the driver is taking too long or consuming too much CPU resources, preventing the executors from receiving tasks or data to process. This can happen when the code has driver-side operations that are not parallelized or distributed, such as collecting large amounts of data to the driver, performing complex calculations on the driver, or using non-Spark libraries on the driver.
138. Frage
The marketing team is looking to share data in an aggregate table with the sales organization, but the field names used by the teams do not match, and a number of marketing specific fields have not been approval for the sales org.
Which of the following solutions addresses the situation while emphasizing simplicity?
- A. Use a CTAS statement to create a derivative table from the marketing table configure a production jon to propagation changes.
- B. Create a view on the marketing table selecting only these fields approved for the sales team alias the names of any fields that should be standardized to the sales naming conventions.
- C. Add a parallel table write to the current production pipeline, updating a new sales table that varies as required from marketing table.
- D. Create a new table with the required schema and use Delta Lake's DEEP CLONE functionality to sync up changes committed to one table to the corresponding table.
- E. Instruct the marketing team to download results as a CSV and email them to the sales organization.
Antwort: B
Begründung:
Creating a view is a straightforward solution that can address the need for field name standardization and selective field sharing between departments. A view allows for presenting a transformed version of the underlying data without duplicating it. In this scenario, the view would only include the approved fields for the sales team and rename any fields as per their naming conventions.
139. Frage
......
Wir EchteFrage Team versteht völlig, dass das Vertrauen zwischen die Verkäufer und die Kunden nicht leicht zu erstellen ist. Wir präsentieren Sie die Fachlichkeit und hohe Effizienz mit Databricks Certified-Data-Engineer-Professional Prüfungssoftware, die von unserer Herzlichkeit erfüllt ist. Wir helfen Ihnen mit umfassenden Prüfungsaufgaben und ausführlichen Analysen, die Databricks Certified-Data-Engineer-Professional Prüfung zu bestehen. Wir bieten Sie die freundlichsten Kundendienst, um Ihre Vertrauen zu erwerben. Und das Zertifikat der Databricks Certified-Data-Engineer-Professional, das Sie erwerben, ist die beste Anerkennung für uns.
Certified-Data-Engineer-Professional Testfagen: https://www.echtefrage.top/Certified-Data-Engineer-Professional-deutsch-pruefungen.html
- Certified-Data-Engineer-Professional Fragen Und Antworten 🤏 Certified-Data-Engineer-Professional Fragenkatalog 🐧 Certified-Data-Engineer-Professional Tests 🤖 Sie müssen nur zu “ www.itzert.com ” gehen um nach kostenloser Download von “ Certified-Data-Engineer-Professional ” zu suchen 🏨Certified-Data-Engineer-Professional Übungsmaterialien
- Kostenlos Certified-Data-Engineer-Professional dumps torrent - Databricks Certified-Data-Engineer-Professional Prüfung prep - Certified-Data-Engineer-Professional examcollection braindumps 💓 Suchen Sie jetzt auf ➽ www.itzert.com 🢪 nach ⏩ Certified-Data-Engineer-Professional ⏪ um den kostenlosen Download zu erhalten 🐜Certified-Data-Engineer-Professional Online Prüfungen
- Certified-Data-Engineer-Professional Lernhilfe 😭 Certified-Data-Engineer-Professional Fragenkatalog ⏮ Certified-Data-Engineer-Professional Testengine ⏭ Erhalten Sie den kostenlosen Download von 【 Certified-Data-Engineer-Professional 】 mühelos über 【 www.zertsoft.com 】 💸Certified-Data-Engineer-Professional Prüfungen
- Certified-Data-Engineer-Professional Deutsche Prüfungsfragen 🔗 Certified-Data-Engineer-Professional Fragenkatalog 🦗 Certified-Data-Engineer-Professional Deutsche Prüfungsfragen 🏟 Öffnen Sie ➥ www.itzert.com 🡄 geben Sie { Certified-Data-Engineer-Professional } ein und erhalten Sie den kostenlosen Download 🤙Certified-Data-Engineer-Professional Übungsmaterialien
- Certified-Data-Engineer-Professional Musterprüfungsfragen 🌯 Certified-Data-Engineer-Professional Prüfungs-Guide 🌆 Certified-Data-Engineer-Professional Musterprüfungsfragen 🪒 Öffnen Sie die Website ⏩ www.echtefrage.top ⏪ Suchen Sie 「 Certified-Data-Engineer-Professional 」 Kostenloser Download 🍡Certified-Data-Engineer-Professional Exam
- Certified-Data-Engineer-Professional Prüfungsfragen Prüfungsvorbereitungen, Certified-Data-Engineer-Professional Fragen und Antworten, Databricks Certified Data Engineer Professional 🕚 URL kopieren ( www.itzert.com ) Öffnen und suchen Sie ➠ Certified-Data-Engineer-Professional 🠰 Kostenloser Download 🌝Certified-Data-Engineer-Professional Prüfungsvorbereitung
- Certified-Data-Engineer-Professional Fragenkatalog 👓 Certified-Data-Engineer-Professional Tests 🚼 Certified-Data-Engineer-Professional Exam 🧷 Geben Sie 【 www.pruefungfrage.de 】 ein und suchen Sie nach kostenloser Download von 「 Certified-Data-Engineer-Professional 」 ☔Certified-Data-Engineer-Professional Online Tests
- Certified-Data-Engineer-Professional Lernressourcen 🚅 Certified-Data-Engineer-Professional Musterprüfungsfragen 🍯 Certified-Data-Engineer-Professional Lernhilfe 🏤 Öffnen Sie die Webseite ➤ www.itzert.com ⮘ und suchen Sie nach kostenloser Download von ▶ Certified-Data-Engineer-Professional ◀ 🚋Certified-Data-Engineer-Professional Prüfungsvorbereitung
- Certified-Data-Engineer-Professional Aktuelle Prüfung - Certified-Data-Engineer-Professional Prüfungsguide - Certified-Data-Engineer-Professional Praxisprüfung 🚎 Sie müssen nur zu “ www.itzert.com ” gehen um nach kostenloser Download von 「 Certified-Data-Engineer-Professional 」 zu suchen 🤪Certified-Data-Engineer-Professional Prüfungsvorbereitung
- Certified-Data-Engineer-Professional Fragen Und Antworten 🕰 Certified-Data-Engineer-Professional Prüfungen 🌶 Certified-Data-Engineer-Professional Fragenkatalog 👑 URL kopieren { www.itzert.com } Öffnen und suchen Sie 《 Certified-Data-Engineer-Professional 》 Kostenloser Download 😴Certified-Data-Engineer-Professional Testengine
- Certified-Data-Engineer-Professional Fragenpool 🏹 Certified-Data-Engineer-Professional Exam 🧢 Certified-Data-Engineer-Professional Fragen Und Antworten 🤛 Suchen Sie jetzt auf ▛ www.itzert.com ▟ nach ➥ Certified-Data-Engineer-Professional 🡄 um den kostenlosen Download zu erhalten 👍Certified-Data-Engineer-Professional Übungsmaterialien
- www.stes.tyc.edu.tw, learn.csisafety.com.au, www.stes.tyc.edu.tw, telegra.ph, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes