よくできたDEA-C01復習攻略問題 &資格試験のリーダープロバイダー &無料PDFDEA-C01日本語試験情報

P.S. JPNTestがGoogle Driveで共有している無料かつ新しいDEA-C01ダンプ:https://drive.google.com/open?id=1ixG3FUgV3TQ_7iTZxAKbxOm28eYo0i7e
DEA-C01トレーニングテストの購入は複雑ではありません。Snowflake主に4つのステップがあります。最初に、必要に応じて対応するバージョンを選択できます。 次に、正しいメールアドレスを入力する必要があります。 また、その後のリリースでユーザーがメールを変更した場合は、JPNTestメールを更新する必要があります。 次に、ユーザーは購入するためにDEA-C01学習教材の支払いページに入る必要があります。 最後に、支払いから10分以内に、システムは自動的にSnowPro Advanced: Data Engineer Certification ExamのDEA-C01学習資料をユーザーのメールアドレスに送信します。 そして、すぐにDEA-C01試験に合格して合格することができます。
Snowflake DEA-C01 Exam Syllabus Topics:
| Section | Objectives |
|---|
| Data Pipelines and Transformation | - ETL/ELT design patterns in Snowflake
- 1. Data orchestration concepts
- 2. Staging and transformation layers
- Streams and Tasks
- 1. Change Data Capture (CDC) with Streams
- 2. Automating pipelines with Tasks
|
| Data Loading and Integration | - Bulk data loading
- 1. COPY INTO command usage
- 2. File format handling
- Snowpipe and continuous ingestion
- 1. Event-driven loading
- 2. Automated ingestion workflows
|
| Data Engineering Fundamentals on Snowflake | - Data ingestion concepts
- 1. Batch loading strategies
- 2. Continuous ingestion concepts
- Snowflake architecture for data engineering
- 1. Storage and compute separation
- 2. Virtual warehouses and compute scaling
|
| Semi-Structured and Advanced Data Handling | - Advanced transformation techniques
- 1. Complex transformations in SQL
- 2. Flattening nested data
- Semi-structured data processing
- 1. JSON, Avro, Parquet handling
- 2. VARIANT data type usage
|
| Performance Optimization | - Query performance tuning
- 1. Clustering and micro-partitions
- 2. Caching mechanisms
- Warehouse optimization
- 1. Scaling strategies
- 2. Concurrency management
|
| Security, Governance, and Data Sharing | - Access control
- 1. Object-level permissions
- 2. Role-based access control (RBAC)
- Data governance
- 1. Secure data sharing concepts
- 2. Data masking policies
|
>> DEA-C01復習攻略問題 <<
100%合格率DEA-C01復習攻略問題試験-試験の準備方法-最高のDEA-C01日本語試験情報
SnowflakeのDEA-C01試験トレントの指示に従って、準備期間を非常に短い時間で完了し、試験に合格することもできます。これにより、多くの時間とエネルギーを節約し、SnowPro Advanced: Data Engineer Certification Exam準備トレントで生産性を高めることができます。 実際、あなたが進歩するための高効率な準備時間を保証する理由は、主に、当社JPNTestのDEA-C01テストで学習プロセス中に顧客を集中させ、ターゲットを絞ることができるコンテンツとレイアウトの素晴らしい組織に起因します ブレインダンプ。 DEA-C01のSnowPro Advanced: Data Engineer Certification Exam試験準備の高い合格率は99%〜100%です。
Snowflake SnowPro Advanced: Data Engineer Certification Exam 認定 DEA-C01 試験問題 (Q222-Q227):
質問 # 222
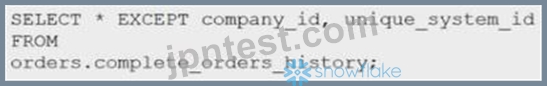
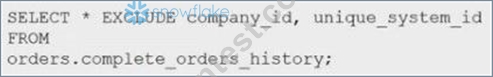
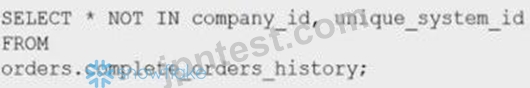
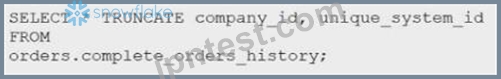
A company uses Amazon Redshift for its data warehouse. A data engineer must query a table named orders.complete_orders_history, which contains 100 columns. The query must return all columns except columns named companyId and unique_system_id. Which Amazon Redshift SQL statement will meet this requirement?
正解:B
解説:
Amazon Redshift supports the SELECT * EXCLUDE syntax, which allows returning all columns from a table except the specified ones. This is the most efficient and direct way to exclude specific columns like company_id and unique_system_id without listing all remaining columns.
質問 # 223
A media company uploads large video files to Amazon S3 for processing. After processing, the company needs to keep the original files for 90 days in case the files require reprocessing. After
90 days, the company can delete the files to reduce storage costs. The company stores the processed videos in a different S3 bucket. Which S3 Lifecycle configuration will meet these requirements for the original files MOST cost-effectively?
- A. Store the files in S3 Standard for 90 days. Transition the files to S3 Glacier Flexible Retrieval for long-term storage. Then expire the files.
- B. Store the files in S3 Intelligent-Tiering for 90 days. Enable versioning. Add S3 Lifecycle management to expire the files.
- C. Store the files in S3 Standard for 90 days. Implement S3 Lifecycle management to expire the files.
- D. Store the files in S3 Standard for 90 days. Enable versioning. Enable Object Lock on the files for
90 days. Then expire the files.
正解:C
解説:
Keeping the files in S3 Standard for 90 days and using an S3 Lifecycle expiration rule is the most cost-effective option among the choices because the objects only need to be retained for 90 days and then deleted. Adding Glacier Flexible Retrieval would introduce archival and restore behavior intended for longer-term storage, and AWS notes that S3 Glacier Flexible Retrieval is a long-term archival class with a 90-day minimum storage duration. S3 Intelligent-Tiering also adds monitoring and automation charges, and Object Lock/versioning add unnecessary cost and controls beyond the stated requirement.
Reference:
https://docs.aws.amazon.com/AmazonS3/latest/userguide/glacier-storage-classes.html
https://docs.aws.amazon.com/AmazonS3/latest/userguide/lifecycle-expire-general- considerations.html
https://docs.aws.amazon.com/AmazonS3/latest/userguide/intelligent-tiering.html
質問 # 224
Assuming that the session parameter USE_CACHED_RESULT is set to false, what are characteristics of Snowflake virtual warehouses in terms of the use of Snowpark?
- A. Creating a DataFrame from a staged file with the read () method will start a virtual warehouse
- B. Calling a Snowpark stored procedure to query the database with session, call () will start a virtual warehouse
- C. Creating a DataFrame from a table will start a virtual warehouse
- D. Transforming a DataFrame with methods like replace () will start a virtual warehouse -
正解:C
解説:
Explanation
Creating a DataFrame from a table will start a virtual warehouse because it requires reading data from Snowflake. The other options will not start a virtual warehouse because they either operate on local data or use an existing session to query Snowflake.
質問 # 225
A company stores employee data in Amazon Resdshift. A table names Employee uses columns named Region ID, Department ID, and Role ID as a compound sort key.
Which queries will MOST increase the speed of query by using a compound sort key of the table?
(Choose two.)
- A. Select *from Employee where Department ID=20 and Region ID='North America';
- B. Select *from Employee where Region ID='North America';
- C. Select *from Employee where Region ID='North America' and Role ID=50;
- D. Select *from Employee where Region ID='North America' and Department ID=20;
- E. Select *from Employee where Role ID=50;
正解:C、D
解説:
To maximize the speed of queries by using the compound sort key (Region ID, Department ID, and Role ID) in the Employee table in Amazon Redshift, the queries should align with the order of the columns in the sort key.
質問 # 226
When using the CURRENT_ROLE and CURRENT_USER functions with secure UDFs that will be shared with Snowflake accounts, Snowflake returns a NULL value for these functions?
正解:A
解説:
Explanation
When using the CURRENT_ROLE and CURRENT_USER functions with secure UDFs that will be shared with Snowflake accounts, Snowflake returns a NULL value for these functions. The rea-son is that the owner of the data being shared does not typically control the users or roles in the ac-count with which the UDF is being shared.
質問 # 227
......
時代に対応するために、科学技術は人々の学習方法を向上させると信じています。特にこのようなペースの速い生活テンポでは、効率の高い学習を非常に重視しています。したがって、当社のDEA-C01学習資料は、過去の試験問題と現在の試験の傾向に基づいており、実際の試験環境に配置するためのこのような効果的なシミュレーション機能を設計します。高度なDEA-C01学習教材を備えた高品質のシミュレーションシステムを提供することをお約束します。シミュレーション機能により、DEA-C01トレーニングガイドの理解が容易になり、DEA-C01試験に合格できます。
DEA-C01日本語試験情報: https://www.jpntest.com/shiken/DEA-C01-mondaishu
- DEA-C01資格認証攻略 😿 DEA-C01関連受験参考書 🤯 DEA-C01合格記 🐄 ➡ www.mogiexam.com ️⬅️から簡単に➠ DEA-C01 🠰を無料でダウンロードできますDEA-C01学習教材
- DEA-C01関連試験 ➡ DEA-C01関連受験参考書 🤪 DEA-C01的中率 🔦 [ www.goshiken.com ]から簡単に( DEA-C01 )を無料でダウンロードできますDEA-C01専門トレーリング
- 完璧なSnowflake DEA-C01復習攻略問題 は主要材料 - 信頼できるDEA-C01日本語試験情報 🥂 ⇛ www.mogiexam.com ⇚に移動し、【 DEA-C01 】を検索して無料でダウンロードしてくださいDEA-C01ブロンズ教材
- DEA-C01認定試験 🍍 DEA-C01学習教材 😤 DEA-C01日本語版サンプル 🏹 最新( DEA-C01 )問題集ファイルは“ www.goshiken.com ”にて検索DEA-C01日本語版参考書
- 完璧なSnowflake DEA-C01復習攻略問題 は主要材料 - 信頼できるDEA-C01日本語試験情報 ❕ ウェブサイト➠ www.goshiken.com 🠰から▶ DEA-C01 ◀を開いて検索し、無料でダウンロードしてくださいDEA-C01日本語試験情報
- 正確的なDEA-C01復習攻略問題試験-試験の準備方法-高品質なDEA-C01日本語試験情報 🤔 【 www.goshiken.com 】の無料ダウンロード▷ DEA-C01 ◁ページが開きますDEA-C01関連試験
- 試験の準備方法-実際的なDEA-C01復習攻略問題試験-最新のDEA-C01日本語試験情報 🐙 《 www.jpshiken.com 》に移動し、⮆ DEA-C01 ⮄を検索して無料でダウンロードしてくださいDEA-C01資格認証攻略
- 試験の準備方法-実際的なDEA-C01復習攻略問題試験-最新のDEA-C01日本語試験情報 💯 ☀ www.goshiken.com ️☀️で➽ DEA-C01 🢪を検索して、無料で簡単にダウンロードできますDEA-C01関連試験
- 権威のあるDEA-C01復習攻略問題試験-試験の準備方法-有効的なDEA-C01日本語試験情報 🐈 ⮆ DEA-C01 ⮄を無料でダウンロード➠ www.goshiken.com 🠰ウェブサイトを入力するだけDEA-C01合格記
- 最新のDEA-C01復習攻略問題 - 資格試験のリーダー - 無料ダウンロードSnowflake SnowPro Advanced: Data Engineer Certification Exam 💈 ✔ www.goshiken.com ️✔️を開き、“ DEA-C01 ”を入力して、無料でダウンロードしてくださいDEA-C01模擬トレーリング
- DEA-C01日本語関連対策 🥾 DEA-C01日本語試験情報 🍔 DEA-C01資格認証攻略 🧢 時間限定無料で使える▛ DEA-C01 ▟の試験問題は➠ www.mogiexam.com 🠰サイトで検索DEA-C01合格記
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
BONUS!!! JPNTest DEA-C01ダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1ixG3FUgV3TQ_7iTZxAKbxOm28eYo0i7e