In order to provide a convenient study method for all people, our company has designed the online engine of the Databricks-Certified-Professional-Data-Engineer study materials. The online engine is very convenient and suitable for all people to study, and you do not need to download and install any APP. We believe that the Databricks-Certified-Professional-Data-Engineer study materials from our company will help all customers save a lot of installation troubles. You just need to have a browser on your device you can use our study materials. We can promise that the Databricks-Certified-Professional-Data-Engineer Study Materials from our company will help you prepare for your exam well.
| Section | Objectives |
|---|---|
| Topic 1: Security, Governance, Monitoring, and Optimization | - Cost optimization and performance tuning - Implement Unity Catalog governance and access control - Monitor and optimize Spark workloads |
| Topic 2: Production Pipelines and Orchestration | - Build and manage workflows using Databricks Jobs - Pipeline reliability and fault tolerance - Automate ETL pipelines and scheduling |
| Topic 3: Data Modeling and Storage | - Schema evolution and data partitioning strategies - Delta Lake table design and optimization - Design scalable data lakehouse architectures |
| Topic 4: Data Ingestion and Transformation | - Transform and clean datasets using Spark SQL and DataFrame APIs - Handle batch and streaming data pipelines - Ingest data using Apache Spark and Databricks |
>> Databricks-Certified-Professional-Data-Engineer New Braindumps Ebook <<
Appropriately, we can wrap up this post with the way that the test centers around the material that is essential to handily clear your Databricks Certified Professional Data Engineer Exam certification exam. You can trust the material and set aside an edge to zero in on those before you win eventually over the last Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam dates. To get it, find the source that assists you with getting the right test and spotlight on material agreeable for you for organizing the Databricks Certified Professional Data Engineer Exam exam.
NEW QUESTION # 42
A data engineer wants to join a stream of advertisement impressions (when an ad was shown) with another stream of user clicks on advertisements to correlate when impression led to monitizable clicks.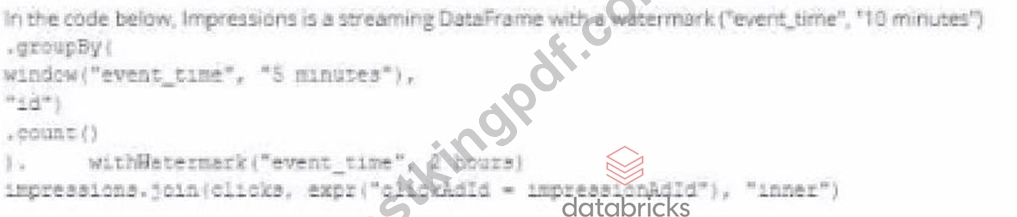
Which solution would improve the performance?




Answer: A
Explanation:
When joining a stream of advertisement impressions with a stream of user clicks, you want to minimize the state that you need to maintain for the join. Option A suggests using a left outer join with the condition that clickTime == impressionTime , which is suitable for correlating events that occur at the exact same time.
However, in a real-world scenario, you would likely need some leeway to account for the delay between an impression and a possible click. It ' s important to design the join condition and the window of time considered to optimize performance while still capturing the relevant user interactions. In this case, having the watermark can help with state management and avoid state growing unbounded by discarding old state data that ' s unlikely to match with new data.
NEW QUESTION # 43
The data governance team is reviewing code used for deleting records for compliance with GDPR. They note the following logic is used to delete records from the Delta Lake table named users.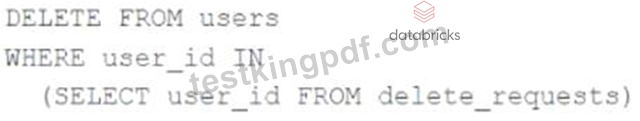
Assuming that user_id is a unique identifying key and that delete_requests contains all users that have requested deletion, which statement describes whether successfully executing the above logic guarantees that the records to be deleted are no longer accessible and why?
Answer: C
Explanation:
The code uses the DELETE FROM command to delete records from the users table that match a condition based on a join with another table called delete_requests, which contains all users that have requested deletion.
The DELETE FROM command deletes records from a Delta Lake table by creating a new version of the table that does not contain the deleted records. However, this does not guarantee that the records to be deleted are no longer accessible, because Delta Lake supports time travel, which allows querying previous versions of the table using a timestamp or version number. Therefore, files containing deleted records may still be accessible with time travel until a vacuum command is used to remove invalidated data files from physical storage.
Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Delete from a table" section; Databricks Documentation, under "Remove files no longer referenced by a Delta table" section.
NEW QUESTION # 44
A table named user_ltv is being used to create a view that will be used by data analysis on various teams. Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:
An analyze who is not a member of the auditing group executing the following query:
Which result will be returned by this query?
Answer: A
Explanation:
Given the CASE statement in the view definition, the result set for a user not in the auditing group would be constrained by the ELSE condition, which filters out records based on age. Therefore, the view will return all columns normally for records with an age greater than 18, as users who are not in the auditing group will not satisfy the is_member('auditing') condition. Records not meeting the age > 18 condition will not be displayed.
NEW QUESTION # 45
A junior member of the data engineering team is exploring the language interoperability of Databricks notebooks. The intended outcome of the below code is to register a view of all sales that occurred in countries on the continent of Africa that appear in thegeo_lookuptable.
Before executing the code, runningSHOWTABLESon the current database indicates the database contains only two tables:geo_lookupandsales.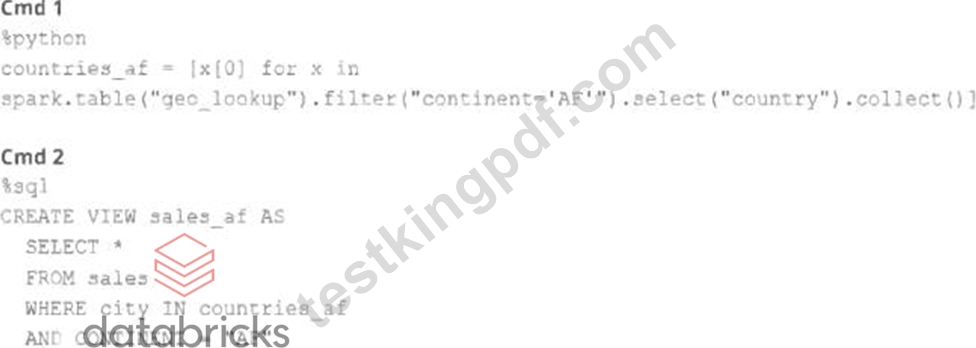
Which statement correctly describes the outcome of executing these command cells in order in an interactive notebook?
Answer: B
Explanation:
This is the correct answer because Cmd 1 is written in Python and uses a list comprehension to extract the country names from the geo_lookup table and store them in a Python variable named countries af. This variable will contain a list of strings, not a PySpark DataFrame or a SQL view. Cmd 2 is written in SQL and tries to create a view named sales af by selecting from the sales table where city is in countries af. However, this command will fail because countries af is not a valid SQL entity and cannot be used in a SQL query. To fix this, a better approach would be to use spark.sql() to execute a SQL query in Python and pass the countries af variable as a parameter. Verified References: [Databricks Certified Data Engineer Professional], under
"Language Interoperability" section; Databricks Documentation, under "Mix languages" section.
NEW QUESTION # 46
A data engineer is masking a column containing email addresses. The goal is to produce output strings of identical length for all rows, while generating different outputs for different email values.
Which SQL function should be used to achieve this?
Answer: B
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
The hash() function in Databricks SQL returns a deterministic fixed-length integer (or hexadecimal string) derived from the input. When applied to sensitive identifiers like email addresses, it produces a unique value for each distinct input while ensuring uniform output size, making it suitable for anonymization where referential consistency is required.
Functions like mask() perform pattern-based substitutions that change string lengths, and sha1() or sha2() produce long hexadecimal strings of varying lengths (depending on hash size), which may not match requirements for fixed-length masking.
Therefore, the correct choice for fixed-length, deterministic pseudonymization of email addresses is hash(email), as it maintains analytical usability while anonymizing sensitive data.
NEW QUESTION # 47
......
Our Databricks-Certified-Professional-Data-Engineer practice materials made them enlightened and motivated to pass the exam within one week, which is true that someone did it always. The number is real proving of our Databricks-Certified-Professional-Data-Engineer exam questions rather than spurious made-up lies. And you can also see the comments on the website to see how our loyal customers felt about our Databricks-Certified-Professional-Data-Engineer training guide. They all highly praised our Databricks-Certified-Professional-Data-Engineer learning prep and got their certification. So will you!
Databricks-Certified-Professional-Data-Engineer Exam Sample: https://www.testkingpdf.com/Databricks-Certified-Professional-Data-Engineer-testking-pdf-torrent.html