2026 Latest Exam4Free DP-700 PDF Dumps and DP-700 Exam Engine Free Share: https://drive.google.com/open?id=13YVl6d3ilSQ6La0tLq2UpSrcCSGoAyN_
We make sure that the Microsoft DP-700 exam questions prices are affordable for everyone. All three Exam4Free DP-700 exam practice test questions formats are being offered at the lowest price. Just get benefits from this cheap Implementing Data Engineering Solutions Using Microsoft Fabric DP-700 Exam Questions price and download it right now.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
We have handled professional DP-700 practice materials for over ten years. Our experts have many years’ experience in this particular line of business, together with meticulous and professional attitude towards jobs. Their abilities are unquestionable, besides, DP-700 Exam Questions are priced reasonably with three kinds: the PDF, Software and APP online. Though the content is the same, but their displays are totally different and functionable.
NEW QUESTION # 100
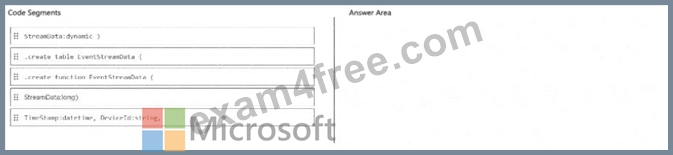
You have Fabric workspace that contains eventhouse named Eventhouse1.
In Eventhouse1, you plan to create a table named EventStreamData in a KQL database. The table will contain data based on the following sample.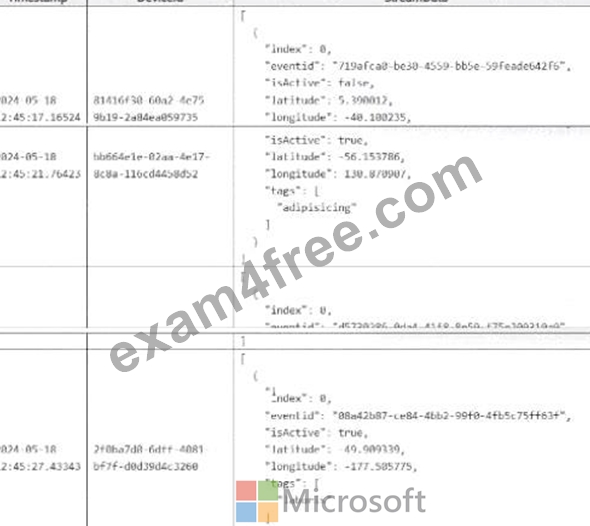
Answer:
Explanation: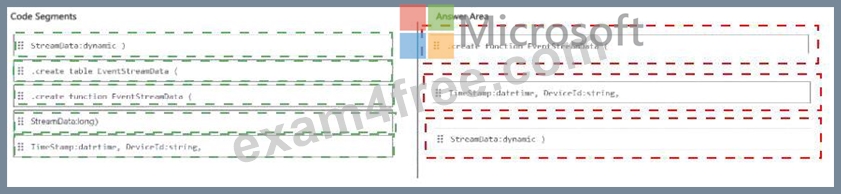
Explanation: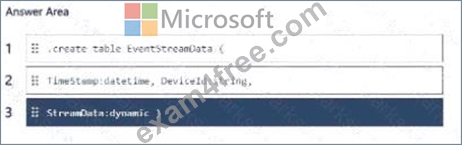
NEW QUESTION # 101
You have a Fabric workspace named Workspace1 that contains a lakehouse named Lakehouse1.
You need to automate a PySpark-based data transformation process. The solution must meet the following requirements:
* Ensure that users can edit and test the PySpark code interactively.
* Ensure that the code can be operationalized for automated execution.
Which three actions should you perform in sequence?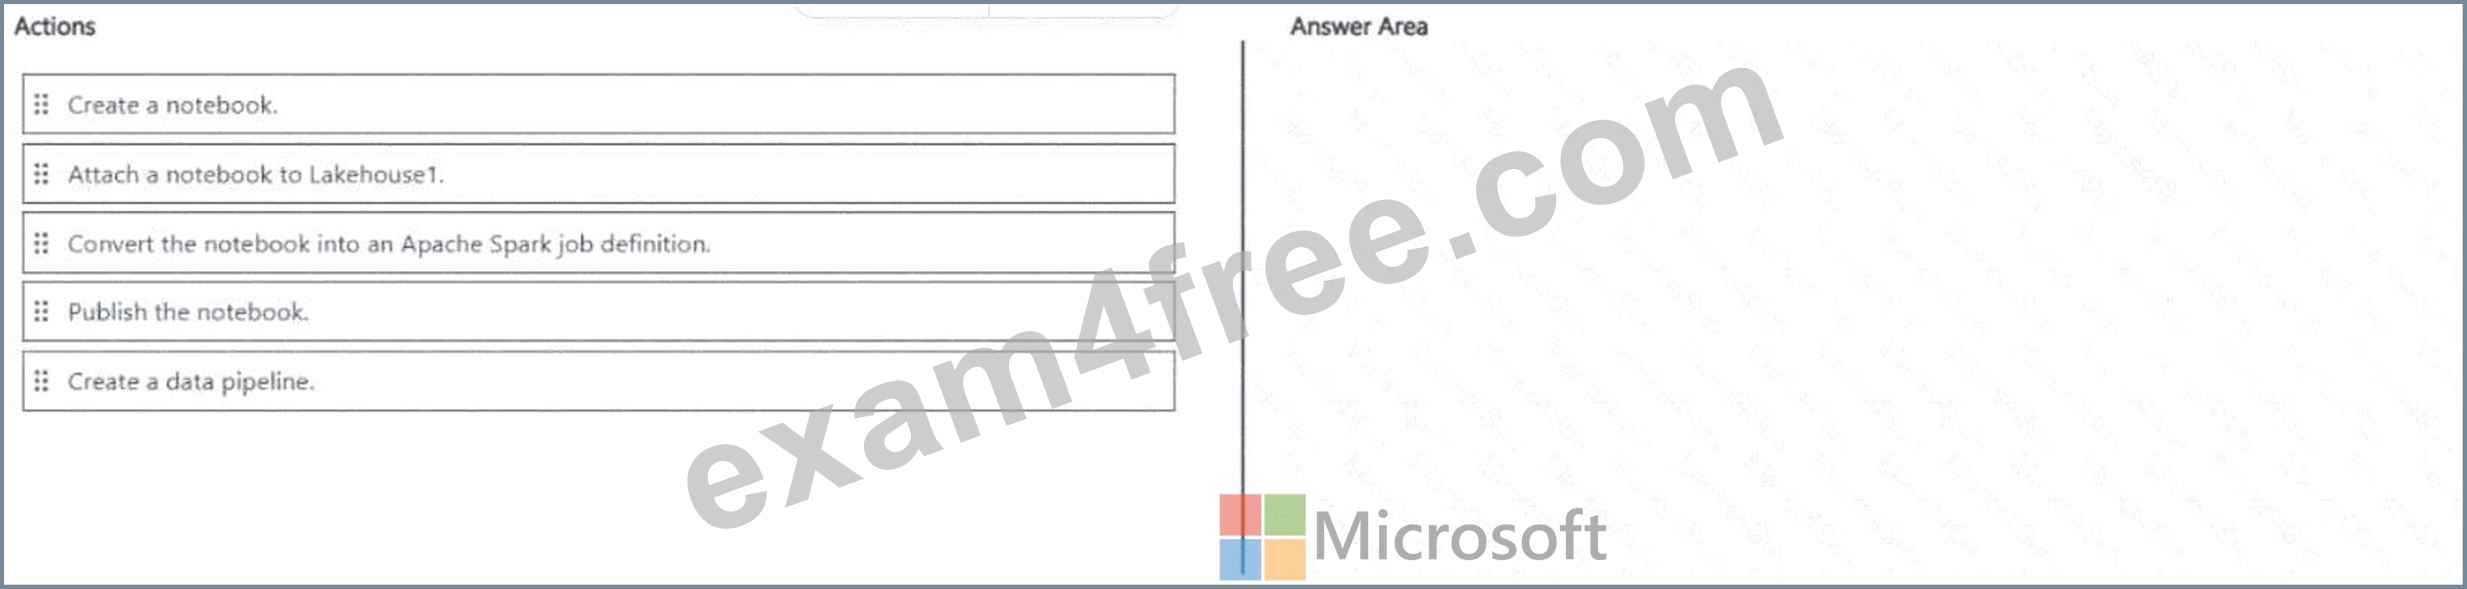
Answer:
Explanation: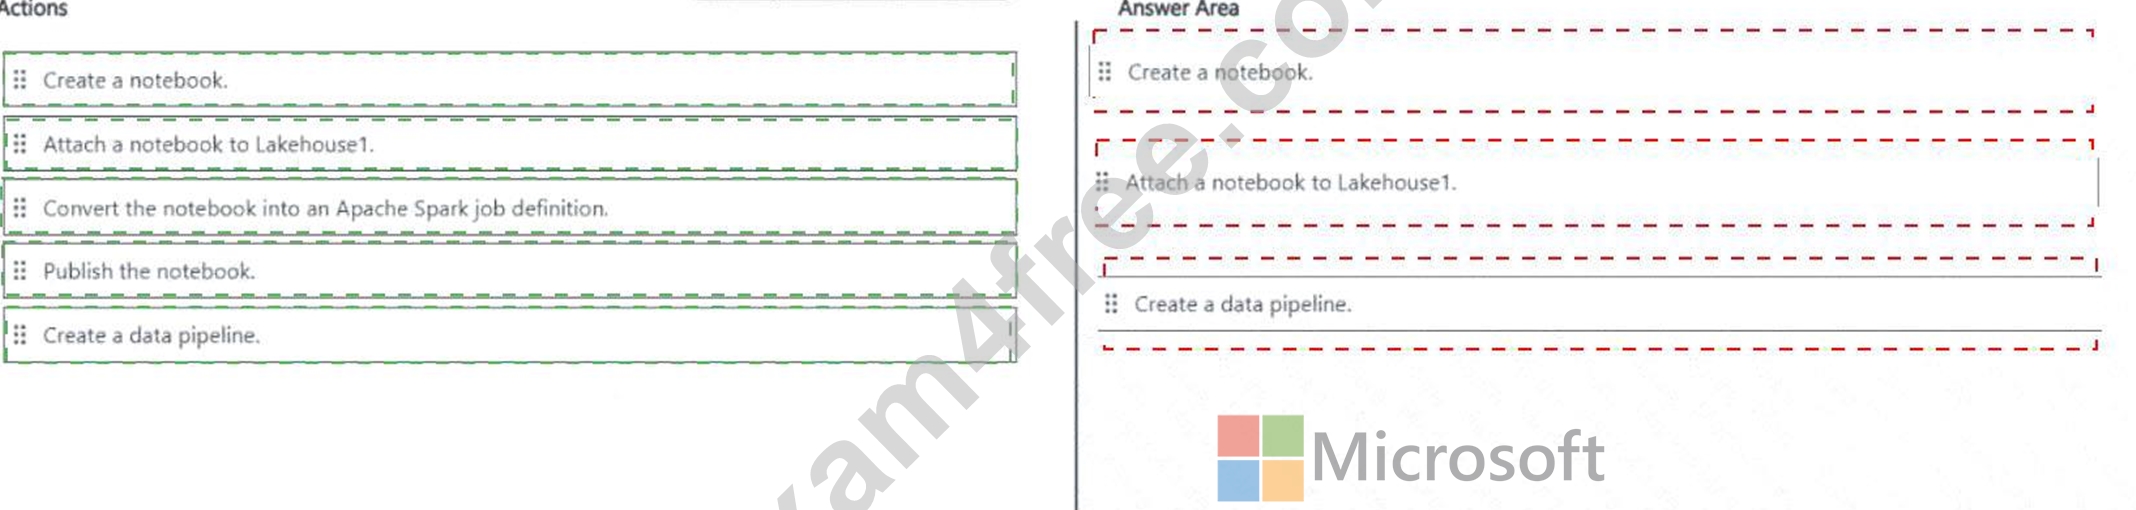
Explanation:
The correct sequence is Create a notebook # Attach the notebook to Lakehouse1 # Create a data pipeline
.
First, create a Fabric notebook because notebooks provide the interactive development environment required for authoring, executing, debugging, and testing PySpark code. Microsoft describes Fabric notebooks as a primary code item for developing Apache Spark workloads and specifically supports their use for data ingestion, preparation, and transformation.
Second, attach the notebook to Lakehouse1 . Attaching a lakehouse establishes the notebook ' s lakehouse context, allowing PySpark code to access the lakehouse ' s Files and Tables through Spark and OneLake. This enables developers to interactively validate the transformation against the required Fabric data.
Third, create a data pipeline and use a Notebook activity to operationalize the notebook. Fabric Data Factory explicitly supports running Fabric notebooks as pipeline activities for automated data transformation workflows. Pipelines can subsequently be run manually, scheduled, or incorporated into larger orchestration processes.
Converting the notebook to an Apache Spark job definition is unnecessary; Spark job definitions are separate executable Fabric items. Publishing the notebook is also not required for pipeline execution.
Study Guide reference: Ingest and transform data # Transform data with Apache Spark # Fabric notebooks # Orchestrate processes and schedules with Data Factory pipelines.
NEW QUESTION # 102
You have a Fabric workspace named Workspace1 that contains a notebook named Notebook1.
In Workspace1, you create a new notebook named Notebook2.
You need to ensure that you can attach Notebook2 to the same Apache Spark session as Notebook1.
What should you do?
Answer: C
Explanation:
To ensure that Notebook2 can attach to the same Apache Spark session as Notebook1, you need to enable high concurrency for notebooks. High concurrency allows multiple notebooks to share a Spark session, enabling them to run within the same Spark context and thus share resources like cached data, session state, and compute capabilities. This is particularly useful when you need notebooks to run in sequence or together while leveraging shared resources.
NEW QUESTION # 103
HOTSPOT
You have a Fabric workspace that contains two lakehouses named Lakehouse1 and Lakehouse2. Lakehouse1 contains staging data in a Delta table named Orderlines. Lakehouse2 contains a Type 2 slowly changing dimension (SCD) dimension table named Dim_Customer.
You need to build a query that will combine data from Orderlines and Dim_Customer to create a new fact table named Fact_Orders. The new table must meet the following requirements:
Enable the analysis of customer orders based on historical attributes.
Enable the analysis of customer orders based on the current attributes.
How should you complete the statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation: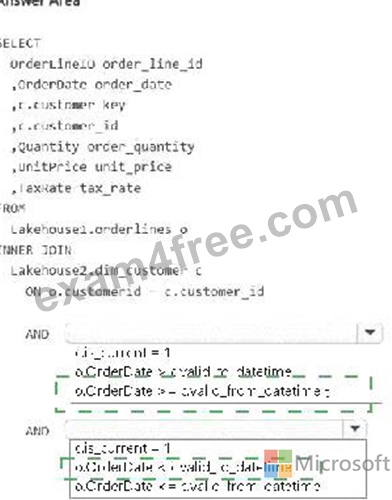
Explanation: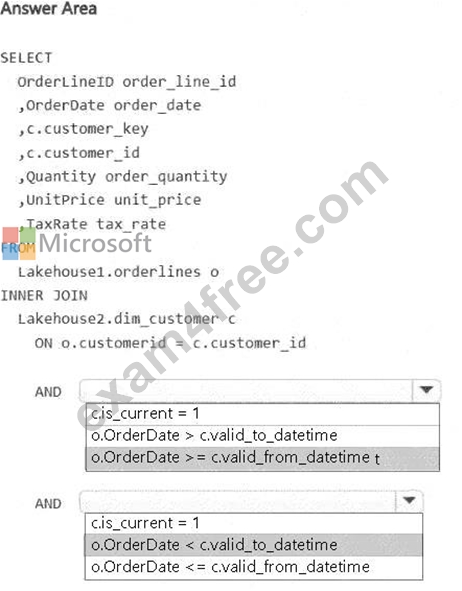
NEW QUESTION # 104
HOTSPOT
You have a Fabric workspace.
You are debugging a statement and discover the following issues:
Sometimes, the statement fails to return all the expected rows.
The PurchaseDate output column is NOT in the expected format of mmm dd, yy.
You need to resolve the issues. The solution must ensure that the data types of the results are retained. The results can contain blank cells.
How should you complete the statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.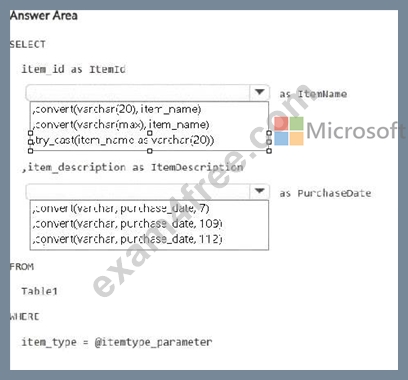
Answer:
Explanation:
Explanation: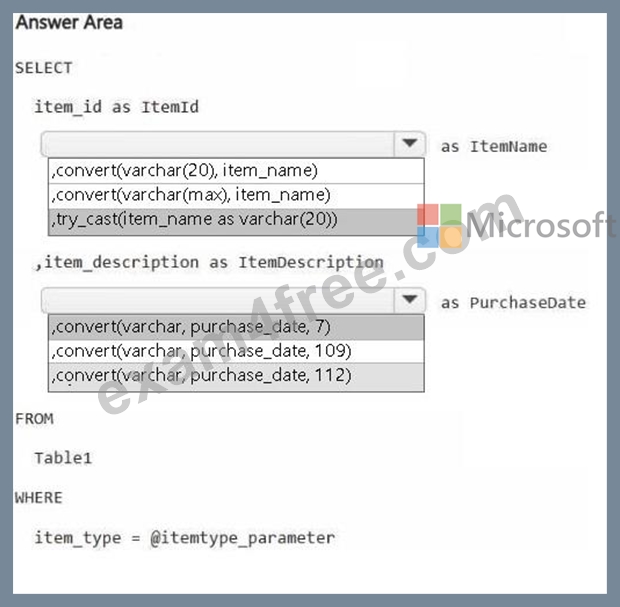
Topic 1, Litware, IncCase Study
This is a case study. Case studies are not timed separately. You can use as much exam time as you would like to complete each case. However, there may be additional case studies and sections on this exam. You must manage your time to ensure that you are able to complete all questions included on this exam in the time provided.
To answer the questions included in a case study, you will need to reference information that is provided in the case study. Case studies might contain exhibits and other resources that provide more information about the scenario that is described in the case study. Each question is independent of the other questions in this case study.
At the end of this case study, a review screen will appear. This screen allows you to review your answers and to make changes before you move to the next section of the exam. After you begin a new section, you cannot return to this section.
To start the case study
To display the first question in this case study, click the Next button. Use the buttons in the left pane to explore the content of the case study before you answer the questions. Clicking these buttons displays information such as business requirements, existing environment, and problem statements. If the case study has an All Information tab, note that the information displayed is identical to the information displayed on the subsequent tabs. When you are ready to answer a question, click the Question button to return to the question.
Overview
Litware, Inc. is a publishing company that has an online bookstore and several retail bookstores worldwide.
Litware also manages an online advertising business for the authors it represents.
Existing Environment. Fabric Environment
Litware has a Fabric workspace named Workspace1. High concurrency is enabled for Workspace1.
The company has a data engineering team that uses Python for data processing.
Existing Environment. Data Processing
The retail bookstores send sales data at the end of each business day, while the online bookstore constantly provides logs and sales data to a central enterprise resource planning (ERP) system.
Litware implements a medallion architecture by using the following three layers: bronze, silver, and gold. The sales data is ingested from the ERP system as Parquet files that land in the Files folder in a lakehouse.
Notebooks are used to transform the files in a Delta table for the bronze and silver layers. The gold layer is in a warehouse that has V-Order disabled.
Litware has image files of book covers in Azure Blob Storage. The files are loaded into the Files folder.
Existing Environment. Sales Data
Month-end sales data is processed on the first calendar day of each month. Data that is older than one month never changes.
In the source system, the sales data refreshes every six hours starting at midnight each day.
The sales data is captured in a Dataflow Gen1 dataflow. When the dataflow runs, new and historical data is captured. The dataflow captures the following fields of the source:
Sales Date
Author
Price
Units
SKU
A table named AuthorSales stores the sales data that relates to each author. The table contains a column named AuthorEmail. Authors authenticate to a guest Fabric tenant by using their email address.
Existing Environment. Security Groups
Litware has the following security groups:
Sales
Fabric Admins
Streaming Admins
Existing Environment. Performance Issues
Business users perform ad-hoc queries against the warehouse. The business users indicate that reports against the warehouse sometimes run for two hours and fail to load as expected. Upon further investigation, the data engineering team receives the following error message when the reports fail to load: "The SQL query failed while running." The data engineering team wants to debug the issue and find queries that cause more than one failure.
When the authors have new book releases, there is often an increase in sales activity. This increase slows the data ingestion process.
The company's sales team reports that during the last month, the sales data has NOT been up-to-date when they arrive at work in the morning.
Requirements. Planned Changes
Litware recently signed a contract to receive book reviews. The provider of the reviews exposes the data in Amazon Simple Storage Service (Amazon S3) buckets.
Litware plans to manage Search Engine Optimization (SEO) for the authors. The SEO data will be streamed from a REST API.
Requirements. Version Control
Litware plans to implement a version control solution in Fabric that will use GitHub integration and follow the principle of least privilege.
Requirements. Governance Requirements
To control data platform costs, the data platform must use only Fabric services and items. Additional Azure resources must NOT be provisioned.
Requirements. Data Requirements
Litware identifies the following data requirements:
Process the SEO data in near-real-time (NRT).
Make the book reviews available in the lakehouse without making a copy of the data.
When a new book cover image arrives in the Files folder, process the image as soon as possible.
NEW QUESTION # 105
......
For candidates who will attend an exam, some practice for it is necessary. DP-700 Exam Dumps of us will give you the practice you need. DP-700 exam dumps of us contain the knowledge point of the exam. Skilled professionals will verify the questions and answers, which will guarantee the correctness. Besides, we also offer you free update for one year after purchasing, and the update version will send to your email address automatically.
Online DP-700 Bootcamps: https://www.exam4free.com/DP-700-valid-dumps.html
BTW, DOWNLOAD part of Exam4Free DP-700 dumps from Cloud Storage: https://drive.google.com/open?id=13YVl6d3ilSQ6La0tLq2UpSrcCSGoAyN_