Nutanix exam simulation software is the best offline method to boost preparation for the Nutanix NCP-BC-7.5 examination. The software creates a NCP-BC-7.5 real practice test-like scenario where aspirants face actual NCP-BC-7.5 exam questions. This feature creates awareness among users about Nutanix Certified Professional - Business Continuity (NCP-BC) 7.5 exam pattern and syllabus. With the desktop Nutanix NCP-BC-7.5 Practice Exam software, you can practice for the test offline via any Windows-based computer.
| Section | Objectives |
|---|---|
| Topic 1: Security and Hardening | - Approval policies configuration - Designing secure BCDR environments - Security best practices for replication - RBAC implementation for disaster recovery |
| Topic 2: BCDR Fundamentals and Requirements Interpretation | - Defining recovery strategies aligned to business requirements and risk tolerance - Understanding RTO and RPO concepts and business impact analysis - Availability metrics and SLA definitions - Selecting appropriate replication types (async, near-sync, synchronous, metro) - Translating business requirements into resilient recovery architectures |
| Topic 3: Monitoring, Testing and Troubleshooting | - Resolving third-party backup integration problems - Non-disruptive recovery testing - Troubleshooting permission issues and misconfigured DR environments - Diagnosing network, storage and replication failures - Setting up alerts for replication lag - Documenting runbooks for incident response |
| Topic 4: Replication and Failover Architecture | - Asynchronous replication planning - Failover readiness validation - Recovery site capacity management - Network segmentation for BCDR environments - Synchronous replication across sites |
| Topic 5: Nutanix Disaster Recovery Solutions | - Integration with third-party backup solutions - Metro Availability configuration and management - Configuring and managing replication policies - Failover procedures and execution - Recovery workflows using Nutanix native tools |
| Topic 6: Data Protection and Snapshots | - Data restoration at VM and application level - Storage configuration for BCDR - Snapshot retention policies design - Incremental backup implementation - Snapshot scheduling and management |
>> Reliable NCP-BC-7.5 Test Braindumps <<
If you buy TestPassed Nutanix NCP-BC-7.5 Exam Training materials, you will solve the problem of your test preparation. You will get the training materials which have the highest quality. Buy our products today, and you will open a new door, and you will get a better future. We can make you pay a minimum of effort to get the greatest success.
NEW QUESTION # 45
A VM is protected in an Async Protection Policy and added to a Recovery Plan. An administrator is attempting to perform a planned failover of the VM. How many recovery points are created and replicated during the planned failover process?
Answer: B
Explanation:
A Planned Failover in Nutanix Disaster Recovery is an orchestrated workflow designed to migrate workloads with zero data loss. However, the behavior of recovery point creation depends on the current state of synchronization and the type of replication policy. For standard Asynchronous (Async) Protection Policies, the system typically relies on the established schedule to maintain recovery point consistency. In many automated workflows, especially during a test or a specific " planned " trigger, the administrator might assume a new snapshot is generated; however, if the system is designed to use the most recent " consistent " state, it may rely on the last successfully replicated recovery point to initiate the restore.
Technically, if a new point were to be created, it would require the VM to be shut down at the source to ensure application consistency-a process that is part of the planned failover sequence. If the policy is configured to use existing data for speed, it bypasses new creation to minimize the maintenance window. This emphasizes the importance of verifying that replication is " In-Sync " or " Healthy " before starting a planned failover. If the last recovery point is several hours old, the " planned " move could result in a significant rollback unless the administrator manually triggers a synchronization task prior to the failover event.
Understanding this behavior ensures that BCDR administrators can accurately predict data states following a controlled migration between sites.
NEW QUESTION # 46
An administrator configures a VM-VM Anti-Affinity policy for a web application cluster to ensure high availability. The application is protected by a Protection Policy in Prism Central. A failover occurs, moving the VMs to the recovery site.
What determines whether the VM-VM Anti-Affinity rules are active on the recovery site?
Answer: C
Explanation:
VM-VM Anti-Affinity rules are used in Nutanix to ensure that specific virtual machines (such as the nodes of a database cluster or redundant web servers) never run on the same physical host, thereby protecting the application from a single host failure. These rules are typically managed through Prism Central (PC) in a modern deployment.
However, in the context of Disaster Recovery (DR) between two different clusters or availability zones, there is a technical limitation regarding the replication of these affinity policies. While the virtual machine ' s data and primary metadata (CPU, RAM, Disks) are replicated by the Cerebro service, the affinity rules are often considered local cluster constraints. In many versions of Nutanix Disaster Recovery (specifically the initial iterations of Leap/Prism Central-based DR), these affinity policies are not natively " synchronized " or enforced at the recovery site during a failover. This means that when the VMs are recovered at the destination cluster, the hypervisor ' s dynamic scheduler (ADS) may place them on the same host if that host has the most available resources. To maintain anti-affinity at the recovery site, an administrator would typically need to manually recreate the affinity policies at the destination AZ or use specialized orchestration scripts.
Understanding this limitation is vital for ensuring that high-availability requirements are still met after a disaster recovery event has occurred.
NEW QUESTION # 47
An administrator has been tasked with configuring a Nutanix replication solution that provides an RPO of zero. Which solution should the administrator choose?
Answer: D
Explanation:
The Recovery Point Objective (RPO) is a measure of how much data an organization can afford to lose during an outage. An RPO of zero means that absolutely no data loss is tolerated; every write performed at the primary site must be safely committed to the recovery site before the application receives a confirmation. In the Nutanix portfolio, Synchronous Replication (Option A) is the only technology that guarantees this level of data protection. It mirrors every write in real-time between two clusters, ensuring they are always in perfect synchronization. In contrast, Nearsync Replication (Option B) allows for very low RPOs (as low as 20 seconds to 1 minute), but it is still fundamentally an asynchronous process using lightweight snapshots, meaning some " data-in-flight " could be lost. Async Replication (Option C) typically involves RPOs of one hour or more and is used for less critical workloads. Cloud Connect (Option D) is a legacy feature for off-site backup and does not support zero-RPO requirements. Synchronous Replication is the " gold standard " for Tier-1, mission-critical applications where data integrity and zero loss are the primary business requirements, provided the network latency between sites is 5ms or less.
NEW QUESTION # 48
Refer to Exhibit: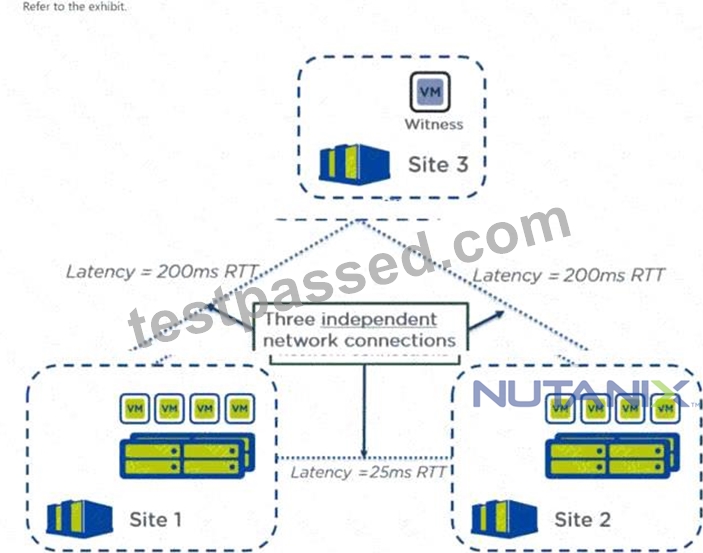
An administrator is configuring Metro Availability in their environment, as shown in the diagram. What issue in the configuration will prevent Metro from working correctly?
Answer: D
Explanation:
Nutanix Metro Availability and Synchronous Replication have very strict networking requirements to ensure that real-time data mirroring does not introduce unacceptable application latency. The industry-standard requirement for Nutanix synchronous operations is a maximum Round Trip Time (RTT) latency of 5ms between the two primary clusters (Site 1 and Site 2). According to the diagram provided in the question, the latency between Site 1 and Site 2 is 25ms RTT. This latency is significantly higher than the 5ms threshold and will prevent the Metro Availability configuration from functioning correctly. While the latency to the Witness VM (200ms RTT) is perfectly acceptable (Option D), and having a Witness at a third site (Option A) is a best practice, the " data path " between the storage clusters is the bottleneck here. If an administrator attempts to enable Metro with 25ms of latency, the guest VMs would experience severe performance degradation because every write would be delayed by the 25ms it takes to receive an acknowledgment from the remote site.
Therefore, the high latency between the data-serving sites is the primary configuration issue that must be resolved, typically by moving the clusters closer together or upgrading the inter-site fiber connection.
NEW QUESTION # 49
An administrator configures disaster recovery between an on-premises AZ and a Nutanix Cloud AZ. After enabling DR and assigning protection policies to several VMs with volume groups, the administrator initiates failover and notices the VMs do not have their volume groups attached. Investigation reveals:
* The clusters are successfully paired in Prism Central.
* Protection policies and replication schedules are configured correctly.
* Recovery plan validation completes successfully.
* Required firewall ports between sites are confirmed open.
* Management IP addresses are reachable in both directions.
Despite this, the administrator observes the volume groups are still not attached. Which network-related prerequisite is most likely misconfigured?
Answer: C
Explanation:
Nutanix Volume Groups (VGs) provide block-level storage to virtual machines, often used for high- performance databases or shared storage clusters. Unlike standard vDisks, which are managed directly as part of the VM ' s hardware definition, VGs are presented as iSCSI targets. In a Disaster Recovery scenario, when a VM is recovered at a new site, it must be able to " find " and re-attach these Volume Groups to resume operation.
For this attachment to succeed, especially across different clusters or into a Nutanix Cloud AZ, both the source and recovery clusters must have a " Data Services IP Address " configured. The Data Services IP acts as the cluster-wide iSCSI target portal. When a VM fails over, the Nutanix orchestration engine uses this IP to coordinate the iSCSI login and mapping of the Volume Group to the guest OS. If this IP is missing on either cluster, the internal iSCSI redirection and handoff mechanisms will fail, even if the general management networking and Protection Policies are perfectly healthy. This is a common " Day 1 " configuration error because management connectivity (Prism) works without a Data Services IP, but block-level services like VGs and certain NGT features strictly require it. Verifying and configuring the Data Services IP at both availability zones is the primary fix for Volume Group attachment failures during DR failover.
NEW QUESTION # 50
......
Do you want to find a job that really fulfills your ambitions? That's because you haven't found an opportunity to improve your ability to lay a solid foundation for a good career. Our NCP-BC-7.5 quiz torrent can help you get out of trouble regain confidence and embrace a better life. Our NCP-BC-7.5 Exam Question can help you learn effectively and ultimately obtain the authority certification of Nutanix, which will fully prove your ability and let you stand out in the labor market. We have the confidence and ability to make you finally have rich rewards.
Exam NCP-BC-7.5 Price: https://www.testpassed.com/NCP-BC-7.5-still-valid-exam.html