ちなみに、Jpshiken DP-600の一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1egVz1VSNhptE4pzhqTIUs01aAmC3dcB3
我々はDP-600試験を準備しているあなたに便利をもたらすために、PDF版、ソフト版、オンライン版の3つの異なるバーションを提供しています。PDF版のDP-600問題集を利用したら、紙でプリントすることができて読みやすいです。ソフト版であなたは試験の環境でDP-600模擬試験をすることができて複数のパソコンで使用することができます。また、オンライン版を通して、どの電子製品でも使うことができて、オンライン版の機能はソフト版のと大体同じです。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
DP-600練習資料には、オンラインでPDF、ソフトウェア、APPの3つの異なるバージョンがあります。 Microsoftそして、DP-600学習教材は、その高い効率のために多くの時間を節約できます。 地下鉄またはバスでDP-600の実際のテストのオンラインバージョンを学習できます。 食事の準備をしているときに確認できます。 寝る前に勉強することができます。 同時に、APPバージョンのDP-600学習教材はオフライン学習をサポートしているため、ネットワークなしではImplementing Analytics Solutions Using Microsoft Fabric学習する方法がない状況を回避できます。 なぜあなたはまだためらっていますか? 来て買ってください!
質問 # 160
You have a Fabric tenant.
You need to create a semantic model that delivers fast report rendering, minimizes query latency, and maximizes flexibility for DAX calculations.
Which storage mode should you select?
正解:D
解説:
For a Microsoft Fabric tenant requiring fast report rendering, minimal query latency, and maximum DAX flexibility, the appropriate storage mode is Direct Lake.
Direct Lake is a native Fabric storage mode that provides Import-like performance by loading data directly into memory from Delta tables in OneLake, bypassing the need for traditional data refreshes or slow DirectQuery translations.
Direct Lake combines the advantages of traditional modes while mitigating their common drawbacks:
Fast Rendering & Low Latency: It utilizes the same VertiPaq in-memory engine as Import mode, ensuring lightning-fast query execution for interactive reports.
Maximum DAX Flexibility: Unlike DirectQuery, which often limits DAX functions to what the source SQL can understand, Direct Lake supports the full breadth of DAX because it operates on data already paged into memory.
No Refresh Latency: It reads directly from OneLake (Delta Parquet files), meaning as soon as your data is updated in the Lakehouse or Warehouse, the semantic model can reflect those changes without waiting for a scheduled refresh.
Reduced Overhead: It eliminates data duplication and the "refresh tax" (CPU/memory spikes during scheduled imports) because it loads columns on-demand as they are needed for visuals.
Reference:
https://learn.microsoft.com/en-us/fabric/fundamentals/direct-lake-overview
質問 # 161
You are analyzing customer purchases in a Fabric notebook by using PySpanc You have the following DataFrames:
You need to join the DataFrames on the customer_id column. The solution must minimize data shuffling. You write the following code.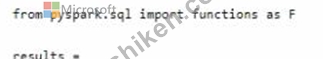
Which code should you run to populate the results DataFrame?




正解:A
質問 # 162
You have a Fabric tenant that contains a lakehouse.
You are using a Fabric notebook to save a large DataFrame by using the following code.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.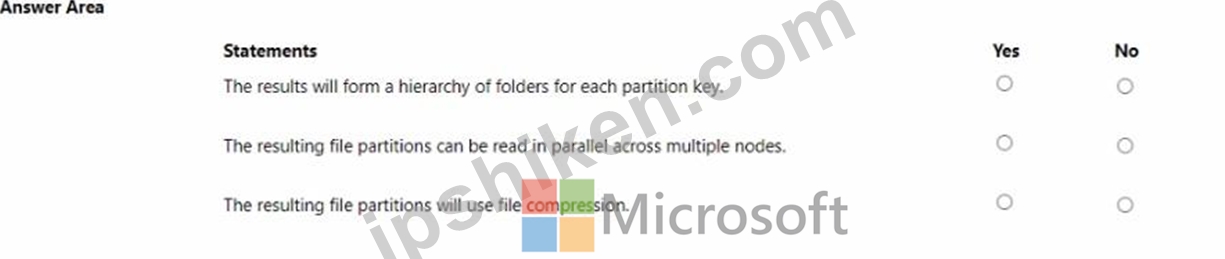
正解:
解説: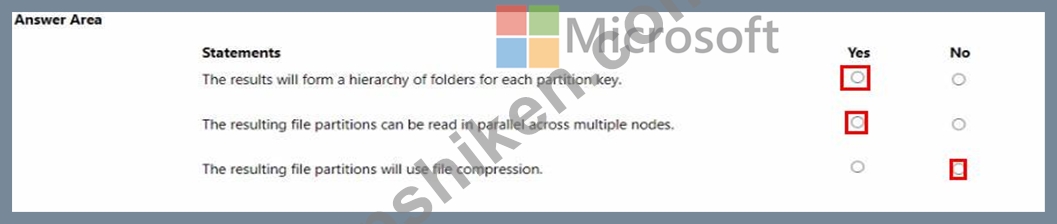
Reference:
DataFrame write partitionBy
Apache Spark optimization with partitioning
質問 # 163
You have a Microsoft Power Bl report named Report1 that uses a Fabric semantic model.
Users discover that Report1 renders slowly.
You open Performance analyzer and identify that a visual named Orders By Date is the slowest to render. The duration breakdown for Orders By Date is shown in the following table.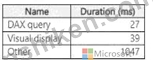
What will provide the greatest reduction in the rendering duration of Report1?
正解:A
解説:
Based on the duration breakdown provided, the major contributor to the rendering duration is categorized as " Other, " which is significantly higher than DAX Query and Visual display times. This suggests that the issue is less likely with the DAX calculation or visual rendering times and more likely related to model performance or the complexity of the visual. However, of the options provided, optimizing the DAX query can be a crucial step, even if " Other " factors are dominant. Using DAX Studio, you can analyze and optimize the DAX queries that power your visuals for performance improvements. Here's how you might proceed:
Open DAX Studio and connect it to your Power BI report.
Capture the DAX query generated by the Orders By Date visual.
Use the Performance Analyzer feature within DAX Studio to analyze the query.
Look for inefficiencies or long-running operations.
Optimize the DAX query by simplifying measures, removing unnecessary calculations, or improving iterator functions.
Test the optimized query to ensure it reduces the overall duration.
References: The use of DAX Studio for query optimization is a common best practice for improving Power BI report performance as outlined in the Power BI documentation.
質問 # 164
You are managing a set of Dataflow Gen2 queries that are currently ingesting tables into a Fabric lakehouse. You need to ensure that the tables are optimized for Direct Lake connections that will be used by connected semantic models. What should you do?
正解:B
質問 # 165
......
多くのIT業界の友達によるとMicrosoft認証試験を準備することが多くの時間とエネルギーをかからなければなりません。もし訓練班とオンライン研修などのルートを通じないと試験に合格するのが比較的に難しい、一回に合格率非常に低いです。Jpshikenはもっとも頼られるトレーニングツールで、MicrosoftのDP-600認定試験の実践テストソフトウェアを提供したり、MicrosoftのDP-600認定試験の練習問題と解答もあって、最高で最新なMicrosoftのDP-600認定試験「Implementing Analytics Solutions Using Microsoft Fabric」問題集も一年間に更新いたします。
DP-600合格対策: https://www.jpshiken.com/DP-600_shiken.html
BONUS!!! Jpshiken DP-600ダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1egVz1VSNhptE4pzhqTIUs01aAmC3dcB3