BONUS!!! ShikenPASS Data-Engineer-Associateダンプの一部を無料でダウンロード:https://drive.google.com/open?id=13r8KNNm4iLKplcSUiiN9AxuiHpD8qVJt
貴重な時間を無駄にすることを心配する必要はありませんが、Data-Engineer-Associate認定を取得することに失敗します。多くの人が教材を使用しており、試験の合格率は99%です。これは、教材で学習している限り、間違いなくData-Engineer-Associate試験に合格することを意味します。何らかの問題が発生し、Data-Engineer-Associate試験にAWS Certified Data Engineer - Associate (DEA-C01)合格しなかった場合、全額返金されます。当社Amazonの誠実さは、製品の品質に起因しています。試験の学習資料の1年間の無料アップデートを提供します。さあ、決心してData-Engineer-Associate試験の急流を手に入れましょう!
| Section | Weight | Objectives |
|---|---|---|
| Data Store Management | 26% | - Design data models
|
| Data Security and Governance | 18% | - Apply authentication and authorization
|
| Data Ingestion and Transformation | 34% | - Apply programming concepts
|
| Data Operations and Support | 22% | - Manage and troubleshoot data processes
|
>> Data-Engineer-Associate模擬問題集 <<
近年、IT業種の発展はますます速くなることにつれて、ITを勉強する人は急激に多くなりました。人々は自分が将来何か成績を作るようにずっと努力しています。AmazonのData-Engineer-Associate試験はIT業種に欠くことができない認証ですから、試験に合格することに困っている人々はたくさんいます。ここで皆様に良い方法を教えてあげますよ。ShikenPASSが提供したAmazonのData-Engineer-Associateトレーニング資料を利用する方法です。あなたが試験に合格することにヘルプをあげられますから。それにShikenPASSは100パーセント合格率を保証します。あなたが任意の損失がないようにもし試験に合格しなければShikenPASSは全額で返金できます。
質問 # 291
A data engineer is using Amazon QuickSight to build a dashboard to report a company's revenue in multiple AWS Regions. The data engineer wants the dashboard to display the total revenue for a Region, regardless of the drill-down levels shown in the visual.
Which solution will meet these requirements?
正解:A
解説:
Option C (LAC-A) is the correct choice because the requirement is to always show the Region-level total even when the visual is drilled down into lower levels (for example, country # city # store). A simple calculated field (Option B) is computed at the row level and then aggregated by the visual, so it will change as the drill-down changes the grain. A table calculation (Option A) is evaluated based on the current visual layout and can vary with the fields placed in the visual, which makes it unreliable for enforcing a fixed
"Region total regardless of drill-down."
A level-aware calculation (aggregate) is specifically intended to "lock" an aggregation to a chosen dimensional level (here: Region). That means you can compute revenue aggregated at the Region level and reuse that value across lower drill levels without it recalculating at city/store granularity. A window LAC (LAC-W) is primarily for windowed analytics (running totals, period-over-period, rank, moving averages) over a partition/order, not for enforcing a fixed dimensional aggregation level. Therefore, LAC-A best matches the requirement.
質問 # 292
A data engineer uses Amazon Redshift to run resource-intensive analytics processes once every month. Every month, the data engineer creates a new Redshift provisioned cluster. The data engineer deletes the Redshift provisioned cluster after the analytics processes are complete every month. Before the data engineer deletes the cluster each month, the data engineer unloads backup data from the cluster to an Amazon S3 bucket.
The data engineer needs a solution to run the monthly analytics processes that does not require the data engineer to manage the infrastructure manually.
Which solution will meet these requirements with the LEAST operational overhead?
正解:B
解説:
Amazon Redshift Serverless is a new feature of Amazon Redshift that enables you to run SQL queries on data in Amazon S3 without provisioning or managing any clusters. You can use Amazon Redshift Serverless to automatically process the analytics workload, as it scales up and down the compute resources based on the query demand, and charges you only for the resources consumed. This solution will meet the requirements with the least operational overhead, as it does not require the data engineer to create, delete, pause, or resume any Redshift clusters, or to manage any infrastructure manually. You can use the Amazon Redshift Data API to run queries from the AWS CLI, AWS SDK, or AWS Lambda functions12.
The other options are not optimal for the following reasons:
A . Use Amazon Step Functions to pause the Redshift cluster when the analytics processes are complete and to resume the cluster to run new processes every month. This option is not recommended, as it would still require the data engineer to create and delete a new Redshift provisioned cluster every month, which can incur additional costs and time. Moreover, this option would require the data engineer to use Amazon Step Functions to orchestrate the workflow of pausing and resuming the cluster, which can add complexity and overhead.
C . Use the AWS CLI to automatically process the analytics workload. This option is vague and does not specify how the AWS CLI is used to process the analytics workload. The AWS CLI can be used to run queries on data in Amazon S3 using Amazon Redshift Serverless, Amazon Athena, or Amazon EMR, but each of these services has different features and benefits. Moreover, this option does not address the requirement of not managing the infrastructure manually, as the data engineer may still need to provision and configure some resources, such as Amazon EMR clusters or Amazon Athena workgroups.
D . Use AWS CloudFormation templates to automatically process the analytics workload. This option is also vague and does not specify how AWS CloudFormation templates are used to process the analytics workload. AWS CloudFormation is a service that lets you model and provision AWS resources using templates. You can use AWS CloudFormation templates to create and delete a Redshift provisioned cluster every month, or to create and configure other AWS resources, such as Amazon EMR, Amazon Athena, or Amazon Redshift Serverless. However, this option does not address the requirement of not managing the infrastructure manually, as the data engineer may still need to write and maintain the AWS CloudFormation templates, and to monitor the status and performance of the resources.
Reference:
1: Amazon Redshift Serverless
2: Amazon Redshift Data API
: Amazon Step Functions
: AWS CLI
: AWS CloudFormation
質問 # 293
The company stores a large volume of customer records in Amazon S3. To comply with regulations, the company must be able to access new customer records immediately for the first 30 days after the records are created. The company accesses records that are older than 30 days infrequently.
The company needs to cost-optimize its Amazon S3 storage.
Which solution will meet these requirements MOST cost-effectively?
正解:A
解説:
The most cost-effective solution in this case is to apply a lifecycle policy to transition records to Amazon S3 Standard-IA storage after 30 days. Here's why:
Amazon S3 Lifecycle Policies: Amazon S3 offers lifecycle policies that allow you to automatically transition objects between different storage classes to optimize costs. For data that is frequently accessed in the first 30 days and infrequently accessed after that, transitioning from the S3 Standard storage class to S3 Standard- Infrequent Access (S3 Standard-IA) after 30 days makes the most sense. S3 Standard-IA is designed for data that is accessed less frequently but still needs to be retained, offering lower storage costs than S3 Standard with a retrieval cost for access.
Cost Optimization: S3 Standard-IA offers a lower price per GB than S3 Standard. Since the data will be accessed infrequently after 30 days, using S3 Standard-IA will lower storage costs while still allowing for immediate retrieval when necessary.
Compliance with Regulations: Since the records need to be immediately accessible for the first 30 days, the use of S3 Standard for that period ensures compliance with regulatory requirements. After 30 days, transitioning to S3 Standard-IA continues to meet access requirements for infrequent access while reducing storage costs.
Alternatives Considered:
Option B (S3 Intelligent-Tiering): While S3 Intelligent-Tiering automatically moves data between access tiers based on access patterns, it incurs a small monthly monitoring and automation charge per object. It could be a viable option, but transitioning data to S3 Standard-IA directly would be more cost-effective since the pattern of access is well-known (frequent for 30 days, infrequent thereafter).
Option C (S3 Glacier Deep Archive): Glacier Deep Archive is the lowest-cost storage class, but it is not suitable in this case because the data needs to be accessed immediately within 30 days and on an infrequent basis thereafter. Glacier Deep Archive requires hours for data retrieval, which is not acceptable for infrequent access needs.
Option D (S3 Standard-IA for all records): Using S3 Standard-IA for all records would result in higher costs for the first 30 days, as the data is frequently accessed. S3 Standard-IA incurs retrieval charges, making it less suitable for frequently accessed data.
Amazon S3 Lifecycle Policies
S3 Storage Classes
Cost Management and Data Optimization Using Lifecycle Policies
AWS Data Engineering Documentation
質問 # 294
An application uses an AWS Lambda function that is configured with managed runtimes. The Lambda function successfully writes logs to the default Amazon CloudWatch Logs log group. A data engineer wants to modify the logging behavior to show only ERROR level logs for application logs and WARN level logs for system logs.
Which solution will meet these requirements?
正解:B
解説:
Option C is correct because AWS Lambda's advanced logging controls support separate application log level and system log level filtering, but AWS documentation states that for Lambda to filter application logs according to their log level, the function must use JSON formatted logs. AWS also documents that in the advanced logging configuration you can choose a log level such as ERROR for application logs and WARN for system logs. Therefore, configuring the function to use JSON log format is the necessary step that enables the required log-level filtering behavior.
Option A is irrelevant because the function already writes logs successfully. Option B alone is insufficient because changing code-level logging does not configure Lambda's separate system log filtering behavior, and Lambda's application log filtering relies on structured JSON logs. Option D changes the log destination but does not implement the required filtering levels. The official Lambda documentation makes clear that JSON log format is the enabling configuration for this feature, so that is the correct answer.
質問 # 295
A company receives .csv files that contain physical address data. The data is in columns that have the following names: Door_No, Street_Name, City, and Zip_Code. The company wants to create a single column to store these values in the following format: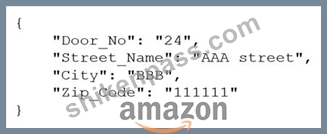
Which solution will meet this requirement with the LEAST coding effort?
正解:C
解説:
The NEST TO MAP transformation allows you to combine multiple columns into a single column that contains a JSON object with key-value pairs. This is the easiest way to achieve the desired format for the physical address data, as you can simply select the columns to nest and specify the keys for each column. The NEST TO ARRAY transformation creates a single column that contains an array of values, which is not the same as the JSON object format. The PIVOT transformation reshapes the data by creating new columns from unique values in a selected column, which is not applicable for this use case. Writing a Lambda function in Python requires more coding effort than using AWS Glue DataBrew, which provides a visual and interactive interface for data transformations. References:
* 7 most common data preparation transformations in AWS Glue DataBrew (Section: Nesting and unnesting columns)
* NEST TO MAP - AWS Glue DataBrew (Section: Syntax)
質問 # 296
......
高質のAmazon試験資料を持って、短い時間で気軽に試験に合格したいですか?そうしたら、我が社ShikenPASSのData-Engineer-Associate問題集をご覧にください。我々Data-Engineer-Associate資料はIT認定試験の改革に準じて更新していますから、お客様は改革での問題変更に心配するは全然ありません。お客様か購入する前、我が社ShikenPASSのData-Engineer-Associate問題集の見本を無料にダウンロードできます。
Data-Engineer-Associate過去問無料: https://www.shikenpass.com/Data-Engineer-Associate-shiken.html
P.S.ShikenPASSがGoogle Driveで共有している無料の2026 Amazon Data-Engineer-Associateダンプ:https://drive.google.com/open?id=13r8KNNm4iLKplcSUiiN9AxuiHpD8qVJt