Our AI-200 study materials do not have the trouble that users can't read or learn because we try our best to present those complex and difficult test sites in a simple way. As long as you learn according to the plan of our AI-200 training materials, normal learning can make you grasp the knowledge points better. Whether you are an experienced top student or a student with poor grades, our AI-200 learning guide can help you get started quickly.
| Section | Objectives |
|---|---|
| Implement and monitor AI workloads | - Deploy AI models and services - Monitor performance and troubleshoot issues |
| Plan and manage Azure AI solutions | - Plan security and compliance requirements - Select appropriate Azure AI services - Monitor and optimize AI solutions |
| Implement Azure AI solutions | - Implement computer vision solutions - Implement natural language processing solutions - Implement generative AI solutions using Azure OpenAI - Implement knowledge mining with Azure AI Search |
>> AI-200 Valid Exam Answers <<
The Exam-Killer Microsoft AI-200 exam questions is 100% verified and tested. Exam-Killer Microsoft AI-200 exam practice questions and answers is the practice test software. In Exam-Killer, you will find the best exam preparation material. The material including practice questions and answers. The information we have could give you the opportunity to practice issues, and ultimately achieve your goal that through Microsoft AI-200 Exam Certification.
NEW QUESTION # 61
A semantic search application queries Azure Database for PostgreSQL and stores document embeddings and metadata in a table with the following columns:
* embedding (pgvector)
* department
* created_at
The application must return the top five most similar documents for a given query embedding only from the finance department. You need to implement semantic retrieval with metadata filtering.
Which query components should you select? To answer, move the appropriate query components to the correct requirements. You may use each query component once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.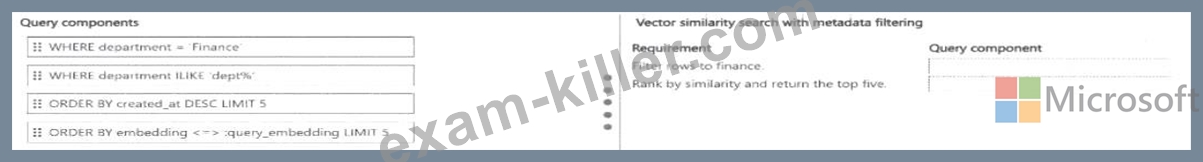
Answer:
Explanation: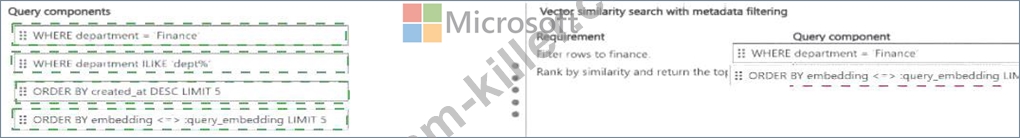
Explanation: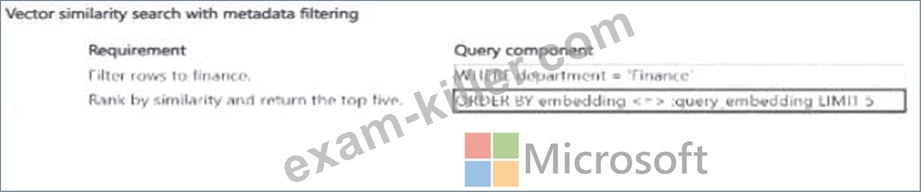
Verified Answer: Filter: `WHERE department = ' finance ' `. Rank/top five: `ORDER BY embedding < = > query_embedding LIMIT 5`.
Detailed Explanation: The metadata predicate must restrict the candidate rows to the Finance department, so the `WHERE department = ' finance ' ` component supplies the required filter. The pgvector cosine-distance operator ` < = > ` orders rows by vector distance to the supplied query embedding, and `LIMIT 5` keeps only the five nearest matches. Ordering by creation date would rank recency rather than semantic similarity, and a wildcard department filter would not satisfy the Finance-only requirement.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Vector similarity search with Azure PostgreSQL
NEW QUESTION # 62
You are reviewing an Azure Function app that processes incoming order requests for a company. The function must:
* Accept order submissions from an external client application.
* Require controlled access for security
* Return a response containing the processed request payload.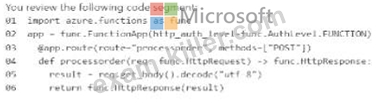
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.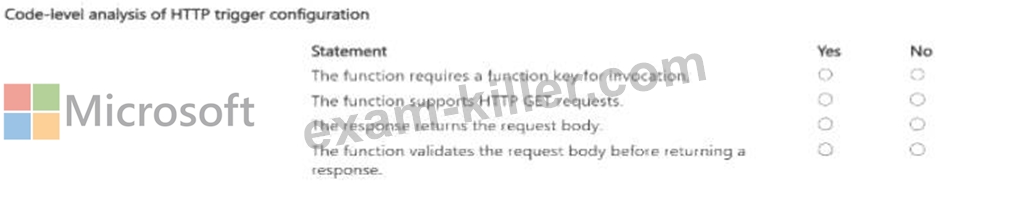
Answer:
Explanation: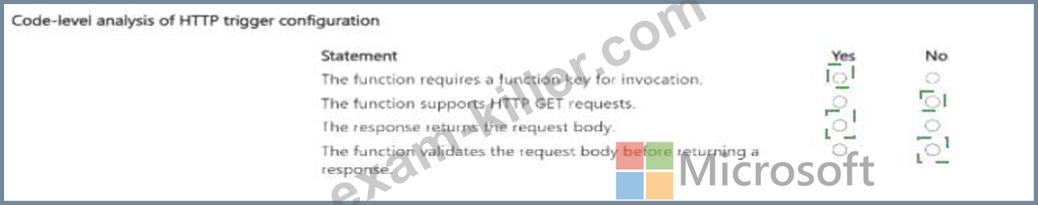
Explanation: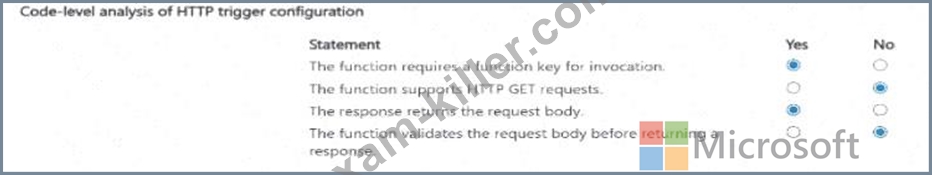
Verified Answer: Yes; No; Yes; No.
Detailed Explanation: `auth_level=FUNCTION` means invocation requires a function key unless a stronger platform authentication layer is configured, so the first statement is true. The route explicitly permits POST, not GET. The function reads `req.get_body()` and returns that value in the HttpResponse, so the response contains the request body. No schema, type, required-field, or other payload validation is performed before the response is constructed, making the final statement false.
Study Guide Alignment: Azure service integration: Service Bus, Event Grid, Azure Functions triggers
/bindings, and event-driven processing.
Official Microsoft Learn References: AI-200 Study Guide | Azure Functions HTTP trigger
NEW QUESTION # 63
You are developing several microservices to run on Azure Container Apps. External HTTP ingress traffic has been enabled for the Microservices.
A deployed microservice must be updated to allow users to test new features. You have the following requirements:
* Enable and maintain a single URL for the updated microservice to provide to test users.
* Update the microservice that corresponds to the current microservice version.
You need to configure Azure Container Apps.
Which features should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.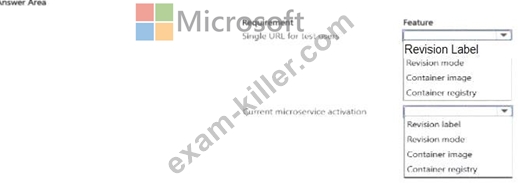
Answer:
Explanation: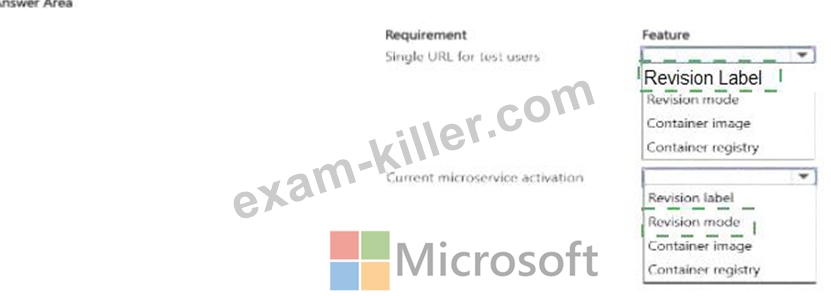
Explanation: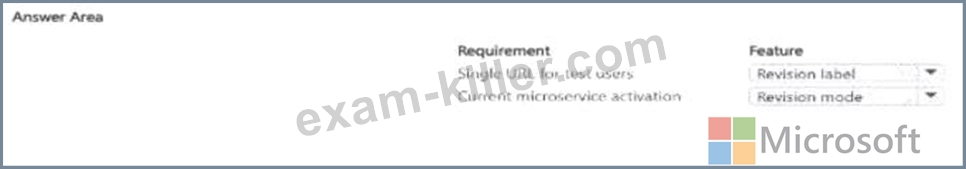
Verified Answer: Single URL for test users: Revision label. Current microservice activation behavior:
Revision mode.
Detailed Explanation: Azure Container Apps revision labels provide a stable label-specific URL that can be reassigned to a different revision, which is appropriate for a consistent test endpoint. Revision mode controls whether one or multiple revisions can be active at the same time and therefore governs how the current and updated application versions are activated. The container image and registry identify what is deployed, but they do not provide the stable test URL or the application-level revision activation behavior requested.
Study Guide Alignment: Containerized Azure workloads: registry builds, App Service containers, Container Apps revision/scaling behavior, and AKS deployment choices.
Official Microsoft Learn References: AI-200 Study Guide | Azure Container Apps revisions | Azure Container Apps revision labels
NEW QUESTION # 64
You manage an Azure Cosmos DB for a NoSQL API account named account1. The account contains a database named db1, which contains a container named container1. You configure account1 with a session consistency level.
You plan to develop an application named App1 that will access container1. Individual instances of App1 must perform reads and writes. App1 must allow multiple nodes to participate in the same session.
You need to configure an object to share the session token between the nodes.
Which object should you use?
Answer: A
NEW QUESTION # 65
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure.
The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security.
The solution must meet strict performance, scalability, and security requirements.
Current environment
Application architecture
The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
Semantic retrieval uses metadata filtering combined with vector similarity search.
Azure Managed Redis is used as a caching layer.
Front-end and API workloads are deployed to Azure Container Apps (ACA).
Batch model retraining workloads run in Azure Kubernetes Service (AKS).
Container and CI/CD
Container images are stored in Azure Container Registry (ACR).
CI/CD uses ACR Tasks to build images on commit.
ACA environments support revision management.
AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring
Logs are collected in Azure Monitor.
Teams inspect container logs and Kubernetes events when troubleshooting.
Developers write KQL queries to analyze latency spikes.
Business requirements
Customer experience: Maintain a seamless, low-latency recommendation experience for end- users, even during unpredictable seasonal traffic spikes.
Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs.
Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction.
Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets.
Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers.
Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization.
Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates.
Identity: Use managed identities for all service-to-service and service-to-database authentication.
Plain-text credentials in configuration files are strictly prohibited.
Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy.
Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero.
CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
Drag and Drop Question
You need to troubleshoot connectivity failures between microservices running in AKS.
Which troubleshooting actions should you perform? To answer, move the appropriate action to the correct troubleshooting scenario. You may use each action once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.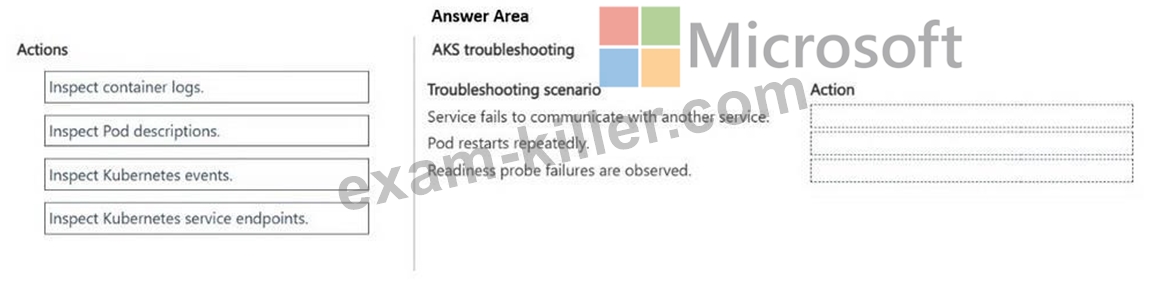
Answer:
Explanation: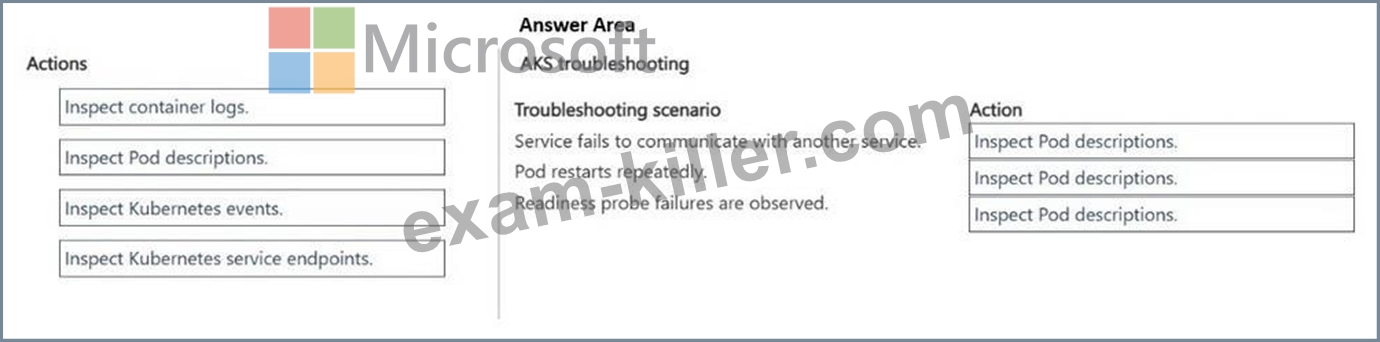
Explanation:
Box 1: Inspect Pod descriptions
Inspecting Pod descriptions is an excellent and standard first troubleshooting step to fix inter- service communication failures in Azure Kubernetes Service (AKS).
To remedy a communication failure between containerized microservices in Azure Kubernetes Service (AKS), the first and most direct troubleshooting action is to verify and debug core Kubernetes networking and DNS resolution within the cluster.
1. Check Pod Status: Ensure both the source and target pods are actively running.
Run kubectl get pods -n <namespace> to check for crash loops.
2. Verify DNS Resolution
Etc.
Box 2: Inspect Pod descriptions
To troubleshoot sudden or frequent Pod restarts in Azure Kubernetes Service (AKS), you should inspect Pod descriptions first, as they contain the Last State, Exit Code, and Reason (such as OOMKilled) for the restarted container.
Pod descriptions (Correct Choice): This is the best starting point. Running kubectl describe pod
<pod-name> provides a comprehensive status overview. It specifically reveals the Last State of the container, the Exit Code, and the Termination Reason (e.g., OOMKilled if it exceeded memory limits, or Error). It also displays the Pod's recent lifecycle events at the bottom.
Incorrect:
Container logs: While highly valuable, logs are only useful if the application managed to write an error message to stdout or stderr before crashing. If a Pod is killed externally by the system (such as an Out-Of-Memory event), the container logs will suddenly stop without showing the root cause.
Box 3: Inspect Pod descriptions
To address readiness probe failures, the most immediate and effective troubleshooting action is to inspect the Pod descriptions.
Pod descriptions: This is the correct starting point. Running kubectl describe pod <pod-name> provides a dedicated Events section at the bottom of the output. This section explicitly details exactly why a readiness probe failed, including the specific error codes, timeouts, or connection refusals, and lists the exact timestamps of the failures.
Reference:
https://blog.devgenius.io/k8s-troubleshooting-pod-in-containercreating-status-e89e093d996e?gi=e4e93cbfd5d6
https://learn.microsoft.com/en-us/troubleshoot/azure/azure-kubernetes/availability-performance/troubleshoot-oomkilled-aks-clusters
NEW QUESTION # 66
......
Do you want to spend the least time to pass your exam? If you do, then we will be your bets choice. AI-200 training materials are compiled by experienced experts who are quite familiar with the exam center, so the quality can be guaranteed. In addition, AI-200 exam materials contain most of the knowledge points for the exam, and you can have a good command of these knowledge points through practicing. In order to strengthen your confidence for the AI-200 Exam Braindumps, we are pass guarantee and money back guarantee if you fail to pass the exam. The money will be returned to your payment account.
Reliable AI-200 Dumps Free: https://www.exam-killer.com/AI-200-valid-questions.html