Die Prüfungsfragen und Antworten von It-Pruefung Microsoft DP-800 bieten Ihnen alles, was Sie zur Prüfungsvorbereitung brauchen. Für Microsoft DP-800 Prüfung können Sie auch Lernhilfe aus anderen Websites oder Büchern finden. Aber Hauptsache ist es, sie müssen logisch verbinden. Unsere Microsoft DP-800 Zertifizierungsantworten ermöglichen es Ihnen, mühelos die Prüfung zum ersten Mal zu bestehen. Zugleich können Sie auch viele wertvolle Zeit sparen.
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Microsoft Developing AI-Enabled Database Solutions (DP-800) |
| Exam Number: | DP-800 |
| Certificate Validity Period: | 1 year (Microsoft role-based certifications require annual renewal) |
| Passing Score: | 700/1000 (typical Microsoft passing score; subject to confirmation) |
| Available Languages: | English |
| Exam Format: | Multiple choice, Case studies |
| Recommended Training: | Microsoft Learn - Azure Data & AI Learning Paths |
| Exam Registration: | Microsoft Certification Dashboard |
| Sample Questions: | Microsoft DP-800 Sample Questions |
| Exam Way: | Online proctored or onsite testing center |
| Pre Condition: | No formal prerequisites required, but familiarity with Azure data services and database concepts is recommended |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/ |
Wir It-Pruefung bieten Ihnen verschiede Unterlagensversionen, die Ihre Nutzung erleichtern können. Die PDF-Versionen können das Lesen erleichtern und Ihnen die aktuellen Microsoft DP-800 Prüfungsfragen zeigen, Die Software-Versionen sind die Simulationssoftwaren, die Ihre Vorbereitungssituation auf jeden Fall testen. Wenn Sie wissen wollen, ob Sie sich für Microsoft DP-800 Prüfung gut bereit sind, können Sie helfen, Ihre Stärke und Schwäche ganz schnell finden, um Ihren nächsten Lernplan zu erstellen.
| Thema | Einzelheiten |
|---|---|
| Thema 1 |
|
| Thema 2 |
|
| Thema 3 |
|
18. Frage
You have an Azure Al Search service and an index named hotels that includes a vector Held named DescriptionVector.
You query hotels by using the Search Documents REST API.
You add semantic ranking to the hybrid search query and discover that some queries return fewer results than expected, and captions and answers are missing.
You need to complete the hybrid search request to meet the following requirements:
* Include more documents when ranking.
* Always include captions and answers.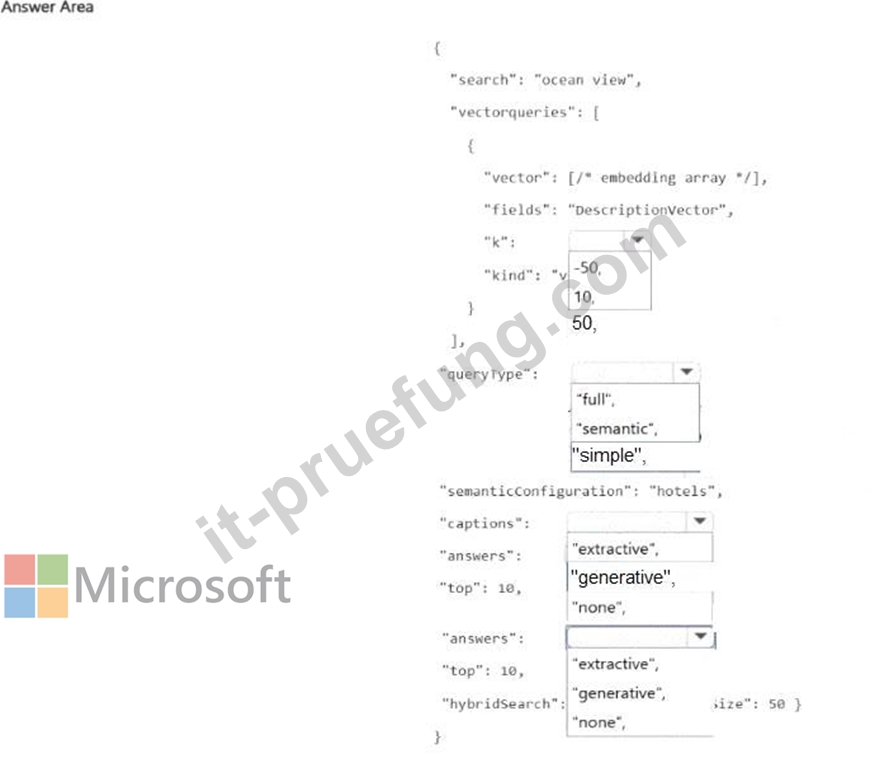
Antwort:
Begründung: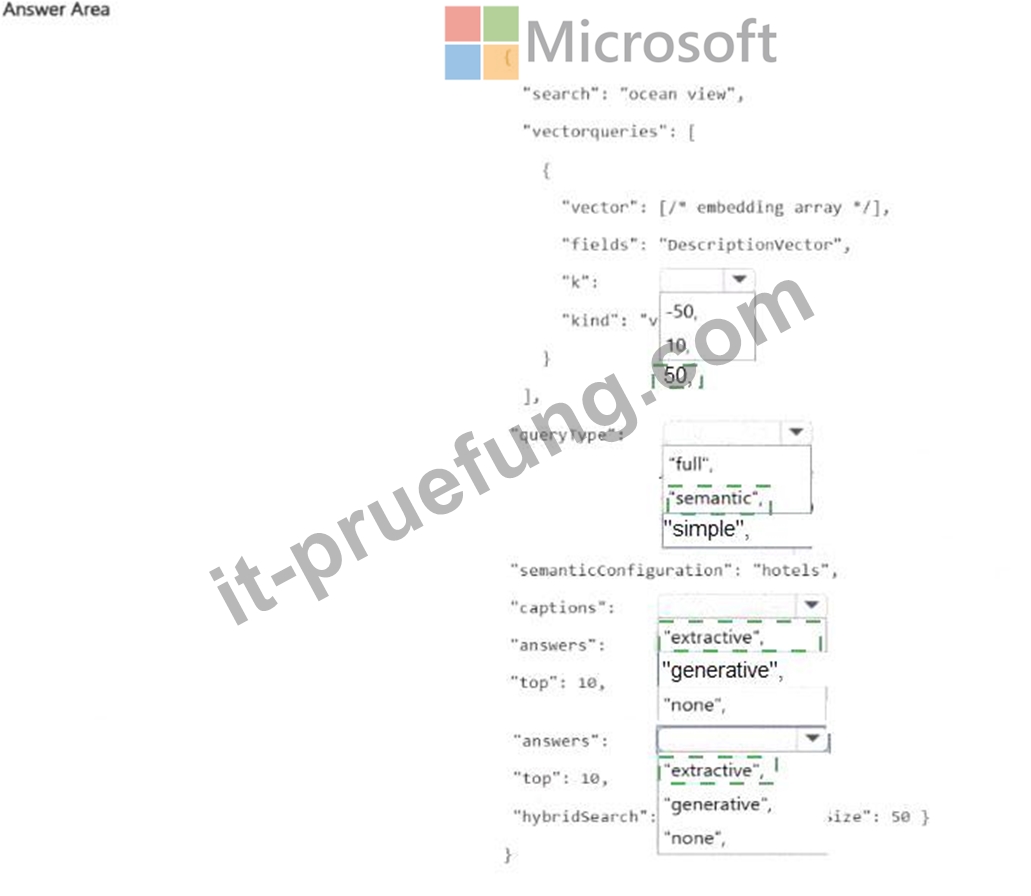
Explanation: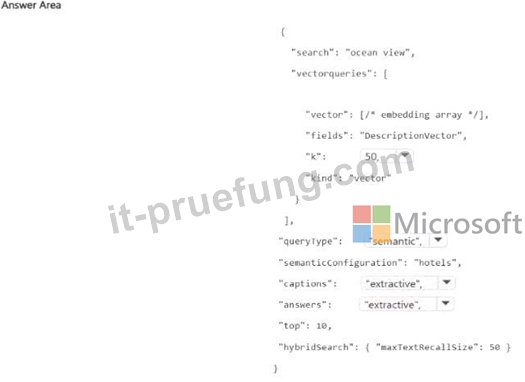
These are the correct selections for a hybrid query that uses semantic ranking in Azure AI Search.
Use k = 50 because Microsoft explicitly recommends that when you combine semantic ranking with vector queries , you should set k to 50 so the semantic ranker has enough candidates to rerank. If you use a smaller value such as 10, semantic ranking can receive too few inputs, which is exactly why some queries return fewer results than expected.
Use queryType = " semantic " because captions and answers are only available on semantic queries.
Microsoft documents that captions is valid only when the query type is semantic, and semantic answers are returned only for semantic queries.
Use captions = " extractive " because semantic captions are extractive passages pulled from the top-ranked documents. Microsoft's REST documentation states that the valid captions option here is extractive and that it defaults to none if not specified.
Use answers = " extractive " because semantic answers in Azure AI Search are extractive, not generated.
Microsoft documents that semantic answers are verbatim passages recognized as answers and the REST API lists extractive as the answer-return option.
19. Frage
You have an Azure SQL database that contains a table named dbo.Products. dbo.Products contains three columns named Embedding, Category, and Price. The Embedding column is defined as VECTOR(1536).
You use AI_GENERATE_EMBEDDINGS and VECTOR_SEARCH to support semantic search and apply additional filters on two columns named Category and Price.
You plan to change the embedding model from text-embedding-ada-002 to text-embedding-3- small. Existing rows already contain embeddings in the Embedding column.
You need to implement the model change. Applications must be able to use VECTOR_SEARCH without runtime errors.
What should you do first?
Antwort: D
Begründung:
To ensure your applications can transition models without runtime errors while using VECTOR_SEARCH, you must first define a Vector Index that explicitly identifies the dimensions and distance metric.
Since you are moving from text-embedding-ada-002 to text-embedding-3-small, both models default to 1536 dimensions, which matches your existing column definition. To create the index as the first step, use the following SQL:
CREATE VECTOR INDEX idx_embedding ON YourTableName (Embedding)
WITH ( DISTANCE_METRIC = 'COSINE' );
Use code with caution.
Why this works:
Schema Consistency: Because both models use 1536 dimensions, you don't need to alter the VECTOR(1536) column type immediately.
Search Stability: Creating the index allows the engine to optimize the VECTOR_SEARCH function. As long as the incoming query vector (generated by the app) matches the dimensions of the stored vectors, the search will execute without a runtime dimension mismatch error.
Reference:
https://docs.couchbase.com/cloud/n1ql/n1ql-language-reference/vectorfun.html
20. Frage
You have an Azure SQL database named SalesDB that supports an AI-enabled product search application.
SalesDB has a table named SalesLT.Product that contains the following columns:
* ProductID (int)
* Name (nvarchar(100))
* ListPrice (decimal(18,2))
You need to create an object that returns products priced above a caller-provided threshold. The solution must meet the following requirements:
* Support being used in a join.
* Accept one input parameter.
* Return a table result.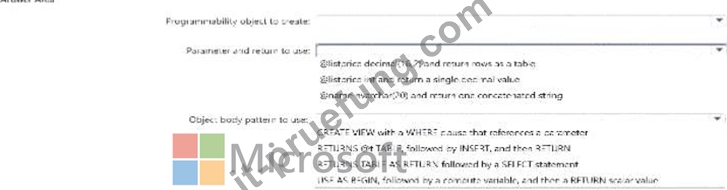
Antwort:
Begründung: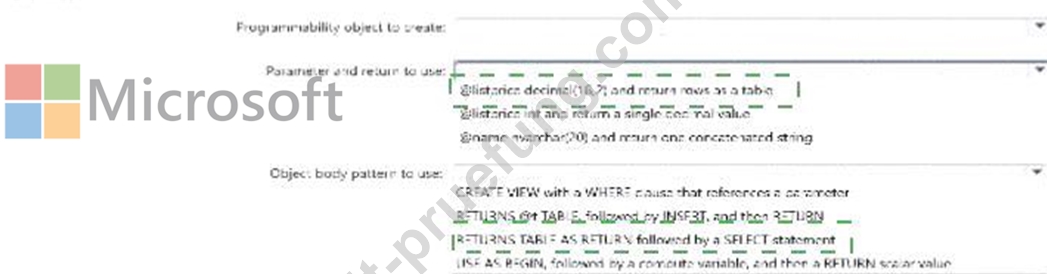
Explanation: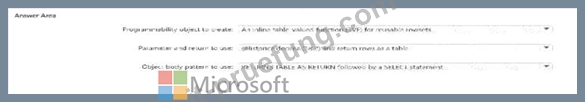
21. Frage
You have an Azure SQL database that has Query Store enabled
Query Performance Insight shows that one stored procedure has the longest runtime. The procedure runs the following parameterized query.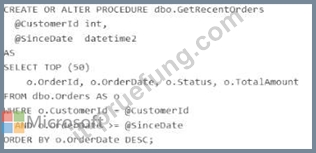
The dbo.orders table has approximately 120 million rows. Customer-id is highly selective, and orderOate is used for range filtering and sorting.
Vou have the following indexes:
* Clustered index: PK_Orders on (Orderld)
* Nonclustered index: lx_0rders_order-Date on (OrderDate) with no included columns An actual execution plan captured from Query Store for slow runs shows the following:
* An index seek on ixordersorderDate followed by a Key Lookup (Clustered) on PKOrders for customerid, status, and TotalAnount
* A sort operator before top (50), because the results are ordered by orderDate DESC For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.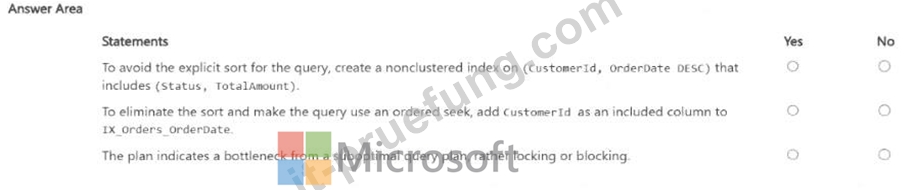
Antwort:
Begründung: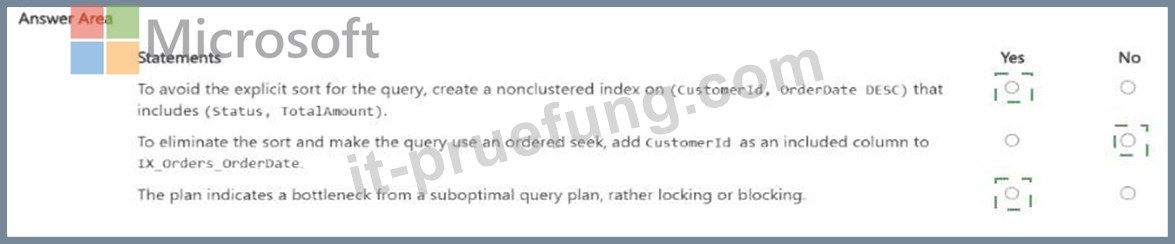
Explanation: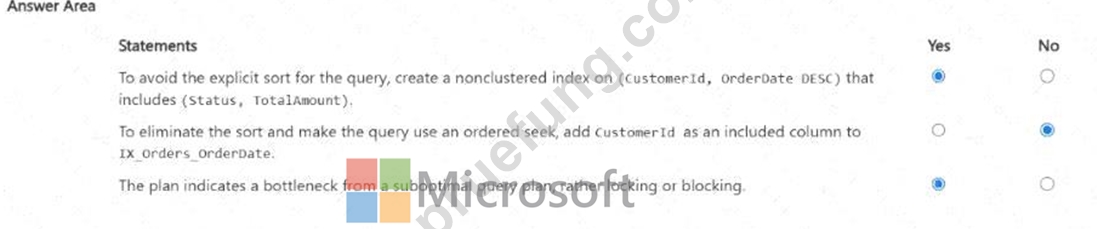
The first statement is Yes . The query filters on CustomerId, applies a range predicate on OrderDate, and sorts by OrderDate DESC. Microsoft's index design guidance recommends putting equality predicates first in the key, followed by columns used for ordering/range access, because the order of key columns determines seek and sort support. A nonclustered index on (CustomerId, OrderDate DESC) can support an ordered seek for this query and avoid the explicit sort. Including Status and TotalAmount helps cover the query, and OrderId is already available because the clustered key is stored with nonclustered index rows.
The second statement is No . Adding CustomerId as an included column to IX_Orders_OrderDate does not make it part of the index's navigational structure. Microsoft states that included columns are nonkey columns used to cover queries; they do not provide the seek and ordering characteristics that key columns do. So an index keyed only on OrderDate still is not the right ordered access path for WHERE CustomerId =
@CustomerId ... ORDER BY OrderDate DESC.
The third statement is Yes . The described actual plan shows an index seek on the wrong access path for the workload, followed by clustered key lookups and an explicit sort before TOP (50). That is characteristic of a suboptimal query/index plan . Query Store and Query Performance Insight are designed to surface plan- related performance regressions, while locking/blocking problems are typically identified through waits
/DMVs and blocking-session indicators, not from a plan shape like seek + lookup + sort alone.
22. Frage
Drag and Drop Question
You have an Azure SQL database named SalesDB. SalesDB contains a table named dbo.Articles. dbo.Articles contains the following columns:
- ArticleId
- Title
- Body
- LastModifiedUtc
- EmbeddingVector
You have an application that generates embeddings from the concatenation of Title and Body and stores the results in EmbeddingVector.
You plan to implement an incremental embedding maintenance method that will use change data capture (CDC) to update embeddings only for rows that change, without scanning the entire table.
You need to ensure that only the columns required to generate the embeddings are captured.
The solution must support querying net changes.
How should you complete the Transact-SQL script? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.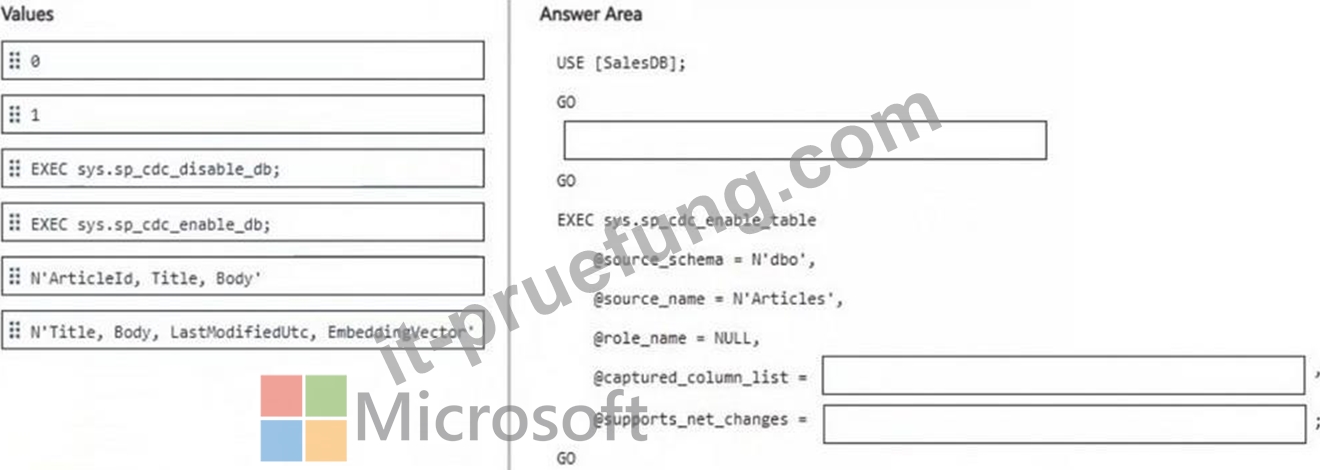
Antwort:
Begründung: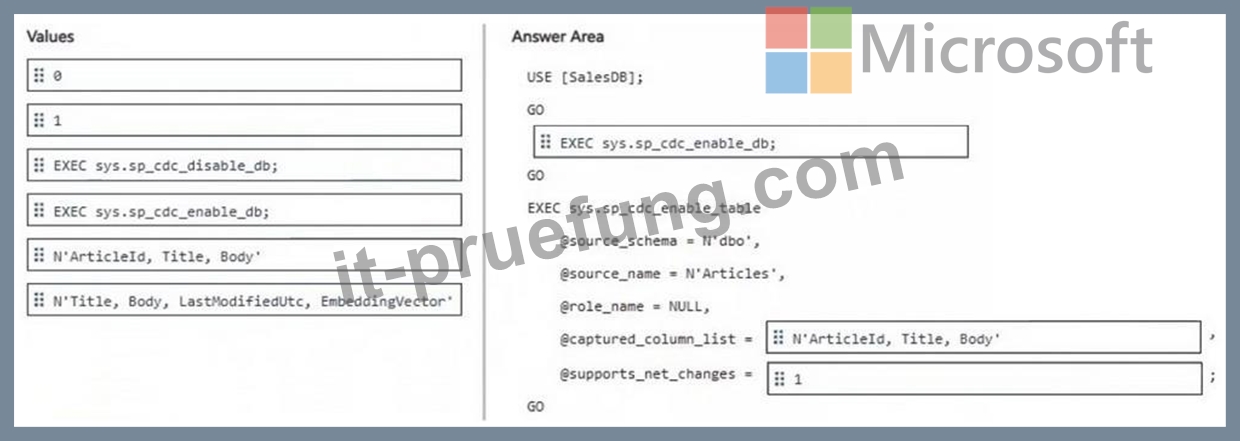
23. Frage
......
DP-800 PDF Demo: https://www.it-pruefung.com/DP-800.html