What's more, part of that Actual4Labs DP-600 dumps now are free: https://drive.google.com/open?id=1e7v6erZa26rf4zzgUv7vbbJqB7Lq0biM
For a guaranteed path to success in the Implementing Analytics Solutions Using Microsoft Fabric (DP-600) certification exam, Actual4Labs offers a comprehensive collection of highly probable Microsoft DP-600 Exam Questions. Our practice questions are meticulously updated to align with the latest exam content, enabling you to prepare efficiently and effectively for the DP-600 examination. Don't leave your success to chance—trust our reliable resources to maximize your chances of passing the Microsoft DP-600 exam with confidence.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> Simulation DP-600 Questions <<
Our DP-600 guide questions have the most authoritative test counseling platform, and each topic in DP-600 practice engine is carefully written by experts who are engaged in researching in the field of professional qualification exams all the year round. They have a very keen sense of change in the direction of the exam, so that they can accurately grasp the important points of the DP-600 Exam. And you will pass the exam for the DP-600 exam questions are all keypoints.
NEW QUESTION # 107
You have a Fabric tenant that contains a data warehouse named DW1. DW1 contains a table named DimCustomer. DimCustomer contains the fields shown in the following table.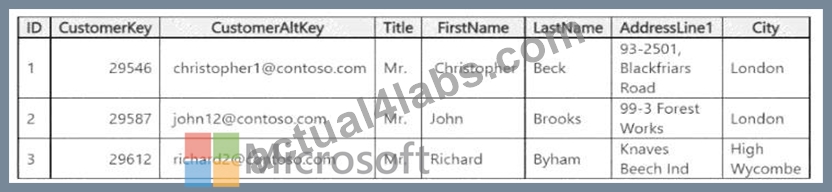
You need to identify duplicate email addresses in DimCustomer. The solution must return a maximum of
1,000 records.
Which four T-SQL statements should you run in sequence? To answer, move the appropriate statements from the list of statements to the answer area and arrange them in the correct order.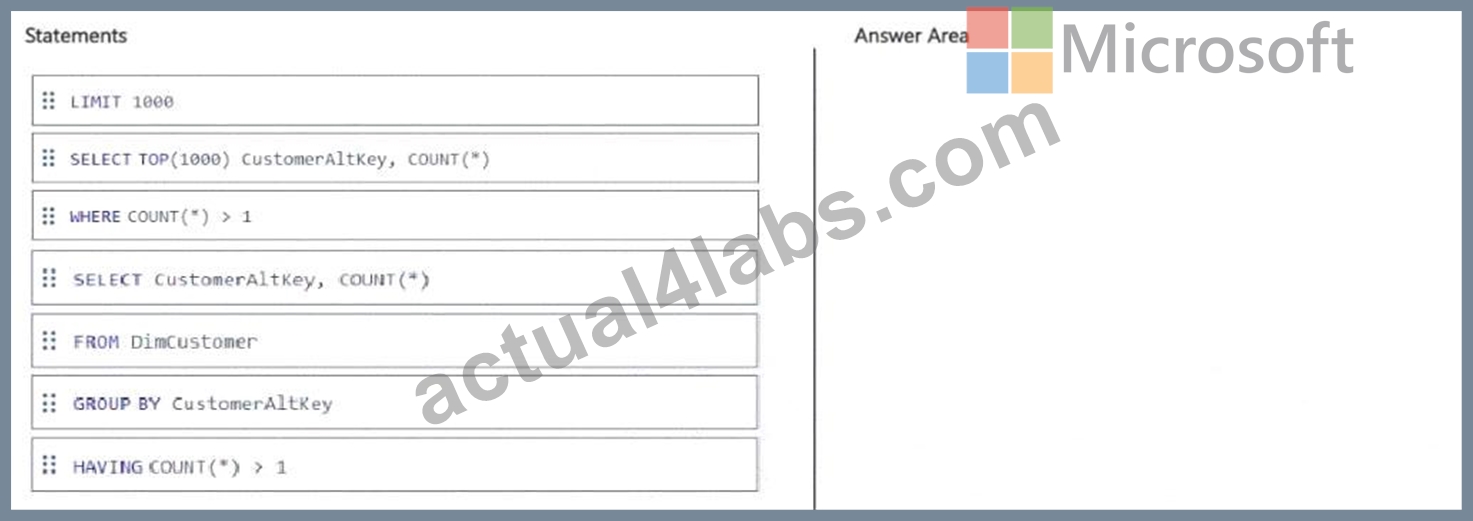
Answer:
Explanation: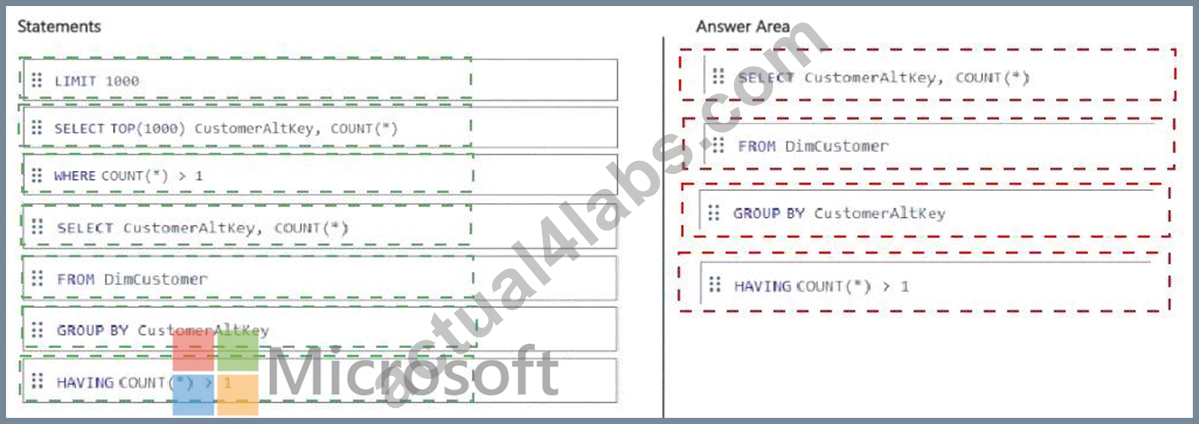
Explanation: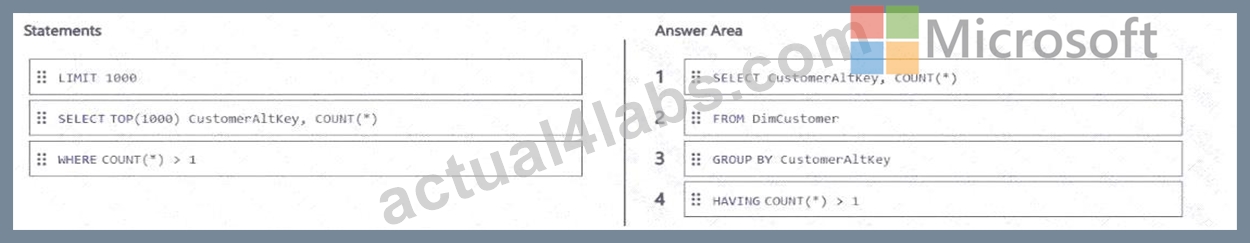
Step 1 - Select the required fields and count
We want to group by CustomerAltKey and count occurrences.
SELECT CustomerAltKey, COUNT(*)
Step 2 - From the table
FROM DimCustomer
Step 3 - Grouping by email
GROUP BY CustomerAltKey
Step 4 - Filtering duplicates (only values with count > 1)
HAVING COUNT(*) > 1
Step 5 - Limiting the result to 1,000 rows
LIMIT 1000
(or in T-SQL, SELECT TOP(1000) ...). Since both options are shown, we use LIMIT 1000 because Fabric Warehouse supports Synapse SQL T-SQL + ANSI SQL style.
Correct Sequence:
SELECT CustomerAltKey, COUNT(*)
FROM DimCustomer
GROUP BY CustomerAltKey
HAVING COUNT(*) > 1
LIMIT 1000
NEW QUESTION # 108
You have a Fabric tenant that contains the workspaces shown in the following table.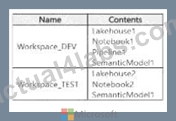
You have a deployment pipeline named Pipeline1 that deploys items from Workspace_DEV to Workspace_TEST. In Pipeline1, all items that have matching names are paired.
You deploy the contents of Workspace_DEV to Workspace_TEST by using Pipeline1.
What will the contents of Workspace_TEST be once the deployment is complete?
Answer: A
Explanation:
Workspace_DEV contents:
Lakehouse1, Notebook1, Pipeline1, SemanticModel1
Workspace_TEST contents (before deployment):
Lakehouse2, Notebook2, SemanticModel1
After deployment:
SemanticModel1 # same name, so it will be paired and overwritten with the DEV version.
Lakehouse1 and Notebook1 # new items, so they will be added to TEST.
Lakehouse2 and Notebook2 # remain because they don't conflict in name.
Pipeline1 # new item, so it will also be added .
So the final content is:
Lakehouse1, Lakehouse2, Notebook1, Notebook2, Pipeline1, SemanticModel1
NEW QUESTION # 109
You need to implement the date dimension in the data store. The solution must meet the technical requirements.
What are two ways to achieve the goal? Each correct answer presents a complete solution.
NOTE: Each correct selection is worth one point.
Answer: A,D
Explanation:
Both a dataflow (A) and a Stored procedure activity in a pipeline (B) are capable of creating and populating a date dimension table. A dataflow can perform the transformation needed to create the date dimension, and it aligns with the preference for using low-code tools for data ingestion when possible. A Stored procedure could be written to generate the necessary date dimension data and executed within a pipeline, which also adheres to the technical requirements for the PoC.
Topic 1, Litware. Inc. Case Study
Overview
Litware. Inc. is a manufacturing company that has offices throughout North America. The analytics team at Litware contains data engineers, analytics engineers, data analysts, and data scientists.
Existing Environment
litware has been using a Microsoft Power Bl tenant for three years. Litware has NOT enabled any Fabric capacities and features.
Fabric Environment
Litware has data that must be analyzed as shown in the following table.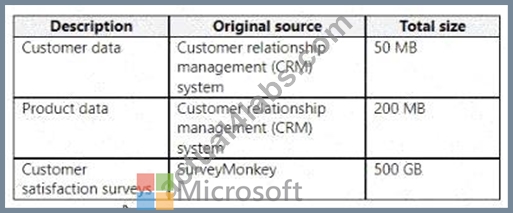
The Product data contains a single table and the following columns.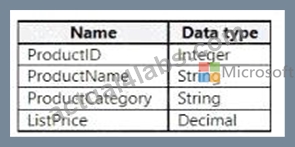
The customer satisfaction data contains the following tables:
* Survey
* Question
* Response
For each survey submitted, the following occurs:
* One row is added to the Survey table.
* One row is added to the Response table for each question in the survey.
The Question table contains the text of each survey question. The third question in each survey response is an overall satisfaction score. Customers can submit a survey after each purchase.
User Problems
The analytics team has large volumes of data, some of which is semi-structured. The team wants to use Fabric to create a new data store.
Product data is often classified into three pricing groups: high, medium, and low. This logic is implemented in several databases and semantic models, but the logic does NOT always match across implementations.
Planned Changes
Litware plans to enable Fabric features in the existing tenant. The analytics team will create a new data store as a proof of concept (PoC). The remaining Litware users will only get access to the Fabric features once the PoC is complete. The PoC will be completed by using a Fabric trial capacity.
The following three workspaces will be created:
* AnalyticsPOC: Will contain the data store, semantic models, reports, pipelines, dataflows, and notebooks used to populate the data store
* DataEngPOC: Will contain all the pipelines, dataflows, and notebooks used to populate Onelake
* DataSciPOC: Will contain all the notebooks and reports created by the data scientists The following will be created in the AnalyticsPOC workspace:
* A data store (type to be decided)
* A custom semantic model
* A default semantic model
* Interactive reports
The data engineers will create data pipelines to load data to OneLake either hourly or daily depending on the data source. The analytics engineers will create processes to ingest transform, and load the data to the data store in the AnalyticsPOC workspace daily. Whenever possible, the data engineers will use low-code tools for data ingestion. The choice of which data cleansing and transformation tools to use will be at the data engineers ' discretion.
All the semantic models and reports in the Analytics POC workspace will use the data store as the sole data source.
Technical Requirements
The data store must support the following:
* Read access by using T-SQL or Python
* Semi-structured and unstructured data
* Row-level security (RLS) for users executing T-SQL queries
Files loaded by the data engineers to OneLake will be stored in the Parquet format and will meet Delta Lake specifications.
Data will be loaded without transformation in one area of the AnalyticsPOC data store. The data will then be cleansed, merged, and transformed into a dimensional model.
The data load process must ensure that the raw and cleansed data is updated completely before populating the dimensional model.
The dimensional model must contain a date dimension. There is no existing data source for the date dimension. The Litware fiscal year matches the calendar year. The date dimension must always contain dates from 2010 through the end of the current year.
The product pricing group logic must be maintained by the analytics engineers in a single location. The pricing group data must be made available in the data store for T-SQL queries and in the default semantic model. The following logic must be used:
* List prices that are less than or equal to 50 are in the low pricing group.
* List prices that are greater than 50 and less than or equal to 1,000 are in the medium pricing group.
* List pnces that are greater than 1,000 are in the high pricing group.
Security Requirements
Only Fabric administrators and the analytics team must be able to see the Fabric items created as part of the PoC. Litware identifies the following security requirements for the Fabric items in the AnalyticsPOC workspace:
* Fabric administrators will be the workspace administrators.
* The data engineers must be able to read from and write to the data store. No access must be granted to datasets or reports.
* The analytics engineers must be able to read from, write to, and create schemas in the data store. They also must be able to create and share semantic models with the data analysts and view and modify all reports in the workspace.
* The data scientists must be able to read from the data store, but not write to it. They will access the data by using a Spark notebook.
* The data analysts must have read access to only the dimensional model objects in the data store. They also must have access to create Power Bl reports by using the semantic models created by the analytics engineers.
* The date dimension must be available to all users of the data store.
* The principle of least privilege must be followed.
Both the default and custom semantic models must include only tables or views from the dimensional model in the data store. Litware already has the following Microsoft Entra security groups:
* FabricAdmins: Fabric administrators
* AnalyticsTeam: All the members of the analytics team
* DataAnalysts: The data analysts on the analytics team
* DataScientists: The data scientists on the analytics team
* Data Engineers: The data engineers on the analytics team
* Analytics Engineers: The analytics engineers on the analytics team
Report Requirements
The data analysis must create a customer satisfaction report that meets the following requirements:
* Enables a user to select a product to filter customer survey responses to only those who have purchased that product
* Displays the average overall satisfaction score of all the surveys submitted during the last 12 months up to a selected date
* Shows data as soon as the data is updated in the data store
* Ensures that the report and the semantic model only contain data from the current and previous year
* Ensures that the report respects any table-level security specified in the source data store
* Minimizes the execution time of report queries
NEW QUESTION # 110
You have the source data model shown in the following exhibit.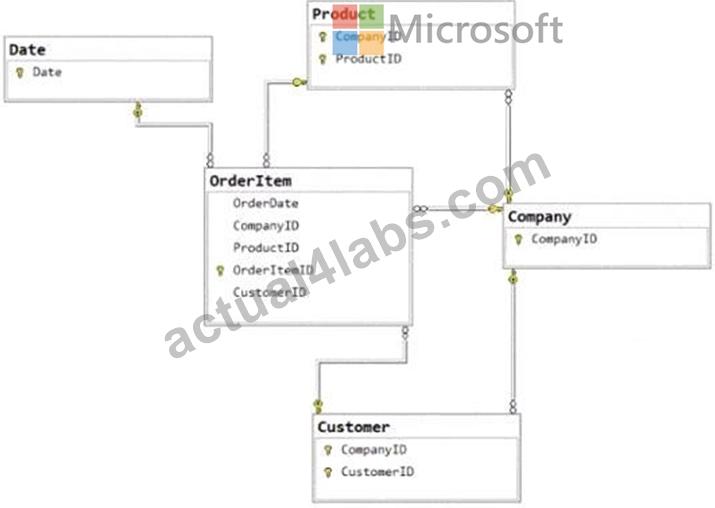
The primary keys of the tables are indicated by a key symbol beside the columns involved in each key.
You need to create a dimensional data model that will enable the analysis of order items by date, product, and customer.
What should you include in the solution? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.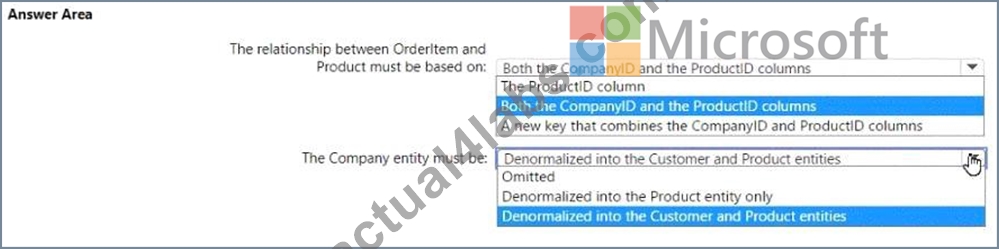
Answer:
Explanation: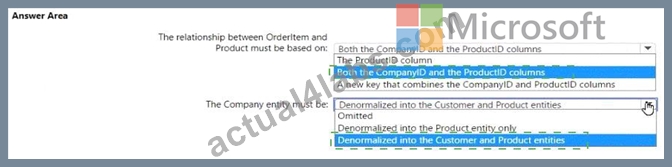
Explanation: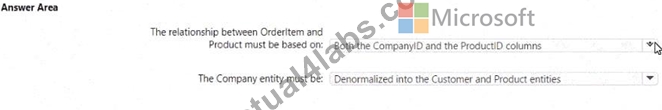
The relationship between OrderItem and Product must be based on: Both the CompanyID and the ProductID columns The Company entity must be: Denormalized into the Customer and Product entities In a dimensional model, the relationships are typically based on foreign key constraints between the fact table (OrderItem) and dimension tables (Product, Customer, Date). Since CompanyID is present in both the OrderItem and Product tables, it acts as a foreign key in the relationship. Similarly, ProductID is a foreign key that relates these two tables. To enable analysis by date, product, and customer, the Company entity would need to be denormalized into the Customer and Product entities to ensure that the relevant company information is available within those dimensions for querying and reporting purposes.
References =
Dimensional modeling
Star schema design
NEW QUESTION # 111
You have a Fabric workspace named Workspace1 and a warehouse named Warehouse1.
Workspace1 contains a user named User1. User1 is assigned the Viewer role for Workspace1.
You need to ensure that User1 can share Warehouse1 with other users. The solution must follow the principle of least privilege.
Which role should you assign to User1?
Answer: B
Explanation:
To allow a Viewer to share a Warehouse while following the Principle of Least Privilege, you should assign the user the Member role.
The Member role is the lowest-level workspace role that includes the permission to share items (including Warehouses).
Permission to Share: Unlike Viewers or Contributors, Members can share items and manage permissions for those items.
Restricted Control: Members cannot delete the workspace, change its settings, or manage the roles of Admins/Members (unlike the Admin role).
Infrastructure Isolation: It provides the necessary administrative authority over content without giving full "owner" rights to the entire workspace environment.
Reference:
https://www.linkedin.com/pulse/understanding-role-based-access-control-rbac-fabric-abiola- uw8oe
NEW QUESTION # 112
......
Don't waste much more time on preparing for a test. Hurry to purchase Actual4Labs Microsoft DP-600 certification training dumps. With the exam dumps, you will know how to effectively prepare for your exam. This is precious tool that can let you sail through DP-600 test with no mistakes. Missing the chance, I am sure you must regret it. Thus, don't hesitate and act quickly.
DP-600 Guide: https://www.actual4labs.com/Microsoft/DP-600-actual-exam-dumps.html
DOWNLOAD the newest Actual4Labs DP-600 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1e7v6erZa26rf4zzgUv7vbbJqB7Lq0biM