認めなければならないことは、あなたが所有する認定資格がますます増えていることです。 これが、DP-750認定を取得することの重要性を認識する必要がある理由です。 私たちの将来の雇用のためのより資格のある認定は、彼らの能力を証明するのに十分な資格認定を持っているだけで、社会的競争でライバルに勝つことができると見なされる効果があります。 したがって、DP-750ガイド急流は、ユーザーがより速く、より効率的に参加するために必要な資格のあるDP-750試験に合格するのに役立ちます。
| Section | Weight | Objectives |
|---|---|---|
| Prepare and process data | 30-35% | - Data transformation and modeling
|
| Deploy and manage data pipelines and workloads | 30-35% | - Lakehouse architecture operations
|
| Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
| Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
現在の仕事にまだ満足していますか?あなたはまだあなたの仕事にうまく対処する能力を持っていますか?同じ分野で働いている人々と比較したときに、競争上の優位性があるかどうかを考えますか?あなたの答えがいいえなら、あなたは今正しい場所です。私たちのDP-750試験トレントはあなたの良いパートナーであり、あなたは満足していない仕事を変更する機会があり、私たちのDP-750ガイド質問であなたの能力を高めることができるので、あなたはDP-750試験に合格します目標を達成します。 DP-750試験問題のデモを無料でダウンロードしてください!
質問 # 87
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.dropna(subset=["order_amount"])
Does this meet the goal?
正解:A
解説:
The correct answer is A - Yes.
df.dropna(subset=['order_amount']) is the idiomatic PySpark way to remove rows where a specific column contains a null. It inspects only the columns listed in subset and drops any row where those columns are null.
The resulting DataFrame contains only rows where order_amount is not null - exactly what the requirement asks for.
The subset parameter is important: without it, dropna() would drop rows where ANY column is null, which could incorrectly exclude rows that have nulls in other columns but a valid order_amount. By specifying subset=['order_amount'], the filter is applied precisely and only to the column in question.
This method is semantically equivalent to df.filter(df.order_amount.isNotNull()) and to the SQL clause WHERE order_amount IS NOT NULL. Both are correct - dropna with a subset is arguably the more readable Pythonic approach.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
質問 # 88
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a catalog named finance, finance contains two schemas named default and procurement.
You need to create a table named assets in the procurement schema, assets must contain the following columns:
* asset.id
* asset, type
* asset_name
How should you complete the SQL statement? To answer, drag the appropriate values to the correct targets.
Each value may be used once, more than once, or not at all You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.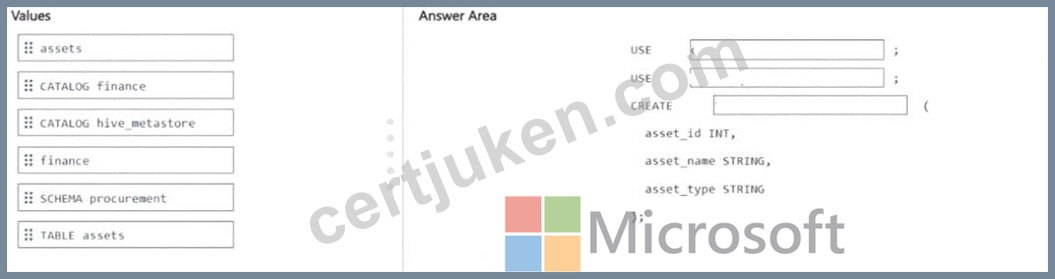
正解:
解説: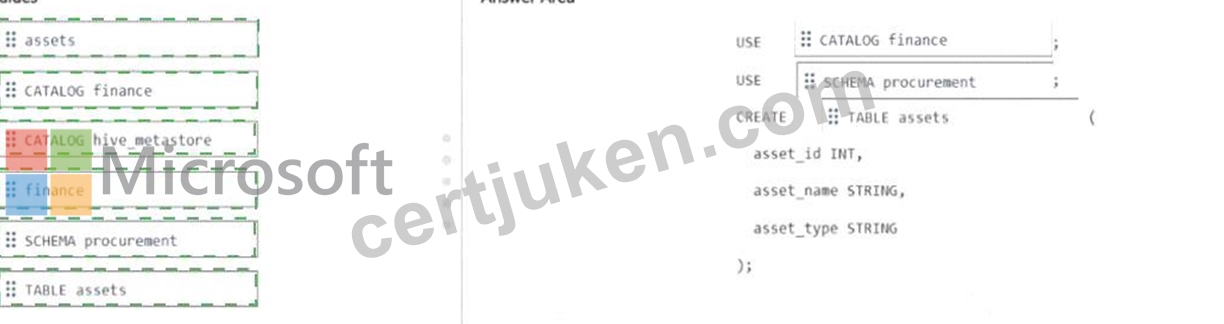
Explanation:
The correct SQL statement uses the full three-part namespace finance.procurement.assets with the three specified columns.
In Unity Catalog, every object lives in a three-tier hierarchy: catalog # schema # table. Using the full path finance.procurement.assets guarantees the table lands in the right schema regardless of the session's current catalog or schema context. Omitting the catalog or schema name relies on the session default, which may not be finance.procurement - a silent mistake that's hard to catch.
The column names asset_id, asset_type, and asset_name must match the spec exactly. Unity Catalog applies access controls, lineage tracking, and tagging at the column level, so the names are meaningful beyond just the schema. Once created, any GRANT statements can target specific columns for fine-grained access control.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/sql-ref-syntax-ddl-create- table-using
質問 # 89
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job! processes raw data files stored in Azure Storage.
New files arrive at unpredictable intervals.
You need to ensure that Job1 starts automatically when new files arrive and does NOT consume compute resources when no data is available.
Which type of job trigger should you use?
正解:A
解説:
The correct answer is C - File Arrival trigger.
File Arrival monitors a specified Azure Storage path and fires a job run each time a new file lands there. This ticks both requirements: Job1 starts automatically in response to new data (no human involvement), and when no files arrive, no job runs - no cluster spins up, no compute cost is incurred.
Option A (scheduled) runs at fixed intervals regardless of whether files are waiting. A quiet weekend still kicks off hourly (or daily) runs, burning compute for nothing. Option B (continuous) keeps the job running perpetually, consuming resources even during long gaps between file arrivals - exactly what 'does NOT consume compute resources when no data is available' rules out. Option D (manual) requires a person to trigger every run, which is unsuitable for unpredictable arrival patterns.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/triggers#file-arrival-trigger
質問 # 90
You have an Azure Databricks workspace that contains an all-purpose cluster named Cluster! You need to configure Cluster1 to meet the following requirements;
* The cluster must scale up automatically when workloads increase.
* The cluster must scale down automatically when workloads decrease.
The solution must minimize costs.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
正解:B、D
解説:
The correct answers are C and D. Together they deliver cost-efficient autoscaling:
D (Enable autoscaling) allows the cluster to grow when workloads increase and shrink when they ease off.
This satisfies both scale-up and scale-down requirements without manual intervention.
C (Auto-termination after 30 minutes of inactivity) ensures the cluster stops entirely when no work is running, eliminating the cost of an idle cluster. This is the cheapest possible state.
Option A (disable Photon) reduces compute acceleration - that's a performance regression with no meaningful cost benefit for autoscaling. Option B (compute policy that lets users manage settings) adds governance overhead and doesn't address scaling behaviour. Option E (fixed number of workers) is the opposite of autoscaling - a static worker count that either over-provisions during quiet periods or under- provisions during peaks.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/configure#autoscaling
質問 # 91
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.filter(df.order_amount.isNotNull())
Does this meet the goal?
正解:A
解説:
Correct:
* You run the following expression.
df.dropna(subset=["order_amount"])
The expression df.dropna(subset=["order_amount"]) is an appropriate and effective way to exclude rows where order_amount is null.
* You run the following expression.
df.filter(df.order_amount.isNotNull())
To exclude rows where the order amount is null, you can use the isNotNull() method or a SQL expression within the filter() or where() functions.Here are the standard, appropriate expressions:
Option 1: Python/PySpark API (Recommended)
pythondf_clean = df.filter(df["order_amount"].isNotNull())
Incorrect:
* You run the following expression.
df.fillna(0, subset=['order_amount'])
* You run the following expression.
df.filter(df.order_amount != None)
Reference:
https://www.geeksforgeeks.org/python/filter-pyspark-dataframe-columns-with-none-or-null-values/
https://learn.microsoft.com/en-us/azure/databricks/pyspark/reference/classes/dataframe/dropna
質問 # 92
......
形式に関するDP-750試験問題の3つの異なるバージョンがあります:PDF、ソフトウェア、オンラインAPP。内容は同じですが、さまざまな形式が実際にお客様に多くの利便性をもたらします。 PDFバージョンのDP-750試験の練習問題を印刷して、どこにいても受験できるようにすることができます。また、ソフトウェアバージョンは実際の試験環境をシミュレートし、オフラインでの練習をサポートできます。また、APPオンラインはあらゆる種類の電子機器に適用できます。誰であっても、DP-750準備の質問を通じて、あなたの目標を達成するために最善を尽くすことができると信じています!
DP-750関連日本語版問題集: https://www.certjuken.com/DP-750-exam.html