BTW, DOWNLOAD part of Pass4guide DP-600 dumps from Cloud Storage: https://drive.google.com/open?id=1ledcPWBWhv3llnogIJl7MeRyNaLiw6u3
By updating the study system of the DP-600 study materials, we can guarantee that our company can provide the newest information about the exam for all people. We believe that getting the newest information about the exam will help all customers pass the DP-600 Exam easily. If you purchase our study materials, you will have the opportunity to get the newest information about the DP-600 exam. More importantly, the updating system of our company is free for all customers.
| Section | Weight | Objectives |
|---|---|---|
| Implement and manage semantic models | 25–30 | - Design and build semantic models
|
| Maintain a data analytics solution | 25–30 | - Implement security and governance
|
| Prepare data for analytics | 45–50 | - Implement data storage structures
|
>> Microsoft DP-600 Valid Test Forum <<
No doubt the Implementing Analytics Solutions Using Microsoft Fabric (DP-600) certification is one of the most challenging certification exams in the market. This Microsoft DP-600 certification exam gives always a tough time to Implementing Analytics Solutions Using Microsoft Fabric (DP-600) exam candidates. The Pass4guide understands this hurdle and offers recommended and real Microsoft DP-600 exam practice questions in three different formats.
NEW QUESTION # 47
You have a Fabric tenant that contains a lakehouse named Lakehouse1
Readings from 100 loT devices are appended to a Delta table in Lakehouse1. Each set of readings is approximately 25 KB. Approximately 10 GB of data is received daily.
All the table and SparkSession settings are set to the default.
You discover that queries are slow to execute. In addition, the lakehouse storage contains data and log files that are no longer used.
You need to remove the files that are no longer used and combine small files into larger files with a target size of 1 GB per file.
What should you do? To answer, drag the appropriate actions to the correct requirements. Each action may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.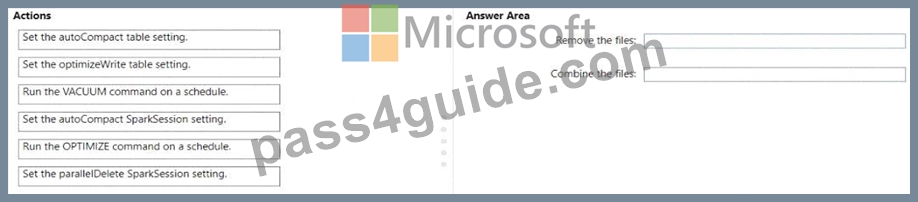
Answer:
Explanation: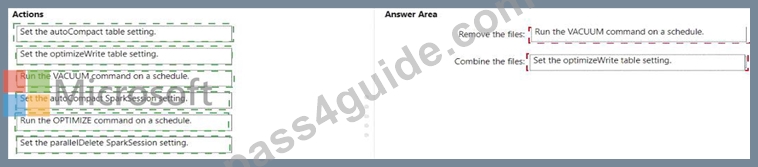
Explanation:
* Remove the files: Run the VACUUM command on a schedule.
* Combine the files: Set the optimizeWrite table setting. or Run the OPTIMIZE command on a schedule.
To remove files that are no longer used, the VACUUM command is used in Delta Lake to clean up invalid files from a table. To combine smaller files into larger ones, you can either set the optimizeWrite setting to combine files during write operations or use the OPTIMIZE command, which is a Delta Lake operation used to compact small files into larger ones.
NEW QUESTION # 48
You have a Fabric tenant that contains a lakehouse named LH1.
You need to deploy a new semantic model. The solution must meet the following requirements:
* Support complex calculated columns that include aggregate functions, calculated tables, and Multidimensional Expressions (MDX) user hierarchies.
* Minimize page rendering times.
How should you configure the model? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.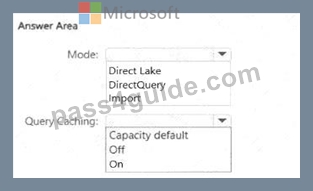
Answer:
Explanation: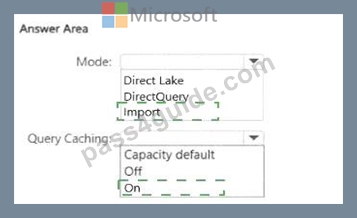
Explanation: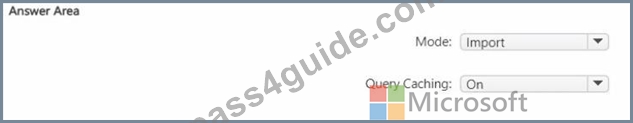
Supports complex calculated columns (with aggregate functions, calculated tables, MDX hierarchies).
Minimizes page rendering times.
Step 1 - Choosing the Mode
Direct Lake # Best for near real-time queries, avoids duplication, but has limitations (e.g., some complex calculated columns, MDX user hierarchies are not fully supported).
DirectQuery # Sends queries to the source each time. It supports complex expressions but is slow (not optimal for minimizing page rendering times).
Import # Data is loaded into VertiPaq in-memory engine, supports full DAX capabilities, calculated tables, MDX hierarchies, and provides fastest query performance.
# Correct choice: Import.
Step 2 - Choosing Query Caching
Capacity default # Relies on the workspace/capacity setting.
Off # Disables caching, which could slow down report rendering.
On # Ensures queries are cached for faster page rendering times.
# Correct choice: On.
Final Answer:
Mode: Import
Query Caching: On
References:
Semantic model storage modes in Fabric
Query caching in Power BI / Fabric
NEW QUESTION # 49
You have a Fabric warehouse that contains two tables named DimDate and Trips.
DimDate contains the following fields.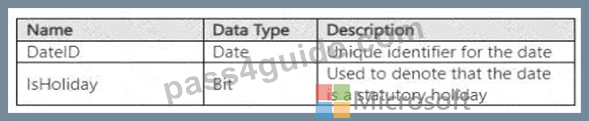
Trips contains the following fields.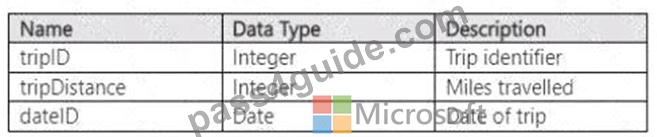
You need to compare the average miles per trip for statutory holidays versus non-statutory holidays.
How should you complete the T-SQL statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.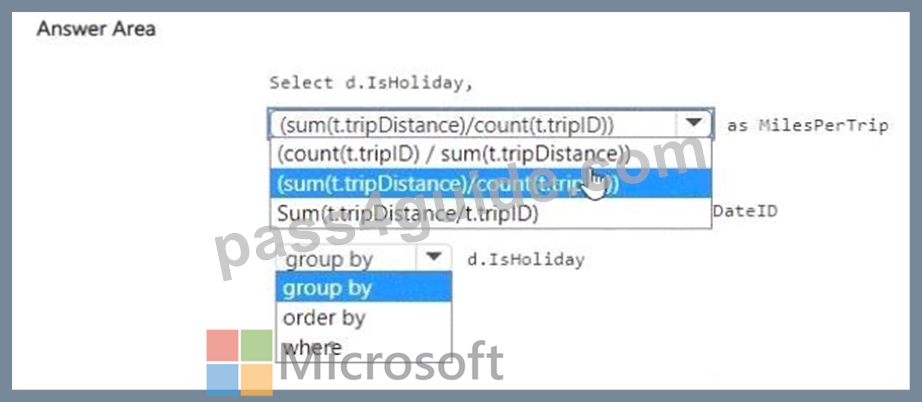
Answer:
Explanation: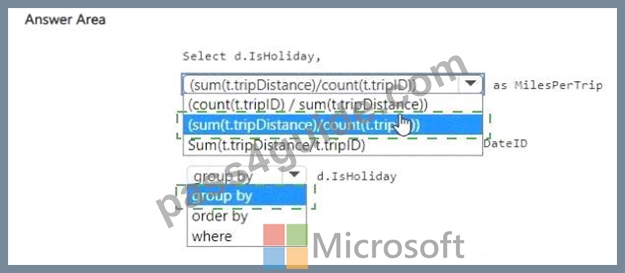
Explanation: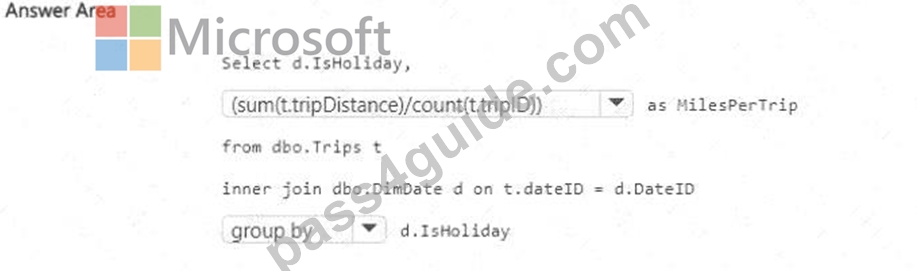
Comprehensive Detailed Explanation
Step 1: Requirement
We need to compare the average miles per trip for:
Statutory holidays (when IsHoliday = 1)
Non-statutory holidays (when IsHoliday = 0)
Step 2: Formula for average miles per trip
Average miles per trip = total miles ÷ number of trips
Total miles # SUM(t.tripDistance)
Number of trips # COUNT(t.tripID)
So the calculation is:
(SUM(t.tripDistance) / COUNT(t.tripID)) AS MilesPerTrip
Step 3: Grouping
We need a comparison by holiday status.
So we must group the results by:
GROUP BY d.IsHoliday
This ensures we get two rows: one for IsHoliday = 1 and one for IsHoliday = 0.
Step 4: Final Query
SELECT
d.IsHoliday,
(SUM(t.tripDistance) / COUNT(t.tripID)) AS MilesPerTrip
FROM DimDate d
INNER JOIN Trips t ON d.DateID = t.DateID
GROUP BY d.IsHoliday;
Why This is Correct
The formula ensures average miles per trip.
Grouping ensures comparison between holidays vs non-holidays.
Efficient aggregation, minimal computation.
References
Aggregate functions in T-SQL
GROUP BY clause
NEW QUESTION # 50
You have a Fabric tenant that contains two lakehouses.
You are building a dataflow that will combine data from the lakehouses. The applied steps from one of the queries in the dataflow is shown in the following exhibit.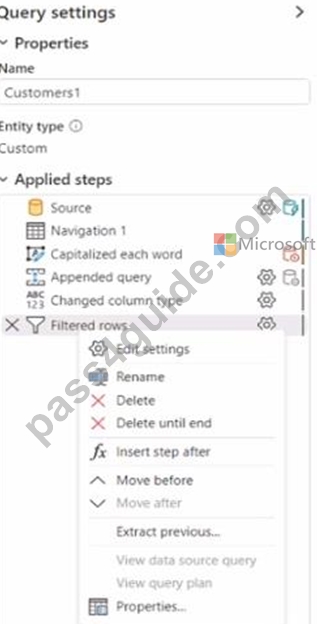
Use the drop-down menus to select the answer choice that completes each statement based on the information presented in the graphic. NOTE: Each correct selection is worth one point.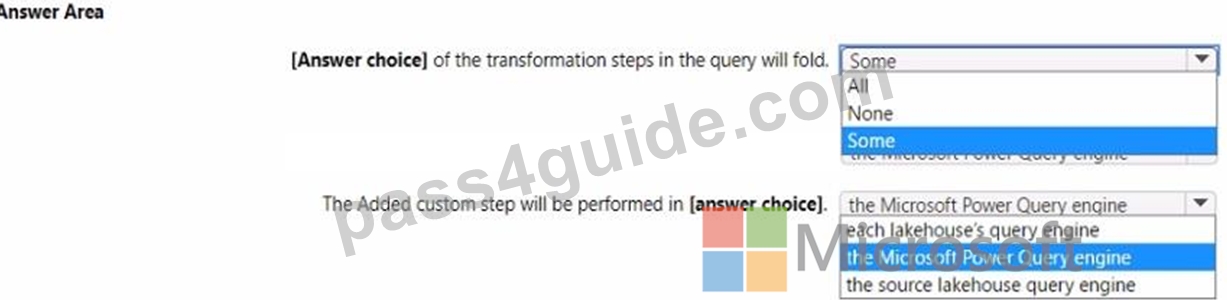
Answer:
Explanation: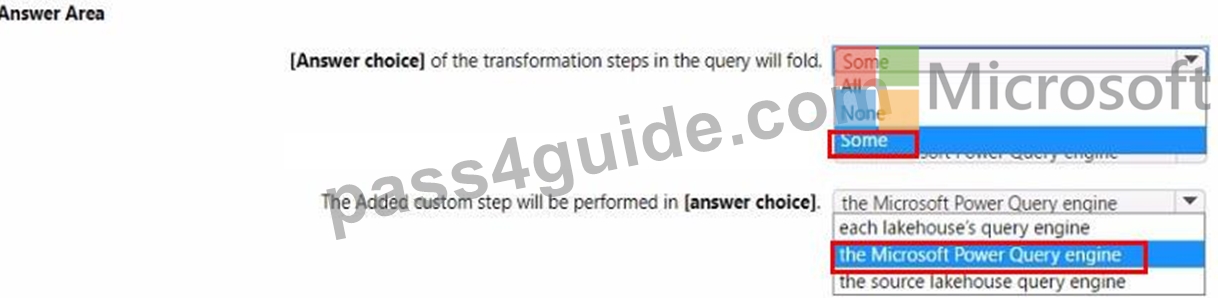
NEW QUESTION # 51
You have the source data model shown in the following exhibit.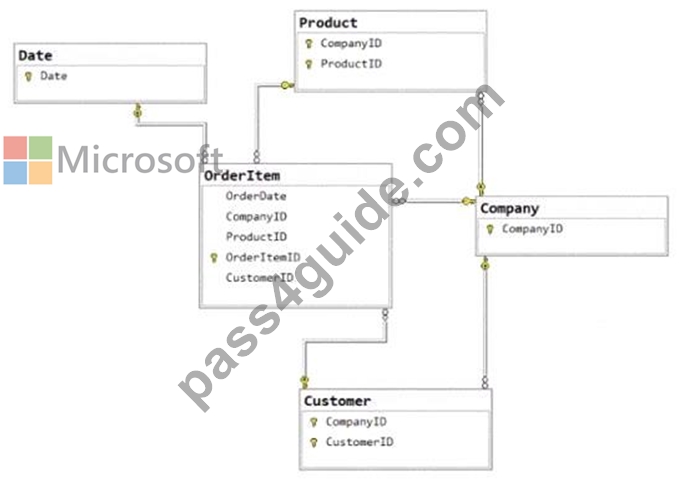
The primary keys of the tables are indicated by a key symbol beside the columns involved in each key.
You need to create a dimensional data model that will enable the analysis of order items by date, product, and customer.
What should you include in the solution? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.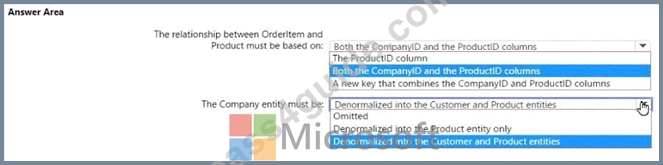
Answer:
Explanation: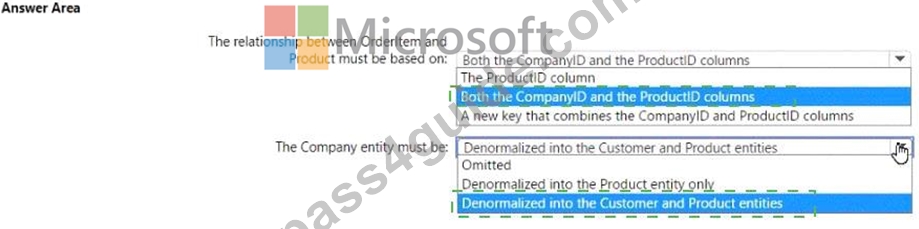
Explanation: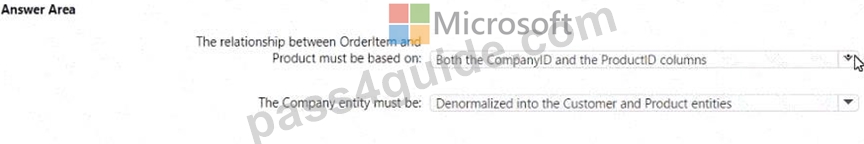
* The relationship between OrderItem and Product must be based on: Both the CompanyID and the ProductID columns
* The Company entity must be: Denormalized into the Customer and Product entities In a dimensional model, the relationships are typically based on foreign key constraints between the fact table (OrderItem) and dimension tables (Product, Customer, Date). Since CompanyID is present in both the OrderItem and Product tables, it acts as a foreign key in the relationship. Similarly, ProductID is a foreign key that relates these two tables. To enable analysis by date, product, and customer, the Company entity would need to be denormalized into the Customer and Product entities to ensure that the relevant company information is available within those dimensions for querying and reporting purposes.
References =
* Dimensional modeling
* Star schema design
NEW QUESTION # 52
......
Just like the old saying goes, motivation is what gets you started, and habit is what keeps you going. A good habit, especially a good study habit, will have an inestimable effect in help you gain the success. The DP-600 exam prep from our company will offer the help for you to develop your good study habits. If you buy and use our study materials, you will cultivate a good habit in study. More importantly, the good habits will help you find the scientific prop learning methods and promote you study efficiency, and then it will be conducive to helping you pass the DP-600 Exam in a short time. So hurry to buy the DP-600 test guide from our company, you will benefit a lot from it.
DP-600 Valid Test Pattern: https://www.pass4guide.com/DP-600-exam-guide-torrent.html
DOWNLOAD the newest Pass4guide DP-600 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1ledcPWBWhv3llnogIJl7MeRyNaLiw6u3