참고: KoreaDumps에서 Google Drive로 공유하는 무료 2026 Microsoft DP-700 시험 문제집이 있습니다: https://drive.google.com/open?id=1f4JIVqXA7FEYeKvY-8-ocw2isUFmdREP
Microsoft 인증DP-700시험에 도전해보려고 하는데 공부할 내용이 너무 많아 스트레스를 받는 분들은 지금 보고계시는 공부자료는 책장에 다시 넣으시고KoreaDumps의Microsoft 인증DP-700덤프자료에 주목하세요. KoreaDumps의 Microsoft 인증DP-700덤프는 오로지 Microsoft 인증DP-700시험에 대비하여 제작된 시험공부가이드로서 시험패스율이 100%입니다. 시험에서 떨어지면 덤프비용전액환불해드립니다.
| 주제 | 소개 |
|---|---|
| 주제 1 |
|
| 주제 2 |
|
| 주제 3 |
|
KoreaDumps 는 완전히 여러분이 인증시험준비와 안전이 시험패스를 위한 완벽한 덤프제공사이트입니다.우리 KoreaDumps의 덤프들은 응시자에 따라 ,시험 ,시험방법에 따라 제품의 완성도도 다릅니다.그 말은 즉 알 맞춤 자료입니다.여러분은 KoreaDumps의 알맞춤 덤프들로 아주 간단하고 편안하게 패스할 수 있습니다.많은 Microsoft인증관연 응시자들은 모두 우리KoreaDumps가 제공하는 DP-700문제와 답 덤프로 자격증 취득을 했습니다.때문에 우리KoreaDumps또한 업계에서 아주 좋은 이미지를 가지고 잇습니다
질문 # 141
You have a Fabric warehouse named DW1 that contains four staging tables named ProductCategory, ProductSubcategory, Product, and SalesOrder. ProductCategory, ProductSubcategory, and Product are used often in analytical queries.
You need to implement a star schema for DW1. The solution must minimize development effort.
Which design approach should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.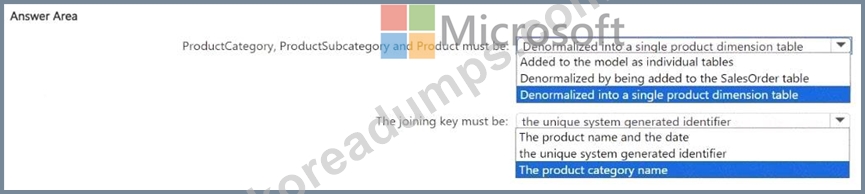
정답:
설명: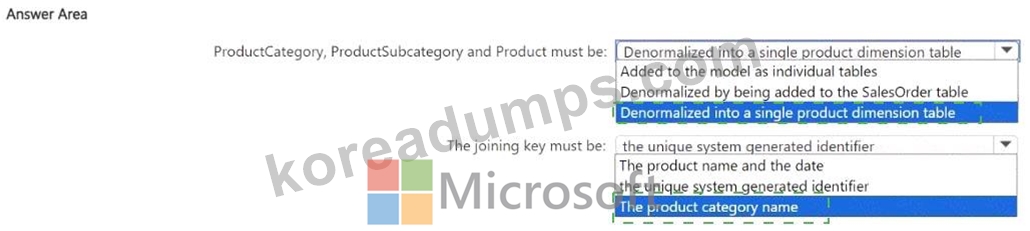
Explanation: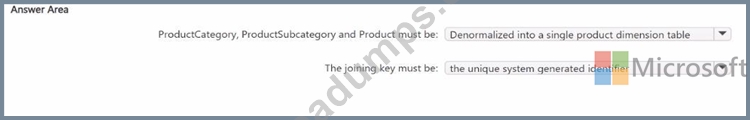
질문 # 142
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a KQL database that contains two tables named Stream and Reference. Stream contains streaming data in the following format.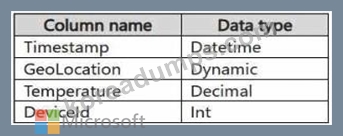
Reference contains reference data in the following format.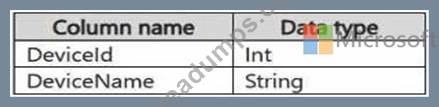
Both tables contain millions of rows.
You have the following KQL queryset.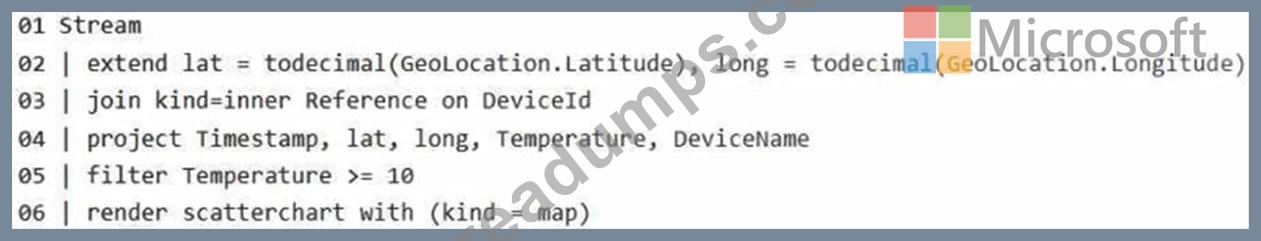
You need to reduce how long it takes to run the KQL queryset.
Solution: You change the join type to kind=outer.
Does this meet the goal?
정답:B
설명:
An outer join will include unmatched rows from both tables, increasing the dataset size and processing time. It does not improve query performance.
질문 # 143
You have a Fabric workspace that contains a lakehouse named Lakehousel. Lakehousel contains a table named Status_Target that has the following columns:
* Key
* Status
* LastModified
The data source contains a table named Status.Source that has the same columns as Status_Target. Status.Source is used to populate Status_Target. In a notebook name Notebook!, you load Status_Source to a DataFrame named sourceDF and Status_Target to a DataFrame named targetDF. You need to implement an incremental loading pattern by using Notebook-!. The solution must meet the following requirements:
* For all the matching records that have the same value of key, update the value of LastModified in Status_Target to the value of LastModified in Status_Source.
* Insert all the records that exist in Status_Source that do NOT exist in Status_Target.
* Set the value of Status in Status_Target to inactive for all the records that were last modified more than seven days ago and that do NOT exist in Status.Source.
How should you complete the statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.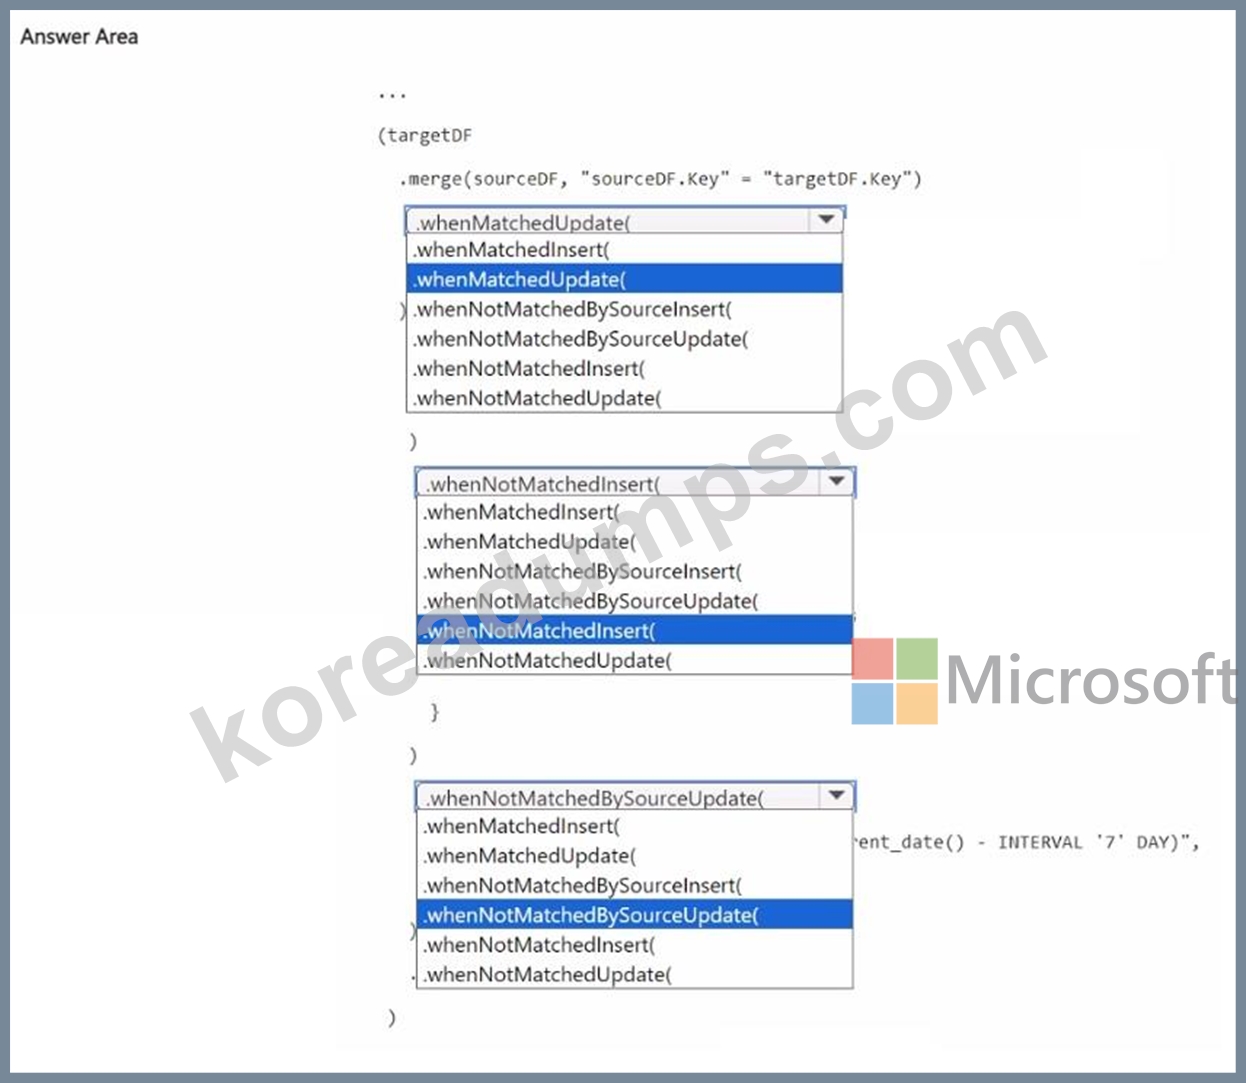
정답:
설명: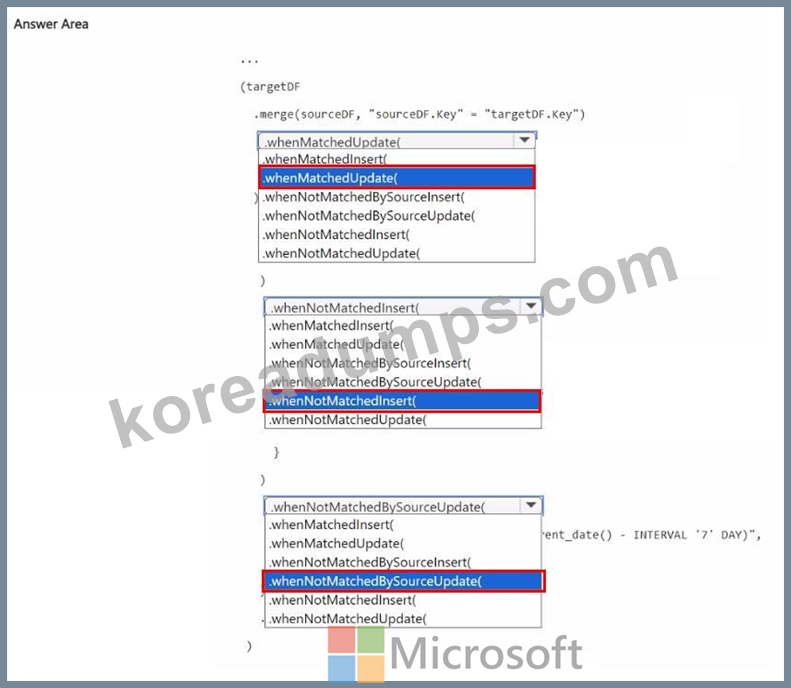
질문 # 144
You have a Fabric workspace that contains a lakehouse named Lakehouse1. Data is ingested into Lakehouse1 as one flat table. The table contains the following columns.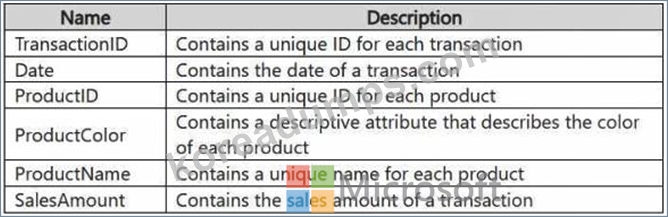
You plan to load the data into a dimensional model and implement a star schema. From the original flat table, you create two tables named FactSales and DimProduct. You will track changes in DimProduct.
You need to prepare the data.
Which three columns should you include in the DimProduct table? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
정답:B,C,E
설명:
In a star schema, the DimProduct table serves as a dimension table that contains descriptive attributes about products. It will provide context for the FactSales table, which contains transactional data. The following columns should be included in the DimProduct table:
ProductName: The ProductName is an important descriptive attribute of the product, which is needed for analysis and reporting in a dimensional model.
ProductColor: ProductColor is another descriptive attribute of the product. In a star schema, it makes sense to include attributes like color in the dimension table to help categorize products in the analysis.
ProductID: ProductID is the primary key for the DimProduct table, which will be used to join the FactSales table to the product dimension. It's essential for uniquely identifying each product in the model.
질문 # 145
HOTSPOT
You have an Azure Event Hubs data source that contains weather data.
You ingest the data from the data source by using an eventstream named Eventstream1. Eventstream1 uses a lakehouse as the destination.
You need to batch ingest only rows from the data source where the City attribute has a value of Kansas. The filter must be added before the destination. The solution must minimize development effort.
What should you use for the data processor and filtering? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.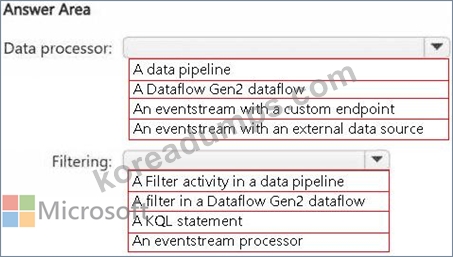
정답:
설명: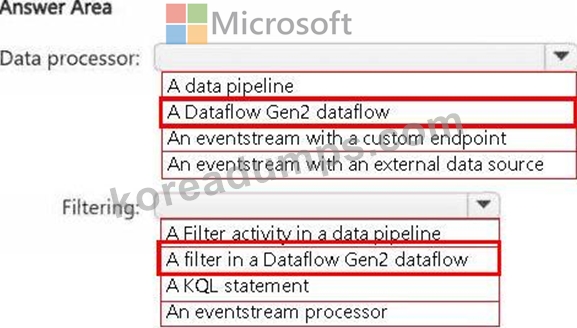
질문 # 146
......
KoreaDumps는 여러 it인증에 관심 있고 또 응시하고 싶으신 분들에게 편리를 드립니다. 그리고 많은 분들이 이미 KoreaDumps제공하는 덤프로 it인증시험을 한번에 패스를 하였습니다. 즉 우리 KoreaDumps 덤프들은 아주 믿음이 가는 보장되는 덤프들이란 말이죠. KoreaDumps에는 베터랑의전문가들로 이루어진 연구팀이 잇습니다, 그들은 it지식과 풍부한 경험으로 여러 가지 여러분이Microsoft인증DP-700시험을 패스할 수 있을 자료 등을 만들었습니다 여러분이Microsoft인증DP-700시험에 많은 도움이DP-700될 것입니다. KoreaDumps 가 제공하는DP-700테스트버전과 문제집은 모두DP-700인증시험에 대하여 충분한 연구 끝에 만든 것이기에 무조건 한번에DP-700시험을 패스하실 수 있습니다.
DP-700시험대비 덤프 최신자료: https://www.koreadumps.com/DP-700_exam-braindumps.html
KoreaDumps DP-700 최신 PDF 버전 시험 문제집을 무료로 Google Drive에서 다운로드하세요: https://drive.google.com/open?id=1f4JIVqXA7FEYeKvY-8-ocw2isUFmdREP