What's more, part of that Free4Torrent SPS-C01 dumps now are free: https://drive.google.com/open?id=1g298BG3iVIrodnfkjga1AcJOKQDarwYK
Our Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) PDF format is user-friendly and accessible on any smart device, allowing applicants to study from anywhere at any time. We have included actual and updated Snowflake SPS-C01 questions in this Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) Dumps PDF file. Our Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam dumps PDF format is designed to help individuals acquire the knowledge necessary to succeed in the test.
| Section | Objectives |
|---|---|
| Topic 1: Data Engineering with Snowpark | - Pipeline development
|
| Topic 2: Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| Topic 3: Testing, Debugging, and Deployment | - Production readiness
|
| Topic 4: User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Topic 5: DataFrame Operations and Data Processing | - Data transformation workflows
|
| Topic 6: Snowpark Fundamentals | - Snowpark architecture and concepts
|
>> SPS-C01 Free Dump Download <<
We can proudly claim that you can successfully pass the exam just on the condition that you study with our SPS-C01 preparation materials for 20 to 30 hours. And not only you will get the most rewards but also you will get an amazing study experience by our Snowflake Certified SnowPro Specialty - Snowpark SPS-C01 Exam Questions. For we have three different versions of our Snowflake SPS-C01 study guide, and you will have different feelings if you have a try on them.
NEW QUESTION # 321
You are setting up a development environment for Snowpark using Anaconda and encounter the following error: 'ModuleNotFoundError: No module named 'snowflake.snowpark". You have already installed the package using pip. What is the MOST likely cause of this error and how do you resolve it?
Answer: A,E
Explanation:
The most common reasons for 'ModuleNotFoundErroff are that the Anaconda environment is not activated (B), meaning the Python interpreter doesn't know where to find the installed packages, or the package was installed in a different environment (D) than the one being used. While Python version compatibility (A) and Snowflake driver (C) can cause issues, they usually manifest as different errors. A misconfigured account identifier (E) would prevent a connection to Snowflake, but wouldn't directly cause a 'ModuleNotFoundError' for the Snowpark library itself.
NEW QUESTION # 322
You have a Snowpark application that performs machine learning inference on a large dataset of images stored in Snowflake. The inference logic is implemented within a Python UDF that utilizes a pre-trained deep learning model. You notice that the inference process is slow and consumes a significant amount of resources. Which of the following optimization techniques would be MOST effective in improving the performance and reducing the resource consumption of this application?
Answer: A,B,D
Explanation:
Auto-scaling helps manage resources dynamically. Batch processing reduces UDF overhead by processing multiple images in one call. Storing the model in a stage requires repeated loading. Managing the model's lifecycle within the Snowpark Session prevents reloading the model. External functions require data transfer out of Snowflake.
NEW QUESTION # 323
You are using Snowpark in Python within a Jupyter Notebook environment to analyze sales data'. You've established a connection to Snowflake and loaded your data into a Snowpark DataFrame named 'sales ff. You need to calculate the cumulative sales for each product category over time. The 'sales_df' DataFrame has columns 'SALE DATE' (DATE), 'PRODUCT CATEGORY' (VARCHAR), and 'SALE AMOUNT' (NUMBER). Which of the following approaches, or combination of approaches, will correctly calculate the cumulative sales while optimizing for Snowflake's performance and scalability? (Select all that apply)
Answer: B,D,E
Explanation:
Options A, C, and E are correct. Option A utilizes Snowpark's DataFrame transformations with window functions, which are optimized for Snowflake's engine and can efficiently handle large datasets. This leverages Snowflake's parallel processing capabilities. Option C involves creating a stored procedure within Snowflake. This approach pushes the computation to the Snowflake server, potentially improving performance, especially if the cumulative sales calculation is complex. This also benefits from Snowflake's optimization capabilities. Option E executes a SQL query with a window function that's optimized. Option B is incorrect because iterating through rows in a Jupyter Notebook will be extremely slow and inefficient for large datasets. It defeats the purpose of using Snowpark for distributed data processing. Calculating cumulative sales this way doesn't leverage Snowflake's capabilities. Option D is partially correct in that it orders the data, but using a UDF for cumulative sum calculation will likely be less efficient than using native window functions within Snowflake.
NEW QUESTION # 324
Consider the following Snowpark Python code snippet designed to calculate a custom metric on financial data, using a vectorized UDF for performance. Identify potential performance bottlenecks and recommend optimization strategies.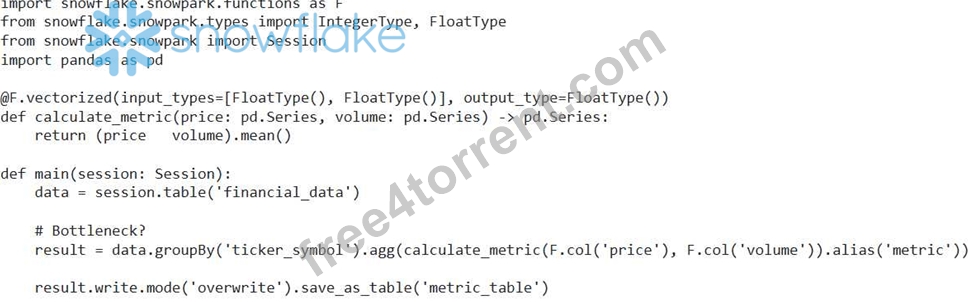
Which of the following actions (may be more than one) would MOST likely improve the performance of this Snowpark application?
Answer: A,C,E
Explanation:
Clustering by 'ticker_symbol' significantly optimizes the 'groupBy' operation by organizing data physically for efficient retrieval. Caching the result before writing to a table is crucial if the intermediate result 'result' will be used multiple times, avoiding redundant computations. Repartitioning by 'ticker_symbol' before grouping helps distribute data evenly, improving parallelism and locality. While Pandas is generally available, explicitly declaring it might be necessary in certain isolated environments, so B can be considered a good practice, but not as impactful. Changing FloatType to DoubleType (C) will not lead to performnace improvement. It only changes precision level which is not required here.
NEW QUESTION # 325
Which of the following statements are correct regarding the authentication methods available when creating a Snowpark session?
Answer: A,C,E
Explanation:
Options B, C, and D are correct. OAuth provides a secure delegation mechanism. Key pair authentication is also a secure method, eliminating password storage in code. Snowflake Browser-Based MFA relies on web browser redirection. Option A is incorrect because username/password is generally less secure than key pair or OAuth. Option E is incorrect because External Oauth providers like Okta are Azure AD is supported for authentication using a federated OAuth flow.
NEW QUESTION # 326
......
Now you need not be worried, if you are run short of time for SPS-C01 exam preparation or your tough work schedule doesn't allow you spare time for studying preparatory guides. Relying on Free4Torrent SPS-C01 Dumps will award an easy course to get through the exam and obtain a credential such as SPS-C01 you ever desired.
Pass SPS-C01 Guide: https://www.free4torrent.com/SPS-C01-braindumps-torrent.html
P.S. Free & New SPS-C01 dumps are available on Google Drive shared by Free4Torrent: https://drive.google.com/open?id=1g298BG3iVIrodnfkjga1AcJOKQDarwYK