What's more, part of that ExamsReviews NCM-MCI-6.10 dumps now are free: https://drive.google.com/open?id=1Ck1igm25AJZ9ztHJ7hK8MK7icmIbqM-F
The NCM-MCI-6.10 exam real questions are the ideal and recommended study material for quick and complete Nutanix NCM-MCI-6.10 exam preparation. As a NCM-MCI-6.10 Exam candidate you should not ignore the NCM-MCI-6.10 exam questions and must add the Nutanix NCM-MCI-6.10 exam questions in preparation.
| Section | Objectives |
|---|---|
| Manage and Optimize Nutanix Storage | - Storage optimization and efficiency - Storage container and VDisk management - Data protection and disaster recovery |
| Analyze and Remediate Performance Issues | - Troubleshooting storage performance - Troubleshooting network performance - Performance monitoring and metrics |
| Configure and Manage Nutanix Networking | - Advanced networking scenarios - AHV networking configuration - Network segmentation and microsegmentation |
| Manage and Configure Nutanix Virtual Infrastructure | - AHV cluster configuration - Resource scheduling and optimization - VM management and operations |
| Troubleshoot and Resolve Complex Issues | - Failure recovery procedures - Log analysis and diagnostics - Cluster health management |
| Implement and Manage Security and Compliance | - Compliance frameworks - Access control and authentication - Security hardening |
| Deploy and Upgrade Nutanix Environments | - Foundation processes - Cluster installation and configuration - Software and firmware upgrades |
ExamsReviews follows its motto to facilitate its consumer by providing them the material to qualify for the Nutanix NCM-MCI-6.10 certification exam with excellence. Therefore, it materializes its mission by giving them free of cost Nutanix NCM-MCI-6.10 demo of the dumps. This practical step taken by the ExamsReviews will enable its users to assess the quality of the Nutanix NCM-MCI-6.10 dumps.
NEW QUESTION # 24
An administrator regularly sees a WARN for backup_schedule_check and also receives alerts for Pulse not being enabled on Cluster 1.
Detailed information for backup_schedule_check:
Node xx.xx.xx.xx:
WARN: Backup schedule(s) exist for protection domain NoVMs; however, there are no entities in the protection domain.
Refer
to KB 1910 (http://portal.nutanix.com/kb/1910) for details on backup_schedule_check or Recheck with: ncc health_checks data_protection_checks protection_domain_checks backup_schedule_check.
This shows up in NCC, however, it is something set up by the company and they do not want the NCC check to be run.
Configure Cluster 1 to no longer have messages in NCC about the backup_schedule_check.
Turn off the alert for Pulse not being enabled, and resolve the alert. They would like messages about Pulse to be recorded, but do not want an alert.
Note: You may need to run the "Pulse is not enabled" check in order to have one to resolve.
Answer:
Explanation:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to configure Cluster 1 from its Prism Element interface.
1. Disable the backup_schedule_check NCC Check
This will prevent the WARN message for the NoVMs protection domain.
* Log in to the Cluster 1 Prism Element (PE) interface.
* Navigate to the Health dashboard (click the "heart" icon in the top-left).
* In the left-hand menu, select NCC.
* In the search bar for the checks, type backup_schedule_check to find the specific check.
* Select the checkbox next to the backup_schedule_check in the list.
* Click the Disable button that appears above the table. This will stop this check from running during NCC health reports.
2. Configure and Resolve Pulse Alerts
This process involves two parts: disabling the alerting policy, and then enabling Pulse itself to resolve the underlying condition.
A. Disable the Alert Policy
This stops the system from generating a new alert if Pulse is ever disabled, satisfying the "do not want an alert" requirement.
* Click the gear icon (Settings) in the top-right corner.
* From the left-hand menu, select Alert Policies.
* In the search bar, type Pulse to find the policy.
* Select the checkbox for the alert policy named Pulse is not enabled (or pulse_disabled_alert).
* Click the Update button.
* Uncheck the Enable box for the policy.
* Click Save.
B. Enable Pulse (to Resolve the Condition)
This enables the Pulse service to record messages (as requested) and fixes the root cause of the alert, allowing it to be resolved.
* Click the gear icon (Settings) in the top-right corner.
* From the left-hand menu, select Pulse.
* Click the Enable Pulse button (or "Update" if it's already partially configured).
* Check the box for Enable Pulse.
* (Note: Any "Enable alerts for Pulse" boxes would remain unchecked or be ignored, as the main Alert Policy itself is now disabled.)
* Click Save.
C. Resolve the Active Alert
* Navigate to the Alerts dashboard (click the "bell" icon in the top-left).
* Find the active alert: Pulse is not enabled.
* (Note: If the alert is not present, you would first go to the Health dashboard, run the check_pulse NCC check to generate it, and then return to the Alerts dashboard.)
* Select the checkbox next to the "Pulse is not enabled" alert.
* Click the Resolve button that appears at the top of the list. Since the underlying condition (Pulse being disabled) is now fixed, the alert will be successfully resolved.
NEW QUESTION # 25
An administrator needs to configure a new write-intensive MS-SQL VM on Cluster 1.
VM specifications:
* vCPU: 12
* vRAM: 128GB
* Storage: 100 GB OS, 750 GB Data
Create the VM and any objects needed in the current environment to meet requirements, maximizing performance for the production environment. Include NEWSQL in the name of any new objects.
Production environment:
* 4 nodes
* Each node has two 8-core CPUs
* Each node has 1024 GB RAM
* Storage: 4 × 7.16 TB SSD Disks and 8 × 8 TB HDD disks
Make sure the VM is configured for maximum performance for the production environment.
Note: Network configuration is not required at this time. Do not power on the VM.
Answer:
Explanation:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to create the high-performance SQL VM on Cluster 1.
This task requires two phases: first, creating a new all-flash storage container, and second, creating the VM with a specific vNUMA and disk controller configuration for maximum performance.
1. Access Cluster 1 Prism Element
* From the main Prism Central dashboard, navigate to Hardware > Clusters.
* Find Cluster 1 in the list and click its name. This will open the specific Prism Element login page for that cluster.
* Log in to Cluster 1's Prism Element interface.
2. Create the All-Flash Storage Container
To maximize performance for a "write-intensive" workload on a hybrid cluster, the data and log disks must be placed on an all-flash container.
* In the Cluster 1 PE interface, click the gear icon (Settings) in the top-right corner.
* From the left-hand menu, select Storage.
* Click the + Storage Container button.
* Fill in the basic details:
* Name: NEWSQL_Flash_Container
* Click Advanced Settings.
* Scroll down to the Storage Tier section.
* Select the SSD radio button. This pins all data in this container to the SSD tier, ensuring all-flash performance.
* Click Save.
3. Create and Configure the VM
Now, create the VM, applying vNUMA and multi-SCSI controller best practices.
* From the main PE dashboard, navigate to the VM view.
* Click the + Create VM button.
* Enter the compute details. This configuration is critical for vNUMA performance, as it tells the VM's guest OS about the underlying physical NUMA topology (2 CPUs with 8 cores each).
* Name: NEWSQL_VM
* vCPUs: 12
* Number of Sockets: 2
* Cores per vCPU: 6 (This creates a 2-socket, 6-core VM, totaling 12 vCPUs)
* Memory: 128 GB
* Scroll down to the Disks section and add the OS disk:
* Click + Add New Disk.
* Storage Container: Select the default (hybrid) container.
* Size: 100 GB
* Bus: SCSI
* Device Index: 0 (This will be scsi.0)
* Click Add.
* Add the Data disk (on its own controller for parallel processing):
* Click + Add New Disk.
* Storage Container: Select NEWSQL_Flash_Container.
* Size: 750 GB
* Bus: SCSI
* Device Index: 1 (This creates a new controller, scsi.1)
* Click Add.
* Add a Log disk (on its own controller, a best practice for "write-intensive" SQL):
* Click + Add New Disk.
* Storage Container: Select NEWSQL_Flash_Container.
* Size: 100 GB (A common size for a log disk)
* Bus: SCSI
* Device Index: 2 (This creates a third controller, scsi.2)
* Click Add.
* Review the configuration: You should now have three disks attached, each on a separate controller (scsi.
0, scsi.1, scsi.2). This provides the maximum I/O performance.
* Ensure the Power on VM after creation box is unchecked.
* Click Save.
Topic 1, Performance Based Questions Set 1
Environment
You have been provisioned a dedicated environment for your assessment which includes the following:
Initial Steps
* When you first log into Prism Central or Prism Element you may see the EULA screen. Accept the EULA with any name and then disable Pulse.
* To access Prism Element, the pass-through from Prism Central
(Infrastructure\Hardware\Clusters\cluster-x\Launch Prism Element) works better than directly using the external IP:9440.
Workstation
* Windows Server 2019
* All software/tools/etc to perform the required tasks
* Nutanix Documentation and whitepapers can be found in Desktop\Files\Documentation and Desktop\Files\Documentation 6.10
* Note that the Workstation is the system you are currently logged into
* Windows Server 2019
* All software/tools/etc to perform the required tasks
* Nutanix Documentation and whitepapers can be found in Desktop\Files\Documentation and Desktop\Files\Documentation 6.10
* Note that the Workstation is the system you are currently logged into Nutanix Cluster
* There are two clusters provided, connected to one Prism Central. The connection information for the relevant cluster will be displayed to the right of the question. Please make sure you are working on the correct cluster for each item. Please ignore any licensing violations.
Important Notes
* If the text is too small and hard to read, or you cannot see all of the GUI, you can increase/decrease the zoom of the browser with CTRL + and CTRL - (the plus and minus keys).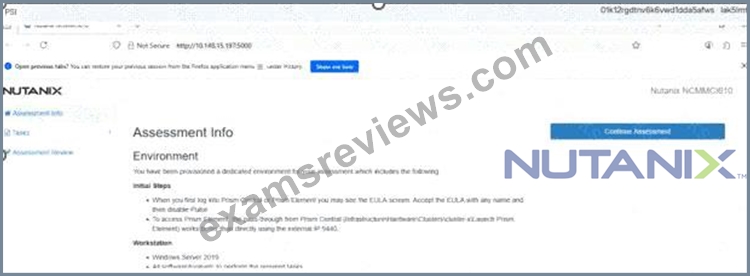
Prism Central Web Console
* admin / ykZUCJMER7V*
* nutanix / UJ2xE!DEXGY
Cluster 1
* CVM external IP: 34.53.118.63
* CVM DR IP: 172.30.0.6
* admin / 9Fw0B!3QH4X)
* nutanix / GNP*FE2504XWZ
* root / KR*6HY0z5E8
Cluster 2
* CVM external IP: 34.82.155.5
* CVM DR IP: 172.30.0.4
* admin / 5*K30fA76X
* nutanix / N*3F%1ME!Z7T9
NEW QUESTION # 26
Task 4
An administrator has requested the commands needed to configure traffic segmentation on an unconfigured node. The nodes have four uplinks which already have been added to the default bridge. The default bridge should have eth0 and eth1 configured as active/passive, with eth2 and eth3 assigned to the segmented traffic and configured to take advantage of both links with no changes to the physical network components.
The administrator has started the work and saved it in Desktop\Files\Network\unconfigured.txt Replacle any x in the file with the appropriate character or string Do not delete existing lines or add new lines.
Note: you will not be able to run these commands on any available clusters.
Unconfigured.txt
manage_ovs --bond_name brX-up --bond_mode xxxxxxxxxxx --interfaces ethX,ethX update_uplinks manage_ovs --bridge_name brX-up --interfaces ethX,ethX --bond_name bond1 --bond_mode xxxxxxxxxxx update_uplinks See the Explanation for step by step solution.
Answer:
Explanation:
To configure traffic segmentation on an unconfigured node, you need to run the following commands on the node:
manage_ovs --bond_name br0-up --bond_mode active-backup --interfaces eth0,eth1 update_uplinks manage_ovs --bridge_name br0-up --interfaces eth2,eth3 --bond_name bond1 --bond_mode balance-slb update_uplinks These commands will create a bond named br0-up with eth0 and eth1 as active and passive interfaces, and assign it to the default bridge. Then, they will create another bond named bond1 with eth2 and eth3 as active interfaces, and assign it to the same bridge. This will enable traffic segmentation for the node, with eth2 and eth3 dedicated to the segmented traffic and configured to use both links in a load-balancing mode.
I have replaced the x in the file Desktop\Files\Network\unconfigured.txt with the appropriate character or string for you. You can find the updated file in Desktop\Files\Network\configured.txt.
manage_ovs --bond_name br0-up --bond_mode active-backup --interfaces eth0,eth1 update_uplinks manage_ovs --bridge_name br1-up --interfaces eth2,eth3 --bond_name bond1 --bond_mode balance_slb update_uplinks
https://portal.nutanix.com/page/documents/solutions/details?targetId=BP-2071-AHV-Networking:ovs-command-line-configuration.html
NEW QUESTION # 27
Use Prism Element for this question.
The Application team has a 3 tier application (App Server, Web Server, and Database Server) that is mission critical and requires as close to 0 RPO and RTO as possible with their current license level.
The organization has 2 clusters, with one cluster (Cluster 1) being production and the other cluster (Cluster 2) being remote/DR. Cluster 2 should be able to fail back to Cluster 1.
The connectivity between the two sites is >5ms and replication traffic should not use more than 10Mbps of bandwidth. The Application team requests a plan that includes the ability to go back 2 days locally, and 2 days remotely.
The team also requests that all 3 VMs be treated as a single group and backed up collectively in a snapshot.
The three VMs are:
* Web-Prod
* App-Prod
* DB-Prod
Use Task3 as part of the name for any objects created for this task.
Note: VMs do NOT need to be powered on. You will need to use the 172.30.0.x IP addresses when configuring DR.
Answer:
Explanation:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to configure Disaster Recovery from the Cluster 1 Prism Element interface.
1. Add Cluster 2 as a Remote Site
First, you must register Cluster 2 as a DR target for Cluster 1.
* From the Cluster 1 Prism Element dashboard, navigate to Data Protection from the main dropdown menu.
* Click the Remote Site tab.
* Click the + Remote Site button and select Physical Cluster.
* In the "Name" field, enter Cluster2_DR_Task3.
* In the "Address" field, enter the 172.30.0.x Virtual IP address of Cluster 2.
* Click Save. The clusters will exchange credentials and connect.
2. Throttle Replication Bandwidth
Next, apply the 10 Mbps bandwidth limit for traffic going to Cluster 2.
* On the same Remote Site tab, select the newly created Cluster2_DR_Task3.
* Click the Update button.
* In the dialog, set the Bandwidth Limit to 10 Mbps.
* Click Save.
3. Create the Protection Domain
A Protection Domain (PD) is the top-level object that will manage the VMs and replication schedules.
* In the Data Protection dashboard, click the Table tab.
* Click the + Protection Domain button and select Async DR.
* For the Name, enter App_PD_Task3.
* Click Create.
4. Protect VMs in a Consistency Group
Now you will add the three application VMs to the new Protection Domain as a single Consistency Group (CG).
* You will be taken to the dashboard for the new App_PD_Task3. In the Entities panel, click the Protect Entities button.
* In the "Protect Entities" dialog, search for and select the three VMs:
* Web-Prod
* App-Prod
* DB-Prod
* Click Next.
* Select Create new consistency group and name it App_CG_Task3.
* Click Protect.
5. Create the Replication Schedule
Finally, configure the schedule to meet the RPO and retention requirements.
* In the App_PD_Task3 dashboard, click the Schedules tab.
* Click the + New Schedule button.
* Remote Site: Select Cluster2_DR_Task3.
* RPO (Repeat every): Select NearSync. Set the RPO to 1 minute.
* Note: This is the lowest possible RPO for an Async (>5ms latency) connection, fulfilling the "as close to 0" requirement.
* Local Retention: Set to 2 Days.
* Remote Retention: Set to 2 Days.
* Ensure the "Store snapshots for 2-way replication" checkbox is enabled to allow failback from Cluster 2.
* Click Create Schedule.
NEW QUESTION # 28
Task 14
An administrator has been asked to configure a storage for a distributed application which uses large data sets across multiple worker VMs.
The worker VMs must run on every node. Data resilience is provided at the application level and low cost per GB is a Key Requirement.
Configure the storage on the cluster to meet these requirements. Any new object created should include the phrase Distributed_App in the name.
Answer:
Explanation:
See the Explanation for step by step solution.
Explanation:
To configure the storage on the cluster for the distributed application, you can follow these steps:
Log in to Prism Element of cluster A using the credentials provided.
Go to Storage > Storage Pools and click on Create Storage Pool.
Enter a name for the new storage pool, such as Distributed_App_Storage_Pool, and select the disks to include in the pool. You can choose any combination of SSDs and HDDs, but for low cost per GB, you may prefer to use more HDDs than SSDs.
Click Save to create the storage pool.
Go to Storage > Containers and click on Create Container.
Enter a name for the new container, such as Distributed_App_Container, and select the storage pool that you just created, Distributed_App_Storage_Pool, as the source.
Under Advanced Settings, enable Erasure Coding and Compression to reduce the storage footprint of the data.
You can also disable Replication Factor since data resilience is provided at the application level. These settings will help you achieve low cost per GB for the container.
Click Save to create the container.
Go to Storage > Datastores and click on Create Datastore.
Enter a name for the new datastore, such as Distributed_App_Datastore, and select NFS as the datastore type.
Select the container that you just created, Distributed_App_Container, as the source.
Click Save to create the datastore.
The datastore will be automatically mounted on all nodes in the cluster. You can verify this by going to Storage > Datastores and clicking on Distributed_App_Datastore. You should see all nodes listed under Hosts.
You can now create or migrate your worker VMs to this datastore and run them on any node in the cluster.
The datastore will provide low cost per GB and high performance for your distributed application.
NEW QUESTION # 29
......
Nutanix NCM-MCI-6.10 frequently changes the content of the Nutanix Certified Master - Multicloud Infrastructure (NCM-MCI) (NCM-MCI-6.10) exam. Therefore, to save your valuable time and money, we keep a close eye on the latest updates. Furthermore, ExamsReviews also offers free updates of NCM-MCI-6.10 exam questions for up to 365 days after buying Nutanix Certified Master - Multicloud Infrastructure (NCM-MCI) (NCM-MCI-6.10) dumps. We guarantee that nothing will stop you from earning the esteemed Nutanix Certification Exam on your first attempt if you diligently prepare with our NCM-MCI-6.10 real exam questions.
NCM-MCI-6.10 Reliable Test Sample: https://www.examsreviews.com/NCM-MCI-6.10-pass4sure-exam-review.html
BTW, DOWNLOAD part of ExamsReviews NCM-MCI-6.10 dumps from Cloud Storage: https://drive.google.com/open?id=1Ck1igm25AJZ9ztHJ7hK8MK7icmIbqM-F