2026 Die neuesten ExamFragen Databricks-Certified-Data-Engineer-Associate PDF-Versionen Prüfungsfragen und Databricks-Certified-Data-Engineer-Associate Fragen und Antworten sind kostenlos verfügbar: https://drive.google.com/open?id=1JFb3v-BB_L6VGiS7QM1VIVQvQLZ9rja9
Wenn Sie finden, dass eine große Herausforderung in Ihrem Berufsleben vor Ihnen steht, so müssen Sie die Databricks Databricks-Certified-Data-Engineer-Associate Zertifizierungsprüfung bestehen. ExamFragen ist eine echte Website, die umfassende Kenntnisse zur Databricks Databricks-Certified-Data-Engineer-Associate Zertifizierungsprüfung besitzt. Wir bieten exklusive Online-Databricks Databricks-Certified-Data-Engineer-Associate Prüfungsfragen und Antworten. So ist es ganz leicht, die Prüfung zu bestehen. Unser ExamFragen bietet Ihnen 100%-Pass-Garantie. ExamFragen ist als Anführer der professionalen Zertifizierung anerkannt. Sie bietet die umfangreichste Zertifizierungsantworten. Sie werden feststellen, dass die Databricks Databricks-Certified-Data-Engineer-Associate Prüfungsfragen und Antworten zur Zeit die gründlichste, genaueste und neueste Praxis sind. Wenn Sie die Databricks Databricks-Certified-Data-Engineer-Associate Prüfungsfragen und Antworten haben, werden Sie sicher mehr sicher sein, die Prüfung zum ersten Mal zu bestehen.
| Section | Weight | Objectives |
|---|---|---|
| Spark SQL and DataFrames | 15-20% | - Aggregate and group data - Join and union DataFrames - Write and execute Spark SQL queries - Handle null values and data quality |
| Python for Data Engineering | 10-15% | - Work with Spark APIs in Python - Implement user-defined functions (UDFs) - Use PySpark for data processing |
| Lakehouse Platform Concepts | 10-15% | - Understand the Lakehouse architecture and its benefits - Explain data governance and security concepts - Describe key Databricks Lakehouse platform components |
| Apache Spark Data Processing Fundamentals | 20-25% | - Use Spark SQL for data processing - Create and use Spark DataFrames - Apply transformations and actions on DataFrames - Work with structured data types (arrays, maps, structs) |
| Delta Lake Fundamentals | 20-25% | - Write to and read from Delta tables - Understand ACID transactions and time travel - Explain Delta Lake features and benefits - Create and manage Delta tables |
| Data Pipeline Architecture | 15-20% | - Implement incremental data processing - Monitor and optimize pipeline performance - Design data pipelines for batch and streaming - Understand ELT vs ETL patterns |
>> Databricks-Certified-Data-Engineer-Associate Fragenkatalog <<
Über die Prüfungsfragen und Antworten zur Databricks Databricks-Certified-Data-Engineer-Associate Zertifizierung hat ExamFragen eine gute Qualität. ExamFragen wird die zuverlässigsten Informationsressourcen sein. Durch die Feedbacks und tiefintensive Analyse sind wir in einer Stelle. Wir müssen darüber entscheiden, welche Anbieter Ihnen die neuesten Übungen von guter Qualität zur Databricks Databricks-Certified-Data-Engineer-Associate Zertifizierungsprüfung bieten und aktualisieren zu können. Unsere Schulungsunterlagen zur Databricks Databricks-Certified-Data-Engineer-Associate Zertifizierungsprüfung werden ständig bearbeitet und modifiziert. Wir haben die umfassendesten Ausbildungserfahrugnen. Wenn Sie Zertifikate erhalten wollen, benutzen Sie doch unsere Schulungsunterlagen zur Databricks Databricks-Certified-Data-Engineer-Associate Zertifizierungsprüfung. Schicken ExamFragen doch schnell in Ihren Warenkorb. Unzählige Überraschungen warten schon auf Sie.
279. Frage
A data engineer is cleaning a Bronze table that receives the same customer records from multiple source systems. Duplicate rows have the same customer_id and email values but different ingestion_timestamp values. The Silver table should contain only one record for each unique combination of customer_id and email.
Which PySpark operation correctly deduplicates the records based on the business keys?
Antwort: A
280. Frage
A data engineering team ingests customer transaction data from three enterprise sources (SQL database, S3, and Kafka stream) into Unity Catalog tables. The data must maintain lineage and support compliance audits requiring historical snapshots. Which Lakeflow Connect configuration satisfies both the governance and audit requirements?
Antwort: A
Begründung:
Separate source-specific connectors support incremental ingestion or CDC into Unity Catalog- managed Delta tables, preserving governance and lineage. Retaining table versions/history enables historical audit queries; a single connector cannot combine unrelated SQL, S3, and Kafka sources.
281. Frage
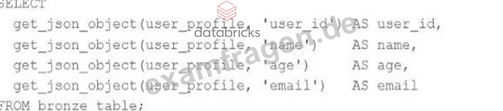
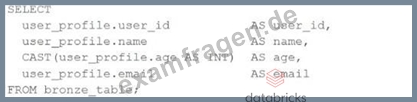
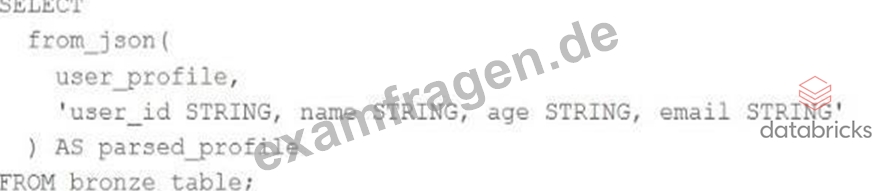
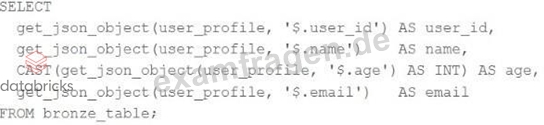
A data engineer is transforming a bronze table containing API response data into a silver table.
The bronze table has a user_profile column of type STRING that contains JSON data. An example value is:
The silver table needs to make this data easily queryable for analytics without requiring JSON parsing in every downstream query.
Which approach standardizes this column for the silver table?
Antwort: D
Begründung:
It uses valid JSONPath expressions ($.field) to extract each attribute into a separate silver-table column and casts age to INT, making the data typed and directly queryable. The other options use invalid paths, treat a string as a struct, or retain an inadequately typed nested structure.
282. Frage
A data engineer is running a Spark job that processes data stored in Delta format. The engineer wants to reduce the number of files by compacting smaller files into larger ones to improve query performance. Which Delta Lake command performs this operation?
Antwort: C
283. Frage
A data engineer is developing a small proof of concept in a notebook. When running the entire notebook, cluster usage spikes. The data engineer wants to keep the development experience and get real-time results.
Which cluster meets these requirements?
Antwort: B
Begründung:
For interactive notebook development, Databricks distinguishes between all-purpose compute and job compute. All-purpose compute is designed for analysis, notebook development, and interactive workloads, while job compute is intended for automated scheduled or triggered jobs. Because the engineer is actively developing a proof of concept in a notebook and wants real-time feedback, an all-purpose cluster is the right compute type. Adding autoscaling makes it better suited to the observed usage spikes, because the cluster can expand when notebook execution demands more resources and scale down afterward, reducing waste compared with a large fixed-size cluster. That makes option B the best answer. Option A keeps the interactive development model, but the fixed large size is less efficient. Options C and D use job clusters, which are better aligned with production jobs rather than iterative notebook-based development. Databricks documentation consistently positions all-purpose compute for collaborative and interactive development, and autoscaling is a standard mechanism to handle variable workloads more efficiently.
=========
284. Frage
......
Wenn Sie ExamFragen wählen, kommt der Erfolg auf Sie zu. Die Examsfragen zur Databricks Databricks-Certified-Data-Engineer-Associate Zertifizierungsprüfung wird Ihnen helfen, die Prüfung zu bestehen. Die Simulationsprüfung vor der Databricks Databricks-Certified-Data-Engineer-Associate Zertifizierungsprüfung zu machen, ist ganz notwendig und effizient. Wenn Sie ExamFragen wählen, können Sie 100% die Prüfung bestehen.
Databricks-Certified-Data-Engineer-Associate Online Prüfung: https://www.examfragen.de/Databricks-Certified-Data-Engineer-Associate-pruefung-fragen.html
P.S. Kostenlose und neue Databricks-Certified-Data-Engineer-Associate Prüfungsfragen sind auf Google Drive freigegeben von ExamFragen verfügbar: https://drive.google.com/open?id=1JFb3v-BB_L6VGiS7QM1VIVQvQLZ9rja9