P.S. PassTestがGoogle Driveで共有している無料かつ新しいDP-600ダンプ:https://drive.google.com/open?id=1gZWI85TBo5hMTN7af0olk5YFJXpXgXui
最初の試行でPassTest最短時間でDP-600認定を取得したい場合、効果的で便利なDP-600質問バンクほど刺激的なものはありません。 DP-600トレーニング資料を早くMicrosoft使用するほど、DP-600試験に合格する可能性が高くなり、DP-600証明書を早く取得できます。 私たちのDP-600試験問題を必ず試してみる必要があります。間違いなく満足するでしょう。 それに加えて、有効かつ正確なDP-600学習教材だけでなく、Implementing Analytics Solutions Using Microsoft Fabric優れたサービスも世界中のお客様から高く評価されています。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
DP-600試験問題の最大の利点は、時間と市場の試練に耐えることです。それは、誠実で温かいサービスです。受験者がDP-600試験に合格できるように、完璧な製品とサービスシステムを確立しています。対応する製品とサービスをお楽しみいただける、適切で満足のいくDP-600試験問題を提供できます。絶対に100%良いとは言えませんが、すべての顧客にサービスを提供するために最善を尽くしています。このようにして初めて、顧客を維持し、長期的な協力パートナーになれます。 DP-600テストガイドへの転送をお試しください。
質問 # 16
You have a Fabric tenant tha1 contains a takehouse named Lakehouse1. Lakehouse1 contains a Delta table named Customer.
When you query Customer, you discover that the query is slow to execute. You suspect that maintenance was NOT performed on the table.
You need to identify whether maintenance tasks were performed on Customer.
Solution: You run the following Spark SQL statement:
EXPLAIN TABLE customer
Does this meet the goal?
正解:B
解説:
No, the EXPLAIN TABLE statement does not identify whether maintenance tasks were performed on a table. It shows the execution plan for a query. Reference = The usage and output of the EXPLAIN command can be found in the Spark SQL documentation.
質問 # 17
You have a Fabric tenant.
You need to configure OneLake security for users shown in the following table.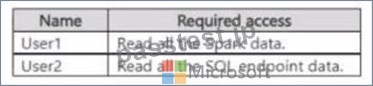
The solution must follow the principle of least privilege.
Which permission should you assign to each user? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.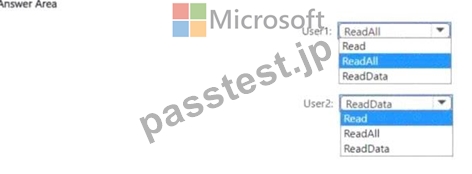
正解:
解説: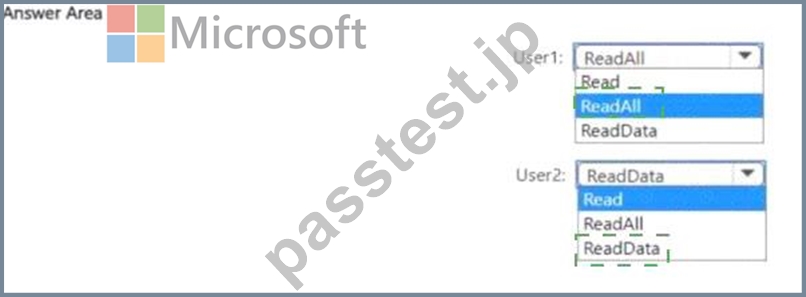
Explanation: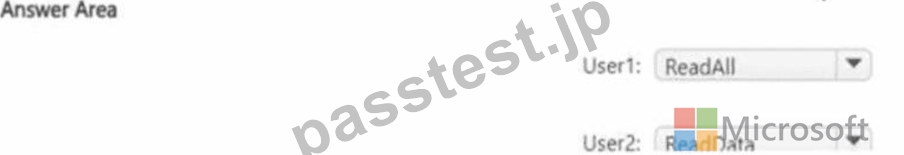
You need to configure OneLake security for two users with the following requirements:
User1: Read all the Spark data
User2: Read all the SQL endpoint data
The available permissions are: Read, ReadAll, and ReadData.
Understanding the permissions:
Read # Grants access to metadata but not the data itself.
ReadData # Grants access to query data through SQL endpoints (SQL-based access).
ReadAll # Grants access to read data across all engines (including Spark and SQL endpoints).
Applying least privilege principle:
User1 (Spark access): Needs to read all the Spark data # Assign ReadAll because Spark requires this permission to access data in OneLake.
User2 (SQL endpoint access): Needs to read SQL endpoint data only # Assign ReadData, as this grants access to SQL endpoints without over-provisioning Spark access.
Final Answer:
User1: ReadAll
User2: ReadData
References:
Microsoft Fabric OneLake permissions
Fabric Lakehouse & SQL Endpoint security
質問 # 18
You have a Fabric tenant named Tenant! that contains a lakehouse named Lakehouse1.
You need to add data to Lakehouse1 from a CSV file in an Azure Storage account outside of Fabric. The solution must minimize development effort.
What should you use to add the data?
正解:C
解説:
Comprehensive Detailed Explanation
Requirement
Tenant: Fabric tenant Tenant1
Data target: Lakehouse1
Data source: CSV file in an Azure Storage account (outside of Fabric)
Requirement: Minimize development effort
Step 1: Understand options
A). Dataflow Gen2
Used for ETL (transformations, cleansing, ingestion).
More effort because you need to build Power Query transformations.
Not minimal effort for simply exposing a file.
B). Shortcut
Fabric supports creating shortcuts to external data sources (OneLake, ADLS Gen2, Azure Blob, Dataverse, etc.).
Shortcut directly exposes external files/tables inside the lakehouse without copying or moving data.
This is the lowest-effort solution to access external CSV.
C). Copy job
Pipelines have a copy activity to physically copy data into Fabric.
Requires setup and execution. More development effort than a shortcut.
D). Pipeline
Used for orchestrating complex ETL workflows.
Overhead for this scenario.
Step 2: Correct Answer
Since the goal is simply to access a CSV in external storage with minimal development effort, the right solution is:
B). a shortcut
References
Shortcuts in Microsoft Fabric OneLake
Dataflow Gen2 overview
Topic 1, Contoso, ltd.
Overview
Contoso, ltd. is a US-based health supplements company, Contoso has two divisions named Sales and Research. The Sales division contains two departments named Online Sales and Retail Sales. The Research division assigns internally developed product lines to individual teams of researchers and analysts.
Identity Environment
Contoso has a Microsoft Entra tenant named contoso.com. The tenant contains two groups named ResearchReviewersGroupi and ReseachReviewefsGfoup2.
Data Environment
Contoso has the following data environment
* The Sales division uses a Microsoft Power B1 Premium capacity.
* The semantic model of the Online Sales department includes a fact table named Orders that uses import mode. In the system of origin, the OrderlD value represents the sequence in which orders are created.
* The Research department uses an on-premises. third-party data warehousing product.
* Fabric is enabled for contoso.com.
* An Azure Data Lake Storage Gen2 storage account named storage1 contains Research division data for a product line named Producthne1. The data is in the delta format.
* A Data Lake Storage Gen2 storage account named storage2 contains Research division data for a product line named Productline2. The data is in the CSV format.
Planned Changes
Contoso plans to make the following changes:
* Enable support for Fabric in the Power Bl Premium capacity used by the Sales division.
* Make all the data for the Sales division and the Research division available in Fabric.
* For the Research division, create two Fabric workspaces named Producttmelws and Productline2ws.
* in Productlinelws. create a lakehouse named LakehouseV
* In Lakehouse1. create a shortcut to storage1 named ResearchProduct.
Data Analytics Requirements
Contoso identifies the following data analytics requirements:
* All the workspaces for the Sales division and the Research division must support all Fabric experiences.
* The Research division workspaces must use a dedicated, on-demand capacity that has per-minute billing.
* The Research division workspaces must be grouped together logically to support OneLake data hub filtering based on the department name.
* For the Research division workspaces, the members of ResearchRevtewersGroupl must be able to read lakehouse and warehouse data and shortcuts by using SQL endpoints.
* For the Research division workspaces, the members of ResearchReviewersGroup2 must be able to read lakehouse data by using Lakehouse explorer.
* All the semantic models and reports for the Research division must use version control that supports branching Data Preparation Requirements Contoso identifies the following data preparation requirements:
* The Research division data for Producthne2 must be retrieved from Lakehouset by using Fabric notebooks.
* All the Research division data in the lakehouses must be presented as managed tables in Lakehouse explorer.
Semantic Model Requirements
Contoso identifies the following requirements for implementing and managing semantic models;
* The number of rows added to the Orders table during refreshes must be minimized.
* The semantic models in the Research division workspaces must use Direct Lake mode.
General Requirements
Contoso identifies the following high-level requirements that must be considered for all solutions:
* Follow the principle of least privilege when applicable
* Minimize implementation and maintenance effort when possible.
質問 # 19
You have a Fabric workspace named Workspace1 that contains a dataflow named Dataflow1. Dataflow1 returns 500 rows of data.
You need to identify the min and max values for each column in the query results.
Which three Data view options should you select? Each correct answer presents part of the solution.
NOTE: Each correct answer is worth one point.
正解:A、D、E
解説:
Scenario Recap
* You are working in Dataflow Gen2 inside a Fabric workspace.
* Dataflow1 returns 500 rows.
* You want to identify the minimum and maximum values for each column in the query results.
Key Concept: Column Profiling in Power Query (Fabric Dataflows)
In Power Query (used in Dataflows), profiling tools help you inspect and understand data. The following profiling features are available:
* Column quality # Shows % valid, % error, % empty values.
* Does not show min/max values.
* Column distribution # Shows distinct and unique value distribution (frequency).
* Does not show min/max values.
* Column profile # Provides statistics for each column including:
* Minimum value
* Maximum value
* Average, Standard deviation, Count, etc.
* This is the feature required here.
* Details pane # Displays the profiling results when profiling options (such as column profile) are enabled.
Correct Answer Breakdown
B). Show column profile in details pane
* Must be selected to display min/max, averages, and distribution in the details pane.
C). Enable details pane
* Required to actually display the profiling results. Without enabling the details pane, you cannot see column profiles.
E). Enable column profile
* Enables the calculation of statistics (min, max, avg, etc.) for each column.
These three together give you the ability to see min and max values.
Why the Other Options Are Incorrect
A). Show column quality details
* Shows only valid/empty/error statistics. No min/max.
D). Show column value distribution
* Displays distinct/unique values and counts but does not calculate min/max.
Summary
To identify min and max values per column in a Fabric Dataflow, you must:
* Enable the details pane
* Enable column profile
* Show column profile in details pane
Correct answers: B, C, E
References
* Data profiling tools in Power Query
* Column profiling options in Power Query
* Fabric Dataflows Gen2 overview
質問 # 20
You have a Fabric tenant that contains a lakehouse named Lakehouse1. Lakehouse1 contains a subfolder named Subfolder1 that contains CSV files. You need to convert the CSV files into the delta format that has V-Order optimization enabled. What should you do from Lakehouse explorer?
正解:B
解説:
To convert CSV files into the delta format with Z-Order optimization enabled, you should use the Optimize feature (D) from Lakehouse Explorer. This will allow you to optimize the file organization for the most efficient querying. References = The process for converting and optimizing file formats within a lakehouse is discussed in the lakehouse management documentation.
質問 # 21
......
Microsoftご存知のように、競争の激しい世界では、PassTestのDP-600認定などのソフトパワーを向上させる以外に選択肢はありません。 あなたは転職の状態にあるかもしれませんが、あなた自身のキャリアを持つことは信じられないほど難しいです。 それからあなた自身を改善し、不可能な任務を可能にする方法はあなたの優先事項です。 Implementing Analytics Solutions Using Microsoft Fabricガイドトレントがあなたを助けてくれます。 DP-600質問トレントを使用してv試験に合格し、履歴書を強調することは非常に重要です。したがって、職場で成功を収めることができます。
DP-600合格体験記: https://www.passtest.jp/Microsoft/DP-600-shiken.html
2026年PassTestの最新DP-600 PDFダンプおよびDP-600試験エンジンの無料共有:https://drive.google.com/open?id=1gZWI85TBo5hMTN7af0olk5YFJXpXgXui