Außerdem sind jetzt einige Teile dieser DeutschPrüfung ARA-C01 Prüfungsfragen kostenlos erhältlich: https://drive.google.com/open?id=1B5U_hgs8NXxLCM9-BnsW58f9eZngo2rB
Schulungsunterlagen zur Snowflake ARA-C01 Zertifizierungsprüfung von DeutschPrüfung sind effizient, die von manchen Experten und einigen bestandenen Kandidaten bewiesen sind. Sie sind fast gleich wie die echten ARA-C01 Prüfungsfragen. Sie können Ihnen dabei helfen, die ARA-C01 Zertifizierungsprüfung zu bestehen. Wir werden Ihnen alle Ihren bezahlten Summe zurückgeben, entweder Sie die ARA-C01 Prüfung nicht bestehen, oder die Testaufgaben von Snowflake ARA-C01 irgend ein Qualitätsproblem haben. Vertrauen Sie bitte auf DeutschPrüfung, denn wir werden Ihnen stets begleiten.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Engineering | 25% | - Transformation and processing frameworks - Data pipeline and integration design - Data loading and unloading solutions |
| Topic 2: Accounts and Security | 25% | - Security principles and implementation scenarios - Security, compliance and governance architecture - Account and database strategy design |
| Topic 3: Performance Optimization | 20% | - Query performance tuning - Cost optimization and resource management - Clustering and partitioning strategies - Virtual warehouse configuration and sizing |
| Topic 4: Snowflake Architecture | 30% | - Data modeling and use cases - Data sharing architecture design - Data protection and recovery strategies - Development lifecycle and workload support - Object hierarchy and architectural impact |
>> ARA-C01 Ausbildungsressourcen <<
Wenn Sie die Unterlagen von DeutschPrüfung kaufen, bekommen Sie einjährigen kostlosen Aktualisierungsservice. Wenn die Dumps aktualisiert sind, werden wir DeutschPrüfung Ihnen die neuesten Versionen per E-Mail senden. Sie können auch an uns E-Mails schreiben, die neuesten Prüfungsunterlagen zur Snowflake ARA-C01 Zertifizierung zu fordern. Und DeutschPrüfung kann Ihnen die Aktualisierungsservice innerhalb einem Jahr kostenlos bieten, obwohl Sie diese Snowflake ARA-C01 Prüfung erfolgsreich machen.
198. Frage
How can the Snowflake context functions be used to help determine whether a user is authorized to see data that has column-level security enforced? (Select TWO).
Antwort: C,E
Begründung:
Snowflake context functions are functions that return information about the current session, user, role, warehouse, database, schema, or object. They can be used to help determine whether a user is authorized to see data that has column-level security enforced by setting masking policy conditions based on the context functions. The following context functions are relevant for column-level security:
* current_role: This function returns the name of the role in use for the current session. It can be used to set masking policy conditions that target the current session and are not affected by the execution context of the SQL statement. For example, a masking policy condition using current_role can allow or deny access to a column based on the role that the user activated in the session.
* invoker_role: This function returns the name of the executing role in a SQL statement. It can be used to set masking policy conditions that target the executing role and are affected by the execution context of the SQL statement. For example, a masking policy condition using invoker_role can allow or deny access to a column based on the role that the user specified in the SQL statement, such as using the AS ROLE clause or a stored procedure.
* is_role_in_session: This function returns TRUE if the user's current role in the session (i.e. the role returned by current_role) inherits the privileges of the specified role. It can be used to set masking policy conditions that involve role hierarchy and privilege inheritance. For example, a masking policy condition using is_role_in_session can allow or deny access to a column based on whether the user's current role is a lower privilege role in the specified role hierarchy.
The other options are not valid ways to use the Snowflake context functions for column-level security:
* Set masking policy conditions using is_role_in_session targeting the role in use for the current account.
This option is incorrect because is_role_in_session does not target the role in use for the current account, but rather the role in use for the current session. Also, the current account is not a role, but rather a logical entity that contains users, roles, warehouses, databases, and other objects.
* Determine if there are ownership privileges on the masking policy that would allow the use of any function. This option is incorrect because ownership privileges on the masking policy do not affect the use of any function, but rather the ability to create, alter, or drop the masking policy. Also, this is not a way to use the Snowflake context functions, but rather a way to check the privileges on the masking policy object.
* Assign the accountadmin role to the user who is executing the object. This option is incorrect because assigning the accountadmin role to the user who is executing the object does not involve using the Snowflake context functions, but rather granting the highest-level role to the user. Also, this is not a recommended practice for column-level security, as it would give the user full access to all objects and data in the account, which could compromise data security and governance.
References:
* Context Functions
* Advanced Column-level Security topics
* Snowflake Data Governance: Column Level Security Overview
* Data Security Snowflake Part 2 - Column Level Security
199. Frage
A table for IOT devices that measures water usage is created. The table quickly becomes large and contains more than 2 billion rows.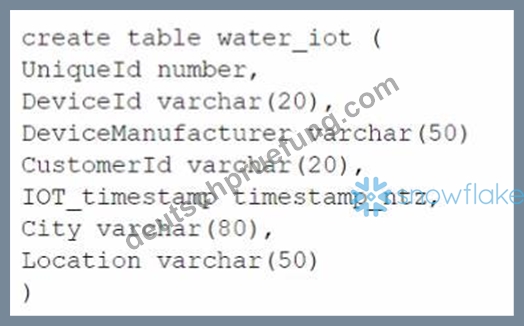
The general query patterns for the table are:
1. DeviceId, lOT_timestamp and Customerld are frequently used in the filter predicate for the select statement
2. The columns City and DeviceManuf acturer are often retrieved
3. There is often a count on Uniqueld
Which field(s) should be used for the clustering key?
Antwort: A
Begründung:
A clustering key is a subset of columns or expressions that are used to co-locate the data in the same micro-partitions, which are the units of storage in Snowflake. Clustering can improve the performance of queries that filter on the clustering key columns, as it reduces the amount of data that needs to be scanned. The best choice for a clustering key depends on the query patterns and the data distribution in the table. In this case, the columns DeviceId, IOT_timestamp, and CustomerId are frequently used in the filter predicate for the select statement, which means they are good candidates for the clustering key. The columns City and DeviceManufacturer are often retrieved, but not filtered on, so they are not as important for the clustering key.
The column UniqueId is used for counting, but it is not a good choice for the clustering key, as it is likely to have a high cardinality and a uniform distribution, which means it will not help to co-locate the data.
Therefore, the best option is to use DeviceId and CustomerId as the clustering key, as they can help to prune the micro-partitions and speed up the queries. References: Clustering Keys & Clustered Tables, Micro-partitions & Data Clustering, A Complete Guide to Snowflake Clustering
200. Frage
What transformations are supported in the below SQL statement? (Select THREE).
CREATE PIPE ... AS COPY ... FROM (...)
Antwort: B,C,E
Begründung:
* The SQL statement is a command for creating a pipe in Snowflake, which is an object that defines the COPY INTO <table> statement used by Snowpipe to load data from an ingestion queue into tables1. The statement uses a subquery in the FROM clause to transform the data from the staged files before loading it into the table2.
* The transformations supported in the subquery are as follows2:
* Data can be filtered by an optional WHERE clause, which specifies a condition that must be satisfied by the rows returned by the subquery. For example:
SQLAI-generated code. Review and use carefully. More info on FAQ.
create pipe mypipe as
copy into mytable
from (
select * from @mystage
where col1 = 'A' and col2 > 10
);
* Columns can be reordered, which means changing the order of the columns in the subquery to match the order of the columns in the target table. For example:
SQLAI-generated code. Review and use carefully. More info on FAQ.
create pipe mypipe as
copy into mytable (col1, col2, col3)
from (
select col3, col1, col2 from @mystage
);
* Columns can be omitted, which means excluding some columns from the subquery that are not needed in the target table. For example:
SQLAI-generated code. Review and use carefully. More info on FAQ.
create pipe mypipe as
copy into mytable (col1, col2)
from (
select col1, col2 from @mystage
);
* The other options are not supported in the subquery because2:
* Type casts are not supported, which means changing the data type of a column in the subquery.
For example, the following statement will cause an error:
SQLAI-generated code. Review and use carefully. More info on FAQ.
create pipe mypipe as
copy into mytable (col1, col2)
from (
select col1::date, col2 from @mystage
);
* Incoming data can not be joined with other tables, which means combining the data from the staged files with the data from another table in the subquery. For example, the following statement will cause an error:
SQLAI-generated code. Review and use carefully. More info on FAQ.
create pipe mypipe as
copy into mytable (col1, col2, col3)
from (
select s.col1, s.col2, t.col3 from @mystage s
join othertable t on s.col1 = t.col1
);
* The ON ERROR - ABORT statement command can not be used, which means aborting the entire load operation if any error occurs. This command can only be used in the COPY INTO <table> statement, not in the subquery. For example, the following statement will cause an error:
SQLAI-generated code. Review and use carefully. More info on FAQ.
create pipe mypipe as
copy into mytable
from (
select * from @mystage
on error abort
);
References:
* 1: CREATE PIPE | Snowflake Documentation
* 2: Transforming Data During a Load | Snowflake Documentation
201. Frage
What transformations are supported in the following SQL statement? (Select THREE).
CREATE PIPE ... AS
COPY INTO ...
FROM ( ... )
Antwort: C,D,E
Begründung:
Snowflake's COPY INTO statement (including when used with Snowpipe) supports a limited but useful set of transformations. Data can be filtered using a WHERE clause when loading from a staged SELECT statement, enabling simple row-level filtering (Answer A). Columns can also be reordered by explicitly selecting fields in a different order than they appear in the source (Answer B). Additionally, type casting is supported, allowing raw data to be cast into target column data types during ingestion (Answer D).
However, COPY INTO does not support joins with other tables; it is designed for ingestion, not complex transformations. Columns can be omitted implicitly by not selecting them, but this is not considered a transformation feature in the context of Snowpipe exam questions. The ON_ERROR option is an error- handling configuration, not a transformation.
SnowPro Architect candidates are expected to recognize that COPY INTO and Snowpipe are ingestion- focused tools. More complex transformations should be handled downstream using streams and tasks, dynamic tables, or transformation frameworks like dbt.
=========
202. Frage
A data ingestion pipeline loads data randomly throughout the day. A requirement states that data must be processed within 10 minutes of landing in Snowflake.
What is the MOST cost-effective solution?
Antwort: C
Begründung:
Streams and tasks are Snowflake's native mechanism for incremental data processing. A stream tracks row- level changes (inserts, updates, deletes) on a table, while tasks enable scheduled or conditional execution of SQL statements.
Using SYSTEM$STREAM_HAS_DATA allows the task to run only when new data is available, avoiding unnecessary compute usage (Answer D). This makes the solution both timely-meeting the 10-minute SLA- and cost-efficient, as compute resources are consumed only when there is work to do.
Views alone do not materialize transformations and still require compute at query time. Third-party orchestration introduces unnecessary operational overhead and cost. Running a task on a fixed schedule without checking stream data would waste compute cycles.
This pattern-streams + tasks with conditional execution-is a core SnowPro Architect design pattern for efficient, low-latency data pipelines.
=========
203. Frage
......
Ea ist Traum der Angestellten, sich in der IT-Branche engagieren zu können, die Snowflake ARA-C01 Zertifizierungsprüfung zu bestehen. Wenn Sie Ihren Traum verwirklichen wollen, brauchen Sie nur fachliche Ausbildung zu wählen. DeutschPrüfung ist eine fachliche Website, die Schulungsunterlagen zur Snowflake ARA-C01 Zertifizierung bietet. Wählen Sie DeutschPrüfung. Und wir versprechen, dass Sie den Erfolg erlangen und Ihren Traum verwirklichen , egal welches hohes Ziel Sie anstreben, können.
ARA-C01 Testking: https://www.deutschpruefung.com/ARA-C01-deutsch-pruefungsfragen.html
Außerdem sind jetzt einige Teile dieser DeutschPrüfung ARA-C01 Prüfungsfragen kostenlos erhältlich: https://drive.google.com/open?id=1B5U_hgs8NXxLCM9-BnsW58f9eZngo2rB