Databricks-Certified-Data-Engineer-Professional Visual Cert Exam | Exam Databricks-Certified-Data-Engineer-Professional Pattern

The Pass4cram offers three formats for applicants to practice and prepare for the Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) exam as per their needs. The pdf format of Pass4cram is portable and can be used on laptops, tablets, and smartphones. Print real Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) exam questions in our PDF file. The pdf is user-friendly and accessible on any smart device, allowing applicants to study from anywhere at any time.
| Section | Weight | Objectives |
|---|
| Topic 1: Data Quality and Governance | 12% | - Data Quality
- Data Lineage
- Governance
|
| Topic 2: Databricks Lakehouse Platform | 24% | - Lakehouse Architecture
- Unity Catalog
- Data Management
- Delta Lake
|
| Topic 3: Monitoring and Troubleshooting | 16% | - Troubleshooting
- Performance Optimization
- Monitoring
|
| Topic 4: Data Modeling and Storage | 20% | - File Formats
- Data Modeling
- Storage Optimization
|
| Topic 5: Data Processing | 28% | - Data Transformation
- ETL Pipelines
- Structured Streaming
- Spark SQL
|
>> Databricks-Certified-Data-Engineer-Professional Visual Cert Exam <<
Exam Databricks-Certified-Data-Engineer-Professional Pattern, Test Databricks-Certified-Data-Engineer-Professional Registration
Our company is a multinational company which is famous for the Databricks-Certified-Data-Engineer-Professional training materials in the international market. After nearly ten years' efforts, now our company have become the topnotch one in the field, therefore, if you want to pass the Databricks-Certified-Data-Engineer-Professional Exam as well as getting the related certification at a great ease, I strongly believe that the Databricks-Certified-Data-Engineer-Professional study materials compiled by our company is your solid choice.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q221-Q226):
NEW QUESTION # 221
A nightly job ingests data into a Delta Lake table using the following code:
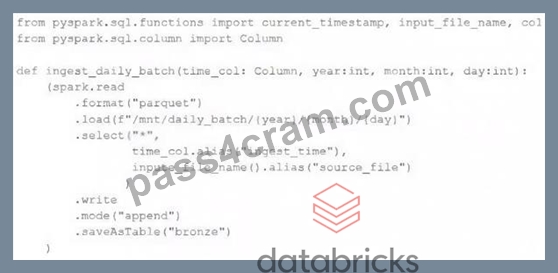
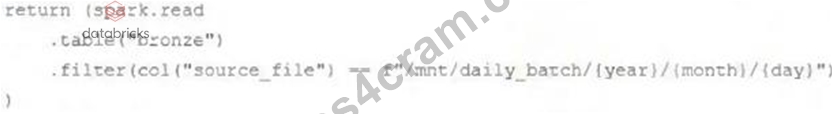
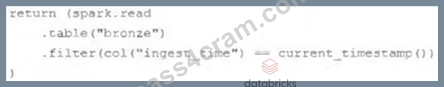
The next step in the pipeline requires a function that returns an object that can be used to manipulate new records that have not yet been processed to the next table in the pipeline.
Which code snippet completes this function definition?
def new_records():
- A.
- B. return spark.read.option("readChangeFeed", "true").table ("bronze")
- C.
- D. return spark.readStream.load("bronze")
- E. return spark.readStream.table("bronze")
Answer: A
Explanation:
https://docs.databricks.com/en/delta/delta-change-data-feed.html
NEW QUESTION # 222
The data engineering team maintains a table of aggregate statistics through batch nightly updates. This includes total sales for the previous day alongside totals and averages for a variety of time periods including the 7 previous days, year-to-date, and quarter-to-date. This table is named store_saies_summary and the schema is as follows:

The table daily_store_sales contains all the information needed to update store_sales_summary.
The schema for this table is:
store_id INT, sales_date DATE, total_sales FLOAT
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from If daily_store_sales is implemented as a Type 1 table and the total_sales column might be adjusted after manual data auditing, which approach is the safest to generate accurate reports in the store_sales_summary table?
- A. Implement the appropriate aggregate logic as a Structured Streaming read against the daily_store_sales table and use upsert logic to update results in the store_sales_summary table.
- B. Implement the appropriate aggregate logic as a batch read against the daily_store_sales table and use upsert logic to update results in the store_sales_summary table.
- C. Implement the appropriate aggregate logic as a batch read against the daily_store_sales table and overwrite the store_sales_summary table with each Update.
- D. Implement the appropriate aggregate logic as a batch read against the daily_store_sales table and append new rows nightly to the store_sales_summary table.
- E. Use Structured Streaming to subscribe to the change data feed for daily_store_sales and apply changes to the aggregates in the store_sales_summary table with each update.
Answer: C
NEW QUESTION # 223
A data engineer is designing a system to process batch patient encounter data stored in an S3 bucket, creating a Delta table (patient_encounters) with columns encounter_id, patient_id, encounter_date, diagnosis_code, and treatment_cost. The table is queried frequently by patient_id and encounter_date, requiring fast performance. Fine-grained access controls must be enforced. The engineer wants to minimize maintenance and boost performance. How should the data engineer create the patient_encounters table?
- A. Create a managed table in Unity Catalog. Configure Unity Catalog permissions for access controls, and rely on predictive optimization to enhance query performance and simplify maintenance.
- B. Create an external table in Unity Catalog, specifying an S3 location for the data files. Enable predictive optimization through table properties, and configure Unity Catalog permissions for access controls.
- C. Create a managed table in Hive Metastore. Configure Hive Metastore permissions for access controls, and rely on predictive optimization to enhance query performance and simplify maintenance.
- D. Create a managed table in Unity Catalog. Configure Unity Catalog permissions for access controls, schedule jobs to run OPTIMIZE and VACUUM commands daily to achieve best performance.
Answer: A
Explanation:
Databricks documentation specifies that Unity Catalog managed tables are the preferred choice for secure, low-maintenance Delta Lake architectures. Managed tables provide full lifecycle management, including metadata, file storage, and access control integration with Unity Catalog.
Fine-grained permissions can be enforced at the column and row level through built-in Unity Catalog governance.
Additionally, Predictive Optimization (Auto Optimize + Auto Compaction) automatically manages file sizes, metadata pruning, and layout optimization, eliminating the need for manual maintenance such as scheduling OPTIMIZE or VACUUM.
External tables (A) require manual path management, and Hive Metastore tables (D) do not support Unity Catalog access policies. Therefore, creating a managed Unity Catalog table with predictive optimization provides both the security and performance benefits needed, making B the correct solution.
NEW QUESTION # 224
A user wants to use DLT expectations to validate that a derived table report contains all records from the source, included in the table validation_copy.
The user attempts and fails to accomplish this by adding an expectation to the report table definition.
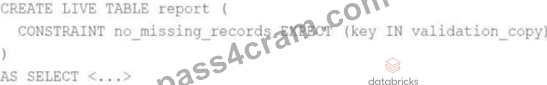
Which approach would allow using DLT expectations to validate all expected records are present in this table?
- A. Define a SQL UDF that performs a left outer join on two tables, and check if this returns null values for report key values in a DLT expectation for the report table.
- B. Define a temporary table that perform a left outer join on validation_copy and report, and define an expectation that no report key values are null
- C. Define a view that performs a left outer join on validation_copy and report, and reference this view in DLT expectations for the report table
- D. Define a function that performs a left outer join on validation_copy and report and report, and check against the result in a DLT expectation for the report table
Answer: C
Explanation:
To validate that all records from the source are included in the derived table, creating a view that performs a left outer join between the validation_copy table and the report table is effective. The view can highlight any discrepancies, such as null values in the report table's key columns, indicating missing records. This view can then be referenced in DLT (Delta Live Tables) expectations for the report table to ensure data integrity. This approach allows for a comprehensive comparison between the source and the derived table.
NEW QUESTION # 225
A streaming video analytics team ingests billions of events daily into a Unity Catalog-managed Delta table video_events. Analysts run ad-hoc point-lookup queries on columns like user_id, campaign_id, and region. The team manually runs OPTIMIZE video_events ZORDER BY (user_id, campaign_id, region), but still sees poor performance on recent data and dislikes the operational overhead. The team wants a hands-off way to keep hot columns co-located as query patterns evolve. Which Delta capability should the team leverage on video_events?
- A. Enable Delta caching.
- B. Enable auto-compaction (optimizeWrite and autoCompact).
- C. Utilize Liquid Clustering (CLUSTER BY AUTO) and Predictive Optimization.
- D. Schedule OPTIMIZE/ZORDER to run after each job to improve recent file performance.
Answer: C
Explanation:
According to Databricks Delta Lake optimization documentation, Liquid Clustering is a next- generation file organization capability that automatically manages file co-location without requiring explicit partitioning or manual Z-ORDERing. When combined with Predictive Optimization, Databricks automatically maintains clustering across frequently filtered or queried columns, adapting dynamically as query workloads evolve.
This approach eliminates the need for manual maintenance (such as periodic OPTIMIZE or Z- ORDER commands) while improving query performance on large tables--particularly for high- ingest streaming workloads.
Delta caching (B) only improves performance for cached queries and does not address file layout issues, and (D) handles file size optimization but not clustering. Thus, C is the most efficient, modern, and low-maintenance solution recommended by Databricks.
NEW QUESTION # 226
......
Therefore, you have the option to use Databricks Databricks-Certified-Data-Engineer-Professional PDF questions anywhere and anytime. Pass4cram Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) dumps are designed according to the Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) certification exam standard and have hundreds of questions similar to the actual Databricks-Certified-Data-Engineer-Professional Exam. Pass4cram Databricks web-based practice exam software also works without installation.
Exam Databricks-Certified-Data-Engineer-Professional Pattern: https://www.pass4cram.com/Databricks-Certified-Data-Engineer-Professional_free-download.html
- Databricks-Certified-Data-Engineer-Professional Guaranteed Success 🎋 Databricks-Certified-Data-Engineer-Professional Updated CBT 🤓 Databricks-Certified-Data-Engineer-Professional Updated CBT ↗ Download ( Databricks-Certified-Data-Engineer-Professional ) for free by simply searching on ⮆ www.testkingpass.com ⮄ 👑Databricks-Certified-Data-Engineer-Professional Frenquent Update
- Databricks-Certified-Data-Engineer-Professional Test Simulator Online 🌑 Exam Databricks-Certified-Data-Engineer-Professional Overview 🌺 Databricks-Certified-Data-Engineer-Professional Reliable Exam Dumps 🤶 Open 《 www.pdfvce.com 》 and search for 《 Databricks-Certified-Data-Engineer-Professional 》 to download exam materials for free 💒Databricks-Certified-Data-Engineer-Professional Reliable Test Topics
- Efficient Databricks-Certified-Data-Engineer-Professional Visual Cert Exam Supply you Fast-Download Exam Pattern for Databricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam to Study casually ⛺ Go to website ➽ www.pdfdumps.com 🢪 open and search for ➽ Databricks-Certified-Data-Engineer-Professional 🢪 to download for free 🐨Test Databricks-Certified-Data-Engineer-Professional Price
- Reliable Databricks-Certified-Data-Engineer-Professional Visual Cert Exam Supply you Verified Exam Pattern for Databricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam to Prepare easily 🥯 Search on ➥ www.pdfvce.com 🡄 for ➤ Databricks-Certified-Data-Engineer-Professional ⮘ to obtain exam materials for free download 🐱Databricks-Certified-Data-Engineer-Professional Test Vce
- 2026 Databricks-Certified-Data-Engineer-Professional Visual Cert Exam | Updated Databricks Certified Data Engineer Professional Exam 100% Free Exam Pattern ⏫ Search for { Databricks-Certified-Data-Engineer-Professional } and download exam materials for free through “ www.dumpsmaterials.com ” 🪀Databricks-Certified-Data-Engineer-Professional Test Questions
- New Databricks-Certified-Data-Engineer-Professional Test Questions 🥵 Databricks-Certified-Data-Engineer-Professional Reliable Braindumps Pdf ⤵ Databricks-Certified-Data-Engineer-Professional Reliable Dumps Sheet 🍕 Copy URL ☀ www.pdfvce.com ️☀️ open and search for [ Databricks-Certified-Data-Engineer-Professional ] to download for free ⛺Databricks-Certified-Data-Engineer-Professional Reliable Dumps Sheet
- Databricks-Certified-Data-Engineer-Professional Visual Cert Exam - Leader in Certification Exams Materials - Exam Databricks-Certified-Data-Engineer-Professional Pattern 🤜 Easily obtain free download of ➡ Databricks-Certified-Data-Engineer-Professional ️⬅️ by searching on ☀ www.testkingpass.com ️☀️ 💡Databricks-Certified-Data-Engineer-Professional Valid Dumps Demo
- Latest Databricks-Certified-Data-Engineer-Professional Dumps Book ⛷ New Databricks-Certified-Data-Engineer-Professional Test Questions 🍯 Databricks-Certified-Data-Engineer-Professional Reliable Dumps Sheet 🏴 Easily obtain ☀ Databricks-Certified-Data-Engineer-Professional ️☀️ for free download through ▷ www.pdfvce.com ◁ 🏘Exam Databricks-Certified-Data-Engineer-Professional Overview
- High-quality Databricks-Certified-Data-Engineer-Professional Visual Cert Exam - Leader in Qualification Exams - Complete Databricks Databricks Certified Data Engineer Professional Exam 🎋 Copy URL ➥ www.vceengine.com 🡄 open and search for ⏩ Databricks-Certified-Data-Engineer-Professional ⏪ to download for free 😡Databricks-Certified-Data-Engineer-Professional Test Questions
- Databricks-Certified-Data-Engineer-Professional Guaranteed Success 💌 Latest Databricks-Certified-Data-Engineer-Professional Dumps Book 🔭 Latest Databricks-Certified-Data-Engineer-Professional Dumps Book 📝 Search for ( Databricks-Certified-Data-Engineer-Professional ) and easily obtain a free download on ☀ www.pdfvce.com ️☀️ 🛩Databricks-Certified-Data-Engineer-Professional Frenquent Update
- Databricks-Certified-Data-Engineer-Professional Reliable Braindumps Pdf 🔊 Customized Databricks-Certified-Data-Engineer-Professional Lab Simulation 📬 New Databricks-Certified-Data-Engineer-Professional Test Questions 🌰 Open website ⏩ www.troytecdumps.com ⏪ and search for ⏩ Databricks-Certified-Data-Engineer-Professional ⏪ for free download 🈺Latest Databricks-Certified-Data-Engineer-Professional Dumps Book
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, github.com, Disposable vapes