P.S. Free 2026 Microsoft AI-300 dumps are available on Google Drive shared by Real4dumps: https://drive.google.com/open?id=1diSSFovkBkr4h2jsHLLJj1sR6S7jNHML
With our AI-300 study materials, all your agreeable outcomes are no longer dreams for you. And with the aid of our Operationalizing Machine Learning and Generative AI Solutions AI-300 exam preparation to improve your grade and change your states of life and get amazing changes in career, everything is possible. It all starts from our Microsoft AI-300 learning questions.
| Section | Objectives |
|---|---|
| Design and implement a GenAIOps infrastructure | - Manage API keys, rate limits, and responsible AI guardrails - Set up Microsoft Foundry and Azure AI services for generative AI workloads - Implement RAG (Retrieval-Augmented Generation) pipelines and vector search - Configure prompt orchestration, prompt flows, and agent frameworks |
| Optimize generative AI systems and model performance | - Optimize inference performance, caching, and throughput - Tune prompts, system messages, and grounding strategies - Implement cost management and scaling strategies for GenAI workloads - Fine-tune and distill models for specific use cases |
| Implement generative AI quality assurance and observability | - Evaluate generative AI outputs for quality, safety, and grounding - Conduct red teaming, adversarial testing, and content filtering - Monitor latency, token usage, cost, and error rates - Implement logging, tracing, and telemetry for GenAI applications |
| Design and implement an MLOps infrastructure | - Configure source control, CI/CD pipelines, and automation for ML workflows - Manage environments, data stores, and model registries - Set up Azure Machine Learning workspace and compute targets - Implement security, governance, and compliance for MLOps |
| Implement machine learning model lifecycle and operations | - Monitor model performance, data drift, and operational health - Deploy models to real-time and batch endpoints - Train, register, and version models using Azure Machine Learning - Retrain, update, and manage model versions in production |
If you don't want to waste much time on preparing for your exam, Microsoft AI-300 exam braindumps files will be a shortcut for you. Good exam materials make you twice the result with half the effort. Our Microsoft AI-300 exam braindumps cover many questions and answers of the real test so that you can be familiar with the real test question. When you attend Microsoft AI-300 Exam, it is easy for you to keep good mood and control your finishing time.
NEW QUESTION # 146
A team runs training and inference jobs in Azure Machine Learning.
The team experiences inconsistent runtime dependencies that cause variation in results.
You need to ensure that all jobs use the same execution dependencies.
Which asset should you define?
Answer: A
Explanation:
To guarantee consistent runtime dependencies in Azure Machine Learning, you must use Azure ML Environments configured with custom Docker images or pinned Conda dependencies.
An Environment asset encapsulates the exact Python packages, environment variables, and software settings for your training and inference workloads.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-set-up-training-targets
NEW QUESTION # 147
A team deploys a model to a real-time endpoint in Azure Machine Learning. You deploy some updates to the endpoint.
The endpoint returns errors after the new deployment is released.
You need to restore the service as quickly as possible.
What should you do first?
Answer: C
Explanation:
Speed of recovery is the central requirement. Rolling back traffic to the previous deployment is the fastest possible action: because the previous deployment still exists on the same endpoint, you simply update the traffic weights - setting the old deployment to 100% and the new deployment to 0% - using a single Azure ML CLI command or SDK call that completes in seconds without reprovisioning any compute. Deleting and redeploying (option B) requires tearing down the endpoint, waiting for deprovisioning, recreating it, re- deploying the model, and waiting for containers to start - potentially 10 to 30 minutes. Changing authentication type (option C) does not affect application errors caused by a bad model. Increasing compute size (option D) does not fix model logic errors. The entire reason Azure ML supports multiple concurrent deployments with traffic splitting is precisely to enable this instant rollback pattern.
Microsoft Learn Reference Topic: Roll back deployments on managed online endpoints - Azure Machine Learning safe deployment practices
NEW QUESTION # 148
You manage an Azure Machine Learning workspace named workspace1 by using the Python SDK v2. You create a General Purpose v2 Azure storage account named mlstorage 1. The storage account includes a publicly accessible container named mlcontainer 1. The container stores 10 blobs with files in the CSV format.
You must develop Python SDK v2 code to create a data asset referencing all blobs in the container named mlcontainer 1.
You need to complete the Python SDK v2 code.
How should you complete the code? To answer, select the appropriate options in the answer area . NOTE:
Each correct selection is worth one point.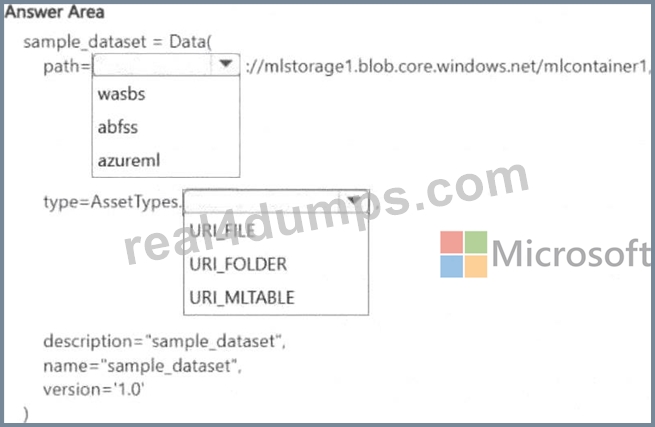
Answer:
Explanation: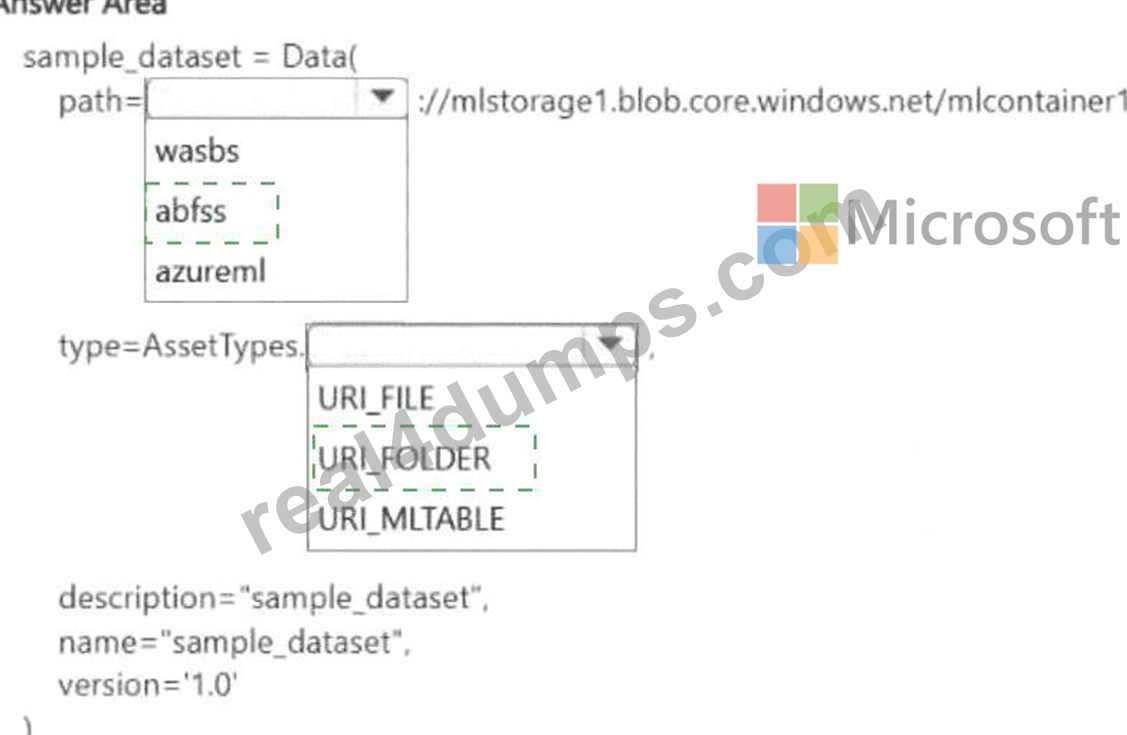
Explanation:
Because you want to reference all blobs in a container rather than a single file, the correct asset type is AssetTypes.URI_FOLDER. This type points to a directory-level URI, allowing Azure ML to traverse all files within it. For a publicly accessible Azure Blob Storage container, the URI follows the pattern
https://storage_account.blob.core.windows.net/container_name/. You then create the Data object with the correct type, path, name, and version parameters, and register it in the workspace using ml_client.data.
create_or_update. Do not use AssetTypes.URI_FILE, which references a single file. Do not use AssetTypes.
MLTABLE unless you have an MLTable YAML descriptor. URI_FOLDER is the correct choice for referencing a collection of CSV blobs in an Azure Blob Storage container, allowing Azure ML to discover and process all files within the specified path.
Microsoft Learn Reference Topic: Create and manage data assets in Azure Machine Learning Python SDK v2 - URI_FOLDER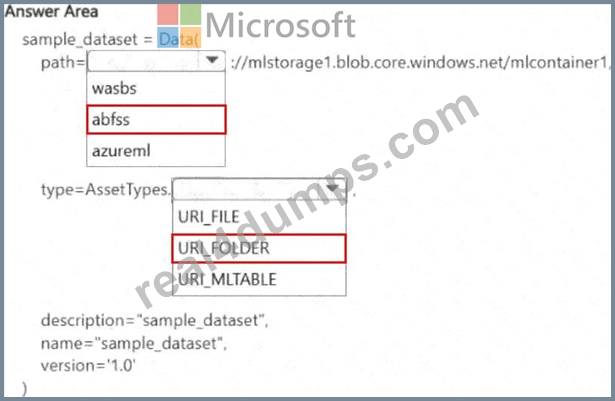
NEW QUESTION # 149
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have an Azure Machine Learning workspace. You connect to a terminal session from the Notebooks page in Azure Machine Learning studio.
You plan to add a new Jupyter kernel that will be accessible from the same terminal session.
You need to perform the task that must be completed before you can add the new kernel.
Solution: Create an environment.
Does the solution meet the goal?
Answer: B
Explanation:
Correct:
* Create an environment.
Incorrect:
* Delete the Python 3.6 - AzureML kernel.
* Delete the Python 3.8 - AzureML kernel.
Note:
Before you can add a new Jupyter kernel on an Azure Machine Learning compute instance terminal, you must create a Conda environment.
Required Workflow
To officially provision and expose the new kernel to your Azure Machine Learning studio Notebooks, you need to execute the following full process from your terminal session:
Create the environment: Provision a new isolated environment (e.g., using conda create -n newenv python=3.10).
Activate the environment: Run conda activate newenv.
Install dependencies: Add the required ipykernel package using conda install ipykernel or pip install ipykernel.
Register the kernel: Bind the new environment configuration to the global Jupyter directory by running:
python -m ipykernel install --user --name newenv --display-name "My New Kernel" Reference:
https://docs.azure.cn/en-us/machine-learning/how-to-access-terminal
NEW QUESTION # 150
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You manage a Retrieval-Augmented Generation (RAG) application built on Microsoft Foundry.
The application retrieves documents from an indexed knowledge base and generates answers for internal users.
Recent feedback indicates that answers are fluent but sometimes include information that is not supported by the documents that were retrieved.
You need to evaluate whether a proposed change improves RAG answer quality by using supported and measurable techniques.
Solution: Review user feedback comments collected after deployment to determine whether answers appear more accurate.
Does the solution meet the goal?
Answer: B
Explanation:
Correct:
* Review user feedback comments collected after deployment to determine whether answers appear more accurate.
Relying solely on user feedback comments is not the proper immediate action for evaluating this specific issue but it is still the best choice.
Evaluate whether your proposed change improves the Retrieval-Augmented Generation (RAG) system by reducing hallucinations (unsupported information), you need to measure faithfulness and context relevance using automated, quantifiable metrics.
The proper course of action is to implement an LLM-as-a-Judge framework using an open-source evaluation library like Ragas or TruLens.
Recommended Evaluation Plan
Establish a baseline: Run your current RAG pipeline through a test dataset of 50-100 representative user queries.
Capture the outputs: Save the user query, the exact retrieved document snippets, and the generated response for every test.
Apply the change: Deploy your proposed modification (e.g., altered prompt, different temperature, or re-ranking algorithm).Run the evaluation: Pass the test dataset through the updated pipeline to generate a new set of responses.
Compare the metrics: Use the framework to score both sets of data and mathematically verify if the change reduced unsupported claims.
Incorrect:
* Compare embedding vector dimensions used by the retrieval pipeline before and after the change.
Comparing embedding vector dimensions is not a valid or effective method for measuring RAG answer quality. Vector dimensions (e.g., 1536 or 3072) are static architectural properties of your embedding model. They do not reflect factual accuracy, semantic grounding, or the rate of hallucinations in your text generation.
* Measure token throughput and average response latency before and after applying the proposed change.
Measuring token throughput and latency is not the correct action to solve this specific problem.
Reference:
https://www.getmaxim.ai/articles/how-to-evaluate-your-rag-system/
NEW QUESTION # 151
......
Maybe you are unfamiliar with our AI-300 latest material, but our AI-300 real questions are applicable to this exam with high passing rate up to 98 percent and over. Choosing from a wide assortment of practice materials, rather than aiming solely to make a profit from our AI-300 latest material, we are determined to offer help. Quick purchase process, free demos and various versions and high quality AI-300 Real Questions are al features of our advantageous practice materials. With passing rate up to 98 to 100 percent, you will get through the AI-300 practice exam with ease. So they can help you save time and cut down additional time to focus on the AI-300 practice exam review only.
AI-300 Exam Forum: https://www.real4dumps.com/AI-300_examcollection.html
P.S. Free & New AI-300 dumps are available on Google Drive shared by Real4dumps: https://drive.google.com/open?id=1diSSFovkBkr4h2jsHLLJj1sR6S7jNHML