Do you want to pass AI-200 exam and get the related certification within the minimum time and effort? If you would like to give me a positive answer, you really should keep a close eye on our website since you can find the best study material in here--our AI-200 training materials. We have helped millions of thousands of candidates to prepare for the AI-200 Exam and all of them have got a fruitful outcome, I wish you could be one of the beneficiaries of our training materials in the near future. The advantages of our AI-200 test prep are more than you can imagine.
| Section | Objectives |
|---|---|
| Topic 1: Implement Azure AI solutions | - Implement computer vision solutions - Implement generative AI solutions using Azure OpenAI - Implement natural language processing solutions - Implement knowledge mining with Azure AI Search |
| Topic 2: Implement and monitor AI workloads | - Monitor performance and troubleshoot issues - Deploy AI models and services |
| Topic 3: Plan and manage Azure AI solutions | - Select appropriate Azure AI services - Plan security and compliance requirements - Monitor and optimize AI solutions |
>> Valid Microsoft AI-200 Test Pdf <<
There are numerious AI-200 exam dumps for the candidates to select for their preparation the exams, some candidates may get confused by so many choice. Our AI-200 learning materials have free demo for the candidates, and they will have a general idea about the AI-200 Learning Materials. You can obtain the AI-200 learning materials for about ten minutes. The payment is also quite easy: online payment with credit card, and the private information of the you is also guaranteed.
NEW QUESTION # 38
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure.
The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security.
The solution must meet strict performance, scalability, and security requirements.
Current environment
Application architecture
The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
Semantic retrieval uses metadata filtering combined with vector similarity search.
Azure Managed Redis is used as a caching layer.
Front-end and API workloads are deployed to Azure Container Apps (ACA).
Batch model retraining workloads run in Azure Kubernetes Service (AKS).
Container and CI/CD
Container images are stored in Azure Container Registry (ACR).
CI/CD uses ACR Tasks to build images on commit.
ACA environments support revision management.
AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring
Logs are collected in Azure Monitor.
Teams inspect container logs and Kubernetes events when troubleshooting.
Developers write KQL queries to analyze latency spikes.
Business requirements
Customer experience: Maintain a seamless, low-latency recommendation experience for end- users, even during unpredictable seasonal traffic spikes.
Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs.
Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction.
Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets.
Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers.
Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization.
Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates.
Identity: Use managed identities for all service-to-service and service-to-database authentication.
Plain-text credentials in configuration files are strictly prohibited.
Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy.
Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero.
CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
Hotspot Question
You need to deploy a batch retraining workload.
How should you complete the scaling configuration? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.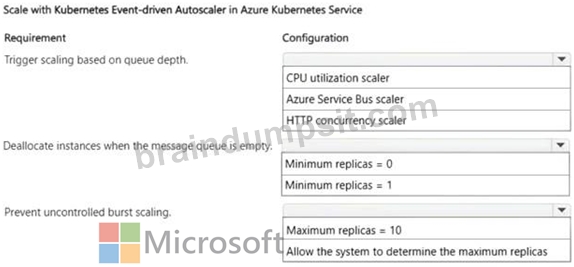
Answer:
Explanation: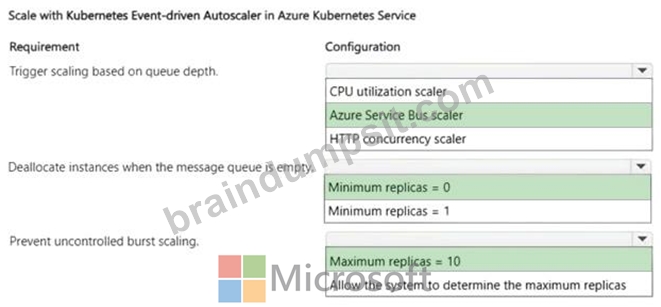
Explanation:
Box 1: Azure Service Bus scaler
An Azure Service Bus scaler needs to be set up to meet this requirement.
Queue-Depth Metrics: To trigger scaling based strictly on queue depth, the orchestration layer (such as Azure Container Apps or AKS using KEDA) requires a scaler that can natively communicate with the message broker and monitor metrics like active message count.
Scale-to-Zero Support: Unlike standard resource scalers, an Azure Service Bus scaler enables event-driven batch workloads to spin up consumers when messages arrive and scale all the way down to zero instances when the queue is completely empty.
Box 2: Minimum replicas = 0.
You need to set Minimum replicas = 0.
Setting the minimum replicas to 0 enables the system to scale down to zero instances when there are no messages left in the queue, completely deallocating resources and eliminating idle compute costs.
Box 3: Maximum replicas = 10
To prevent uncontrolled burst scaling during your batch retraining workloads, you need to set maximum replicas = 10.
Enforcing Upper Bounds: Allowing the system to determine the maximum replica gives the underlying autoscaler (such as KEDA or the Horizontal Pod Autoscaler in Azure Kubernetes Service) the freedom to scale out infinitely or up to large default platform limits. This directly risks uncontrolled burst scaling when a massive batch queue is processed.
Resource and Cost Protection: Hard-coding a ceiling (like maximum replicas = 10) ensures that the batch workload cannot consume more cluster resources than allocated, preventing resource starvation for customer-facing recommendation APIs and keeping operational costs predictable.
Reference:
https://azure.github.io/aca-dotnet-workshop/aca/09-aca-autoscale-keda/
https://kserve.github.io/website/docs/reference/crd-api
NEW QUESTION # 39
You are choosing an embedding strategy for a RAG solution. Documents range from 2 to 200 pages. You need to preserve semantic coherence while staying within embedding model token limits. What should you do?
Answer: B
Explanation:
Embedding models have token limits, and embedding an entire long document as one vector dilutes semantic meaning. Chunking into smaller, slightly overlapping segments preserves context at chunk boundaries and keeps each chunk within model limits while improving retrieval relevance.
NEW QUESTION # 40
A Python API retrieves a document from Azure Database for PostgreSQL by using a SQL statement. The API accepts the document ID from user input. The current implementation inserts the document ID directly into the SQL statement.
You need to secure the SQL statement execution by using a parameterized query. You must minimize the possibility of SQL injection.
How should you update the implementation to execute the SQL statement safely? To answer, move the appropriate configurations to the correct requirements. You may use each configuration once, more than once, or not at all. you may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.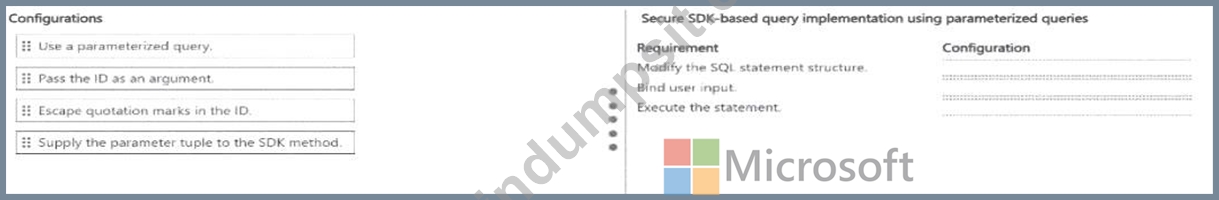
Answer:
Explanation: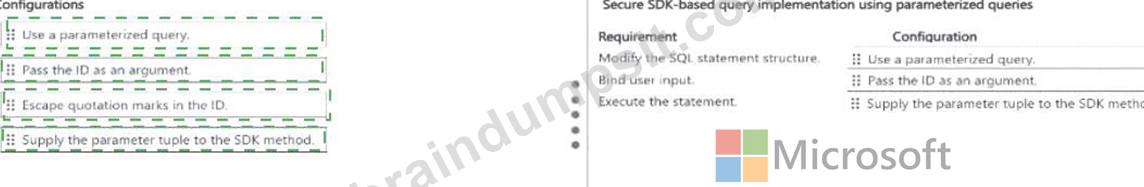
Explanation: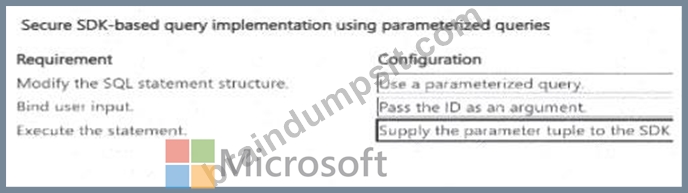
Verified Answer: Modify SQL: use a parameterized query. Bind input: pass the ID as an argument. Execute:
supply the parameter tuple to the SDK/driver method.
Detailed Explanation: The security boundary is created by separating SQL syntax from user-supplied values.
The statement should contain a parameter placeholder rather than concatenated input, and the document ID should be supplied separately through the database driver's parameter mechanism. The driver then performs the correct protocol-level binding and escaping. Manually escaping quotation marks is error-prone and does not provide the same injection resistance as true parameterization.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Vector similarity search with Azure PostgreSQL
NEW QUESTION # 41
You deploy multiple instances of a change feed processor to handle a high ingestion rate within Azure Cosmos DB for NoSQL.
Each processor instance must process a different subset of partitions.
You need to ensure the workload is load-balanced across all processor instances.
What should you configure?
Answer: D
Explanation:
The lease container is the Azure Cosmos DB component that coordinates change feed processing across multiple processor instances. Microsoft defines the lease container as the state store used by the change feed processor to track progress and coordinate ownership of partition ranges among workers. Each lease corresponds to a portion of the change feed workload, and at any given time a lease is owned by one processor instance.
When several change feed processor instances use the same lease container and the same processor name while maintaining unique instance names, the processor distributes leases across the active instances by using an equal-distribution algorithm. If instances are added or removed, the processor dynamically redistributes leases, which provides automatic workload balancing and parallelism. This is exactly what is required when ingestion volume is high and each instance must process a distinct subset of partition ranges.
Indexing precision affects query indexing behavior, not change feed coordination. Strong consistency controls read consistency semantics and does not assign partitions to processors. Autoscale throughput can increase database RU/s capacity, but it does not coordinate which processor instance owns which change feed partition range.
Study Guide references: Azure Cosmos DB for NoSQL # Change Feed Processor; lease container; parallel processing; dynamic scaling and load balancing.
NEW QUESTION # 42
You provisioned an Azure Cosmos DB for NoSQL account named account1 with the default consistency level.
You plan to configure the consistency level on a per request basis. You plan to request Consistent Prefix consistency on a per-request basis.
You need to identify the resulting consistency level for read and write operations.
Which levels result from this configuration? To answer, select the appropriate options in the answer a rea.
NOTE: Each correct selection is worth one point.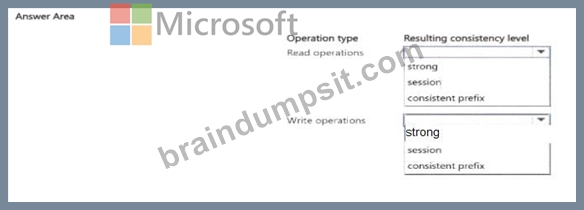
Answer:
Explanation: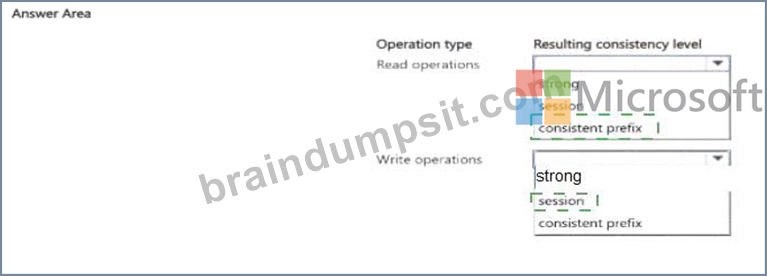
Explanation: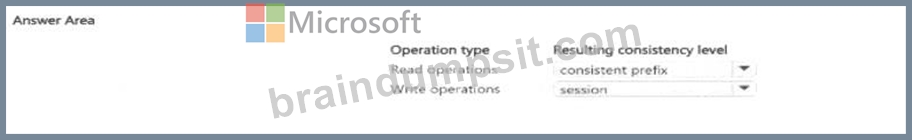
Verified Answer: Read operations: Consistent Prefix. Write operations: Session (the account default remains effective for writes).
Detailed Explanation: Azure Cosmos DB allows a client or request to override consistency for reads.
Microsoft explicitly notes that such an override applies only to reads; it does not change how writes are committed and replicated under the account's configured consistency. Because a new account uses Session consistency by default, requesting Consistent Prefix affects the reads while the account continues to use its Session consistency behavior for writes. This distinction is the key point tested by the hotspot.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Manage Cosmos DB consistency levels | Cosmos DB consistency level choices
NEW QUESTION # 43
......
Workers and students today all strive to be qualified to keep up with dynamically changing world with AI-200 exam. In doing so, they often need practice materials like our AI-200 exam materials to conquer exam or tests in their profession. Without amateur materials to waste away your precious time, all content of AI-200 practice materials are written for your exam based on the real exam specially. So our AI-200 study guide can be your best choice.
AI-200 Questions Exam: https://www.braindumpsit.com/AI-200_real-exam.html