ITDumpsKR Databricks-Generative-AI-Engineer-Associate 최신 PDF 버전 시험 문제집을 무료로 Google Drive에서 다운로드하세요: https://drive.google.com/open?id=1g40ZoroJgXlMh65faJY-ctH755KIs0g_
Databricks인증 Databricks-Generative-AI-Engineer-Associate시험패스는 IT업계종사자들이 승진 혹은 연봉협상 혹은 이직 등 보든 면에서 날개를 가해준것과 같습니다.IT업계는 Databricks인증 Databricks-Generative-AI-Engineer-Associate시험을 패스한 전문가를 필요로 하고 있습니다. ITDumpsKR의Databricks인증 Databricks-Generative-AI-Engineer-Associate덤프로 시험을 패스하고 자격증을 취득하여 더욱더 큰 무대로 진출해보세요.
| 주제 | 소개 |
|---|---|
| 주제 1 |
|
| 주제 2 |
|
| 주제 3 |
|
| 주제 4 |
|
| 주제 5 |
|
>> Databricks Databricks-Generative-AI-Engineer-Associate인기자격증 덤프문제 <<
성공으로 향하는 길에는 많은 방법과 방식이 있습니다. Databricks인증 Databricks-Generative-AI-Engineer-Associate시험을 패스하는 길에는ITDumpsKR의Databricks인증 Databricks-Generative-AI-Engineer-Associate덤프가 있습니다. ITDumpsKR의Databricks인증 Databricks-Generative-AI-Engineer-Associate덤프는 실제시험 출제방향에 초점을 두어 연구제작한 시험준비공부자료로서 높은 시험적중율과 시험패스율을 자랑합니다.국제적으로 승인해주는 IT자격증을 취득하시면 취직 혹은 승진이 쉬워집니다.
질문 # 16
A Generative Al Engineer interfaces with an LLM with prompt/response behavior that has been trained on customer calls inquiring about product availability. The LLM is designed to output "In Stock" if the product is available or only the term "Out of Stock" if not.
Which prompt will work to allow the engineer to respond to call classification labels correctly?
정답:A
설명:
* Problem Context: The Generative AI Engineer needs a prompt that will enable an LLM trained on customer call transcripts to classify and respond correctly regarding product availability. The desired response should clearly indicate whether a product is "In Stock" or "Out of Stock," and it should be formatted in a way that is structured and easy to parse programmatically, such as JSON.
* Explanation of Options:
* Option A: Respond with "In Stock" if the customer asks for a product. This prompt is too generic and does not specify how to handle the case when a product is not available, nor does it provide a structured output format.
* Option B: This option is correctly formatted and explicit. It instructs the LLM to respond based on the availability mentioned in the customer call transcript and to format the response in JSON.
This structure allows for easy integration into systems that may need to process this information automatically, such as customer service dashboards or databases.
* Option C: Respond with "Out of Stock" if the customer asks for a product. Like option A, this prompt is also insufficient as it only covers the scenario where a product is unavailable and does not provide a structured output.
* Option D: While this prompt correctly specifies how to respond based on product availability, it lacks the structured output format, making it less suitable for systems that require formatted data for further processing.
Given the requirements for clear, programmatically usable outputs,Option Bis the optimal choice because it provides precise instructions on how to respond and includes a JSON format example for structuring the output, which is ideal for automated systems or further data handling.
질문 # 17
A Generative AI Engineer is integrating Mosaic AI Vector Search into a Retrieval-Augmented Generation (RAG) system. The source data, comprising simple text entries, is stored in a Delta table. To simplify the workflow, the engineer plans to use an embedding model served via a Mosaic AI Model Serving endpoint to automatically compute embeddings during data synchronization from the Delta table to the vector search index.
Which method should the engineer use to achieve this integration?
정답:B
설명:
A Delta Sync index with managed embeddings supports the workflow described. The engineer identifies the source text column and configures the embedding model endpoint. Databricks computes embeddings as part of synchronization and maintains the corresponding searchable index. This removes the requirement to calculate vectors independently and write them into the source table before indexing. With self-managed embeddings, the application or upstream pipeline must already provide the embedding vectors. A Direct Vector Access index requires explicit updates through an API or SDK and does not automatically synchronize with the source Delta table. "Hybrid embedding computing" is not the relevant index configuration; hybrid search combines retrieval techniques. Managed embeddings and Delta synchronization therefore address both automatic vector generation and source-data integration. Databricks documentation
질문 # 18
A Generative AI Engineer I using the code below to test setting up a vector store: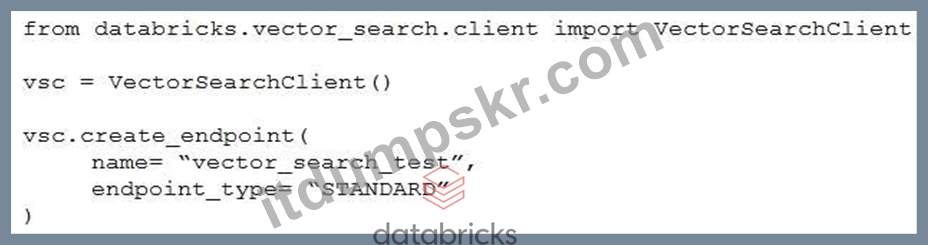
Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?
정답:A
설명:
Context: The Generative AI Engineer is setting up a vector store using Databricks' VectorSearchClient. This is typically done to enable fast and efficient retrieval of vectorized data for tasks like similarity searches.
Explanation of Options:
* Option A: vsc.get_index(): This function would be used to retrieve an existing index, not create one, so it would not be the logical next step immediately after creating an endpoint.
* Option B: vsc.create_delta_sync_index(): After setting up a vector store endpoint, creating an index is necessary to start populating and organizing the data. The create_delta_sync_index() function specifically creates an index that synchronizes with a Delta table, allowing automatic updates as the data changes. This is likely the most appropriate choice if the engineer plans to use dynamic data that is updated over time.
* Option C: vsc.create_direct_access_index(): This function would create an index that directly accesses the data without synchronization. While also a valid approach, it's less likely to be the next logical step if the default setup (typically accommodating changes) is intended.
* Option D: vsc.similarity_search(): This function would be used to perform searches on an existing index; however, an index needs to be created and populated with data before any search can be conducted.
Given the typical workflow in setting up a vector store, the next step after creating an endpoint is to establish an index, particularly one that synchronizes with ongoing data updates, henceOption B.
질문 # 19
When developing an LLM application, it's crucial to ensure that the data used for training the model complies with licensing requirements to avoid legal risks.
Which action is NOT appropriate to avoid legal risks?
정답:A
설명:
* Problem Context: When using data to train a model, it's essential to ensure compliance with licensing to avoid legal risks. Legal issues can arise from using data without permission, especially when it comes from third-party sources.
* Explanation of Options:
* Option A: Reaching out to data curatorsbeforeusing the data is an appropriate action. This allows you to ensure you have permission or understand the licensing terms before starting to use the data in your model.
* Option B: Usingoriginal datathat you personally created is always a safe option. Since you have full ownership over the data, there are no legal risks, as you control the licensing.
* Option C: Using data that is explicitly labeled with an open license and adhering to the license terms is a correct and recommended approach. This ensures compliance with legal requirements.
* Option D: Reaching out to the data curatorsafteryou have already started using the trained model isnot appropriate. If you've already used the data without understanding its licensing terms, you may have already violated the terms of use, which could lead to legal complications. It's essential to clarify the licensing termsbeforeusing the data, not after.
Thus,Option Dis not appropriate because it could expose you to legal risks by using the data without first obtaining the proper licensing permissions.
질문 # 20
A Generative AI Engineer has been reviewing issues with their company's LLM-based question-answering assistant and has determined that a technique called prompt chaining could help alleviate some performance concerns. However, to suggest this to their team, they have to clearly explain how it works and how it can benefit their question-answering assistant. Which explanation do they communicate to the team?
정답:A
설명:
Prompt chaining is a fundamental design pattern in LLM application development used to handle complexity. Instead of sending a single, massive, and highly complex prompt to an LLM-which often results in reasoning errors or hallucinations-chaining breaks the logic into a sequence of smaller, targeted steps. For example, a legal assistant might first chain a step to "identify the legal jurisdiction," followed by a step to "extract relevant statutes," and finally a step to "summarize the findings." This modularity improves reliability because each prompt has a narrower focus, making it easier for the model to follow instructions accurately. While it may actually increase latency (contradicting B) and cost (contradicting D) due to multiple API calls, the primary engineering benefit is the significant boost in the quality and robustness of the output. It also allows for intermediate validation and error handling between steps, which is impossible in a single-call architecture.
질문 # 21
......
ITDumpsKR는Databricks Databricks-Generative-AI-Engineer-Associate시험을 패스할 수 있는 아주 좋은 사이트입니다. ITDumpsKR은 아주 알맞게 최고의Databricks Databricks-Generative-AI-Engineer-Associate시험문제와 답 내용을 만들어 냅니다. 덤프는 기존의 시험문제와 답과 시험문제분석 등입니다. ITDumpsKR에서 제공하는Databricks Databricks-Generative-AI-Engineer-Associate시험자료의 문제와 답은 실제시험의 문제와 답과 아주 비슷합니다.
Databricks-Generative-AI-Engineer-Associate시험패스 인증덤프자료: https://www.itdumpskr.com/Databricks-Generative-AI-Engineer-Associate-exam.html
참고: ITDumpsKR에서 Google Drive로 공유하는 무료 2026 Databricks Databricks-Generative-AI-Engineer-Associate 시험 문제집이 있습니다: https://drive.google.com/open?id=1g40ZoroJgXlMh65faJY-ctH755KIs0g_