BTW, DOWNLOAD part of Prep4SureReview SPS-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1YmRNoU9Lq1FDIgE6NZzlKDUShDb8ekBg
In order to face to the real challenge, to provide you with more excellent SPS-C01 exam certification training materials, we try our best to update the renewal of SPS-C01 exam dumps from the change of Prep4SureReview IT elite team. All of this is just to help you pass SPS-C01 Certification Exam easily as soon as possible. Before purchase our SPS-C01 exam dumps, you can download SPS-C01 free demo and answers on probation.
| Section | Objectives |
|---|---|
| Topic 1: User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Topic 2: Snowpark Fundamentals | - Snowpark architecture and concepts
|
| Topic 3: Data Engineering with Snowpark | - Pipeline development
|
| Topic 4: Testing, Debugging, and Deployment | - Production readiness
|
| Topic 5: Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| Topic 6: DataFrame Operations and Data Processing | - Data transformation workflows
|
>> Latest SPS-C01 Exam Discount <<
Perhaps your ability cannot meet the requirement of a high salary job. So you cannot get the job because of lack of ability. You must really want to improve yourself. Now, our SPS-C01 exam questions can help you realize your dreams. Not only our SPS-C01 study braindumps can help you obtain the most helpful knowledge and skills to let you stand out by solving the probleme the others can't, but also our SPS-C01 praparation guide can help you get the certification for sure.
NEW QUESTION # 109
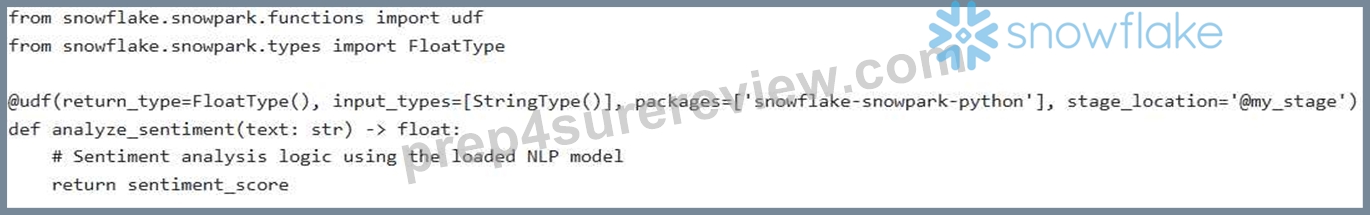
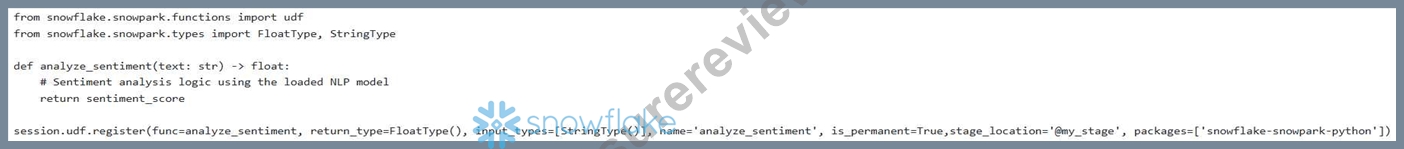
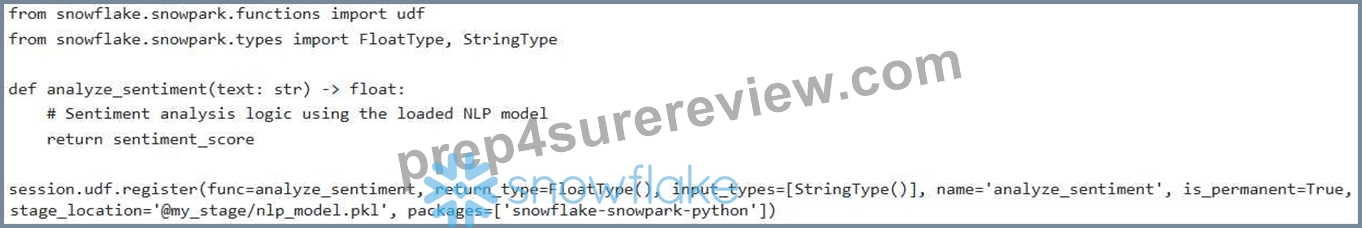
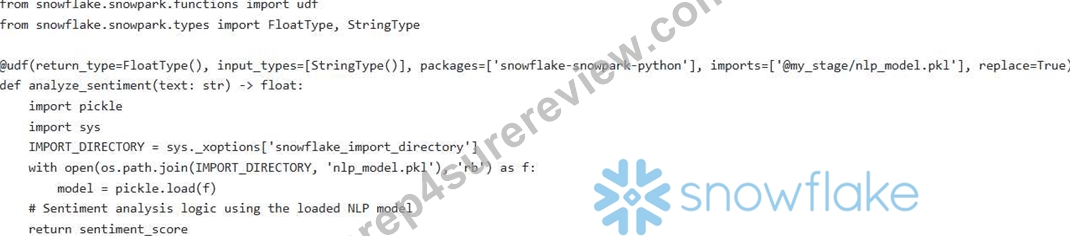
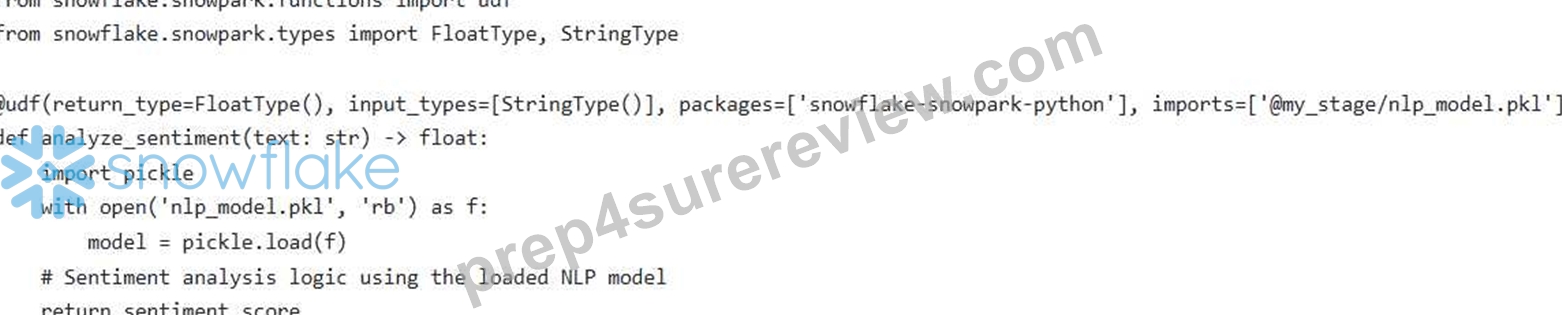
You are developing a Snowpark application to process customer sentiment from text reviews. You have a Python function, , that utilizes a pre-trained NLP model loaded from a file on a Snowflake stage named This function returns a sentiment score (float) between -1 and 1. You need to register this function as a UDF so that it can be used within Snowpark DataFrames. Which of the following code snippets correctly registers the UDF, ensuring the NLP model is available to the function during execution?
Answer: D
Explanation:
Option E correctly uses the '@udf decorator with the 'imports' parameter to specify the location of the pickled model on the stage. It also uses to correctly construct the path to the imported file within the UDF's execution environment. Replace=True prevents errors if the UDF already exists. Options A, C and D don't correctly handle importing the NLP model. Option B has a security issue of loading file without validating the Path.
NEW QUESTION # 110
You are developing a Snowpark application that performs complex data transformations on a large dataset using a UDF written in Scala.
After deploying the application, you observe that the performance is significantly slower than expected. Analyzing the query history in Snowflake, you identify that the UDF execution time is unusually high. Which of the following actions would be MOST effective in improving the performance of the UDF, considering Snowpark's execution context and Snowflake's query processing?
Answer: B,C
Explanation:
Using vectorized UDFs allows processing data in batches, significantly reducing overhead. Returning smaller datatypes optimizes I/O and memory usage. While increasing the warehouse size might offer some improvement, it doesn't directly address the UDF's inefficiency. Snowpark session memory is more relevant for the driver program and less so for the execution of the UDF within Snowflake's environment. SQL Stored procedures are useful but for functions already supported in SQL; vectorized UDFs provide a path fomard for scala code.
NEW QUESTION # 111
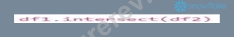
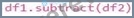
You have two Snowpark DataFrames, 'dfl' and 'df2, representing customer data'. 'dfl' contains columns 'CUSTOMER ID', 'NAME, and 'EMAIL', while 'df2 contains 'CUSTOMER ID' and 'PURCHASE AMOUNT'. You need to create a new DataFrame that combines the information from both DataFrames but only includes customers who exist in BOTH 'dfl ' and 'df2 and the resulting DataFrame should have columns from both. Which of the following Snowpark DataFrame operations should you use, and what is the correct way to call it?


Answer: B,E
Explanation:
To include only customers present in BOTH DataFrames and include columns from both, you need to perform an INNER JOIN. Options B, C and D are incorrect: intersect, union and subtract operations work at a row level. Also, intersect , union and subtract operations expects the number of columns and datatypes to match and is not relevant to the described scenario. Option A and E are valid way to use the join operation: (A) uses the explicit condition 'dfl .CUSTOMER_ID df2.CUSTOMER_lD while (E) is the short form which specifies the column name directly. Both achieves the same inner join behavior. You can choose E as a cleaner option when only joining on column name.
NEW QUESTION # 112
A Snowpark application needs to process large volumes of sensor data stored in a Snowflake table named , which includes columns , 'timestamp' , and The application must calculate a rolling average of for each over a 5-minute window. The data is not perfectly ordered by 'timestamp' within each 'sensor_id'. What is the MOST efficient and accurate way to implement this rolling average calculation using Snowpark?
Answer: C
Explanation:
Option D is the most efficient and accurate. 'partitionBy('sensor_id')' ensures that the rolling average is calculated separately for each sensor. 'orderBy('timestamp'Y orders the data within each partition by timestamp. 0)' defines the 5- minute window relative to the current row, accurately capturing all readings within that window even if they are slightly out of order. 'avg(Y then efficiently calculates the average within that window. Other options are either less efficient (e.g., UDTF iteration) or less accurate (e.g., incorrect window definitions, filtering).
NEW QUESTION # 113
You have two Snowpark DataFrames: 'employees_df with columns 'employee_id' (INTEGER), 'employee_name' (STRING), 'department_id' (INTEGER), and 'salaries_df' with columns 'employee_id' (INTEGER), "salary' (FLOAT), 'effective_date' (DATE). You need to create a new DataFrame that contains the employee's name, department, and the highest salary they have ever received. Assuming there can be multiple salary entries for the same employee with different 'effective date' values, which of the following Snowpark code snippets would correctly and efficiently solve this problem?
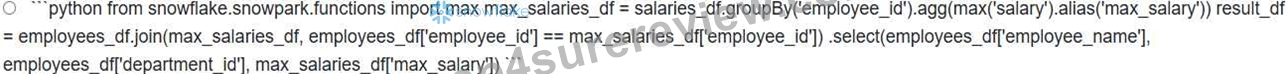

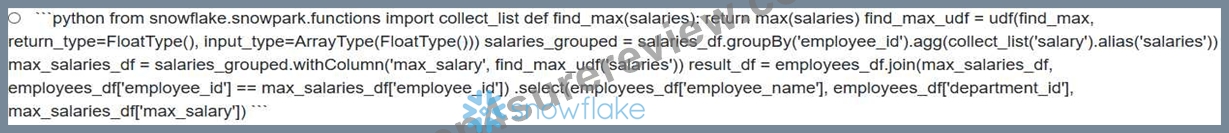


Answer: A
Explanation:
Option B is the most efficient solution. It first calculates the maximum salary for each employee in the DataFrame using 'groupBy' and 'max' , then joins this aggregated result with the 'employees_df to retrieve the employee's name and department. This approach avoids unnecessary data shuffling and minimizes the amount of data processed in the join. Option A performs the join before the aggregation, which can be less efficient. Options C and E use window functions, which are more complex and may not be as efficient for this simple aggregation. Option D uses a UDF and 'collect_list' , which can be very inefficient due to data transfer and UDF overhead.
NEW QUESTION # 114
......
Being anxious for the exam ahead of you? Have a look of our SPS-C01 training engine please. Presiding over the line of our SPS-C01 practice materials over ten years, our experts are proficient as elites who made our SPS-C01 learning questions, and it is their job to officiate the routines of offering help for you. And i can say no people can know the SPS-C01 exam braindumps better than them since they are the most professional.
SPS-C01 Pdf Braindumps: https://www.prep4surereview.com/SPS-C01-latest-braindumps.html
P.S. Free 2026 Snowflake SPS-C01 dumps are available on Google Drive shared by Prep4SureReview: https://drive.google.com/open?id=1YmRNoU9Lq1FDIgE6NZzlKDUShDb8ekBg