P.S. Free 2026 Snowflake SPS-C01 dumps are available on Google Drive shared by DumpStillValid: https://drive.google.com/open?id=1bm7BghmHWrZxgEGHfxD2QBSJA2moxyPl
The software version of the SPS-C01 study materials is very practical. This version has helped a lot of customers pass their exam successfully in a short time. The most important function of the software version is to help all customers simulate the real examination environment. If you choose the software version of the SPS-C01 Study Materials from our company as your study tool, you can have the right to feel the real examination environment. In addition, the software version is not limited to the number of the computer.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Transformations and Operations | 35% | - User-defined logic
|
| Topic 2: Performance and Best Practices | 10% | - Optimization techniques
|
| Topic 3: Snowpark Concepts and Architecture | 25% | - Session management and connection
|
| Topic 4: Snowpark API and Development | 30% | - Multi-language support
|
DumpStillValid delivers up to date SPS-C01 exam products and modify them time to time. Latest SPS-C01 exam questions are assembled in our practice test modernizes your way of learning and replaces the burdensome preparation techniques with flexible learning. We accord you an actual exam environment simulated through our practice test sessions that proves beneficial for SPS-C01 Exams preparation. Our SPS-C01 practice tests provide you knowledge and confidence simultaneously. Candidates who run across the extensive search, DumpStillValid products are the remedy for their worries. Once you have chosen for our SPS-C01 practice test products, no more resources are required for exam preparation.
NEW QUESTION # 128
You have a Snowpark DataFrame with columns 'order_id', 'product_id', 'sale_date' (DATE), and 'sale_amount'. You need to perform the following transformations: 1. Filter out sales records before January 1, 2023.2. Group the data by 'product_id' and calculate the total 'sale_amount' for each product. 3. Create a new column 'average_sale_amount' by dividing the total 'sale_amount' by the number of distinct 'order_id' for each product. You must alias the aggregate function. Which of the following Snowpark code snippets correctly implements these transformations?

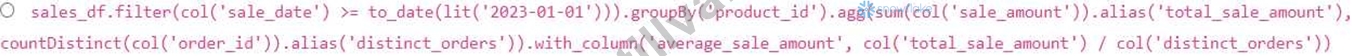



Answer: B
Explanation:
Option E is the most appropriate and correct. It uses for explicit date conversion, ensures correct filtering, aggregates with aliases, and calculates the 'average_sale_amount' correctly using the aliased columns. Options A, B, C and D are all valid for Snowflake. Option B incorrectly passes the date string. 'as_' instead of 'alias' are not valid and will cause an issue.
NEW QUESTION # 129
You are developing a Snowpark Python application that processes streaming data using a dynamic table. The application is experiencing frequent 'net.snowflake.client.jdbc.SnowflakeSQLException: SQL compilation error: Unsupported feature 'Streaming Dynamic Table'. ' errors, even though dynamic tables are enabled in your Snowflake account and the user has the necessary privileges. Which of the following are potential causes and solutions for this error? (Select TWO)
Answer: D,E
Explanation:
Options A and C are correct. Streaming Dynamic Tables require specific warehouse configuration and Snowpark client version. Option A: The 'STREAMING DYNAMIC TABLES' parameter must be enabled on the warehouse. Option C: An outdated Snowpark client might not support the streaming dynamic table feature. Option B might cause a different SQL compilation error related to syntax, but not the specific 'Unsupported feature' error. Option D is related to managed tasks, not dynamic tables directly. Option E would affect performance and potential data staleness, but not the 'Unsupported feature' error. Therefore, the correct answers are A and C.
NEW QUESTION # 130
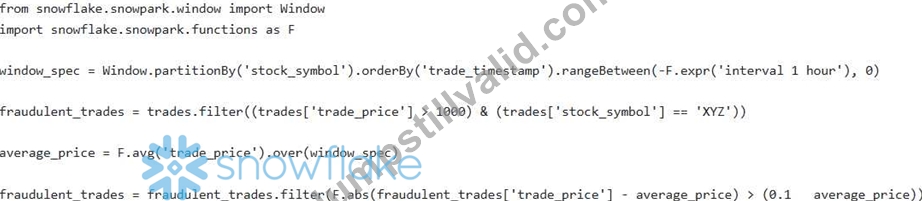
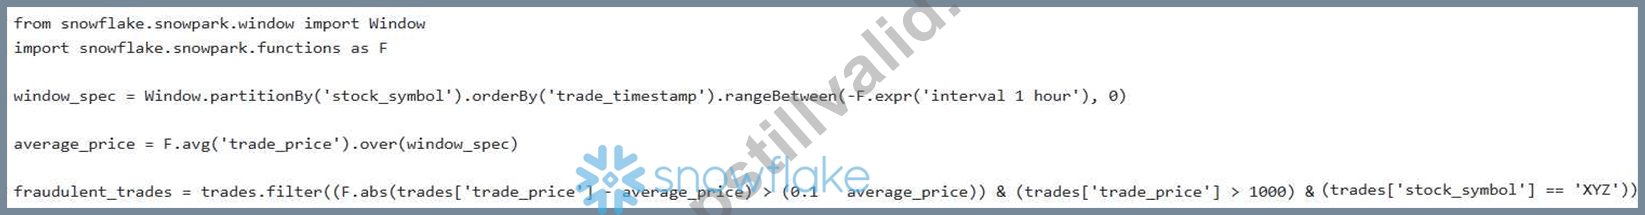
A financial firm is using Snowpark Python to analyze stock trading data'. They have a DataFrame named 'trades' with columns 'trade_id', 'stock_symbol', 'trade_price', and 'trade_timestamp'. They want to identify potentially fraudulent trades based on the following criteria: 1. Trades where the 'trade_price' deviates significantly from the average price of that 'stock_symbol' over the past hour. 2. Trades originating from user accounts where the price is above $1000.3. Trades which has stock symbol 'XYZ'. The firm wants to apply multiple filters to the DataFrame to extract only the fraudulent trades and needs an efficient and concise approach using Snowpark. Which of the following code snippets, using 'trade_price' > 1000 as user identifier, MOST accurately and efficiently implements this filtering logic? Assume that a Snowflake user has a maximum amount they can spend on a trade, and therefore, the user ID is associated with 'trade_price'.
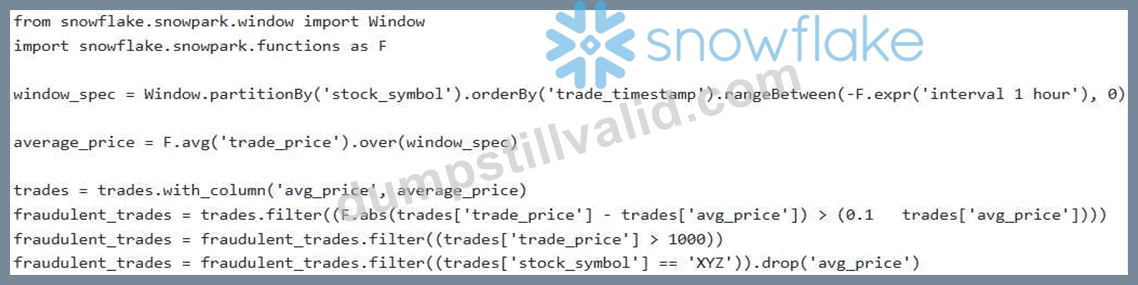
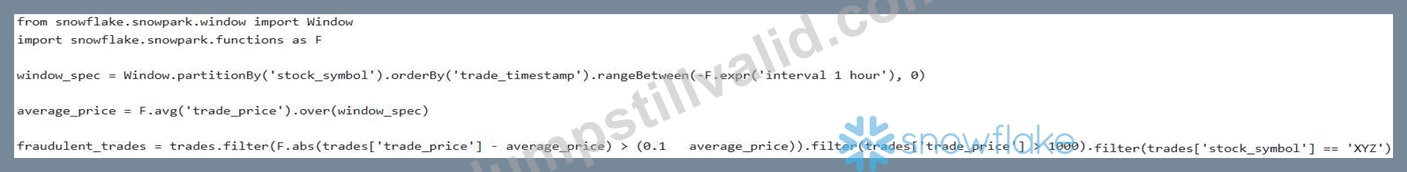
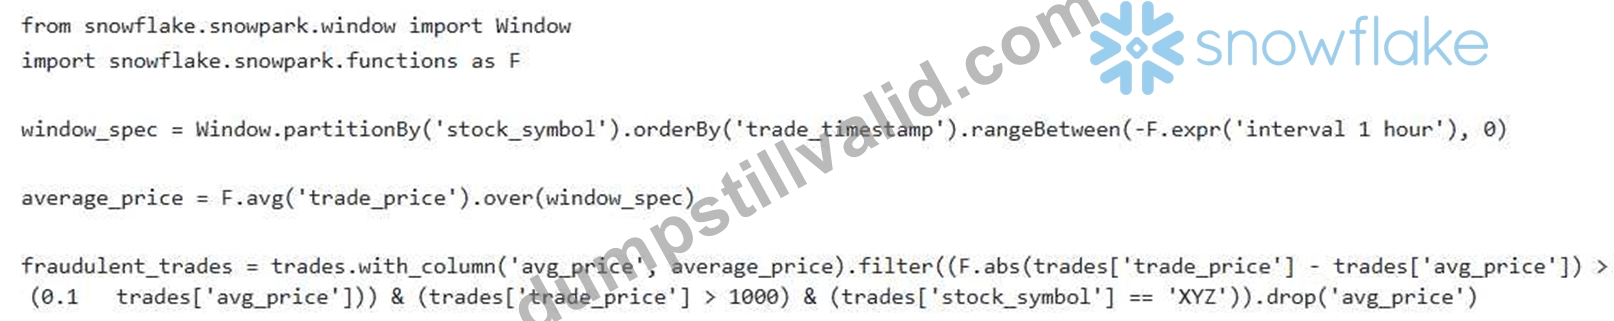
Answer: C
Explanation:
The most efficient and accurate solution is Option B. Here's why: Efficiency: It calculates the average price within the window using and the 'over' clause only once, storing this in a new column called 'avg_price' . The initial calculation uses a window function and does not take place until the query is executed. Accuracy: After adding the new 'avg_price' column, it can filter on multiple conditions. All conditions are evaluated at once. This is efficient as it combines all three conditions for filtering into one filter expression which reduces the number of passes made on the data. After using the 'avg_price' column in the filter step, it immediately drops this column to avoid polluting the 'fraudulent_trades' result. Correctness: After adding the new 'avg_price' column, it can filter on multiple conditions using window functions. Also, the price and the stock symbol are also part of the same filter criteria, ensuring the data is filtered as desired. Other Options: Option A : Does not reuse the calculated average price which decreases readability. Option C : Applies filters one after another. Each filter call will perform a full pass on the data, which is inefficient. Also needs to store the new average price in a new column, which will pollute the resulting dataframe. So, it is worse than Option B. Option D : Applies filters one after another and does not reuse the average price, and the filter steps require window function to be evaluated on separate filter operation. It is less efficient than Option B. Option E : Averages price on previously filtered data, which is not according to the requirements.
NEW QUESTION # 131
You are tasked with creating a Snowpark DataFrame from a complex JSON structure stored in a VARIANT column named 'payload' within a table called 'events'. The 'payload' contains nested objects and arrays, and you need to extract specific fields into separate columns of the DataFrame. You need to extract the 'event_id' (INT) from the top level of the JSON, the 'user _ id' (INT) from the 'user' object nested within the 'payload' , and the first element of the 'tags' array (VARCHAR) also nested within the 'payload'. Which of the following code snippets correctly defines the schema using 'StructType' and 'StructField' and applies it during DataFrame creation assuming events table contains multiple rows?





Answer: A
Explanation:
Option B extracts the necessary data and creates schema separately. Option A cannot chain the schema to after select operatiom Option C defines payload as VariantType, which is already there. option D has with_schema function which does not exist in current snowflake version. Option E tries to apply schema before select statement which is logically wrong.
NEW QUESTION # 132
You have written a Snowpark Python function that utilizes a UDF to perform complex string manipulation on a DataFrame containing customer reviews. When deploying this function using '@sproc.test_utils.mock_snowflake environment, the test fails with a 'ModuleNotFoundError' indicating that a custom Python library (e.g., is not available. You have already confirmed that the library is installed in your local development environment. What is the MOST reliable way to ensure the UDF has access to this dependency during local testing?
Answer: C
Explanation:
Option C is the most reliable solution for local testing with . The function explicitly makes the library available to the Snowpark session during execution, simulating how dependencies are handled in the Snowflake environment. Option A might work locally, but it's not a reliable deployment strategy. Option B is a temporary workaround and not a structured solution. Option D makes the library globally available, defeating the purpose of isolating dependencies for testing. Option E is a valid approach but less explicit and may affect other Python environments on the system. Using 'add_import' ensures that the correct version and dependencies are included in the deployment package.
NEW QUESTION # 133
......
The contents of SPS-C01 study materials are all compiled by industry experts based on the SPS-C01 examination outlines and industry development trends over the years. It does not overlap with the content of the SPS-C01 question banks on the market, and avoids the fatigue caused by repeated exercises. Our SPS-C01 Exam Guide is not simply a patchwork of exam questions, but has its own system and levels of hierarchy, which can make users improve effectively.
SPS-C01 Free Sample Questions: https://www.dumpstillvalid.com/SPS-C01-prep4sure-review.html
BONUS!!! Download part of DumpStillValid SPS-C01 dumps for free: https://drive.google.com/open?id=1bm7BghmHWrZxgEGHfxD2QBSJA2moxyPl