As a key to the success of your life, the benefits that our Certified-Data-Engineer-Professional study braindumps can bring you are not measured by money. Certified-Data-Engineer-Professional exam questions can not only help you pass the exam, but also help you master a new set of learning methods and teach you how to study efficiently, our Certified-Data-Engineer-Professional Study Materials will lead you to success. And Certified-Data-Engineer-Professional study materials provide free trial service for consumers. Come and have a try!
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: CI/CD, Testing, and Deployment | ~6% | - Implement testing and deployment pipelines - Deploy with Declarative Automation Bundles, CLI, and REST API |
| Topic 2: Developing Code for Data Processing using Python and SQL | ~22% | - Implement scalable Python/SQL code and project structures - Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader - Manage dependencies, libraries, and UDFs |
| Topic 3: Data Modeling | ~10% | - Design scalable Delta Lake schemas and clustering - Apply dimensional modeling techniques |
| Topic 4: Cost and Performance Optimization | ~13% | - Leverage system tables and observability tools - Optimize queries, clusters, and storage |
| Topic 5: Monitoring, Logging, and Troubleshooting | ~8% | - Use Spark UI, Query Profiler, and system tables - Diagnose common pipeline and job failures |
| Topic 6: Streaming Workloads and Change Data Capture | ~11% | - Implement reliable streaming pipelines - Apply AUTO CDC APIs and exactly-once semantics |
| Topic 7: Security and Governance | ~10% | - Implement row-level security, column masking, and compliance - Manage Unity Catalog permissions and ACLs |
| Topic 8: Data Transformation, Cleansing, and Quality | ~12% | - Enforce data quality and quarantine bad data - Apply advanced Spark transformations |
| Topic 9: Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation |
>> Free Certified-Data-Engineer-Professional Dumps <<
If you want to get a desirable opposition and then achieve your career dream, you are a right place now. Our Certified-Data-Engineer-Professional study tool can help you pass the exam. So, don't be hesitate, choose the Certified-Data-Engineer-Professional test torrent and believe in us. Let's strive to our dreams together. Life is short for us, so we all should cherish our life. Our Certified-Data-Engineer-Professional Guide Torrent can help you to save your valuable time and let you have enough time to do other things you want to do. Just buy our Certified-Data-Engineer-Professional exam questions, then you will pass the Certified-Data-Engineer-Professional exam easily.
NEW QUESTION # 120
A new data engineer notices that a critical field was omitted from an application that writes its Kafka source to Delta Lake. This happened even though the critical field was in the Kafka source.
That field was further missing from data written to dependent, long-term storage. The retention threshold on the Kafka service is seven days. The pipeline has been in production for three months.
Which describes how Delta Lake can help to avoid data loss of this nature in the future?
Answer: A
Explanation:
This is the correct answer because it describes how Delta Lake can help to avoid data loss of this nature in the future. By ingesting all raw data and metadata from Kafka to a bronze Delta table, Delta Lake creates a permanent, replayable history of the data state that can be used for recovery or reprocessing in case of errors or omissions in downstream applications or pipelines.
Delta Lake also supports schema evolution, which allows adding new columns to existing tables without affecting existing queries or pipelines. Therefore, if a critical field was omitted from an application that writes its Kafka source to Delta Lake, it can be easily added later and the data can be reprocessed from the bronze table without losing any information.
NEW QUESTION # 121
A company has a task management system that tracks the most recent status of tasks. The system takes task events as input and processes events in near real-time using Lakeflow Declarative Pipelines. A new task event is ingested into the system when a task is created or the task status is changed. Lakeflow Declarative Pipelines provides a streaming table (tasks_status) for BI users to query.
The table represents the latest status of all tasks and includes 5 columns:
task_id (unique for each task)
task_name
task_owner
task_status
task_event_time
The table enables three properties: deletion vectors, row tracking, and change data feed (CDF).
A data engineer is asked to create a new Lakeflow Declarative Pipeline to enrich the tasks_status table in near real-time by adding one additional column representing task_owner's department, which can be looked up from a static dimension table (employee).
How should this enrichment be implemented?
Answer: D
Explanation:
Change Data Feed (CDF) allows downstream consumers to read incremental changes (inserts, updates, deletes) from a Delta table. The documentation explains that when streaming from a Delta table with CDF enabled, developers can use readStream().option("readChangeFeed","true") to capture incremental events. For maintaining a derived table with enrichment logic, the recommended practice is to use apply_changes(), which applies CDC semantics (insert/update/delete) correctly to the target streaming table. By joining with the static employee dimension, enriched rows are generated before being merged into the new streaming target. This ensures correctness, scalability, and minimal latency. Batch reads or skipping commits do not maintain correctness for CDC pipelines.
NEW QUESTION # 122
Which approach demonstrates a modular and testable way to use DataFrame transform for ETL code in PySpark?
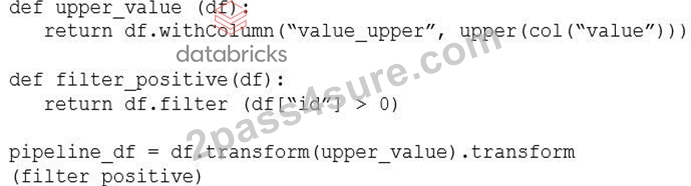
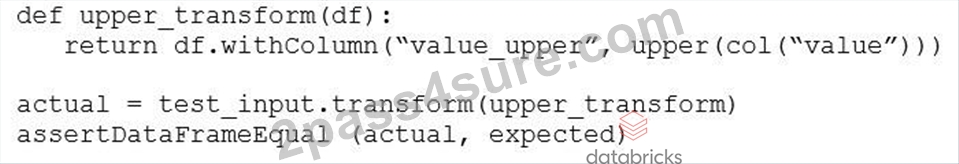
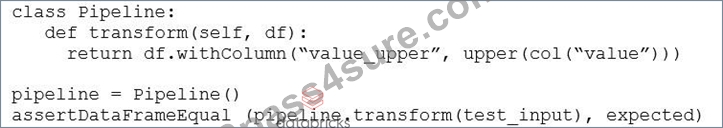
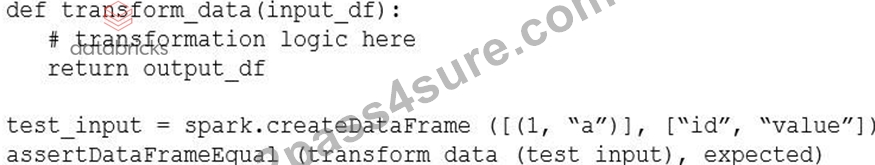
Answer: B
Explanation:
Using DataFrame.transform with a pure transformation function promotes modular, reusable, and easily testable ETL logic. Each transformation is encapsulated as a standalone function, can be independently unit tested, and composed cleanly in a pipeline without coupling to orchestration or class state.
NEW QUESTION # 123
An analytics team wants to run a short-term experiment in Databricks SQL on the customer transactions Delta table (about 20 billion records) created by the data engineering team. Which strategy should the data engineering team use to ensure minimal downtime and no impact on the ongoing ETL processes?
Answer: C
Explanation:
A shallow clone of the production Delta table creates an instantaneous snapshot that references the same data files, so it introduces virtually no downtime or storage overhead and avoids interfering with the ongoing ETL. A deep clone would copy all data (very expensive and slow for
20B rows). CTAS rewrites data and is unnecessary; direct access to prod risks contention and accidental changes.
NEW QUESTION # 124
An upstream system is emitting change data capture (CDC) logs that are being written to a cloud object storage directory. Each record in the log indicates the change type (insert, update, or delete) and the values for each field after the change. The source table has a primary key identified by the field pk_id.
For auditing purposes, the data governance team wishes to maintain a full record of all values that have ever been valid in the source system. For analytical purposes, only the most recent value for each record needs to be recorded. The Databricks job to ingest these records occurs once per hour, but each individual record may have changed multiple times over the course of an hour.
Which solution meets these requirements?
Answer: A
Explanation:
CDF captures changes only from a Delta table and is only forward-looking once enabled. The CDC logs are writing to object storage. So you would need to ingestion those and merge into downstream tables.
NEW QUESTION # 125
......
It is really a tough work to getting Certified-Data-Engineer-Professional certification in their spare time because preparing actual exam dumps needs plenty time and energy. As the one of certification exam dumps provider, 2Pass4sure enjoys a high popularity for its profession of Certified-Data-Engineer-Professional Exam Dumps and training materials. You will get high passing score in test with the help of our Certified-Data-Engineer-Professional braindumps torrent.
Exam Discount Certified-Data-Engineer-Professional Voucher: https://www.2pass4sure.com/Databricks-Certification/Certified-Data-Engineer-Professional-actual-exam-braindumps.html