For candidates who will attend the exam, some practice is quite necessary. Our SPS-C01 training materials contain both questions and answers, and you can have a quickly check after practicing. SPS-C01 training materials cover most knowledge points for the exam, and you can have a good command of the exam if you choose us. Besides, in the process of ing, you professional ability will also be improved. We offer you free update for 365 days if you buying SPS-C01 Exam Dumps from us. And the latest version will be sent to your email automatically.
| Section | Objectives |
|---|---|
| Topic 1: DataFrame Operations and Data Processing | - Data transformation workflows
|
| Topic 2: Snowpark Fundamentals | - Snowpark architecture and concepts
|
| Topic 3: Testing, Debugging, and Deployment | - Production readiness
|
| Topic 4: User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Topic 5: Data Engineering with Snowpark | - Pipeline development
|
| Topic 6: Performance Optimization and Best Practices | - Efficient Snowpark execution
|
To advance your career, take the Snowflake Certified SnowPro Specialty - Snowpark exam. Your Snowflake Certified SnowPro Specialty - Snowpark demonstrates your commitment to lifelong learning. Passing the Snowflake Certified SnowPro Specialty - Snowpark exam in one sitting is not a walk in the park. The Snowflake SPS-C01 exam preparation process takes a lot of time and effort. You have to put time and money into passing the Snowflake Certified SnowPro Specialty - Snowpark exam. The best method to reap the rewards of your investment in becoming an Snowflake Horizon & Snowflake is by using Snowflake SPS-C01 Exam Questions. Additionally, you can confidently study for the SPS-C01 exam.
NEW QUESTION # 121
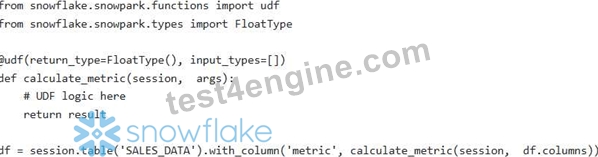
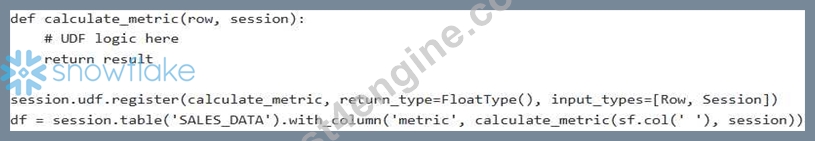
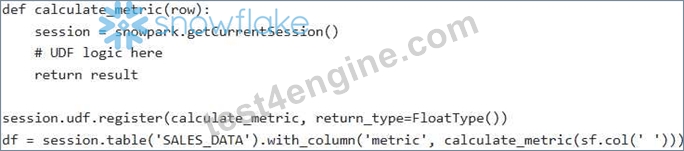
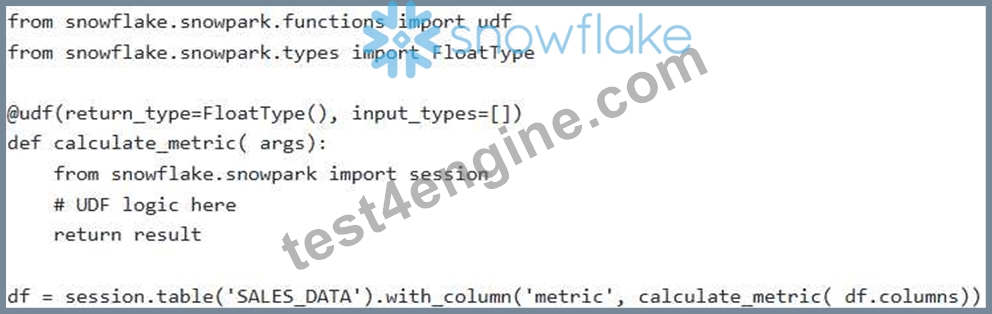
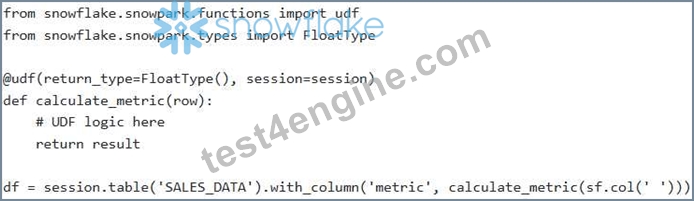
You are using Snowpark Python to create a DataFrame from an existing Snowflake table "SALES DATA'. You want to apply a user- defined function (UDF) to each row of the DataFrame to calculate a custom sales metric. The UDF requires access to the 'session' object. Which of the following approaches is correct for defining and applying the UDF in Snowpark?
Answer: D
Explanation:
Option E is the correct approach. To access the session object from within the UDF, you can import it when registering the UDF with the session. It should be imported inside the function and use the decorator. The input_types parameter should be set to 0, since this allows for session access.
NEW QUESTION # 122
You have a Snowpark Python application that reads data from a Snowflake table named 'SALES DATA', performs several transformations using DataFrames, and then writes the results back to a new table named 'AGGREGATED SALES'. The application runs successfully, but you notice that the write operation to 'AGGREGATED SALES' is consistently slow. After examining the query profile, you observe significant skew in the data being written, causing some worker nodes to be overloaded. Which of the following techniques could you use within your Snowpark application to mitigate the data skew and improve the write performance to 'AGGREGATED SALES'?
Answer: A,B
Explanation:
Both options B and D address data skew directly. Option B, , attempts to redistribute data evenly, which can alleviate skew if the repartitioning strategy is effective (e.g., using a hash function). Option D, using a UDF and 'repartitionByRange' , allows for more sophisticated custom partitioning based on the skew key, potentially achieving a more balanced distribution. Increasing warehouse size (A) might provide more resources, but it doesn't directly address the skew. Sorting (C) can exacerbate skew by concentrating similar values on single nodes. Clustering (E) improves read performance after the data is written, but does not improve the write performance itself. Therefore, B and D are the best choices to reduce skew during the write operation.
NEW QUESTION # 123
You have a Snowflake stage containing image files. You need to write a Snowpark Python application that extracts metadata (e.g., image resolution, format) from these images and stores the metadata in a Snowflake table. You want to leverage a Python library, such as Pillow (PIL), for image processing. Which of the following steps are necessary to correctly and efficiently implement this?
Answer: B
Explanation:
Option B is the MOST correct. Using a Conda environment specification file ('environment.yml') and 'session.add_packages' is the recommended way to manage dependencies in Snowpark. It ensures that the correct version of Pillow is available and simplifies the deployment process. Option A is an older method and may not be as reliable. Option C involves UDFs which, while valid, can be less efficient than using native Snowpark functionalities directly. Option D is incorrect, Snowflake doesn't have built-in image processing functions. Option E again defeats the purpose of server-side processing.
NEW QUESTION # 124
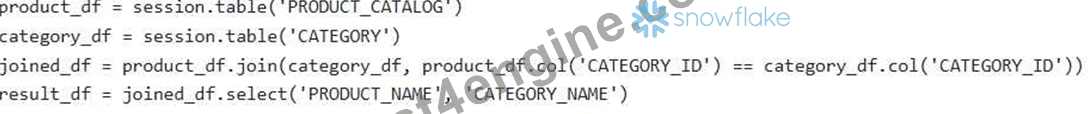
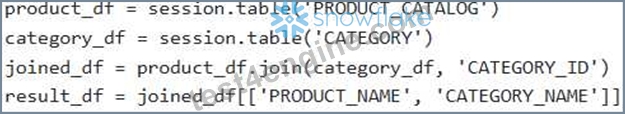
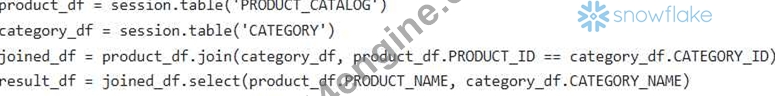
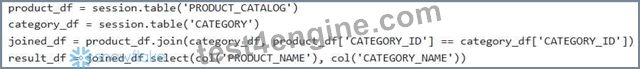
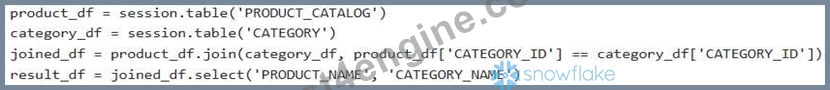
You have a Snowflake table 'PRODUCT CATALOG' with columns 'PRODUCT ID, 'PRODUCT NAME, and 'CATEGORY ID. You also have a table 'CATEGORY' with 'CATEGORY ID' and 'CATEGORY NAME. You need to create a Snowpark DataFrame that joins these two tables and includes only 'PRODUCT NAME and 'CATEGORY NAME. Assume a Snowpark Session object named 'session' is available. Which code snippet demonstrates creating the DataFrame using Snowpark's join functionality and column selection while using the 'table' method?
Answer: D
Explanation:
Option D correctly joins the tables using the 'join' method with a column expression specifying the join condition. It also correctly selects only the desired columns using and option A incorrectly uses 'PRODUCT_ID instead of for the join and needs 'col()' to reference columns. option B selects 'PRODUCT_NAME', 'CATEGORY_NAME' without using 'col(Y which will cause an error since the join brings duplicate column names from product_df and category_df. Option C uses Pythonic '[['PRODUCT_NAME', 'CATEGORY_NAME'I]' which only works on Pandas dataframes. option E attempts to use col() to reference the columns in the join condition which is incorrect as it is a column expression needs to use fully qualified table name for the same named column in two dataframes; moreover selection is missing col().
NEW QUESTION # 125
You have two Snowflake tables, 'customers' and 'orders'. The 'customers' table contains customer information, including a 'customer id' and 'region'. The 'orders' table contains order information, including 'order id', 'customer id', and 'order amount'. You need to create a Snowpark DataFrame that joins these two tables on 'customer id' and calculates the total order amount per region. However, some customers may not have any orders, and you want to include all customers in the result, with a total order amount of 0 for those without orders. Which of the following Snowpark code snippets will achieve this goal MOST efficiently, assuming 'customers_df and 'orders_ff are pre-existing Snowpark DataFrames representing the respective tables?





Answer: D
Explanation:
Option B is the most efficient because it uses 'coalesce' directly within the 'agg' function, avoiding a separate .na.fill' operation which could be less optimized in Snowpark. It handles the null values resulting from the left outer join correctly, ensuring that customers without orders have a 0 total order amount. Options A and C might work in some contexts, but are less idiomatic and potentially less efficient. Options D and E are less concise and may not be the most optimal way to express the desired logic in Snowpark.
NEW QUESTION # 126
......
It is convenient for our consumers to check Snowflake SPS-C01 exam questions free of charge before purchasing the Snowflake Certified SnowPro Specialty - Snowpark SPS-C01 practice exam. To make the Snowflake SPS-C01 exam questions content up-to-date for free of cost up to 365 days after buying them, our certified trainers work strenuously to formulate the exam questions in compliance with the Snowflake Certified SnowPro Specialty - Snowpark SPS-C01 Dumps.
Valid Test SPS-C01 Tutorial: https://www.test4engine.com/SPS-C01_exam-latest-braindumps.html