2026年ShikenPASSの最新CKA PDFダンプおよびCKA試験エンジンの無料共有:https://drive.google.com/open?id=1aF3uTOQyv-GvnTKRaV2IUeYKL78KGAv5
CKA認定資格を取得できれば、その地域で仕事をうまくこなせるので、簡単かつ迅速に昇進できます。最新のCKAクイズトレントは、Linux Foundationあなたのキャリアの成功に直接導くことができます。当社の資料は、実際の運用試験の雰囲気をシミュレートし、試験をシミュレートできます。ダウンロードとインストールでは、コンピューターとCKAテスト準備を使用するユーザーの量に制限はありません。 CKA試験トレントを習得するのに最適な学習方法を選択できるため、最高のサービスを提供します。私たちを信じて、CKA試験問題を購入してください。
| Section | Weight | Objectives |
|---|---|---|
| Troubleshooting | 30% | - Control plane component failures - Network connectivity and DNS resolution problems - Worker node issues and recovery - Cluster component health checks - Pod and application failures - Log collection and analysis |
| Workloads & Scheduling | 15% | - Resource requests, limits and autoscaling - Pod lifecycle, init containers, probes - Configure applications with ConfigMaps and Secrets - Pod scheduling: node selector, affinity, taints/tolerations - Deployments, rolling updates and rollbacks |
| Cluster Architecture, Installation & Configuration | 25% | - Understand CNI, CSI, CRI interfaces - Implement high availability control plane - Work with CRDs and Operators - Manage RBAC - Create and manage clusters with kubeadm - Install components via Helm / Kustomize - Manage cluster lifecycle and upgrades - Prepare infrastructure for cluster installation |
| Services & Networking | 20% | - CNI configuration and troubleshooting - Service types: ClusterIP, NodePort, LoadBalancer, ExternalName - CoreDNS and service discovery - Ingress resources and controllers - Network policies |
| Storage | 10% | - StatefulSet storage configuration - StorageClasses and dynamic provisioning - Persistent Volumes (PV) and Persistent Volume Claims (PVC) - Volume types and access modes |
ShikenPASSはLinux FoundationのCKA試験の最新の問題集を提供するの専門的なサイトです。Linux FoundationのCKA問題集はCKAに関する問題をほとんど含まれます。私たちのLinux FoundationのCKA問題集を使うのは君のベストな選択です。ShikenPASSは君の試験を最も早い時間で合格できる。学習教材がどんな問題があっても、あるいは君の試験を失敗したら、私たちは全額返金するのを保証いたします。
質問 # 59
Score: 4%
Task
Set the node named ek8s-node-1 as unavailable and reschedule all the pods running on it.
正解:
解説:
SOLUTION:
[student@node-1] > ssh ek8s
kubectl cordon ek8s-node-1
kubectl drain ek8s-node-1 --delete-local-data --ignore-daemonsets --force
質問 # 60
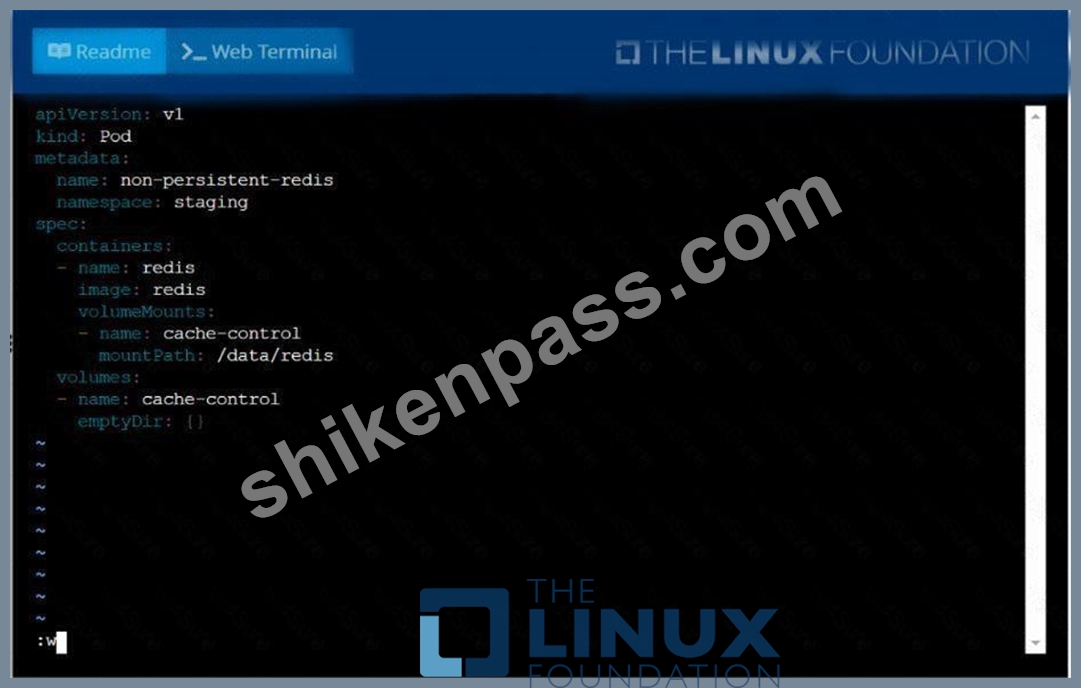
Create a pod as follows:
* Name: non-persistent-redis
* container Image: redis
* Volume with name: cache-control
* Mount path: /data/redis
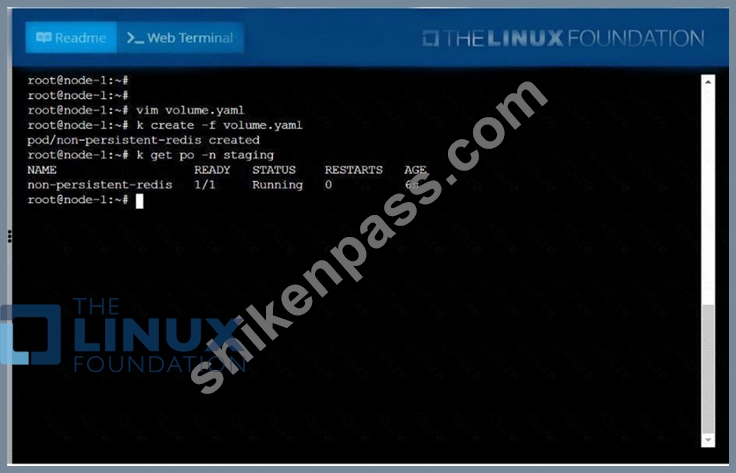
The pod should launch in the staging namespace and the volume must not be persistent.
正解:
解説:
See the solution below.
Explanation
solution
質問 # 61
Score: 7%
Task
Reconfigure the existing deployment front-end and add a port specification named http exposing port 80/tcp of the existing container nginx.
Create a new service named front-end-svc exposing the container port http.
Configure the new service to also expose the individual Pods via a NodePort on the nodes on which they are scheduled.
正解:
解説:
See the solution below.
Explanation
Solution:
kubectl get deploy front-end
kubectl edit deploy front-end -o yaml
#port specification named http
#service.yaml
apiVersion: v1
kind: Service
metadata:
name: front-end-svc
labels:
app: nginx
spec:
ports:
- port: 80
protocol: tcp
name: http
selector:
app: nginx
type: NodePort
# kubectl create -f service.yaml
# kubectl get svc
# port specification named http
kubectl expose deployment front-end --name=front-end-svc --port=80 --tarport=80 --type=NodePort
質問 # 62
You have a Kubernetes cluster running with several pods, each exposed via a 'Service' of type LoadBalance. However, you notice some pods are randomly unreachable from external clients, despite appearing healthy in the cluster. You suspect this could be a network issue within the cluster. Describe the steps you would take to diagnose and troubleshoot this issue, focusing on network-related aspects of Kubernetes.
正解:
解説:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
1. Verify Service Configuration:
- Use 'kubectl describe service ' to examine the service definition.
- Check if the 'externallPs are correctly configured and match the IPs assigned by your cloud provider.
- Ensure that the 'selector' in the service matches the labels on the pods you're trying to access.
2. Check Pod Connectivity:
- Use 'kubectl exec -it bash' to get a shell within one of the pods.
- Run 'ping ' to test connectivity from within the pod to the external IP of the service.
- If ping fails, it indicates that the pod can't reach the service's external IP.
3. Examine Network Policies:
- Check if any 'NetworkPolicy' rules are blocking traffic to or from the pods in question.
- Use 'kubectl get networkpolicies' and 'kubectl describe networkpolicy to list and examine policies.
4. Inspect Network Resources:
- Use "kubectl get nodes' to check the status of the nodes. Look for any node-level networking problems or errors.
- Examine network resource usage (e.g., bandwidth, CPU) on the nodes using tools like 'kubectl top nodes'.
5. Analyze Cluster Events:
- Check the Kubernetes event logs using 'kubectl get events'. Look for events related to networking issues, pod restarts, or other relevant events.
6. Inspect Network Connectivity (Node-Level):
- If the issue seems to originate within the cluster, use tools like 'ping' or 'traceroute' from within a node to test connectivity between nodes and/or to external services.
7. Verify Load Balancer Health:
- If using a cloud provider's load balancer, check its health status and logs. Ensure it's correctly forwarding traffic to the back-end pods.
8. Check Firewall Rules:
- Ensure that there are no external firewall rules blocking traffic to the Kubernetes cluster or specific ports used by the services.
9. Consider Network Plugin Configuration:
- Review the configuration of the network plugin used in your cluster (e.g., Calico, Flannel). Potential issues in the plugin's configuration might cause connectivity problems.
Example Scenario: Imagine you have a NodePort service 'my-service' exposing a web server. The service is configured to forward traffic to pods labeled 'app=web'. You're able to access the service from within the cluster but encounter random disconnections from external clients. Troubleshooting Steps:
1 . Verify the service definition to ensure 'externallPs' are correctly assigned and 'selector' matches pod label
2. 'kubectl exec -it bash' to ping the service's 'externallP'. If unsuccessful, proceed to step 3.
3. Check if any NetworkPolicies are blocking traffic to the 'web' pods.
4. Verify the health status of all nodes in the cluster.
5. Examine cluster events for any networking-related errors.
6. Use ping' and 'traceroute' from a node to test connectivity to the external service.
7. Check the health of the load balancer if it's being used.
8. Ensure no external firewall rules block traffic to the service's ports.
9. Inspect the configuration of the network plugin in your cluster for any potential issues.
質問 # 63
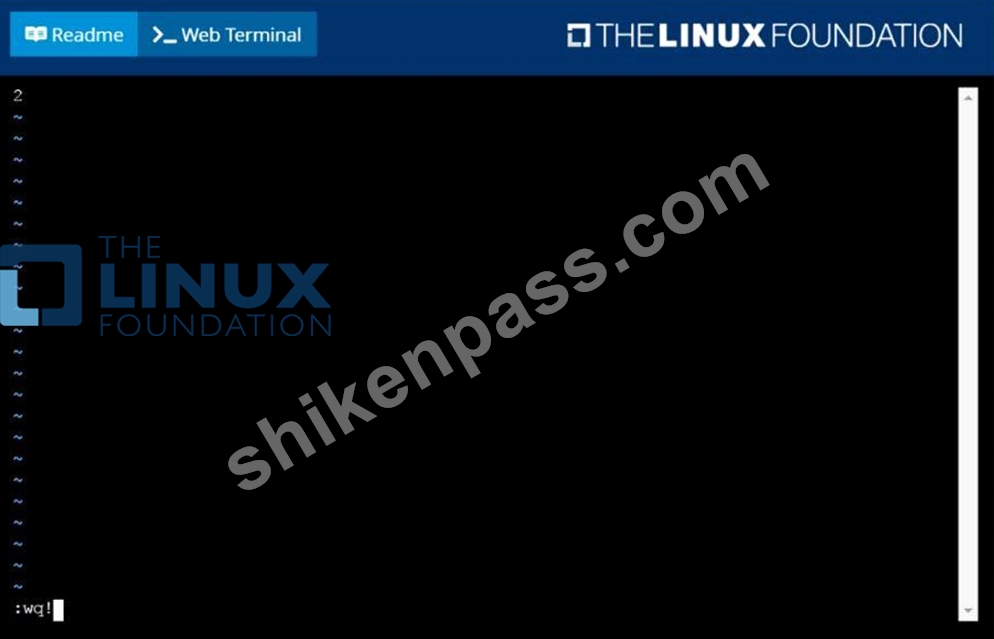
Check to see how many worker nodes are ready (not including nodes tainted NoSchedule) and write the number to /opt/KUCC00104/kucc00104.txt.
正解:
解説:
solution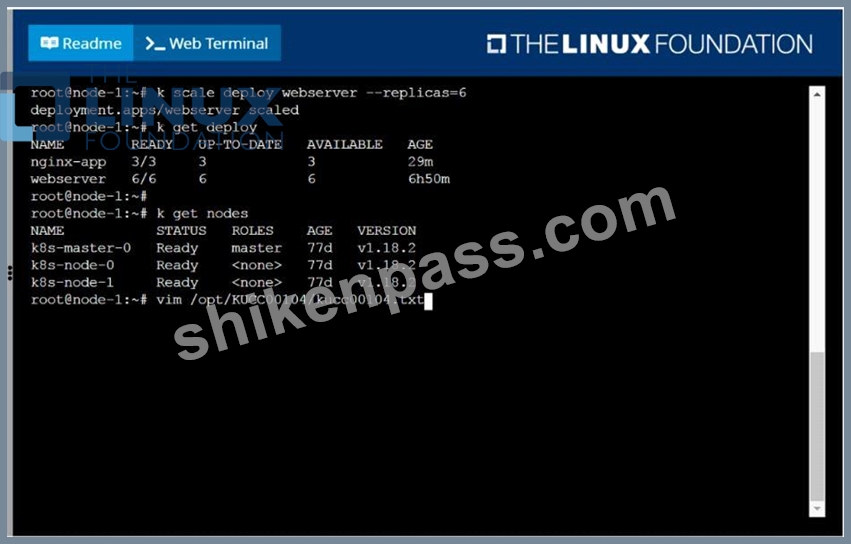
質問 # 64
......
CKA認証試験に合格することは他の世界の有名な認証に合格して国際の承認と受け入れを取ることと同じです。CKA認定試験もIT領域の幅広い認証を取得しました。世界各地でCKA試験に受かることを通じて自分のキャリアをもっと向上させる人々がたくさんいます。ShikenPASSで、あなたは自分に向いている製品をどちらでも選べます。
CKA基礎訓練: https://www.shikenpass.com/CKA-shiken.html
P.S. ShikenPASSがGoogle Driveで共有している無料かつ新しいCKAダンプ:https://drive.google.com/open?id=1aF3uTOQyv-GvnTKRaV2IUeYKL78KGAv5