P.S. Free 2026 Microsoft DP-600 dumps are available on Google Drive shared by SureTorrent: https://drive.google.com/open?id=1IEagXZrmoyP8-2HWNngg6p9mROqCSw4Y
Don't let the Implementing Analytics Solutions Using Microsoft Fabric exam stress you out! Prepare with our DP-600 exam dumps and boost your confidence in the DP-600 exam. We guarantee your road toward success by helping you prepare for the DP-600 exam. Use the best Microsoft DP-600 practice questions to pass your DP-600 Exam with flying colors! In this way, the Implementing Analytics Solutions Using Microsoft Fabric certified professionals can not only validate their skills and knowledge level but also put their careers on the right track. By doing this you can achieve your career objectives.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> Reliable Microsoft DP-600 Test Question <<
Our DP-600 exam guide have also set a series of explanation about the complicated parts certificated by the syllabus and are based on the actual situation to stimulate exam circumstance in order to provide you a high-quality and high-efficiency user experience. In addition, the DP-600 exam guide function as a time-counter, and you can set fixed time to fulfill your task, so that promote your efficiency in real test. The key strong-point of our DP-600 Test Guide is that we impart more important knowledge with fewer questions and answers, with those easily understandable DP-600 study braindumps, you will find more interests in them and experience an easy learning process.
NEW QUESTION # 95
You have a Fabric tenant that contains the workspaces shown in the following table.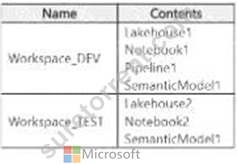
You have a deployment pipeline named Pipeline1 that deploys items from Workspace_DEV to Workspace_TEST. In Pipeline1, all items that have matching names are paired.
You deploy the contents of Workspace_DEV to Workspace_TEST by using Pipeline1.
What will the contents of Workspace_TEST be once the deployment is complete?
Answer: A
Explanation:
Workspace_DEV contents:
Lakehouse1, Notebook1, Pipeline1, SemanticModel1
Workspace_TEST contents (before deployment):
Lakehouse2, Notebook2, SemanticModel1
After deployment:
SemanticModel1 # same name, so it will be paired and overwritten with the DEV version.
Lakehouse1 and Notebook1 # new items, so they will be added to TEST.
Lakehouse2 and Notebook2 # remain because they don't conflict in name.
Pipeline1 # new item, so it will also be added .
So the final content is:
Lakehouse1, Lakehouse2, Notebook1, Notebook2, Pipeline1, SemanticModel1
NEW QUESTION # 96
Case Study 2 - Litware, Inc
Overview
Litware, Inc. is a manufacturing company that has offices throughout North America. The analytics team at Litware contains data engineers, analytics engineers, data analysts, and data scientists.
Existing Environment
Fabric Environment
Litware has been using a Microsoft Power BI tenant for three years. Litware has NOT enabled any Fabric capacities and features.
Available Data
Litware has data that must be analyzed as shown in the following table.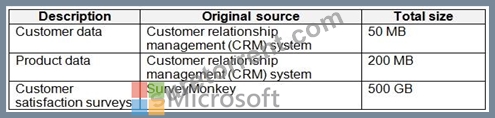
The Product data contains a single table and the following columns.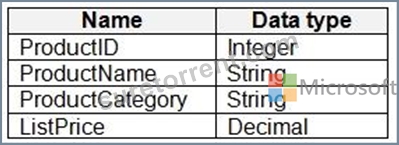
The customer satisfaction data contains the following tables:
- Survey
- Question
- Response
For each survey submitted, the following occurs:
- One row is added to the Survey table.
- One row is added to the Response table for each question in the survey.
- The Question table contains the text of each survey question. The third question in each survey response is an overall satisfaction score. Customers can submit a survey after each purchase.
User Problems
The analytics team has large volumes of data, some of which is semi-structured. The team wants to use Fabric to create a new data store.
Product data is often classified into three pricing groups: high, medium, and low. This logic is implemented in several databases and semantic models, but the logic does NOT always match across implementations.
Requirements
Planned Changes
Litware plans to enable Fabric features in the existing tenant. The analytics team will create a new data store as a proof of concept (PoC). The remaining Liware users will only get access to the Fabric features once the PoC is complete. The PoC will be completed by using a Fabric trial capacity The following three workspaces will be created:
- AnalyticsPOC: Will contain the data store, semantic models, reports pipelines, dataflow, and notebooks used to populate the data store
- DataEngPOC: Will contain all the pipelines, dataflows, and notebooks used to populate OneLake
- DataSciPOC: Will contain all the notebooks and reports created by the data scientists The following will be created in the AnalyticsPOC workspace:
- A data store (type to be decided)
- A custom semantic model
- A default semantic model
Interactive reports
The data engineers will create data pipelines to load data to OneLake either hourly or daily depending on the data source. The analytics engineers will create processes to ingest, transform, and load the data to the data store in the AnalyticsPOC workspace daily. Whenever possible, the data engineers will use low-code tools for data ingestion. The choice of which data cleansing and transformation tools to use will be at the data engineers' discretion.
All the semantic models and reports in the Analytics POC workspace will use the data store as the sole data source.
Technical Requirements
The data store must support the following:
- Read access by using T-SQL or Python
- Semi-structured and unstructured data
- Row-level security (RLS) for users executing T-SQL queries
Files loaded by the data engineers to OneLake will be stored in the Parquet format and will meet Delta Lake specifications.
Data will be loaded without transformation in one area of the AnalyticsPOC data store. The data will then be cleansed, merged, and transformed into a dimensional model The data load process must ensure that the raw and cleansed data is updated completely before populating the dimensional model The dimensional model must contain a date dimension. There is no existing data source for the date dimension. The Litware fiscal year matches the calendar year. The date dimension must always contain dates from 2010 through the end of the current year.
The product pricing group logic must be maintained by the analytics engineers in a single location. The pricing group data must be made available in the data store for T-SOL. queries and in the default semantic model. The following logic must be used:
- List prices that are less than or equal to 50 are in the low pricing group.
- List prices that are greater than 50 and less than or equal to 1,000 are in the medium pricing group.
- List prices that are greater than 1,000 are in the high pricing group.
Security Requirements
Only Fabric administrators and the analytics team must be able to see the Fabric items created as part of the PoC.
Litware identifies the following security requirements for the Fabric items in the AnalyticsPOC workspace:
- Fabric administrators will be the workspace administrators.
- The data engineers must be able to read from and write to the data store. No access must be granted to datasets or reports.
- The analytics engineers must be able to read from, write to, and create schemas in the data store. They also must be able to create and share semantic models with the data analysts and view and modify all reports in the workspace.
- The data scientists must be able to read from the data store, but not write to it. They will access the data by using a Spark notebook
- The data analysts must have read access to only the dimensional model objects in the data store. They also must have access to create Power BI reports by using the semantic models created by the analytics engineers.
- The date dimension must be available to all users of the data store.
- The principle of least privilege must be followed.
Both the default and custom semantic models must include only tables or views from the dimensional model in the data store. Litware already has the following Microsoft Entra security groups:
FabricAdmins: Fabric administrators
- AnalyticsTeam: All the members of the analytics team
- DataAnalysts: The data analysts on the analytics team
- DataScientists: The data scientists on the analytics team
- DataEngineers: The data engineers on the analytics team
- AnalyticsEngineers: The analytics engineers on the analytics team
Report Requirements
The data analysts must create a customer satisfaction report that meets the following requirements:
- Enables a user to select a product to filter customer survey responses to only those who have purchased that product.
- Displays the average overall satisfaction score of all the surveys submitted during the last 12 months up to a selected dat.
- Shows data as soon as the data is updated in the data store.
- Ensures that the report and the semantic model only contain data from the current and previous year.
- Ensures that the report respects any table-level security specified in the source data store.
- Minimizes the execution time of report queries.
Which type of data store should you recommend in the AnalyticsPOC workspace?
Answer: D
Explanation:
The data store must handle semi-structured and unstructured data, therefore a Lakehouse should be the optimal solution supporting read access with T-SQL and Python.
NEW QUESTION # 97
You have a Fabric tenant.
You plan to create a Fabric notebook that will use Spark DataFrames to generate Microsoft Power Bl visuals.
You run the following code.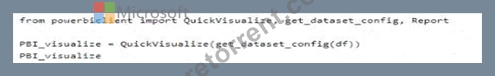
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.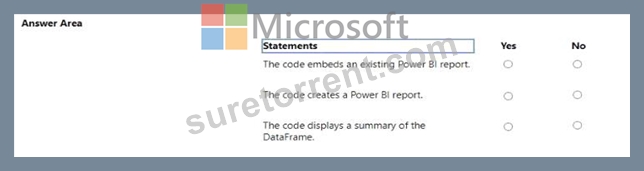
Answer:
Explanation: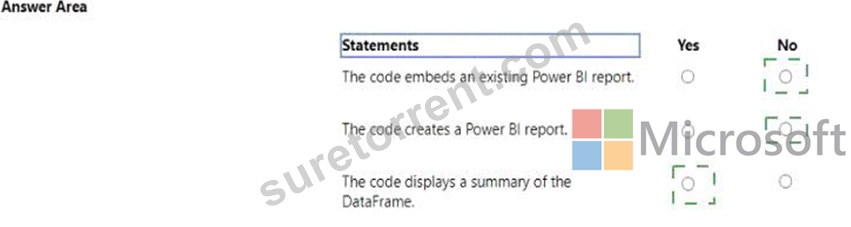
Explanation:
The code embeds an existing Power BI report. - No
The code creates a Power BI report. - Yes
The code displays a summary of the DataFrame. - Yes
The code provided seems to be a snippet from a SQL query or script which is neither creating nor embedding a Power BI report directly. It appears to be setting up a DataFrame for use within a larger context, potentially for visualization in Power BI, but the code itself does not perform the creation or embedding of a report.
Instead, it ' s likely part of a data processing step that summarizes data.
References =
Introduction to DataFrames - Spark SQL
Power BI and Azure Databricks
NEW QUESTION # 98
You have a Microsoft Power Bl project that contains a file named definition.pbir. definition.pbir contains the following JSON.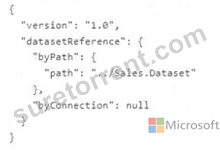
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.
Answer:
Explanation: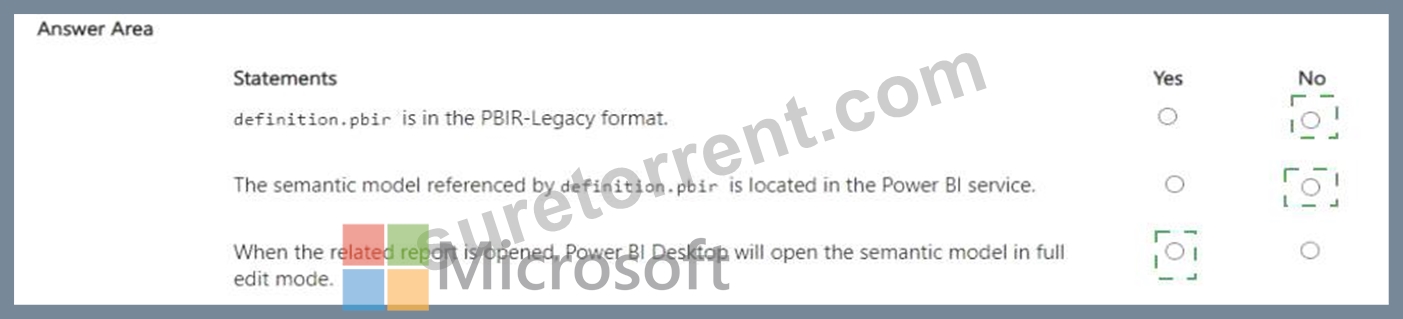
Explanation: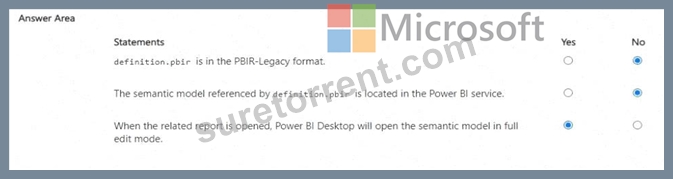
NEW QUESTION # 99
You have a Fabric tenant that contains a lakehouse named Lakehouse1. Lakehouse1 contains a subfolder named Subfolder1 that contains CSV files. You need to convert the CSV files into the delta format that has V-Order optimization enabled. What should you do from Lakehouse explorer?
Answer: B
Explanation:
To convert CSV files into the delta format with Z-Order optimization enabled, you should use the Optimize feature (D) from Lakehouse Explorer. This will allow you to optimize the file organization for the most efficient querying. References = The process for converting and optimizing file formats within a lakehouse is discussed in the lakehouse management documentation.
NEW QUESTION # 100
......
This is a gainful opportunity to choose DP-600 actual exam from our company. They are saleable offerings from our responsible company who dedicated in this line over ten years which helps customers with desirable outcomes with the help of our DP-600 Study Guide. Up to now, there are three versions of DP-600 exam materials for your reference. They are PDF, software and app versions. And we have free demos for you to download before you decide to purchase.
Certification DP-600 Exam Infor: https://www.suretorrent.com/DP-600-exam-guide-torrent.html
DOWNLOAD the newest SureTorrent DP-600 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1IEagXZrmoyP8-2HWNngg6p9mROqCSw4Y