What's more, part of that Free4Torrent Workday-Pro-Integrations dumps now are free: https://drive.google.com/open?id=1hd9Wg8-jsXpP1yWcAzUbe-DuPfT4GyZu
Our website offer you one-year free update Workday-Pro-Integrations study guide from the date of you purchased. We will send you the latest version to your email immediately once we have any updating about the Workday-Pro-Integrations braindumps. Our goal is ensure you get high passing score in the Workday-Pro-Integrations Practice Exam with less effort and less time. The accuracy of our questions and answers will the guarantee of passing actual test.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> Test Workday-Pro-Integrations Cram Pdf <<
It is very necessary for candidates to get valid Workday-Pro-Integrations dumps collection because it can save your time and help you get succeed in IT filed by clearing Workday-Pro-Integrations actual test. Passing real exam is not easy task so many people need to take professional suggestions to prepare Workday-Pro-Integrations Practice Exam. The reason that we get good reputation among dump vendors is the most reliable Workday-Pro-Integrations pdf vce and the best-quality service.
NEW QUESTION # 62
You have been asked to create an integration using the Core Connector: Worker with DIS template. The vendor has requested that you only include employees who are based in the San Francisco area that are on leave.
How do you configure your integration so that only workers who meet the requirements are included in the output file?
Answer: B
Explanation:
When using Core Connector: Worker with DIS, to restrict the population to employees who:
* Are on leave, and
* Are located in San Francisco
You must configure Population Eligibility, which is the only place to filter the worker population included in the connector output.
From Workday Pro documentation:
"The Population Eligibility section defines which workers are eligible for extraction in the integration based on location, status, organization, and other conditions. Boolean calculated fields can be used here to define complex eligibility criteria." In this case:
* Create a Boolean calculated field that returns true for "On Leave AND Location = San Francisco"
* Use that field in Population Eligibility
Why the others are incorrect:
* A, D. Field Overrides and Field Attributes only modify what data is extracted-not who is included.
* C. Integration Attributes don't control population filtering.
Reference:Workday Pro: Core Connector Worker - Population Eligibility and Filtering LogicWorkday Community - Using Boolean Fields in Population Eligibility Rules
NEW QUESTION # 63
A vendor needs an EIB that uses a custom report to output a list of new hires and their child dependent(s). You have been asked to create a calculated field that will be used to add only child dependent(s).
Which calculated field functions do you need to accomplish this?
Answer: B
Explanation:
In this case, you're asked to create a calculated field that:
Filters dependent records
Includes only child relationships
This means:
The worker has multiple dependents (a multi-instance field).
You need to extract only those dependent(s) where the relationship is "Child".
To achieve this in Workday, use:
True/False Condition → check if the relationship descriptor = "Child"
Extract Multi-Instance → filters the multi-instance field (Dependents) using the above condition to return only matching records This two-step logic filters multi-instance relationships correctly.
Why the other options are incorrect:
A and B are missing Extract Multi-Instance, which is required to filter multi-values.
C includes Text Constant unnecessarily - only True/False Condition and Extract Multi-Instance are required.
NEW QUESTION # 64
You have an existing Core Connector: Organization (non-IS) integration that sends organization data to an external vendor. The vendor now requires a specific Legacy ID for each organization to be added to the output. A calculated field that generates this Legacy ID already exists in the tenant.
What is the high-level workflow order you would follow to add this calculated field to the output of the integration?
Answer: A
Explanation:
Because the calculated field already exists, the workflow should not begin by creating another calculated field. For a Core Connector: Organization non-IS integration, the output structure must be extended through the integration service configuration so the connector can support the additional custom field. The next step is to create the custom field override service that makes the custom calculated value available for the connector output. After that, Integration Field Overrides are configured to map the existing Legacy ID calculated field into the appropriate output location. Integration Attributes are used for integration-level settings and are not the correct mechanism for adding a calculated field to the output. Integration Maps transform values, but they do not add a new calculated field to the file structure.
NEW QUESTION # 65
Refer to the following scenario to answer the question below.
You are configuring a Core Connector: Worker integration to send data to a new external compliance and certification tracking vendor. You have begun to configure the connector with the Data Initialization Service (DIS) enabled. Your goal is to extract worker qualification data, but the vendor has three specific requirements:
The file must only include Active workers who are in the "Clinical Staff" Job Family.
The vendor has specified that for each worker's Education data, they only want to receive the Institution Name, Institution Type and Degree.
The vendor requires a custom "License ID" that must combine the Certification Name and Issuing State, for example, "RN-CA". A Calculated Field that provides this custom "License ID" already exists in the tenant.
The License ID calculated field is not displaying in the output however you have confirmed the calculated field exists and is functional in the tenant.
What configuration step should you complete to include this field in the output?
Answer: C
Explanation:
A calculated field that already exists in the tenant is not automatically emitted in a Core Connector output. For this requirement, the connector must be extended so the custom value becomes available and is then placed into the outbound structure. Creating a Custom Field Override service makes the calculated License ID available for the connector output, and the integration field override then adds that calculated field into the file. Integration Maps are used to translate values, such as converting one code set to another; they do not add a new calculated field. Field Attributes mainly control delivered field inclusion and field behavior. Since the requirement is to add a custom calculated output value, the custom field override service plus field override configuration is the correct workflow.
NEW QUESTION # 66
Refer to the following XML to answer the question below.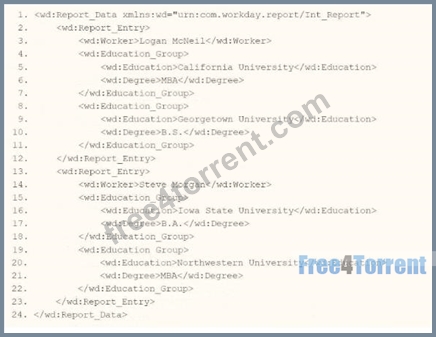
Within the template which matches on wd:Report_Entry, you would like to conditionally process the wd:Education_Group elements by using an <xsl:apply-templates> element. What XPath syntax would be used for the select to iterate over only the wd:Education_Group elements where the Degree is an MBA?
Answer: B
Explanation:
In Workday integrations, XSLT is used to transform XML data, such as the output from a web service-enabled report or EIB, into a desired format for third-party systems. In this scenario, you need to write XSLT to process wd:Education_Group elements within a template matching wd:Report_Entry, using an <xsl:apply-templates> element to iterate only over wd:Education_Group elements where the wd:Degree is "MBA." The correct XPath syntax for the select attribute is critical to ensure accurate filtering.
Here's why option A is correct:
XPath Syntax In XPath, square brackets [ ] are used to specify predicates or conditions to filter elements. The condition wd:Degree='MBA' checks if the wd:Degree child element has the value "MBA." When applied to wd:Education_Group, the expression wd:Education_Group[wd:Degree='MBA'] selects only those wd:Education_Group elements that contain a wd:Degree child element with the value "MBA." Context in XSLT: Within an <xsl:apply-templates> element in a template matching wd:Report_Entry, the select attribute uses XPath to specify which nodes to process. This syntax ensures that the template only applies to wd:Education_Group elements where the degree is "MBA," aligning with the requirement to conditionally process only those specific education groups.
XML Structure Alignment: Based on the provided XML snippet, wd:Education_Group contains wd:Education and wd:Degree child elements (e.g., <wd:Degree>MBA</wd:Degree>). The XPath wd:Education_Group[wd:Degree='MBA'] correctly navigates to wd:Education_Group and filters based on the wd:Degree value, matching the structure and requirement.
Why not the other options?
B . wd:Education_Group/wd:Degree='MBA': This is not a valid XPath expression for a predicate. It attempts to navigate to wd:Degree as a child but does not use square brackets [ ] to create a filtering condition. This would be interpreted as selecting wd:Degree elements under wd:Education_Group, but it wouldn't filter based on the value "MBA" correctly within an <xsl:apply-templates> context.
C . wd:Report_Entry/wd:Education_Group/wd:Degree='MBA' 1:Degree='MBA': This is syntactically incorrect and unclear. It includes a malformed condition (1:Degree='MBA') and does not use proper XPath predicate syntax. It fails to filter wd:Education_Group elements based on wd:Degree='MBA' and is not valid for use in select.
D . wd:Report_Entry/wd:Education_Group[wd:Degree='MBA' 1:Degree='MBA']: This is also syntactically incorrect due to the inclusion of 1:Degree='MBA' within the predicate. The 1: prefix is not valid XPath syntax and introduces an error. The correct predicate should only be wd:Degree='MBA' to filter the wd:Education_Group elements.
To implement this in XSLT:
Within your template matching wd:Report_Entry, you would write an <xsl:apply-templates> element with the select attribute set to wd:Education_Group[wd:Degree='MBA']. This ensures that only wd:Education_Group elements with a wd:Degree value of "MBA" are processed by the corresponding templates, effectively filtering out other degrees (e.g., B.S., B.A.) in the transformation.
This approach ensures the XSLT transformation aligns with Workday's XML structure and integration requirements for processing education data in a report output.
:
Workday Pro Integrations Study Guide: Section on "XSLT Transformations for Workday Integrations" - Details the use of XPath in XSLT for filtering XML elements, including predicates for conditional processing based on child element values.
Workday EIB and Web Services Guide: Chapter on "XML and XSLT for Report Data" - Explains the structure of Workday XML (e.g., wd:Education_Group, wd:Degree) and how to use XPath to navigate and filter data.
Workday Reporting and Analytics Guide: Section on "Web Service-Enabled Reports" - Covers integrating report outputs with XSLT for transformations, including examples of filtering elements based on specific values like degree types.
NEW QUESTION # 67
......
Useful Workday-Pro-Integrations exam prep is subservient to your development. To add up your interests and simplify some difficult points, our experts try their best to design our Workday-Pro-Integrations training material and help you understand the Workday-Pro-Integrations study guide better. And our experts generalize the knowledge of the exam into our products showing in three versions: the PDF, the Software and the APP online. You can choose your most desirable way to practice our Workday-Pro-Integrations Preparation engine on the daily basis.
Workday-Pro-Integrations Passleader Review: https://www.free4torrent.com/Workday-Pro-Integrations-braindumps-torrent.html
BTW, DOWNLOAD part of Free4Torrent Workday-Pro-Integrations dumps from Cloud Storage: https://drive.google.com/open?id=1hd9Wg8-jsXpP1yWcAzUbe-DuPfT4GyZu