さらに、ShikenPASS Databricks-Certified-Data-Engineer-Professionalダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1Mjj6BsNASo1Yh9odjoi_NW9EEtnTHnsf
弊社は一年の更新サービスを提供します。お客様は我々のサイトでDatabricks-Certified-Data-Engineer-Professional問題集をご購入になってから、そのあとの一年間、我々は無料の更新サービスを提供します。もしその一年の中で、Databricks-Certified-Data-Engineer-Professional問題集が更新されたら、我々はお客様に最新版をお送りいたします。すなわち、その一年間、お客様の持っているDatabricks-Certified-Data-Engineer-Professional問題集はずっと最新のです。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Debugging and Deploying | 10% | - Troubleshoot and debug pipelines - Deploy using Asset Bundles, CLI, and APIs - Implement CI/CD and DevOps practices |
| Topic 2: Data Transformation, Cleansing, and Quality | 10% | - Implement schema evolution and management - Enforce data quality standards - Apply data cleansing and validation rules |
| Topic 3: Cost & Performance Optimisation | 13% | - Optimize compute and storage resources - Improve query and pipeline performance - Apply cost management best practices |
| Topic 4: Developing Code for Data Processing using Python and SQL | 22% | - Use Databricks-specific libraries and APIs - Implement complex data processing logic - Write efficient and maintainable code |
| Topic 5: Data Modelling | 6% | - Design Medallion Architecture - Optimize table design and partitioning - Implement dimensional and relational models |
| Topic 6: Ensuring Data Security and Compliance | 10% | - Ensure data privacy and compliance - Implement access control and permissions - Secure data at rest and in transit |
| Topic 7: Data Sharing and Federation | 5% | - Manage cross-platform data access - Use Delta Sharing for secure data sharing - Implement Lakehouse Federation |
| Topic 8: Data Governance | 7% | - Manage data assets and metadata - Enforce data policies and standards - Use Unity Catalog for governance |
| Topic 9: Data Ingestion & Acquisition | 7% | - Handle incremental and batch data loads - Use Auto Loader and structured streaming - Ingest data from diverse sources |
| Topic 10: Monitoring and Alerting | 10% | - Set up alerts and notifications - Track data lineage and metrics - Monitor pipeline performance and health |
>> Databricks-Certified-Data-Engineer-Professional専門試験 <<
IT 職員のそれぞれは昇進または高給のために頑張っています。これも現代社会が圧力に満ちている一つの反映です。そのためにDatabricksのDatabricks-Certified-Data-Engineer-Professional認定試験に受かる必要があります。適当なトレーニング資料を選んだらこの試験はそんなに難しくなくなります。ShikenPASSのDatabricksのDatabricks-Certified-Data-Engineer-Professional「Databricks Certified Data Engineer Professional Exam」試験トレーニング資料は最高のトレーニング資料で、あなたの全てのニーズを満たすことができますから、速く行動しましょう。
質問 # 248
A data engineer is creating a data ingestion pipeline to understand where customers are taking their rented bicycles during use. The engineer noticed that, over time, data being transmitted from the bicycle sensors fail to include key details like latitude and longitude. Downstream analysts need both the clean records and the quarantined records available for separate processing.
The data engineer already has this code:
import dlt
from pyspark.sql.functions import expr
rules = {
"valid_lat": "(lat IS NOT NULL)",
"valid_long": "(long IS NOT NULL)"
}
quarantine_rules = "NOT({})".format(" AND ".join(rules.values()))
@dlt.view
def raw_trips_data():
return spark.readStream.table("ride_and_go.telemetry.trips")
How should the data engineer meet the requirements to capture good and bad data?
正解:A
解説:
The requirement is that both valid (good) and invalid (bad) records must be captured and available separately for downstream processing. Invalid records should not simply be dropped; they must be quarantined in a dedicated table.
In Databricks Lakeflow Declarative Pipelines (DLT), this is achieved by creating separate output tables:
One table for valid records (Silver table) that pass the expectations.
Another quarantine table that explicitly captures records failing the expectations.
Option A correctly implements this by:
Declaring a DLT table trips_data_quarantine.
Using .filter(expr(quarantine_rules)) to isolate invalid records (records where latitude or longitude is NULL).
This ensures analysts can query both good records (from the main Silver pipeline table) and bad records (from the quarantine table).
質問 # 249
A data engineer is designing a secure data sharing strategy for their organization. The company needs to share sensitive customer analytics data with two different partners. Partner A uses Databricks with Unity Catalog enabled, while Partner B uses Apache Spark on AWS without Databricks. How should the company implement secure data sharing for these scenarios?
正解:D
解説:
Databricks-to-Databricks sharing with Unity Catalog provides the most seamless and secure option for Partner A by enabling native governance, fine-grained access controls, and a no-token exchange model. For Partner B, which does not use Databricks, the open sharing protocol enables secure access from external Spark environments using standard authentication mechanisms such as bearer tokens or OIDC federation, while still enforcing sharing policies and protecting sensitive data.
質問 # 250
The downstream consumers of a Delta Lake table have been complaining about data quality issues impacting performance in their applications. Specifically, they have complained that invalid latitude and longitude values in the activity_details table have been breaking their ability to use other geolocation processes.
A junior engineer has written the following code to add CHECK constraints to the Delta Lake table: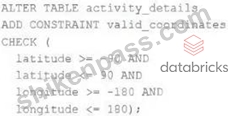
A senior engineer has confirmed the above logic is correct and the valid ranges for latitude and longitude are provided, but the code fails when executed.
Which statement explains the cause of this failure?
正解:B
解説:
The failure is that the code to add CHECK constraints to the Delta Lake table fails when executed. The code uses ALTER TABLE ADD CONSTRAINT commands to add two CHECK constraints to a table named activity_details. The first constraint checks if the latitude value is between -90 and 90, and the second constraint checks if the longitude value is between -180 and
180. The cause of this failure is that the activity_details table already contains records that violate these constraints, meaning that they have invalid latitude or longitude values outside of these ranges. When adding CHECK constraints to an existing table, Delta Lake verifies that all existing data satisfies the constraints before adding them to the table. If any record violates the constraints, Delta Lake throws an exception and aborts the operation.
質問 # 251
A data engineer created a daily batch ingestion pipeline using a cluster with the latest DBR version to store banking transaction data, and persisted it in a MANAGED DELTA table called prod.gold.all_banking_transactions_daily. The data engineer is constantly receiving complaints from business users who query this table ad hoc through a SQL Serverless Warehouse about poor query performance. Upon analysis, the data engineer identified that these users frequently use high- cardinality columns as filters. The engineer now seeks to implement a data layout optimization technique that is incremental, easy to maintain, and can evolve over time. Which command should the data engineer implement?
正解:B
解説:
Databricks recommends Liquid Clustering for optimizing data layout in large Delta tables where query filters involve high-cardinality columns. Liquid Clustering automatically manages file organization and supports incremental maintenance without the need to rewrite data when clustering keys evolve. This is a key advantage over static partitioning or Z-ordering, which require costly file rewrites whenever optimization keys change. By combining Liquid Clustering with a periodic OPTIMIZE command, Databricks automatically compacts small files and maintains efficient data skipping performance. As stated in the Delta Lake optimization guide, Liquid Clustering is designed for scalability, minimal maintenance, and adaptability for analytical workloads with evolving query patterns--making B the correct answer.
質問 # 252
A data engineer needs to create an application that will collect information about the latest job run including the repair history. How should the data engineer format the request?
正解:C
解説:
To retrieve information about the latest job runs along with their repair history, you use the jobs/runs/list endpoint with the job_id and include_history=true. This endpoint returns a list of runs for a specific job, including details about retries and repair attempts, which is not available via runs/get that retrieves a single run by run_id.
質問 # 253
......
アンケート調査によると、IT業種の皆さんが現在最も受験したい認定試験はDatabricksのDatabricks-Certified-Data-Engineer-Professional試験だそうです。確かに、この試験はとても大切な試験で、公的に認可されたものです。しかも、この認定資格があなたが高い技能を身につけていることも証明できます。しかしながら、試験の大切さと同じ、この試験も非常に難しいです。試験に合格するのは少し大変ですが、心配しないでくださいよ。ShikenPASSはあなたに難しいDatabricks-Certified-Data-Engineer-Professional認定試験に合格することを助けてあげますから。
Databricks-Certified-Data-Engineer-Professional資格関連題: https://www.shikenpass.com/Databricks-Certified-Data-Engineer-Professional-shiken.html
さらに、ShikenPASS Databricks-Certified-Data-Engineer-Professionalダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1Mjj6BsNASo1Yh9odjoi_NW9EEtnTHnsf