Actual4Cert's Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam questions contain Microsoft DP-750 real questions and answers that have been compiled and verified by Microsoft specialists in the field. This demonstrates that the real questions and answers in the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) material are legitimate for the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) practice exam. The Microsoft DP-750 practice questions are intended to help you easily and confidently clear the Implementing Data Engineering Solutions Using Azure Databricks (DP-750).
| Section | Weight | Objectives |
|---|---|---|
| Deploy and manage data pipelines and workloads | 30-35% | - Operational reliability
|
| Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
| Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
| Prepare and process data | 30-35% | - Data transformation and modeling
|
Many students often start to study as the exam is approaching. Time is very valuable to these students, and for them, one extra hour of study may mean 3 points more on the test score. If you are one of these students, then Implementing Data Engineering Solutions Using Azure Databricks exam tests are your best choice. Because students often purchase materials from the Internet, there is a problem that they need transport time, especially for those students who live in remote areas. When the materials arrive, they may just have a little time to read them before the exam. However, with DP-750 Exam Questions, you will never encounter such problems, because our materials are distributed to customers through emails. After you have successfully paid, you can immediately receive DP-750 test guide from our customer service staff, and then you can start learning immediately.
NEW QUESTION # 78
Which component enforces table-level permissions in Databricks?
Answer: D
Explanation:
Unity Catalog provides fine-grained access control at table, schema, and column levels. It centralizes governance across workspaces. Cluster policies control compute settings. Spark configuration does not manage security. DBFS permissions are not sufficient for enterprise governance.
NEW QUESTION # 79
You have an Azure Databricks workspace
You are creating a Lakeflow Spark Declarative Pipelines (SDP) pipeline that scales automatically. You need to configure compute for the pipeline. The solution must minimize operational costs and effort. What should you use?
Answer: B
Explanation:
The correct answer is C - a job cluster that uses autoscaling.
Job clusters (also called pipeline clusters in the SDP context) are created exclusively for a pipeline run and terminated when the pipeline stops. You pay only for what the pipeline uses, and there's no idle cost between runs. Autoscaling on a job cluster lets the pipeline expand during heavy processing and contract during lighter stages - the combination of on-demand lifecycle and elastic scaling gives the lowest operational cost.
Option A (all-purpose cluster) runs at a higher DBU rate and persists beyond the pipeline's lifecycle, meaning you're paying for it even when the pipeline isn't running. Option B (SQL warehouse) is optimised for interactive BI and ad-hoc queries, not for the batch/streaming workloads SDP pipelines run. Option D (single- node all-purpose) has no scaling, runs at the all-purpose DBU rate, and is capped at one node - unsuitable for any production pipeline.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/configure-pipeline
NEW QUESTION # 80
What ensures failure recovery in Databricks Structured Streaming?
Answer: B
Explanation:
Checkpointing stores streaming state and progress, allowing recovery after failures without data loss or duplication. Auto scaling adjusts compute resources but does not ensure reliability.
Partition pruning improves query performance. Broadcast joins optimize joins but are unrelated to recovery.
NEW QUESTION # 81
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1. Job1 contains multiple tasks.
Failures of non-critical tasks must be logged but must NOT trigger notifications. Notifications must be triggered only when critical tasks have failed, and Job1 has completed.
You need to configure the job alerting behavior.
What should trigger a notification?
Answer: B
Explanation:
To achieve this, you should set a "Failure" notification at the individual task level for critical tasks only, rather than relying on a job-level notification.
Task-Level Notifications (Critical Tasks): By configuring notifications exclusively on the critical tasks for the "Failure" event status, any failure of these specific tasks will immediately send an alert. Because tasks execute within the job lifecycle, this notification inherently triggers while the job is in progress or completing its critical paths.
No Job-Level Notifications: You must not set a job-level "Failure" notification. If a non-critical task fails, it can cause the overall job status to register as a failure or "Succeeded with failures", which would erroneously trigger a job-level alert.
Handling Non-Critical Tasks: Non-critical tasks should be left without task-level failure notifications. To ensure they don't break downstream flows, you can configure downstream dependent tasks to use the "Run if: All done" or "Run if: None failed" (depending on your dependency architecture) conditional rules so the job execution continues and logs the failures automatically to the matrix view.
Reference:
https://learn.microsoft.com/en-us/azure/databricks/jobs/notifications
NEW QUESTION # 82
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job! contains three tasks named Task1, Task2. and Task3.
If Task1 fails, Task2 and Task3 must be prevented from running. Successfully completed tasks must NOT rerun during recovery.
You need to configure Job1 to support controlled failure handling and recovery What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation: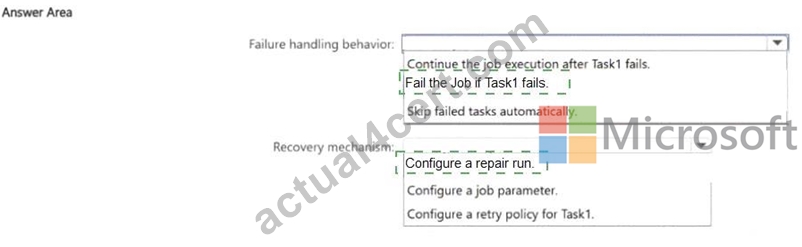
Explanation:
Two configurations are needed:
Task dependency with 'All succeeded' run condition: Set Task2 and Task3 to depend on Task1. Change the run condition on Task2 and Task3 to 'All succeeded' - this means they only execute when all their upstream dependencies (Task1) have succeeded. If Task1 fails, both downstream tasks are skipped automatically, not run with failed inputs.
Repair run for recovery: Lakeflow Jobs' Repair Run feature lets you re-execute only the tasks that failed (Task1 in this case) and their dependents (Task2 and Task3 if they were skipped), while skipping Task1 and any other tasks that already completed successfully. Successfully completed tasks are never re-executed during repair - their results are reused as-is.
Together these provide both controlled failure propagation (nothing runs downstream of a failure) and efficient recovery.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/repair-job-failures
NEW QUESTION # 83
......
With the DP-750 exam, you will harvest many points of theories that others ignore and can offer strong prove for managers. So the DP-750 exam is a great beginning. However, since there was lots of competition in this industry, the smartest way to win the battle is improving the quality of our DP-750 Learning Materials, which we did a great job. With passing rate up to 98 to 100 percent, you will get through the DP-750 exam with ease.
DP-750 Reliable Exam Bootcamp: https://www.actual4cert.com/DP-750-real-questions.html