
2026 Latest ITexamReview MLA-C01 PDF Dumps and MLA-C01 Exam Engine Free Share: https://drive.google.com/open?id=1z9OsncOry7z2GsFpZlmvfBy6kYP-GNXa
Our company always put the quality of the MLA-C01 practice materials on top priority. In the past ten years, we have made many efforts to perfect our MLA-C01 study materials. Our MLA-C01 study questions cannot tolerate any small mistake. All staff has made great dedication to developing the MLA-C01 Exam simulation. Our professional experts are devoting themselves on the compiling and updating the exam materials and our services are ready to guide you 24/7 when you have any question.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
To increase your chances of success, consider utilizing the ITexamReview MLA-C01 Exam Questions, which are valid, updated, and reflective of the actual MLA-C01 exam. Don't miss the opportunity to strengthen your Amazon MLA-C01 exam preparation with these valuable questions. The ITexamReview is a leading platform that has been assisting the Amazon MLA-C01 Exam candidates for many years. Over this long time period countless MLA-C01 exam candidates have passed their Amazon MLA-C01 certification exam. They got success in AWS Certified Machine Learning Engineer - Associate exam with flying colors and did a job in top world companies.
NEW QUESTION # 194
An ML engineer needs to deploy a trained model based on a genetic algorithm. Predictions can take several minutes, and requests can include up to 100 MB of data.
Which deployment solution will meet these requirements with the LEAST operational overhead?
Answer: D
Explanation:
SageMaker Asynchronous Inference is designed for long-running inference workloads and large payloads (up to 1 GB). Requests are queued, processed asynchronously, and results are written to Amazon S3.
Real-time endpoints have payload and timeout limits. EC2 and ECS require infrastructure management, increasing operational overhead.
AWS documentation explicitly recommends asynchronous inference for workloads with large inputs and long execution times.
Therefore, Option C is the correct and most efficient solution.
NEW QUESTION # 195
An ML engineer is deploying a generative AI model-based customer support agent that uses Amazon SageMaker AI for inference. The customer support agent must respond to customer questions about topics such as shipping policies, refund processes, and account management. The generative AI model generates one token at a time.
Customers report dissatisfaction with how long the customer support agent takes to generate lengthy responses to questions. The ML engineer must apply an inference optimization technique to improve the performance of the customer support agent.
Which solution will meet this requirement?
Answer: D
Explanation:
Option B is correct because AWS documentation states that speculative decoding is specifically a technique to speed up the decoding process of large language models . The question highlights that the model generates one token at a time and that users are unhappy with the time needed to generate lengthy responses
. That is exactly the stage of inference targeted by speculative decoding. AWS explains that this method improves latency without compromising the quality of the generated text.
According to AWS, speculative decoding works by using a smaller, faster draft model to generate candidate tokens first. The larger target model then verifies those tokens. AWS further explains that the draft model can generate multiple candidate tokens quickly, and the target model evaluates them in parallel, which speeds up the final response . This directly addresses the problem in the scenario: the customer support agent is slow not because of startup time, but because long answers require many decoding steps.
The other options are not the best fit. Compilation reduces deployment time and auto-scaling latency through ahead-of-time compilation, but AWS documents it primarily as helping model deployment and hardware optimization rather than token-by-token response generation. Quantization reduces hardware requirements and can lower cost, but the docs do not present it as the most direct answer to slow sequential decoding. Fast model loading improves how quickly the model loads onto instances, which helps startup and scale-out time, not long response generation after the model is already serving traffic. Therefore, the best AWS-documented answer is B .
NEW QUESTION # 196
A company has multiple models that are hosted on Amazon SageMaker Al. The models need to be re-trained.
The requirements for each model are different, so the company needs to choose different deployment strategies to transfer all requests to a new model.
Select the correct strategy from the following list for each requirement. Select each strategy one time. (Select THREE.)
. Canary traffic shifting
. Linear traffic shifting guardrail
. All at once traffic shifting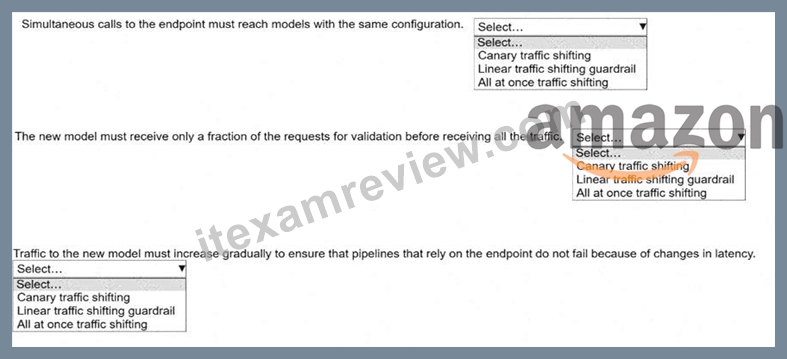
Answer:
Explanation: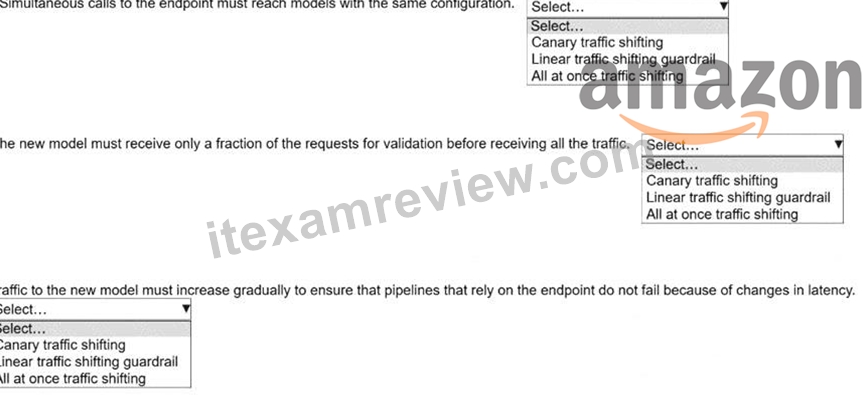
Explanation:
1## Simultaneous calls to the endpoint must reach models with the same configuration Correct strategy: All at once traffic shifting Why:
"All at once" replaces the old model with the new model immediately. After the switch, all concurrent requests hit only the new model configuration, guaranteeing configuration consistency across simultaneous calls.
2## The new model must receive only a fraction of the requests for validation before receiving all the traffic Correct strategy: Canary traffic shifting Why:
Canary deployments route a small percentage of traffic (for example, 5% or 10%) to the new model first. This allows validation of correctness and performance before shifting 100% of traffic.
3## Traffic to the new model must increase gradually to ensure that pipelines that rely on the endpoint do not fail because of changes in latency Correct strategy: Linear traffic shifting guardrail Why:
Linear traffic shifting gradually increases traffic in equal increments over time and includes guardrails (such as CloudWatch alarms) to automatically roll back if latency or errors exceed thresholds.
NEW QUESTION # 197
An ML engineer is analyzing a classification dataset before training a model in Amazon SageMaker AI. The ML engineer suspects that the dataset has a significant imbalance between class labels that could lead to biased model predictions. To confirm class imbalance, the ML engineer needs to select an appropriate pre- training bias metric.
Which metric will meet this requirement?
Answer: A
Explanation:
In Amazon SageMaker AI, identifying bias in machine learning datasets before model training is a critical step to ensure fairness and reliability of predictions. This process is referred to as pre-training bias analysis, and it focuses on understanding whether the training data itself introduces bias-particularly through imbalanced class labels or sensitive attributes.
The Difference in Proportions of Labels (DPL) is a pre-training bias metric specifically designed to measure class imbalance. DPL compares the proportion of a specific label (such as a positive outcome) across different groups or classes within a dataset. If one class or group is overrepresented relative to another, the DPL value will deviate significantly from zero, clearly indicating imbalance. AWS documentation highlights DPL as a key metric used by SageMaker Clarify to detect label imbalance prior to model training.
By contrast, Mean Squared Error (MSE) is a regression evaluation metric used after model training to measure prediction error, not dataset bias. Silhouette score is an unsupervised learning metric used to evaluate clustering quality, making it irrelevant for supervised classification bias detection. Structural Similarity Index Measure (SSIM) is an image-quality metric used in computer vision tasks and has no application in dataset bias analysis.
Using DPL allows ML engineers to proactively detect and address skewed label distributions-such as by re- sampling, re-weighting, or collecting additional data-before training begins. This aligns with AWS best practices for responsible AI and helps reduce the risk of biased predictions that could negatively impact real- world decision-making.
Therefore, Difference in Proportions of Labels (DPL) is the correct and AWS-recommended metric for confirming class imbalance during pre-training bias analysis in Amazon SageMaker AI.
NEW QUESTION # 198
Case study
An ML engineer is developing a fraud detection model on AWS. The training dataset includes transaction logs, customer profiles, and tables from an on-premises MySQL database. The transaction logs and customer profiles are stored in Amazon S3.
The dataset has a class imbalance that affects the learning of the model's algorithm. Additionally, many of the features have interdependencies. The algorithm is not capturing all the desired underlying patterns in the data.
The ML engineer needs to use an Amazon SageMaker built-in algorithm to train the model.
Which algorithm should the ML engineer use to meet this requirement?
Answer: A
Explanation:
Why Linear Learner?
* SageMaker'sLinear Learneralgorithm is well-suited for binary classification problems such as fraud detection. It handles class imbalance effectively by incorporating built-in options forweight balancing across classes.
* Linear Learner can capture patterns in the data while being computationally efficient.
Key Features of Linear Learner:
* Automatically weights minority and majority classes.
* Supports both classification and regression tasks.
* Handles interdependencies among features effectively through gradient optimization.
Steps to Implement:
* Use the SageMaker Python SDK to set up a training job with the Linear Learner algorithm.
* Configure the hyperparameters to enable balanced class weights.
* Train the model with the balanced dataset created using SageMaker Data Wrangler.
NEW QUESTION # 199
......
For candidates who will buy MLA-C01 learning materials online, they may care more about the quality of the exam dumps. We have a professional team to collect the latest information of the MLA-C01 exam dumps, therefore the quality can be guaranteed. Moreover, we have online and offline chat service stuff, who have professional knowledge for MLA-C01 Learning Materials. If you have any questions, you can consult us. We will give you reply as soon as possible. Free demo for MLA-C01 exam dumps will also be offered, and you can have a try before purchasing.
MLA-C01 Online Test: https://www.itexamreview.com/MLA-C01-exam-dumps.html
BONUS!!! Download part of ITexamReview MLA-C01 dumps for free: https://drive.google.com/open?id=1z9OsncOry7z2GsFpZlmvfBy6kYP-GNXa