P.S. Free & New SPS-C01 dumps are available on Google Drive shared by Itcerttest: https://drive.google.com/open?id=1PkoMjV8qsfb_J6LgLHgxjmUONZxnDyXo
Perhaps you are in a bad condition and need help to solve all the troubles. Don’t worry, once you realize economic freedom, nothing can disturb your life. Our SPS-C01 study materials can help you out. Learning is the best way to make money. So you need to learn our SPS-C01 study materials carefully after you have paid for them. As long as you are determined to change your current condition, nothing can stop you. Once you get the SPS-C01 certificate, all things around you will turn positive changes. Never give up yourself. You have the right to own a bright future.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Transformations and DataFrame Operations | 35% | - Complex data pipelines - Window functions - Persisting transformed data - Filtering, Aggregating, and Joining DataFrames - Using built-in functions |
| Topic 2: Performance Optimization and Best Practices | 20% | - Warehouse sizing for Snowpark - Minimizing data transfer - Caching strategies - Vectorized UDFs - Debugging and explain plans - Query pushdown and optimization |
| Topic 3: Snowpark Concepts | 15% | - Stored procedures and conditional logic - Snowpark Sessions and connection management - Snowpark architecture and core concepts - Snowpark DataFrames and query plans - Transformations vs. Actions - Client-side vs. Server-side execution |
| Topic 4: Snowpark API for Python | 30% | - User-Defined Functions (UDFs) and Stored Procedures - DataFrame creation and manipulation - Reading and writing data - Working with Semi-structured data - Establishing connections and session management |
Our SPS-C01 Practice Materials are compiled by first-rank experts and SPS-C01 Study Guide offer whole package of considerate services and accessible content. Furthermore, SPS-C01 Actual Test improves our efficiency in different aspects. Having a good command of professional knowledge will do a great help to your life. With the advent of knowledge times, we all need some professional certificates such as SPS-C01 to prove ourselves in different working or learning condition.
NEW QUESTION # 316
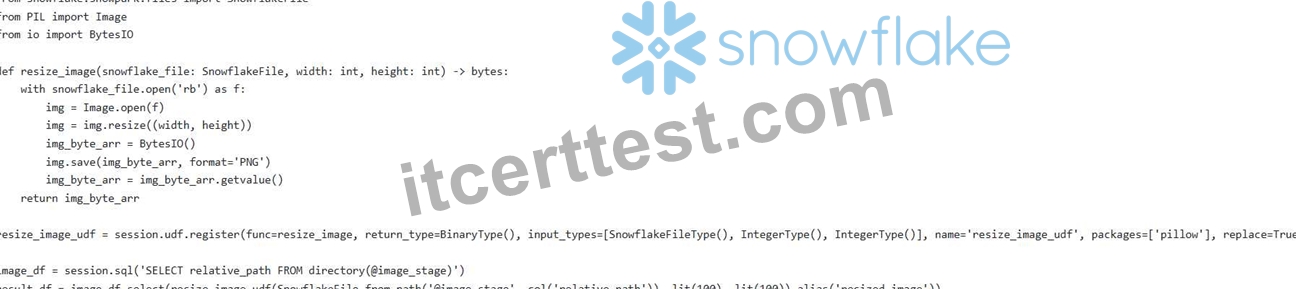
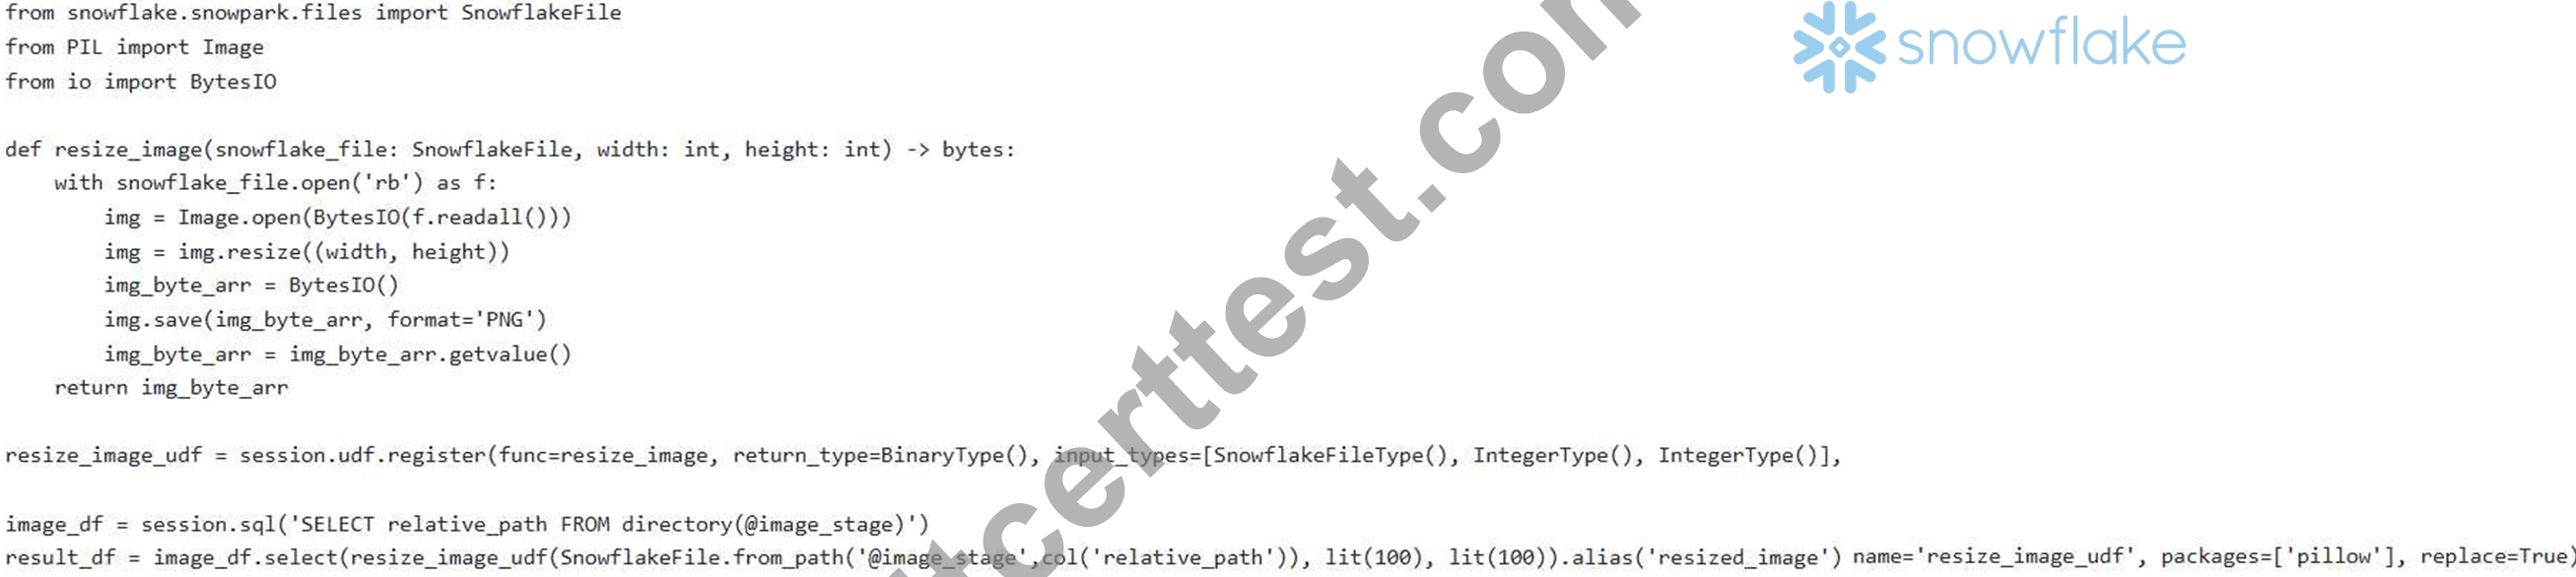
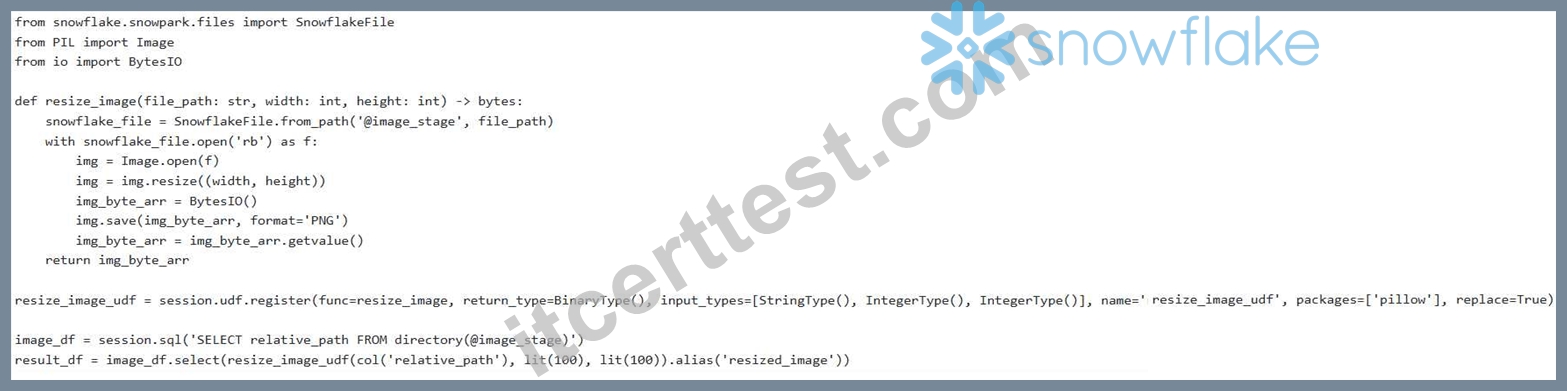
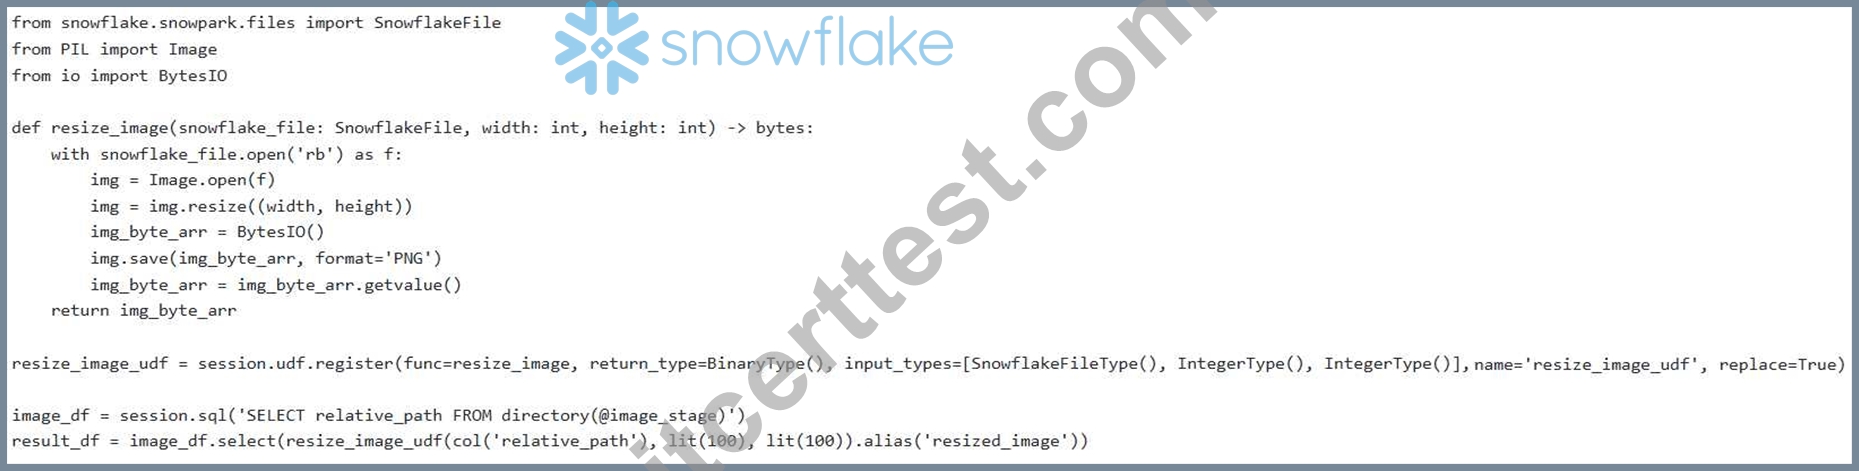
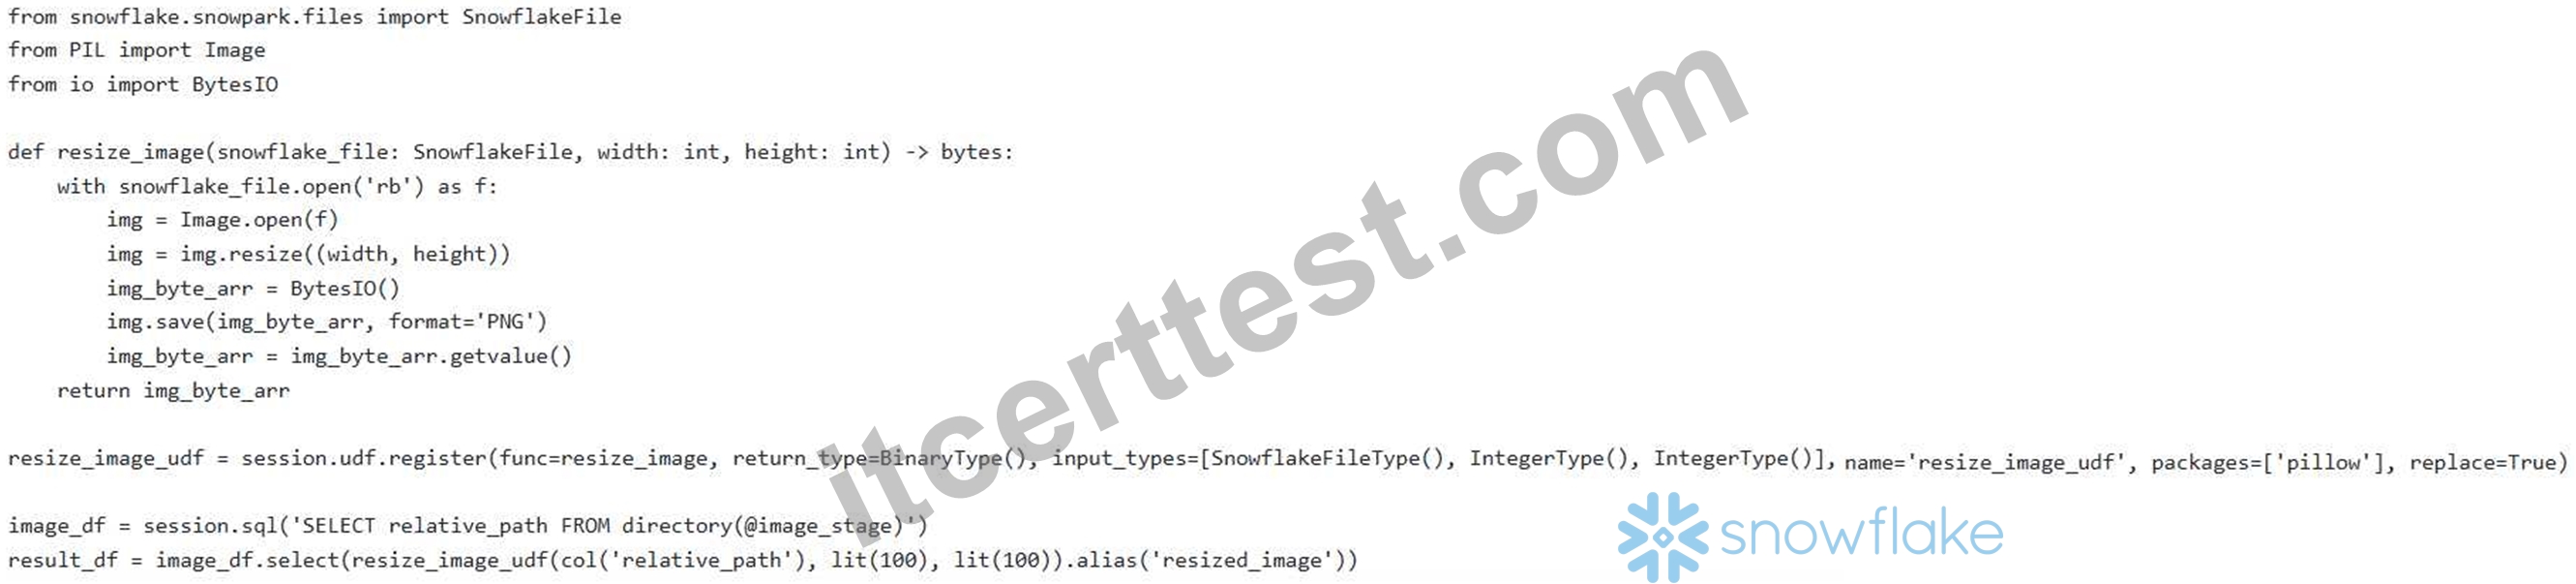
You are working with image files stored in a Snowflake internal stage named 'image_stage'. You need to write a Snowpark Python application to resize these images using a Python library called 'PIG. The resizing logic is encapsulated in a function called resize_image(snowflake_file: SnowflakeFile, width: int, height: int) -> bytes. Which of the following code snippets correctly registers he 'resize image' function as a UDF and applies it to the image files?
Answer: D
Explanation:
Option E correctly implements the image resizing using Snowpark UDF and 'SnowflakeFile' object. - The 'resize_image' function takes the as input and constructs the SnowflakeFile object correctly - 'SnowflakeFile.from_path('@image_stage', file_path)' correctly creates Snowflake file object based on provided file path - The UDF registration specifies the correct input type 'StringType' for file path , BinaryType' for the return and includes the 'pillow' package. - The final select statement calls the UDF correctly with the 'relative_path' column. Option D is incorrect because 'f.readall()' returns bytes, and PIL.lmage.open expects a file-like object or filename, wrapping this within ByteslO is unnecessary. Option B is wrong because the snowflake file object should be created in the python function itself, UDF creation and calling both are wrong Option A and C have registration issue for packages, as it is not provided to function registration.
NEW QUESTION # 317
You have a Snowpark DataFrame named 'orders df with columns 'order id', 'customer id', 'order date', and 'total amount'. You need to create a new DataFrame that contains only the 'customer_id" and the total number of orders placed by each customer. However, you want to perform this aggregation in parallel using a user-defined function (UDF) to improve performance. Which approach is MOST efficient and CORRECT?
Answer: D
Explanation:
The most efficient and correct approach is to use the built-in 'groupBy' and 'count' functions. These functions are optimized for Snowflake's architecture and will generally outperform UDF-based solutions for simple aggregations. Using UDFs for simple tasks introduces overhead and can negate any potential performance benefits. While options A, B and D could achieve the result, they are less efficient. Option E is irrelevant to the problem.
NEW QUESTION # 318
You have a Snowpark DataFrame 'df containing customer data with columns 'customer_id', 'signup_date' (TIMESTAMP NTZ), and 'country'. You need to create a new DataFrame that calculates the number of days since each customer signed up, but only for customers in 'USA' and 'Canada'. Furthermore, you want to filter out records where the signup was more than 365 days ago. Which of the following Snowpark code snippets will achieve this most efficiently?




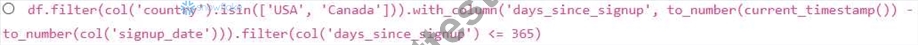
Answer: C
Explanation:
Option E is the most efficient. It first filters the DataFrame by country using 'isin' , which is optimized for multiple values. Then, it calculates 'days_since_signup' using 'datediff and finally filters based on the number of days. Option A is correct but not as efficient as using 'isin-. Option B calculates 'days_since_signup' before filtering, which is less efficient. Option C uses 'to_number' which would result in the difference being represented in milliseconds and would require further conversion. Also using 'to_number' may lead to data loss. Option D has incorrect operator precedence in the 'where' clause, making it functionally wrong.
NEW QUESTION # 319
You are working with a Snowpark DataFrame representing sensor data. The DataFrame contains columns like 'timestamp', 'sensor id' , and 'value'. You need to perform a complex windowing operation to calculate the moving average of the 'value' for each 'sensor id' over a 5-minute window, but only for data points where the 'value' is greater than a threshold. The window should be defined based on the 'timestamp' column. What is the most efficient and correct approach to implement this using Snowpark DataFrames?
Answer: D
Explanation:
The most efficient and correct approach is to use Snowpark's built-in windowing functions. Applying the threshold using 'filter' before the windowing operation reduces the amount of data processed by the window function, improving performance. Using 'Window.partitionBy' and 'Window.orderBy' correctly defines the window based on 'sensor_id' and 'timestamp', respectively. Using 'avg' window function calculates the moving average within the defined window. Options B, C, and D are less efficient because they involve transferring data to the client side (Pandas) or using UDFs, which can introduce overhead. Option E reverses the correct process.
NEW QUESTION # 320
You are tasked with setting up secure authentication for your Snowpark application. You want to use key pair authentication for a service user. Which of the following steps are necessary and in the correct order?
Answer: D
Explanation:
The correct steps for key pair authentication involve generating an RSA key pair, securely storing the private key on the client, providing the path to the private key (and passphrase, if used) in the Snowpark session configuration, and associating the public key with the Snowflake user using the 'ALTER USER command. Storing the private key in the database (option E) is a security risk. Options B and C have incorrect key associations.
NEW QUESTION # 321
......
The SPS-C01 exam questions by experts based on the calendar year of all kinds of exam after analysis, it is concluded that conforms to the exam thesis focus in the development trend, and summarize all kind of difficulties you will face, highlight the user review must master the knowledge content. Our Snowflake Certified SnowPro Specialty - Snowpark study question has high quality. So there is all effective and central practice for you to prepare for your test. With our professional ability, we can accord to the necessary testing points to edit SPS-C01 Exam Questions. It points to the exam heart to solve your difficulty.
SPS-C01 Reliable Exam Registration: https://www.itcerttest.com/SPS-C01_braindumps.html
DOWNLOAD the newest Itcerttest SPS-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1PkoMjV8qsfb_J6LgLHgxjmUONZxnDyXo