Certified-Data-Engineer-Professional資格認定試験、Certified-Data-Engineer-Professionalリンクグローバル

Xhs1991のCertified-Data-Engineer-Professionalこの驚くほど高く受け入れられているCertified-Data-Engineer-Professional試験に適合するには、Databricks のDatabricks Certified Data Engineer Professional学習教材のような上位の実践教材で準備する必要があります。 彼らは時間とお金の面で最良のCertified-Data-Engineer-Professional選択です。 初心者の場合は、練習教材の学習ガイドから始めてください。当社の製品は、テストエンジンの助けを借りて学習問題を修正します。 Databricks Certified Data Engineer ProfessionalのCertified-Data-Engineer-Professionalトレーニング準備のすべてのコンテンツは、素人にだまされているのではなく、このエリアのエリートによって作成されています。 弊社の優秀なヘルパーによる効率に魅了された数万人のCertified-Data-Engineer-Professional受験者を引き付けたリーズナブルな価格に沿ってみましょう。 Databricks Certified Data Engineer Professionalのクイズガイドを使用して、難しい難問を解決してください。
Databricks Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Topic 1: Data Sharing and Federation | - Delta Sharing
- 1. Configure sharing with external platforms using the open sharing protocol
- 2. Share live Lakehouse data with external computing platforms
- 3. Configure Databricks-to-Databricks Sharing
- Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
|
| Topic 2: Cost & Performance Optimisation | - Query Performance
- 1. Identify inefficient joins and excessive data shuffling
- 2. Use Query Profile to identify performance bottlenecks
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Delta Optimization
- 1. Understand deletion vectors and liquid clustering
- 2. Use Change Data Feed to address streaming table limitations and improve latency
- 3. Apply data skipping and file pruning techniques
|
| Topic 3: Data Transformation, Cleansing, and Quality | - Data Quality
- 1. Develop data quarantining processes for invalid data
- 2. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
|
| Topic 4: Data Governance | - Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
- Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
|
| Topic 5: Monitoring and Alerting | - Alerting
- 1. Configure Lakeflow Jobs notifications for job status and performance issues
- 2. Use SQL Alerts for data quality monitoring
- Monitoring
- 1. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 2. Use Query Profiler and Spark UI to monitor workloads
- 3. Use system tables for resource, cost, audit, and workload monitoring
- 4. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
|
| Topic 6: Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Develop User-Defined Functions using Pandas/Python UDFs
- 2. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 3. Manage and troubleshoot third-party library installations and dependencies
- Building and Testing ETL Pipelines
- 1. Compare streaming tables and materialized views
- 2. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 3. Use control flow operators in pipeline components
- 4. Use APPLY CHANGES APIs for change data capture
- 5. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 6. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 7. Develop unit and integration tests for data processing code
- 8. Configure environments, dependencies, memory, and retry behavior
|
| Topic 7: Data Modelling | - Scalable Data Models
- 1. Understand Liquid Clustering versus partitioning and Z-Ordering
- 2. Design and implement scalable data models using Delta Lake
- 3. Optimize data layout using Liquid Clustering
- Dimensional Modelling
- 1. Design dimensional models for analytical workloads
|
| Topic 8: Ensuring Data Security and Compliance | - Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
- Data Security
- 1. Apply anonymization and pseudonymization techniques
- 2. Use ACLs to secure workspace objects and enforce least privilege
- 3. Use row filters and column masks for sensitive data
|
| Topic 9: Debugging and Deploying | - Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs
- 2. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- 3. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- Deploying CI/CD
- 1. Integrate Git-based CI/CD workflows using Databricks Git Folders
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
| Topic 10: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Build append-only pipelines for batch and streaming data using Delta
- 2. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 3. Ingest data from message buses and cloud storage
|
>> Certified-Data-Engineer-Professional資格認定試験 <<
Certified-Data-Engineer-Professionalリンクグローバル、Certified-Data-Engineer-Professional受験記
市場では、顧客の観点から判断するための未定の品質を備えたいくつかの実習用教材が市場に登場しています。 間違ったCertified-Data-Engineer-Professional練習教材を選択した場合、重大な間違いになります。 彼らの行動は厳密に倫理的ではなく、あなたにとって無責任ではありません。 進捗状況を確認し、Certified-Data-Engineer-Professionalトレーニング資料の証明書を取得することは、当然のことながら、最新かつ最も正確な知識を備えた最も専門的な専門家によるものです。 Databricks Certified Data Engineer Professional試験準備は市場の大部分を占めています。 次のようにいくつかの機能を知ってください。
Databricks Certified Data Engineer Professional 認定 Certified-Data-Engineer-Professional 試験問題 (Q122-Q127):
質問 # 122
An upstream source writes Parquet data as hourly batches to directories named with the current date. A nightly batch job runs the following code to ingest all data from the previous day as indicated by the date variable:
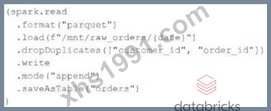
Assume that the fields customer_id and order_id serve as a composite key to uniquely identify each order.
If the upstream system is known to occasionally produce duplicate entries for a single order hours apart, which statement is correct?
- A. Each write to the orders table will only contain unique records, but newly written records may have duplicates already present in the target table.
- B. Each write to the orders table will only contain unique records, and only those records without duplicates in the target table will be written.
- C. Each write to the orders table will run deduplication over the union of new and existing records, ensuring no duplicate records are present.
- D. Each write to the orders table will only contain unique records; if existing records with the same key are present in the target table, these records will be overwritten.
- E. Each write to the orders table will only contain unique records; if existing records with the same key are present in the target table, the operation will tail.
正解:A
解説:
This is the correct answer because the code uses the dropDuplicates method to remove any duplicate records within each batch of data before writing to the orders table. However, this method does not check for duplicates across different batches or in the target table, so it is possible that newly written records may have duplicates already present in the target table. To avoid this, a better approach would be to use Delta Lake and perform an upsert operation using mergeInto.
質問 # 123
Incorporating unit tests into a PySpark application requires upfront attention to the design of your jobs, or a potentially significant refactoring of existing code.
Which statement describes a main benefit that offset this additional effort?
- A. Validates a complete use case of your application
- B. Ensures that all steps interact correctly to achieve the desired end result
- C. Improves the quality of your data
- D. Yields faster deployment and execution times
- E. Troubleshooting is easier since all steps are isolated and tested individually
正解:E
質問 # 124
A data engineer wants to create a cluster using the Databricks CLI for a big ETL pipeline. The cluster should have five workers, one driver of type i3.xlarge, and should use the '14.3.x- scala2.12' runtime. Which command should the data engineer use?
- A. databricks compute create 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster- name Data Engineer_cluster
- B. databricks compute add 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster-name Data Engineer_cluster
- C. databricks clusters add 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster-name Data Engineer_cluster
- D. databricks clusters create 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster- name DataEngineer_cluster
正解:D
解説:
The correct Databricks CLI command to create a new cluster is databricks clusters create. You specify the runtime with --spark-version (here '14.3.x-scala2.12'), the number of workers with -- num-workers, the node type with --node-type-id, and the cluster name with --cluster-name. This command properly initializes the cluster with the desired configuration.
質問 # 125
A data architect is designing a Databricks solution to efficiently process data for different business requirements. In which scenario should a data engineer use a materialized view compared to a streaming table?
- A. Ingesting data from Apache Kafka topics with sub-second processing requirements for immediate alerting.
- B. Precomputing complex aggregations and joins from multiple large tables to accelerate BI dashboard performance.
- C. Processing high-volume, continuous clickstream data from a website to monitor user behavior in real-time.
- D. Implementing a CDC (Change Data Capture) pipeline that needs to detect and respond to database changes within seconds.
正解:B
解説:
Materialized views in Databricks are optimized for precomputing and caching results of complex SQL queries, joins, and aggregations. They store query outputs physically and automatically refresh on a schedule or incremental change basis, drastically improving BI dashboard performance and reducing compute costs.
Conversely, streaming tables are designed for real-time data ingestion and processing, enabling event-driven analytics and low-latency use cases.
Databricks documentation explicitly recommends materialized views for analytical workloads with periodic updates and streaming tables for continuously updating sources. Therefore, the correct choice is C, where complex aggregations from large tables benefit most from materialized precomputation for fast reporting.
質問 # 126
A data engineer is evaluating tools to build a production-grade data pipeline. The team must process change data from cloud object storage, filter out or isolate invalid records, and ensure the timely delivery of clean data to downstream consumers. The team is small, under tight deadlines, and wants to minimize operational overhead while keeping pipelines auditable and maintainable.
Which approach should the data engineer implement?
- A. Use a hybrid approach: Ingest with Auto Loader into Bronze tables, then process using SQL queries in Databricks Workflows to generate cleaned Silver and Gold tables on a schedule.
- B. Implement ingestion using Auto Loader with Structured Streaming, and manage invalid data handling and table updates using checkpointing and merge logic.
- C. Ingest data directly into Delta tables via Spark jobs, apply data quality filters using UDFs, and use LDP for creating Materialized Views.
- D. Use LDP to build declarative pipelines with Streaming Tables and Materialized Views, leveraging built-in support for data expectations and incremental processing.
正解:D
解説:
LDP provides a declarative framework for building production-grade pipelines with minimal operational overhead. Streaming Tables and Materialized Views handle incremental processing automatically, while built-in data expectations allow invalid records to be filtered or isolated in a consistent and auditable way. This approach is well suited for small teams under tight deadlines, as it simplifies maintenance, improves reliability, and ensures timely delivery of clean data to downstream consumers.
質問 # 127
......
当社Xhs1991の専門家は、Certified-Data-Engineer-Professionalテストクイズが毎日更新されるかどうかを確認しています。 Certified-Data-Engineer-Professional試験トレントは、更新システムによってデジタル化された世界に対応できることを保証できます。私たちは、お客様が教材に関する最新情報を入手できるように最善を尽くします。当社のCertified-Data-Engineer-Professional試験トレントを購入する意思がある場合は、更新システムを楽しむ権利があることは間違いありません。 Certified-Data-Engineer-Professional試験のダンプが更新されると、Certified-Data-Engineer-Professionalテストクイズの最新情報がすぐに届きます。すぐにCertified-Data-Engineer-Professional試験準備をすぐに購入しましょう!
Certified-Data-Engineer-Professionalリンクグローバル: https://www.xhs1991.com/Certified-Data-Engineer-Professional.html
- Certified-Data-Engineer-Professional資格準備 🎈 Certified-Data-Engineer-Professional認定資格試験 🛕 Certified-Data-Engineer-Professional全真模擬試験 🎱 今すぐ⏩ www.passtest.jp ⏪で➽ Certified-Data-Engineer-Professional 🢪を検索し、無料でダウンロードしてくださいCertified-Data-Engineer-Professional模擬問題集
- Certified-Data-Engineer-Professional試験解説問題 🍹 Certified-Data-Engineer-Professional模擬問題集 🧽 Certified-Data-Engineer-Professional復習範囲 📡 検索するだけで➽ www.goshiken.com 🢪から⏩ Certified-Data-Engineer-Professional ⏪を無料でダウンロードCertified-Data-Engineer-Professional復習範囲
- Databricks Certified-Data-Engineer-Professional資格認定試験: Databricks Certified Data Engineer Professional - www.passtest.jp パスやすい 🚾 ▷ www.passtest.jp ◁の無料ダウンロード⇛ Certified-Data-Engineer-Professional ⇚ページが開きますCertified-Data-Engineer-Professional日本語版参考書
- 迷わずにこの一冊 Certified-Data-Engineer-Professional 問題集 😤 ▷ www.goshiken.com ◁を開き、( Certified-Data-Engineer-Professional )を入力して、無料でダウンロードしてくださいCertified-Data-Engineer-Professional復習範囲
- Certified-Data-Engineer-Professional資格模擬 😯 Certified-Data-Engineer-Professional試験解説 ⛵ Certified-Data-Engineer-Professional日本語版参考書 🍯 ☀ www.jpshiken.com ️☀️は、▛ Certified-Data-Engineer-Professional ▟を無料でダウンロードするのに最適なサイトですCertified-Data-Engineer-Professional資格練習
- Certified-Data-Engineer-Professional模擬問題集 🈵 Certified-Data-Engineer-Professional対応受験 🥚 Certified-Data-Engineer-Professional資格模擬 🕞 URL ( www.goshiken.com )をコピーして開き、✔ Certified-Data-Engineer-Professional ️✔️を検索して無料でダウンロードしてくださいCertified-Data-Engineer-Professional認定資格試験
- Databricks Certified-Data-Engineer-Professional Exam | Certified-Data-Engineer-Professional資格認定試験 - 試す Certified-Data-Engineer-Professionalリンクグローバル 無料で簡単に購入 🎧 ➡ www.it-passports.com ️⬅️から簡単に{ Certified-Data-Engineer-Professional }を無料でダウンロードできますCertified-Data-Engineer-Professional無料模擬試験
- Databricks Certified-Data-Engineer-Professional Exam | Certified-Data-Engineer-Professional資格認定試験 - オフィシャルパス認証 Certified-Data-Engineer-Professionalリンクグローバル ⏏ ( www.goshiken.com )に移動し、✔ Certified-Data-Engineer-Professional ️✔️を検索して無料でダウンロードしてくださいCertified-Data-Engineer-Professional対応受験
- Databricks Certified-Data-Engineer-Professional Exam | Certified-Data-Engineer-Professional資格認定試験 - オフィシャルパス認証 Certified-Data-Engineer-Professionalリンクグローバル ↖ ➥ www.mogiexam.com 🡄を入力して➡ Certified-Data-Engineer-Professional ️⬅️を検索し、無料でダウンロードしてくださいCertified-Data-Engineer-Professional復習範囲
- Certified-Data-Engineer-Professional認定資格試験 ↘ Certified-Data-Engineer-Professional資格練習 🍌 Certified-Data-Engineer-Professional試験解説 📻 今すぐ▛ www.goshiken.com ▟を開き、{ Certified-Data-Engineer-Professional }を検索して無料でダウンロードしてくださいCertified-Data-Engineer-Professional資格参考書
- Certified-Data-Engineer-Professional試験解説問題 ♻ Certified-Data-Engineer-Professional関連受験参考書 🤪 Certified-Data-Engineer-Professional関連受験参考書 🧓 《 www.topexam.jp 》にて限定無料の{ Certified-Data-Engineer-Professional }問題集をダウンロードせよCertified-Data-Engineer-Professional日本語版参考書
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes