2026 Latest Real4Prep Mule-Arch-201 PDF Dumps and Mule-Arch-201 Exam Engine Free Share: https://drive.google.com/open?id=1HBgtuMLcbX0CAWFnB_WDb3mC0Gc9pbNt
Why do we need so many certifications? One thing has to admit, more and more certifications you own, it may bring you more opportunities to obtain a better job, earn more salary. This is the reason why we need to recognize the importance of getting the test Mule-Arch-201 certification. Therefore, our Mule-Arch-201 Study Tool can help users pass the qualifying examinations that they are required to participate in faster and more efficiently as our Mule-Arch-201 exam questions have a pass rate of more than 98%. Just buy our Mule-Arch-201 practice guide, then you will pass your Mule-Arch-201 exam.
| Section | Weight | Objectives |
|---|---|---|
| Architecting and Deploying API Implementations | 11% | - Networking and security configuration - High availability and fault tolerance - Runtime architecture and deployment options - CI/CD and DevOps integration |
| Applying Integration Patterns | 11% | - Event-driven and synchronous integration - Common integration patterns and use cases - Scalability and performance patterns - Error handling and reliability patterns |
| Meeting API Quality Goals | 8% | - Reliability and availability targets - Security and compliance standards - Performance and latency requirements - Maintainability and testability |
| Managing APIs | 12% | - API lifecycle management - API policies and security enforcement - Versioning and deprecation strategies - Rate limiting and throttling |
| Explaining Application Network Basics | 11% | - Benefits of modern API design - Core concepts of application networks - API-led connectivity principles |
| Monitoring and Analyzing Application Networks | 8% | - Logging and alerting configuration - Monitoring strategies and tools - Analytics and insight generation - Operational visibility and optimization |
| Establishing Organizational and Platform Foundations | 17% | - Anypoint Platform architecture and components - Center for Enablement (C4E) operating model - Governance and organizational structure - Platform strategy and roadmap definition |
| Deploying API Implementations to CloudHub | 11% | - Deployment optimization and scaling - CloudHub architecture and capabilities - Worker sizing and resource planning - VPC and private space configuration |
| Designing and Sharing APIs | 11% | - API specification and documentation - Asset sharing and reuse via Anypoint Exchange - API layering: Experience, Process, System APIs - API design standards and best practices |
>> Mule-Arch-201 Clearer Explanation <<
Our Mule-Arch-201 preparation exam will be very useful for you if you are going to take the exam. So if you buy our Mule-Arch-201 guide quiz, it will help you pass your exam and get the certification in a short time, and you will find that our Mule-Arch-201 study materials are good value for money. Besides, you can enjoy the best after-sales service. We believe that our Mule-Arch-201 Learning Engine will meet your all needs. Please give us a chance to service you; you will be satisfied with our training prep.
NEW QUESTION # 125
Which statement is true about Spike Control policy and Rate Limiting policy?
Answer: D
Explanation:
Understanding Spike Control and Rate Limiting Policies:
Spike Control Policy: Limits the number of requests processed by the API in a short time to handle sudden bursts of traffic. It does not queue requests but rejects any request that exceeds the allowed burst rate.
Rate Limiting Policy: Sets a limit on the number of requests that an API can handle within a given timeframe. Once the limit is reached, additional requests are rejected.
Evaluating the Options:
Option A: Incorrect. In both Spike Control and Rate Limiting policies, requests are rejected once the limit is reached. Spike Control does not queue requests; it only controls the burst rate by rejecting excessive requests.
Option B (Correct Answer): In a clustered environment, each node independently enforces the Rate Limiting and Spike Control policies, meaning that the limits apply to each node separately. This ensures that each node can control its own resource usage independently within the cluster.
Option C: This is partially correct, as Rate Limiting is often used to protect Experience APIs, but Spike Control could also be useful in limiting resource consumption under high burst conditions.
Option D: Incorrect. Although a contract is required to enforce client-specific policies, Rate Limiting and Spike Control do not require a contract to function for general traffic control.
Conclusion:
Option B is the correct answer because, in a clustered environment, Rate Limiting and Spike Control policies apply separately to each node, helping each instance to manage its own load.
For more information, refer to MuleSoft's documentation on applying Rate Limiting and Spike Control policies in a clustered environment.
NEW QUESTION # 126
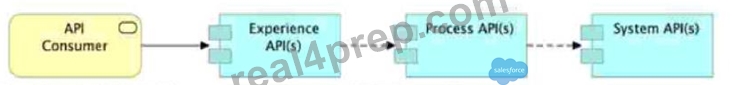
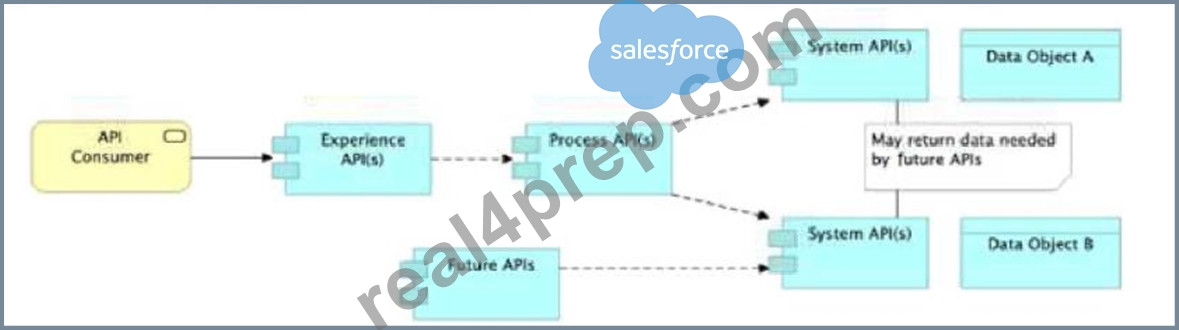
Refer to the exhibits.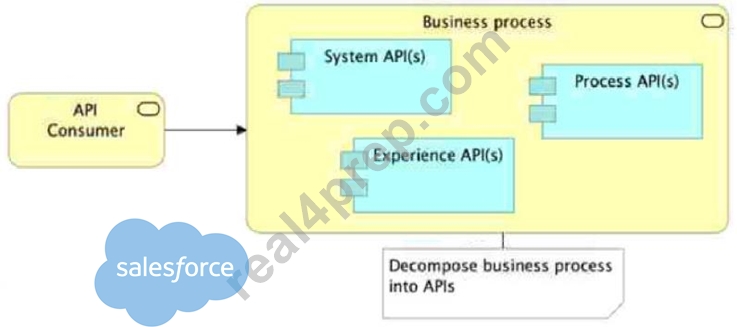
Which architectural constraint is compatible with the API-led connectivity architectural style?
Answer: C
Explanation:
Understanding API-led Connectivity Layers:
In MuleSoft's API-led connectivity approach, APIs are categorized into three layers:
Experience Layer: This layer is responsible for providing data to the end-user applications and is often customized to meet the needs of different user interfaces.
Process Layer: This layer is used to orchestrate and combine data from multiple System APIs. It acts as a mediator and business logic layer without directly interacting with the backend systems.
System Layer: This layer provides direct access to the backend systems (e.g., databases, ERPs) and is usually focused on exposing atomic data operations.
Evaluating the Architectural Constraints:
Option A: Always using a strict tiered approach by creating exactly one API per layer is not necessarily an architectural constraint of API-led connectivity. While a layered approach is recommended, it is common to have multiple APIs in each layer as needed for different functionalities.
Option B (Correct Answer): In API-led connectivity, Process APIs are generally responsible for orchestrating calls to System APIs and should not call other Process APIs. This maintains a clear separation of concerns, ensuring that Process APIs aggregate data from System APIs only and provide it to Experience APIs.
Option C: System APIs are generally designed to provide only the necessary data to meet current business requirements. Allowing them to return extra data that is not needed by Process or Experience APIs is not a best practice, as it can lead to inefficiencies.
Option D: Customizations specific to end-user applications are typically handled at the Experience Layer rather than the Process Layer, as the Experience Layer is intended to tailor the data to fit the needs of each specific client or front-end application.
Conclusion:
Option B is the correct answer as it aligns with the API-led connectivity principles. In this architectural style, Process APIs should orchestrate System APIs but should avoid interacting with other Process APIs to keep a clear separation of responsibilities across the layers.
For additional details, refer to MuleSoft documentation on API-led connectivity best practices, particularly around the roles of each layer in API orchestration and data handling.
NEW QUESTION # 127
An Order API must be designed that contains significant amounts of integration logic and involves the invocation of the Product API.
The power relationship between Order API and Product API is one of "Customer/Supplier", because the Product API is used heavily throughout the organization and is developed by a dedicated development team located in the office of the CTO.
What strategy should be used to deal with the API data model of the Product API within the Order API?
Answer: D
Explanation:
Correct Answe r: Convince the development team of the product API to adopt the API data model of the Order API such that integration logic of the Order API can work with one consistent internal data model
*****************************************
Key details to note from the given scenario:
>> Power relationship between Order API and Product API is customer/supplier So, as per below rules of "Power Relationships", the caller (in this case Order API) would request for features to the called (Product API team) and the Product API team would need to accomodate those requests.
NEW QUESTION # 128
What Mule application deployment scenario requires using Anypoint Platform Private Cloud Edition or Anypoint Platform for Pivotal Cloud Foundry?
Answer: A
Explanation:
Correct Answe r: When regulatory requirements mandate on-premises processing of EVERY data item, including meta-data.
*****************************************
We need NOT require to use Anypoint Platform PCE or PCF for the below. So these options are OUT.
>> We can make ALL applications highly available across multiple data centers using CloudHub too.
>> We can use Anypoint VPN and tunneling from CloudHub to connect to ALL backend systems in the application network that are deployed in the organization's intranet.
>> We can use Anypoint VPC and Firewall Rules to make ALL APIs private and NOT exposed to the public cloud.
Only valid reason in the given options that requires to use Anypoint Platform PCE/ PCF is - When regulatory requirements mandate on-premises processing of EVERY data item, including meta-data.
NEW QUESTION # 129
A retail company with thousands of stores has an API to receive data about purchases and insert it into a single database. Each individual store sends a batch of purchase data to the API about every 30 minutes. The API implementation uses a database bulk insert command to submit all the purchase data to a database using a custom JDBC driver provided by a data analytics solution provider. The API implementation is deployed to a single CloudHub worker. The JDBC driver processes the data into a set of several temporary disk files on the CloudHub worker, and then the data is sent to an analytics engine using a proprietary protocol. This process usually takes less than a few minutes. Sometimes a request fails. In this case, the logs show a message from the JDBC driver indicating an out-of-file-space message. When the request is resubmitted, it is successful. What is the best way to try to resolve this throughput issue?
Answer: C
Explanation:
Correct Answe r: Increase the size of the CloudHub worker(s)
*****************************************
The key details that we can take out from the given scenario are:
>> API implementation uses a database bulk insert command to submit all the purchase data to a database
>> JDBC driver processes the data into a set of several temporary disk files on the CloudHub worker
>> Sometimes a request fails and the logs show a message indicating an out-of-file-space message Based on above details:
>> Both auto-scaling options does NOT help because we cannot set auto-scaling rules based on error messages. Auto-scaling rules are kicked-off based on CPU/Memory usages and not due to some given error or disk space issues.
>> Increasing the number of CloudHub workers also does NOT help here because the reason for the failure is not due to performance aspects w.r.t CPU or Memory. It is due to disk-space.
>> Moreover, the API is doing bulk insert to submit the received batch data. Which means, all data is handled by ONE worker only at a time. So, the disk space issue should be tackled on "per worker" basis. Having multiple workers does not help as the batch may still fail on any worker when disk is out of space on that particular worker.
Therefore, the right way to deal this issue and resolve this is to increase the vCore size of the worker so that a new worker with more disk space will be provisioned.
NEW QUESTION # 130
......
Real4Prep try hard to makes Mule-Arch-201 exam preparation easy with its several quality features. Our Mule-Arch-201 exam dumps come with 100% refund assurance. We are dedicated to your accomplishment, hence pledges you victory in Mule-Arch-201 exam in a single attempt. If for any reason, a user fails in Mule-Arch-201 exam then he will be refunded the money after the process. Also, we offer 1 year free updates to our Mule-Arch-201 Exam esteemed users; and these updates will be entitled to your account right from the date of purchase. Also the 24/7 Customer support is given to users, who can email us if they find any haziness in the Mule-Arch-201 exam dumps, our team will merely answer to your all Mule-Arch-201 exam product related queries.
Mule-Arch-201 Certification Exam Infor: https://www.real4prep.com/Mule-Arch-201-exam.html
BTW, DOWNLOAD part of Real4Prep Mule-Arch-201 dumps from Cloud Storage: https://drive.google.com/open?id=1HBgtuMLcbX0CAWFnB_WDb3mC0Gc9pbNt