P.S. Free & New Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by VCE4Plus: https://drive.google.com/open?id=1TQlsfLYRKAz_5ugzyfbb7A4OlKNvdfdi
The passing rate is the best test for quality of our Databricks-Generative-AI-Engineer-Associate study materials. And we can be very proud to tell you that the passing rate of our Databricks-Generative-AI-Engineer-Associate Exam Questions is almost 100%. That is to say, as long as you choose our study materials and carefully review according to its content, passing the Databricks-Generative-AI-Engineer-Associate Exam is a piece of cake. We're definitely not exaggerating. If you don't believe, you can give it a try.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Generative AI Engineer Associate |
| Exam Number: | Generative AI Engineer Associate |
| Exam Format: | Multiple Select, Multiple Choice |
| Certificate Validity Period: | 2 years |
| Available Languages: | Japanese, Portuguese (Brazil), English, Korean |
| Exam Duration: | 90 minutes |
| Real Exam Qty: | 45 |
| Passing Score: | Scaled Score (approx. 70%) |
| Related Certifications: | Databricks Certified Machine Learning Associate Databricks Certified Data Engineer Associate |
| Exam Price: | $200 USD |
| Sample Questions: | Databricks Databricks-Generative-AI-Engineer-Associate Sample Questions |
| Exam Way: | Online (Proctored) or Test Center |
| Pre Condition: | None (Recommended: 6+ months hands-on experience) |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/genai-engineer-associate |
>> Databricks-Generative-AI-Engineer-Associate Actual Exam <<
We also fully consider the characteristics of the user on studying the Databricks-Generative-AI-Engineer-Associate exam questions. For example, many people who choose to obtain a Databricks-Generative-AI-Engineer-Associate certificate don't have a lot of time to prepare for the exam. Based on this point, our team of experts really took a lot of thought in the layout of the content. The contents of Databricks-Generative-AI-Engineer-Associate Exam Materials are carefully selected by experts. We hope you can get the most effective knowledge in the shortest possible time.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
NEW QUESTION # 67
A Generative AI Engineer is using LangGraph to define multiple tools in a single agentic application. They want to enable the main orchestrator LLM to decide on its own which tools are most appropriate to call for a given prompt. To do this, they must determine the general flow of the code. Which sequence will do this?
Answer: B
Explanation:
In modern agentic frameworks like LangGraph or LangChain, the standard workflow for creating an autonomous tool-calling agent follows a specific sequence. First, tools must be defined (often as Python functions with clear docstrings, which the LLM uses to understand the tool's purpose). Second, the agent logic is defined, which specifies how the LLM should think. Third, the agent is initialized using a logic pattern like ReAct (Reason + Act). The ReAct framework is essential here because it enables the "orchestrator" loop: the LLM receives a prompt, generates a "Thought" about which tool to use, generates an "Action" to call that tool, receives an "Observation" (the tool's output), and repeats until it can provide a final answer. Loading tools into "separate agents" (C) or defining tools "inside" agents (D) are non-standard patterns that add unnecessary complexity and do not align with the centralized orchestration model required for LangGraph.
NEW QUESTION # 68
A Generative AI Engineer is building an LLM to generate article summaries in the form of a type of poem, such as a haiku, given the article content. However, the initial output from the LLM does not match the desired tone or style.
Which approach will NOT improve the LLM's response to achieve the desired response?
Answer: A
Explanation:
The task at hand is to improve the LLM's ability to generate poem-like article summaries with the desired tone and style. Using aneutralizerto normalize the tone and style of the underlying documents (option B) will not help improve the LLM's ability to generate the desired poetic style. Here's why:
* Neutralizing Underlying Documents:A neutralizer aims to reduce or standardize the tone of input data. However, this contradicts the goal, which is to generate text with aspecific tone and style(like haikus). Neutralizing the source documents will strip away the richness of the content, making it harder for the LLM to generate creative, stylistic outputs like poems.
* Why Other Options Improve Results:
* A (Explicit Instructions in the Prompt): Directly instructing the LLM to generate text in a specific tone and style helps align the output with the desired format (e.g., haikus). This is a common and effective technique in prompt engineering.
* C (Few-shot Examples): Providing examples of the desired output format helps the LLM understand the expected tone and structure, making it easier to generate similar outputs.
* D (Fine-tuning the LLM): Fine-tuning the model on a dataset that contains examples of the desired tone and style is a powerful way to improve the model's ability to generate outputs that match the target format.
Therefore, using a neutralizer (option B) isnotan effective method for achieving the goal of generating stylized poetic summaries.
NEW QUESTION # 69
When developing an LLM application, it's crucial to ensure that the data used for training the model complies with licensing requirements to avoid legal risks.
Which action is NOT appropriate to avoid legal risks?
Answer: D
Explanation:
* Problem Context : When using data to train a model, it's essential to ensure compliance with licensing to avoid legal risks. Legal issues can arise from using data without permission, especially when it comes from third-party sources.
* Explanation of Options :
* Option A : Reaching out to data curators before using the data is an appropriate action. This allows you to ensure you have permission or understand the licensing terms before starting to use the data in your model.
* Option B : Using original data that you personally created is always a safe option. Since you have full ownership over the data, there are no legal risks, as you control the licensing.
* Option C : Using data that is explicitly labeled with an open license and adhering to the license terms is a correct and recommended approach. This ensures compliance with legal requirements.
* Option D : Reaching out to the data curators after you have already started using the trained model is not appropriate . If you've already used the data without understanding its licensing terms, you may have already violated the terms of use, which could lead to legal complications.
It's essential to clarify the licensing terms before using the data, not after.
Thus, Option D is not appropriate because it could expose you to legal risks by using the data without first obtaining the proper licensing permissions.
NEW QUESTION # 70
A Generative Al Engineer is responsible for developing a chatbot to enable their company's internal HelpDesk Call Center team to more quickly find related tickets and provide resolution. While creating the GenAI application work breakdown tasks for this project, they realize they need to start planning which data sources (either Unity Catalog volume or Delta table) they could choose for this application. They have collected several candidate data sources for consideration:
call_rep_history: a Delta table with primary keys representative_id, call_id. This table is maintained to calculate representatives' call resolution from fields call_duration and call start_time.
transcript Volume: a Unity Catalog Volume of all recordings as a *.wav files, but also a text transcript as *.txt files.
call_cust_history: a Delta table with primary keys customer_id, cal1_id. This table is maintained to calculate how much internal customers use the HelpDesk to make sure that the charge back model is consistent with actual service use.
call_detail: a Delta table that includes a snapshot of all call details updated hourly. It includes root_cause and resolution fields, but those fields may be empty for calls that are still active.
maintenance_schedule - a Delta table that includes a listing of both HelpDesk application outages as well as planned upcoming maintenance downtimes.
They need sources that could add context to best identify ticket root cause and resolution.
Which TWO sources do that? (Choose two.)
Answer: D,E
Explanation:
In the context of developing a chatbot for a company's internal HelpDesk Call Center, the key is to select data sources that provide the most contextual and detailed information about the issues being addressed. This includes identifying the root cause and suggesting resolutions. The two most appropriate sources from the list are:
* Call Detail (Option D):
* Contents: This Delta table includes a snapshot of all call details updated hourly, featuring essential fields like root_cause and resolution.
* Relevance: The inclusion of root_cause and resolution fields makes this source particularly valuable, as it directly contains the information necessary to understand and resolve the issues discussed in the calls. Even if some records are incomplete, the data provided is crucial for a chatbot aimed at speeding up resolution identification.
* Transcript Volume (Option E):
* Contents: This Unity Catalog Volume contains recordings in .wav format and text transcripts in .txt files.
* Relevance: The text transcripts of call recordings can provide in-depth context that the chatbot can analyze to understand the nuances of each issue. The chatbot can use natural language processing techniques to extract themes, identify problems, and suggest resolutions based on previous similar interactions documented in the transcripts.
Why Other Options Are Less Suitable:
* A (Call Cust History): While it provides insights into customer interactions with the HelpDesk, it focuses more on the usage metrics rather than the content of the calls or the issues discussed.
* B (Maintenance Schedule): This data is useful for understanding when services may not be available but does not contribute directly to resolving user issues or identifying root causes.
* C (Call Rep History): Though it offers data on call durations and start times, which could help in assessing performance, it lacks direct information on the issues being resolved.
Therefore, Call Detail and Transcript Volume are the most relevant data sources for a chatbot designed to assist with identifying and resolving issues in a HelpDesk Call Center setting, as they provide direct and contextual information related to customer issues.
NEW QUESTION # 71
A company has a typical RAG-enabled, customer-facing chatbot on its website.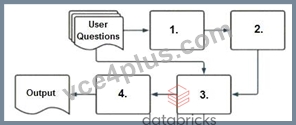
Select the correct sequence of components a user ' s questions will go through before the final output is returned. Use the diagram above for reference.
Answer: C
Explanation:
To understand how a typical RAG-enabled customer-facing chatbot processes a user ' s question, let's go through the correct sequence as depicted in the diagram and explained in option A:
* Embedding Model (1) : The first step involves the user ' s question being processed through an embedding model. This model converts the text into a vector format that numerically represents the text. This step is essential for allowing the subsequent vector search to operate effectively.
* Vector Search (2) : The vectors generated by the embedding model are then used in a vector search mechanism. This search identifies the most relevant documents or previously answered questions that are stored in a vector format in a database.
* Context-Augmented Prompt (3) : The information retrieved from the vector search is used to create a context-augmented prompt. This step involves enhancing the basic user query with additional relevant information gathered to ensure the generated response is as accurate and informative as possible.
* Response-Generating LLM (4) : Finally, the context-augmented prompt is fed into a response- generating large language model (LLM). This LLM uses the prompt to generate a coherent and contextually appropriate answer, which is then delivered as the final output to the user.
Why Other Options Are Less Suitable :
* B, C, D : These options suggest incorrect sequences that do not align with how a RAG system typically processes queries. They misplace the role of embedding models, vector search, and response generation in an order that would not facilitate effective information retrieval and response generation.
Thus, the correct sequence is embedding model, vector search, context-augmented prompt, response- generating LLM , which is option A.
NEW QUESTION # 72
......
Actual Databricks-Generative-AI-Engineer-Associate Test: https://www.vce4plus.com/Databricks/Databricks-Generative-AI-Engineer-Associate-valid-vce-dumps.html
P.S. Free 2026 Databricks Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by VCE4Plus: https://drive.google.com/open?id=1TQlsfLYRKAz_5ugzyfbb7A4OlKNvdfdi