BONUS!!! Download part of Prep4sureGuide DP-750 dumps for free: https://drive.google.com/open?id=1sinC4KecpGKUzResUr0BN6N6hlqBj8n8
We have professional technicians examine the website every day, and if you purchase Implementing Data Engineering Solutions Using Azure Databricks DP-750 Learning Materials from us, we can offer you a clean and safe online shopping environment, and if you indeed meet any questions in the process of buying, you can contact us, our technicians will solve the problem for you.
| Section | Weight | Objectives |
|---|---|---|
| Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
| Prepare and process data | 30-35% | - Data quality and validation
|
| Deploy and manage data pipelines and workloads | 30-35% | - Pipeline design and orchestration
|
| Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
>> DP-750 Valid Exam Duration <<
Would you like to pass Microsoft DP-750 test and to get DP-750 certificate? Prep4sureGuide can guarantee your success. When you are preparing for DP-750 exam, it is necessary to learn test related knowledge. What's more important, you must choose the most effective exam materials that suit you. Prep4sureGuide Microsoft DP-750 Questions and answers are the best study method for you. The high quality exam dumps can produce a wonderful effect. If you fear that you cannot pass DP-750 test, please click Prep4sureGuide.com to know more details.
NEW QUESTION # 75
You need to deploy Databricks Asset Bundles to a development environment. The solution must support automated and repeatable deployments across environments.
What should you use?
Answer: C
Explanation:
The correct answer is C - the Databricks CLI.
Databricks Asset Bundles are deployed using the Databricks CLI (v0.205+) with the commands databricks bundle validate, databricks bundle deploy, and databricks bundle run. The CLI reads the databricks.yml file, resolves the target environment settings, and creates or updates all declared resources (jobs, pipelines, apps) in the workspace. This is the documented, supported deployment mechanism for DABs and integrates naturally into CI/CD pipelines.
Option A (Azure Developer CLI / azd) is a general Azure IaC tool with no native understanding of Databricks bundles. Option B (Git folders) syncs notebook and file content from a Git repository into a workspace - useful for code, but it doesn't deploy Lakeflow Jobs, SDP pipelines, or bundle configurations. Option D (Azure CLI) manages Azure infrastructure (resource groups, storage accounts, etc.) and has no native DAB deployment support.
Reference: https://learn.microsoft.com/en-us/azure/databricks/dev-tools/bundles/deploy-bundle
NEW QUESTION # 76
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
- The schemas and tables can be queried in Databricks.
- The schemas and tables appear alongside other Unity Catalog objects.
- The data is NOT copied into Databricks-managed storage.
Solution: You create a Lakeflow Connect pipeline and connect it to DB1.
Does this meet the goal?
Answer: A
Explanation:
Correct:
* You create a foreign catalog in Catalog Explorer.
You should create a Foreign Catalog using Lakehouse Federation.
Data Copying: Lakehouse Federation queries data directly in the source SQL Server without moving or copying it.
Seamless Integration: The database schemas and tables appear right inside Unity Catalog alongside your other data objects.Real-time Access: It provides immediate access to live SQL Server data.
Incorrect:
* You create a Databricks access connector.
* You create a Lakeflow Connect pipeline and connect it to DB1.
Data Copying: Lakeflow Connect is an ingestion tool that physically replicates and copies data into Databricks-managed storage (Delta tables).
Storage Costs: It violates your requirement to keep data out of Databricks storage.
* You create a new native catalog in Unity Catalog.
Note:
To expose the external SQL Server database in Unity Catalog without copying the data, you must use Lakehouse Federation.
Here are the step-by-step actions you need to take:
1. Create a Connection
Create a securable object in Unity Catalog that specifies the path and credentials to access the SQL Server database.
Go to Catalog Explorer or use SQL.
Select External Data > Connections.
Create a connection using the SQL Server connection details (URL, host, port, and database credentials).
*-> 2. Create a Foreign Catalog
Create a specific type of catalog in Unity Catalog that mirrors the external database.
Use the CREATE FOREIGN CATALOG SQL command or the Catalog Explorer UI.
Link this foreign catalog directly to the connection you created in step 1.
3. Query the DataOnce the foreign catalog is created, Unity Catalog automatically syncs the schemas and tables from SQL Server.
Reference:
https://docs.databricks.com/gcp/en/database-objects/
NEW QUESTION # 77
You have an Azure Databricks workspace that contains an all-purpose cluster named Cluster1.
You discover that out of- memory (OOM) errors intermittently cause jobs running on Cluster1 to fail.
You need to identify the root cause of the failures by analyzing the runtime execution behavior. What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.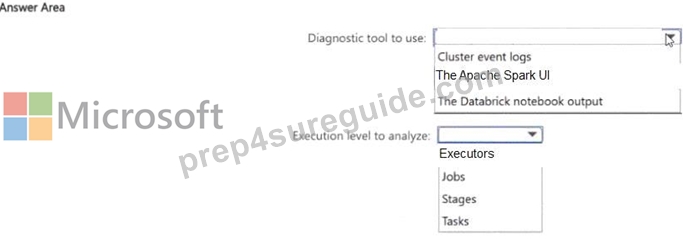
Answer:
Explanation: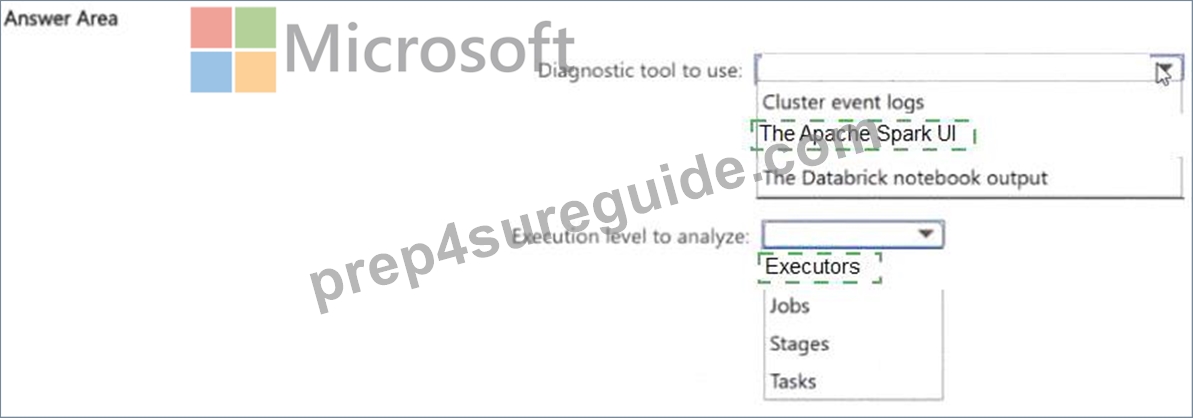
Explanation:
Diagnosing OOM errors requires analysing actual runtime execution behaviour. The Spark UI is the primary tool - it ' s accessible from the cluster detail page and captures rich per-stage and per-task metrics without any extra setup.
In the Executors tab, look at storage memory used, execution memory used, memory spill to disk, and GC time per executor. An executor showing high memory spill is a strong indicator that it ' s processing more data than it can hold in memory - often caused by data skew, where one partition is far larger than the others.
The Stages tab shows task distribution - if one task in a stage is processing 10x more data than its peers, that
' s data skew causing memory pressure on that specific executor. Ganglia (available on older runtimes) provides node-level OS metrics like heap usage over time, which can confirm whether memory pressure is sustained or spiky.
These built-in tools give a complete picture of the root cause before making any configuration changes.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/monitor-cluster
NEW QUESTION # 78
You have an Azure Databricks workspace named Workspace! that uses a Git repository. The repository contains a Databricks notebook named Notebook1.
From the main branch, you create a feature branch named Branch! and commit changes to Notebooks Another user commits changes to Notebook1 in main.
When you attempt to merge Branch! into main, the merge fails due to conflicts.
You need to merge Branch! into the main branch. The solution must ensure that Notebook1 includes all the changes from both the branches.
What should you do?
Answer: D
Explanation:
The correct answer is D - apply the main branch changes to Branch1 and resolve the conflicts.
When a merge fails due to conflicts, the right workflow is to bring main's changes into the feature branch, resolve conflicts there, and then merge the clean feature branch into main. This is the standard Git conflict resolution pattern - resolve in the feature branch, not in main - because it protects the main branch from partial or broken states during resolution.
Option A (clone Branch1 as a new repository) creates a disconnected copy; it doesn't resolve the conflict and breaks the relationship with the remote. Option B (apply changes directly to main) bypasses the feature branch entirely and risks overwriting the other developer's work. Option C (clone main as a new repository) again creates a disconnected copy - none of Branch1's changes would be incorporated, and history would be lost.
Reference: https://learn.microsoft.com/en-us/azure/databricks/repos/git-operations-with-repos
NEW QUESTION # 79
Which feature helps reduce data scan during query execution in Delta Lake?
Answer: A
Explanation:
Delta Lake uses data skipping based on file-level statistics (min/max values). This reduces unnecessary file scans and improves query performance. VACUUM removes old files but does not improve query speed. Cluster restart has no impact on query optimization.
NEW QUESTION # 80
......
The data for our DP-750 practice materials that come up with our customers who have bought our DP-750 actual exam and provided their scores show that our high pass rate is 98% to 100%. This is hard to find and compare with in the market. And numerous enthusiastic feedbacks from our worthy clients give high praises not only on our DP-750 Study Guide, but also on our sincere and helpful 24 hours customer services online. You will feel grateful to choose our DP-750 learning quiz!
DP-750 Labs: https://www.prep4sureguide.com/DP-750-prep4sure-exam-guide.html
DOWNLOAD the newest Prep4sureGuide DP-750 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1sinC4KecpGKUzResUr0BN6N6hlqBj8n8