Data-Engineer-Associate Reliable Braindumps, Reliable Data-Engineer-Associate Exam Pdf
P.S. Free 2026 Amazon Data-Engineer-Associate dumps are available on Google Drive shared by Pass4guide: https://drive.google.com/open?id=1papgNv2lzjlGfsL1o_-ykJQeQcRQXWsl
With the company of our Data-Engineer-Associate study dumps, you will find the direction of success. There is nothing more exciting than an effective and useful Data-Engineer-Associate question bank to study with for your coming exam. The sooner you use Data-Engineer-Associate Training Materials, the more chance you will pass the Data-Engineer-Associate exam, and the earlier you get your certificate. You definitely have to have a try and you will be satisfied without doubt.
| Section | Weight | Objectives |
|---|
| Topic 1: Data Ingestion and Transformation | 34% | - Implement data quality and validation
- Transform and enrich data
- 1. Orchestrate data pipelines
- 2. Apply data processing logic
- 3. Use Spark, EMR, Step Functions
- Ingest data from various sources
- 1. Batch and streaming data ingestion
- 2. Use services like Kinesis, DMS, Glue, S3
|
| Topic 2: Data Store Management | 26% | - Optimize storage performance and cost
- Manage data lifecycle and storage tiers
- Design and implement data storage solutions
- 1. S3, Redshift, DynamoDB, RDS, Lake Formation
- 2. Data lakes, data warehouses, databases
|
| Topic 3: Data Operations and Support | 22% | - Monitor and troubleshoot data pipelines
- 1. CloudWatch, X-Ray, logging and metrics
- Backup, restore, and disaster recovery
- Ensure reliability and scalability
- Automate operational tasks
|
| Topic 4: Data Security and Governance | 18% | - Protect sensitive data
- Implement access control and authentication
- 1. IAM, Lake Formation, resource policies
- Encrypt data at rest and in transit
- Enforce compliance and data governance
- 1. Data lineage, audit logging, regulatory requirements
|
>> Data-Engineer-Associate Reliable Braindumps <<
Reliable Data-Engineer-Associate Exam Pdf, Reliable Data-Engineer-Associate Test Questions
We are conscious of the fact that most of the candidates have a tight schedule which makes it tough to prepare for the Amazon Data-Engineer-Associate exam preparation. Pass4guide provides you with Amazon Data-Engineer-Associate Exam Questions in 3 different formats to open up your study options and suit your preparation tempo.
Amazon AWS Certified Data Engineer - Associate (DEA-C01) Sample Questions (Q247-Q252):
NEW QUESTION # 247
A company uses a variety of AWS and third-party data stores. The company wants to consolidate all the data into a central data warehouse to perform analytics. Users need fast response times for analytics queries.
The company uses Amazon QuickSight in direct query mode to visualize the data. Users normally run queries during a few hours each day with unpredictable spikes.
Which solution will meet these requirements with the LEAST operational overhead?
- A. Use Amazon Redshift provisioned clusters to load all the data into Amazon Redshift managed storage (RMS).
- B. Use Amazon Aurora PostgreSQL to load all the data into Aurora.
- C. Use Amazon Athena to load all the data into Amazon S3 in Apache Parquet format.
- D. Use Amazon Redshift Serverless to load all the data into Amazon Redshift managed storage (RMS).
Answer: D
Explanation:
Problem Analysis:
The company requires a centralized data warehouse for consolidating data from various sources.
They use Amazon QuickSight in direct query mode, necessitating fast response times for analytical queries.
Users query the data intermittently, with unpredictable spikes during the day.
Operational overhead should be minimal.
Key Considerations:
The solution must support fast, SQL-based analytics.
It must handle unpredictable spikes efficiently.
Must integrate seamlessly with QuickSight for direct querying.
Minimize operational complexity and scaling concerns.
Solution Analysis:
Option A: Amazon Redshift Serverless
Redshift Serverless eliminates the need for provisioning and managing clusters.
Automatically scales compute capacity up or down based on query demand.
Reduces operational overhead by handling performance optimization.
Fully integrates with Amazon QuickSight, ensuring low-latency analytics.
Reduces costs as it charges only for usage, making it ideal for workloads with intermittent spikes.
Option B: Amazon Athena with S3 (Apache Parquet)
Athena supports querying data directly from S3 in Parquet format.
While it's cost-effective, performance depends on the size and complexity of the data.
It is not optimized for high-speed analytics needed by QuickSight in direct query mode.
Option C: Amazon Redshift Provisioned Clusters
Requires manual cluster provisioning, scaling, and maintenance.
Higher operational overhead compared to Redshift Serverless.
Option D: Amazon Aurora PostgreSQL
Aurora is optimized for transactional databases, not data warehousing or analytics.
Does not meet the requirement for fast analytics queries.
Final Recommendation:
Amazon Redshift Serverless is the best choice for this use case because it provides fast analytics, integrates natively with QuickSight, and minimizes operational complexity while efficiently handling unpredictable spikes.
Reference:
Amazon Redshift Serverless Overview
Amazon QuickSight and Redshift Integration
NEW QUESTION # 248
A company is setting up a data pipeline in AWS. The pipeline extracts client data from Amazon S3 buckets, performs quality checks, and transforms the data. The pipeline stores the processed data in a relational database. The company will use the processed data for future queries.
Which solution will meet these requirements MOST cost-effectively?
- A. Use AWS Glue Studio to extract the data from the S3 buckets. Use AWS Glue DataBrew to perform the transformations and quality checks. Load the processed data and quality check results into an Amazon RDS for MySQL instance.
- B. Use AWS Glue ETL to extract the data from the S3 buckets and perform the transformations. Use AWS Glue Data Quality to enforce suggested quality rules. Load the data and the quality check results into an Amazon RDS for MySQL instance.
- C. Use AWS Glue Studio to extract the data from the S3 buckets. Use AWS Glue DataBrew to perform the transformations and quality checks. Load the processed data into an Amazon RDS for MySQL instance. Load the quality check results into a new S3 bucket.
- D. Use AWS Glue ETL to extract the data from the S3 buckets and perform the transformations. Use AWS Glue DataBrew to perform quality checks. Load the processed data and the quality check results into a new S3 bucket.
Answer: B
NEW QUESTION # 249
A data engineer needs to create an AWS Lambda function that converts the format of data from .csv to Apache Parquet. The Lambda function must run only if a user uploads a .csv file to an Amazon S3 bucket.
Which solution will meet these requirements with the LEAST operational overhead?
- A. Create an S3 event notification that has an event type of s3:*. Use a filter rule to generate notifications only when the suffix includes .csv. Set the Amazon Resource Name (ARN) of the Lambda function as the destination for the event notification.
- B. Create an S3 event notification that has an event type of s3:ObjectCreated:*. Use a filter rule to generate notifications only when the suffix includes .csv. Set the Amazon Resource Name (ARN) of the Lambda function as the destination for the event notification.
- C. Create an S3 event notification that has an event type of s3:ObjectCreated:*. Use a filter rule to generate notifications only when the suffix includes .csv. Set an Amazon Simple Notification Service (Amazon SNS) topic as the destination for the event notification. Subscribe the Lambda function to the SNS topic.
- D. Create an S3 event notification that has an event type of s3:ObjectTagging:* for objects that have a tag set to .csv. Set the Amazon Resource Name (ARN) of the Lambda function as the destination for the event notification.
Answer: B
Explanation:
Option A is the correct answer because it meets the requirements with the least operational overhead. Creating an S3 event notification that has an event type of s3:ObjectCreated:* will trigger the Lambda function whenever a new object is created in the S3 bucket. Using a filter rule to generate notifications only when the suffix includes .csv will ensure that the Lambda function only runs for .csv files. Setting the ARN of the Lambda function as the destination for the event notification will directly invoke the Lambda function without any additional steps.
Option B is incorrect because it requires the user to tag the objects with .csv, which adds an extra step and increases the operational overhead.
Option C is incorrect because it uses an event type of s3:*, which will trigger the Lambda function for any S3 event, not just object creation. This could result in unnecessary invocations and increased costs.
Option D is incorrect because it involves creating and subscribing to an SNS topic, which adds an extra layer of complexity and operational overhead.
:
AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide, Chapter 3: Data Ingestion and Transformation, Section 3.2: S3 Event Notifications and Lambda Functions, Pages 67-69 Building Batch Data Analytics Solutions on AWS, Module 4: Data Transformation, Lesson 4.2: AWS Lambda, Pages 4-8 AWS Documentation Overview, AWS Lambda Developer Guide, Working with AWS Lambda Functions, Configuring Function Triggers, Using AWS Lambda with Amazon S3, Pages 1-5
NEW QUESTION # 250
A company needs to implement a data mesh architecture for trading, risk, and compliance teams. Each team has its own data but needs to share views. They have 1,000+ tables in 50 Glue databases. All teams use Athena and Redshift, and compliance requires full auditing and PII access control.
- A. Create materialized views and enable Amazon Redshift datashares for each domain.
- B. Use AWS Glue Data Catalog views. Use CloudTrail logs and Lake Formation to manage permissions.
- C. Use Lake Formation to set up cross-domain access to tables. Set up fine-grained access controls.
- D. Create views in Athena for on-demand analysis. Use the Athena views in Amazon Redshift to perform cross-domain analytics. Use AWS CloudTrail to audit data access. Use AWS Lake Formation to establish fine-grained access control.
Answer: D
Explanation:
A data mesh approach in AWS typically uses Lake Formation for domain-level access control and Athena for cross-domain querying through federated views. CloudTrail ensures auditing.
"For data mesh architectures, use AWS Lake Formation for fine-grained access control and Athena views for cross-domain analysis. Enable CloudTrail to audit access."
- Ace the AWS Certified Data Engineer - Associate Certification - version 2 - apple.pdf This ensures scalability, security, and compliance across domains.
NEW QUESTION # 251
A company receives .csv files that contain physical address data. The data is in columns that have the following names: Door_No, Street_Name, City, and Zip_Code. The company wants to create a single column to store these values in the following format:
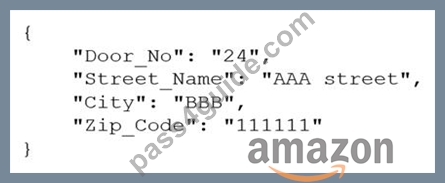
Which solution will meet this requirement with the LEAST coding effort?
- A. Use AWS Glue DataBrew to read the files. Use the NEST TO ARRAY transformation to create the new column.
- B. Use AWS Glue DataBrew to read the files. Use the NEST TO MAP transformation to create the new column.
- C. Write a Lambda function in Python to read the files. Use the Python data dictionary type to create the new column.
- D. Use AWS Glue DataBrew to read the files. Use the PIVOT transformation to create the new column.
Answer: B
Explanation:
The NEST TO MAP transformation allows you to combine multiple columns into a single column that contains a JSON object with key-value pairs. This is the easiest way to achieve the desired format for the physical address data, as you can simply select the columns to nest and specify the keys for each column. The NEST TO ARRAY transformation creates a single column that contains an array of values, which is not the same as the JSON object format. The PIVOT transformation reshapes the data by creating new columns from unique values in a selected column, which is not applicable for this use case. Writing a Lambda function in Python requires more coding effort than using AWS Glue DataBrew, which provides a visual and interactive interface for data transformations. References:
* 7 most common data preparation transformations in AWS Glue DataBrew (Section: Nesting and unnesting columns)
* NEST TO MAP - AWS Glue DataBrew (Section: Syntax)
NEW QUESTION # 252
......
Our Data-Engineer-Associate exam torrent offers you free demo to try before buying. You will get your downing link and password after the payment, and you can download Data-Engineer-Associate exam dumps right now. If you have any questions, you can directly contact us through online live chat or you can notify us through email, we will give you reply as soon as we can. In addition, we provide you free update for one year after purchasing the Data-Engineer-Associate Exam Dumps.
Reliable Data-Engineer-Associate Exam Pdf: https://www.pass4guide.com/Data-Engineer-Associate-exam-guide-torrent.html
- Pass Guaranteed 2026 Amazon Professional Data-Engineer-Associate: AWS Certified Data Engineer - Associate (DEA-C01) Reliable Braindumps 😑 Search on ▛ www.testkingpass.com ▟ for ➠ Data-Engineer-Associate 🠰 to obtain exam materials for free download 📒Relevant Data-Engineer-Associate Answers
- Valid Data-Engineer-Associate Reliable Braindumps - Pass Data-Engineer-Associate Exam 🥪 Go to website ➠ www.pdfvce.com 🠰 open and search for 【 Data-Engineer-Associate 】 to download for free 🅿New Braindumps Data-Engineer-Associate Book
- Data-Engineer-Associate Practical Information 🦮 New Data-Engineer-Associate Exam Experience ❔ Relevant Data-Engineer-Associate Answers 🦖 Search for 「 Data-Engineer-Associate 」 on ➽ www.pass4test.com 🢪 immediately to obtain a free download ↪Updated Data-Engineer-Associate Demo
- Obtained The Data-Engineer-Associate Reliable Braindumps Means Passing The AWS Certified Data Engineer - Associate (DEA-C01) ➰ Search for { Data-Engineer-Associate } and obtain a free download on ▛ www.pdfvce.com ▟ 🍁New Braindumps Data-Engineer-Associate Book
- Data-Engineer-Associate Simulation Questions 🍐 Data-Engineer-Associate Dumps 🐊 Free Data-Engineer-Associate Learning Cram 🚗 ⇛ www.testkingpass.com ⇚ is best website to obtain ➡ Data-Engineer-Associate ️⬅️ for free download 🏄Exam Data-Engineer-Associate Simulator Fee
- Successfully Get the Quality Amazon Data-Engineer-Associate Exam Questions 👊 Easily obtain free download of ( Data-Engineer-Associate ) by searching on ( www.pdfvce.com ) 🎏Data-Engineer-Associate Practice Exam Questions
- Data-Engineer-Associate Reliable Exam Simulations 🏚 Updated Data-Engineer-Associate Demo 🛒 Data-Engineer-Associate Latest Exam Simulator 🚡 Download ➥ Data-Engineer-Associate 🡄 for free by simply entering 【 www.troytecdumps.com 】 website 🥳Relevant Data-Engineer-Associate Answers
- 2026 Data-Engineer-Associate Reliable Braindumps | Excellent AWS Certified Data Engineer - Associate (DEA-C01) 100% Free Reliable Exam Pdf 🦈 Search for ( Data-Engineer-Associate ) and easily obtain a free download on [ www.pdfvce.com ] 🌉Data-Engineer-Associate Latest Exam Simulator
- New Data-Engineer-Associate Exam Experience 🔥 Data-Engineer-Associate Reliable Exam Simulations ⛄ New Data-Engineer-Associate Exam Experience 🧆 Simply search for 【 Data-Engineer-Associate 】 for free download on ⮆ www.examcollectionpass.com ⮄ ❤️New Data-Engineer-Associate Exam Experience
- 100% Pass Quiz Trustable Amazon - Data-Engineer-Associate - AWS Certified Data Engineer - Associate (DEA-C01) Reliable Braindumps 🥖 Search for ✔ Data-Engineer-Associate ️✔️ and download it for free immediately on ☀ www.pdfvce.com ️☀️ 📌Testking Data-Engineer-Associate Exam Questions
- Data-Engineer-Associate Latest Exam Simulator 🧮 Dumps Data-Engineer-Associate Discount 🐠 Exam Data-Engineer-Associate Voucher 🆕 ➽ www.vceengine.com 🢪 is best website to obtain ➥ Data-Engineer-Associate 🡄 for free download ❎Exam Data-Engineer-Associate Voucher
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
BTW, DOWNLOAD part of Pass4guide Data-Engineer-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1papgNv2lzjlGfsL1o_-ykJQeQcRQXWsl