Die Bestehensquote mit einer Höhe von fast 100% ist das beste Geschenk von unseren Kunden. Wir hoffen, dass unsere Microsoft DP-750 Prüfungsunterlagen mehr aufstrebenden Leuten helfen, Microsoft DP-750 Prüfung zu bestehen. Unser Team überprüfen jeden Tag die Aktualisierungsstand vieler IT-Zertifizierungsprüfungen. Sie können auf unsere Microsoft DP-750 vertrauen, weil sie die neuesten und umfassendesten Unterlagen enthält.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
| Topic 2: Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
| Topic 3: Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
|
| Topic 4: Prepare and process data | 30–35% | - Optimize and manage data storage
|
>> DP-750 Quizfragen Und Antworten <<
Wie kann man Erfolge erlangen. Es gibt nur eine Ankürzung, nämlich: die Lernhilfe zur Microsoft DP-750Zertifizierungsprüfung von Zertpruefung zu benutzen. Das ist unser Vorschlag für jeden Kandidaten. Wir hoffen, dass Sie Ihren Traum erfüllen können.
21. Frage
A Delta table receives new fields in incoming JSON data. You want to automatically adapt without breaking pipelines. What should you enable?
Antwort: C
Begründung:
Auto Loader supports schema inference and schema evolution, allowing new columns to be added automatically during ingestion. This reduces pipeline maintenance and avoids failures due to schema drift. Disabling enforcement is unsafe and risks data corruption. Overwrite mode deletes existing data. Manual updates are not scalable.
22. Frage
You have an Azure Databricks workspace that is enabled for Unity Catalog. You plan to run the following PySpark code.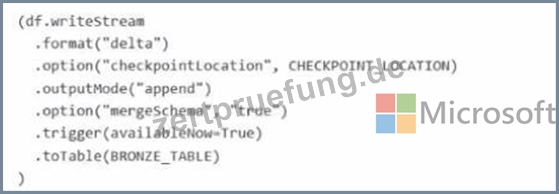
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.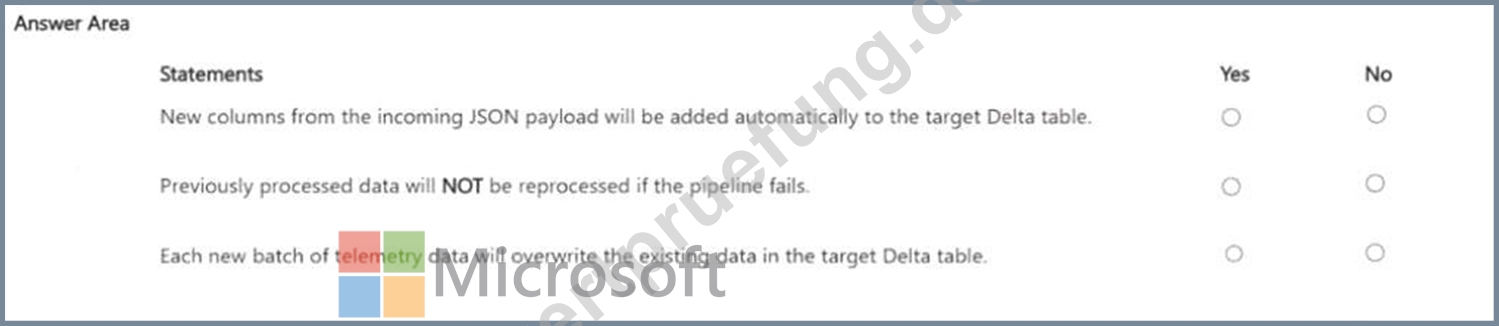
Antwort:
Begründung: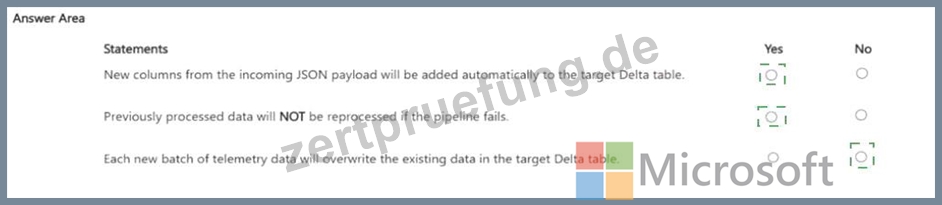
Explanation:
For HOTSPOT questions, each statement must be evaluated against the actual PySpark code shown in the answer area. Key evaluation principles:
DataFrames are immutable - every transformation returns a new DataFrame; the original is unchanged.
Transformations (filter, select, groupBy, join) are lazy and only execute when an action (show, count, write) is called.
Null handling: df.filter(col != None) is incorrect in PySpark due to SQL null semantics; use col.isNotNull() or dropna() instead. Schema changes: using mergeSchema=true or schema evolution handles new columns.
Write modes: 'overwrite' replaces existing data; 'append' adds to it.
Always check whether the code uses the correct Delta format (.format('delta')), Unity Catalog three-part naming, and whether write operations include a checkpointLocation for streaming queries. Evaluate each statement strictly on what the code does, not on what it might intend to do.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
23. Frage
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df-fillna(0, subset=['order_amount'])
Does this meet the goal?
Antwort: A
Begründung:
The correct answer is B - No.
df.fillna(0, subset=['order_amount']) does not remove null rows. It replaces null values in order_amount with the integer 0, leaving those rows in the DataFrame with 0 as their order_amount value. The row count is unchanged - nulls are imputed, not dropped.
The requirement is to exclude rows where order_amount is null, meaning those rows should not appear in the result at all. fillna is a data imputation function - it fills gaps with default values, which is a different operation entirely from filtering. After fillna, a downstream process would see order_amount = 0 and might treat it as a valid zero-value order rather than recognising it was originally null.
The correct approach is df.dropna(subset=['order_amount']) or df.filter(df.order_amount.isNotNull()), both of which physically remove null rows from the resulting DataFrame.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
24. Frage
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Sales. Sales stores transaction data and contains the following columns:
* transactionjd (string)
* transaction date (date)
* amount (decimal)
You need to implement the following data quality requirements by using table-level data quality enforcement:
* amount must be greater than 0.
* transaction id must never be null.
* Invalid records must be rejected when data is written to the Sales table.
What should you do?
Antwort: D
Begründung:
The correct answer is D - a NOT NULL constraint on transaction_id and a CHECK constraint on amount.
Delta Lake table constraints are enforced at write time by the Delta engine itself. A NOT NULL constraint rejects any INSERT or UPDATE that would place a null in transaction_id. A CHECK constraint with amount
> 0 rejects any row where amount is zero or negative. Combined, they implement exactly the stated quality rules: bad rows are rejected when data is written, not filtered away at read time.
Options A and C (SELECT with WHERE / views) are read-time constructs - they don ' t prevent invalid data from entering the table. A clever pipeline bypass could write directly to the table and skip the view entirely. Option B (row-level security with WHERE conditions) is an access-control feature for restricting which rows users see, not for enforcing data quality on writes. Table constraints are the only mechanism that genuinely blocks bad data at the storage layer.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/delta-constraints
25. Frage
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job! runs every hour.
Occasionally, the job run takes longer than one hour to complete. Overlapping runs must be prevented to avoid data corruption.
You need to configure the job scheduling behavior.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.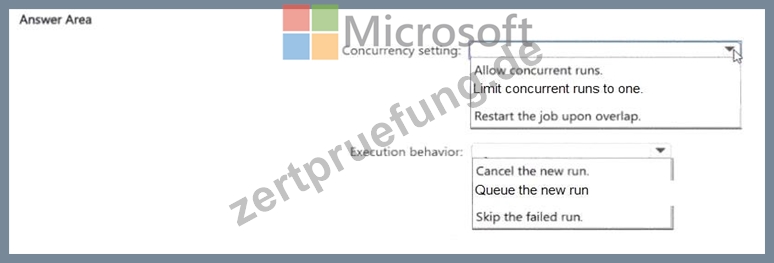
Antwort:
Begründung: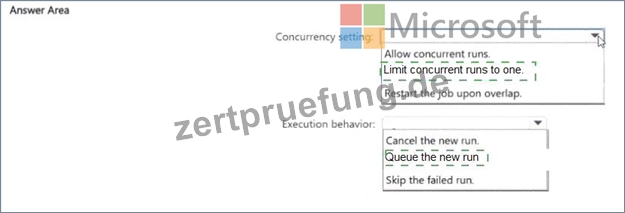
Explanation:
Two settings address the overlapping-run problem:
Concurrent Runs policy set to 'Skip' (or 'Allow only one concurrent run'). When a new scheduled trigger fires while the previous run is still in progress, the new run is skipped rather than starting alongside the ongoing one. This prevents two runs from writing to the same tables at the same time - which is the data corruption risk the question highlights.
Cron-based schedule for the hourly trigger. A cron expression defines the regular execution cadence.
Combined with the concurrency setting, the job runs hourly but never overlaps.
An alternative to 'Skip' is 'Wait' (queue the new run), which ensures every scheduled run eventually executes
- but for this scenario where overlapping is the primary concern, skipping the missed run is typically preferable to building up a queue of back-to-back executions.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/configure-jobs#concurrent-runs
26. Frage
......
Die Schulungsunterlagen zur Microsoft DP-750 Zertifizierungsprüfung von Zertpruefung werden die größte Erfolgsquote erzielen. Naben den Büchern sind heutztage das Internet als ein Wissensschatz angesehen. In Zertpruefung können Sie Ihren Wissensschatz finden. Das ist eine Website, die Ihnen sehr helfen können. Sie werden sicher komplizierte Übungen treffen, Unser Zertpruefung wird Ihnen helfen, die Prüfung ganz einfach zu bestehen, weil es alle erforderlichen Kenntnisse zur Microsoft DP-750 Zertifizierungsprüfung enthält.
DP-750 Unterlage: https://www.zertpruefung.de/DP-750_exam.html