What's more, part of that It-Tests Databricks-Certified-Professional-Data-Engineer dumps now are free: https://drive.google.com/open?id=1Fy5dgTsXyfLAqegXtSFd2sbmPQ6LUF76
Although we have carried out the Databricks-Certified-Professional-Data-Engineer exam questions for customers, it does not mean that we will stop perfecting our study materials. Our experts are still testing new functions for the Databricks-Certified-Professional-Data-Engineerstudy materials. Even if you have purchased our study materials, you still can enjoy our updated Databricks-Certified-Professional-Data-Engineer Practice Engine. We will soon upload our new version of our Databricks-Certified-Professional-Data-Engineer guide braindumps into our official websites.
| Section | Objectives |
|---|---|
| Production Pipelines and Orchestration | - Automate ETL pipelines and scheduling - Build and manage workflows using Databricks Jobs - Pipeline reliability and fault tolerance |
| Data Ingestion and Transformation | - Transform and clean datasets using Spark SQL and DataFrame APIs - Handle batch and streaming data pipelines - Ingest data using Apache Spark and Databricks |
| Security, Governance, Monitoring, and Optimization | - Monitor and optimize Spark workloads - Implement Unity Catalog governance and access control - Cost optimization and performance tuning |
| Data Modeling and Storage | - Design scalable data lakehouse architectures - Delta Lake table design and optimization - Schema evolution and data partitioning strategies |
>> Databricks Databricks-Certified-Professional-Data-Engineer Reliable Test Camp <<
We can promise that we will provide you with quality Databricks-Certified-Professional-Data-Engineer Exam Questions, reasonable price and professional after sale service. Because customer first, service first is our principle of service. If you buy our Databricks-Certified-Professional-Data-Engineer study guide, you will find our after sale service is so considerate for you. We are glad to meet your all demands and answer your all question about our study materials. And you can find that our price is affordable even for the students. Besides, we will the most professional support by our technicals if you have any problem on buying or downloading.
NEW QUESTION # 116
The Databricks workspace administrator has configured interactive clusters for each of the data engineering groups. To control costs, clusters are set to terminate after 30 minutes of inactivity. Each user should be able to execute workloads against their assigned clusters at any time of the day.
Assuming users have been added to a workspace but not granted any permissions, which of the following describes the minimal permissions a user would need to start and attach to an already configured cluster.
Answer: D
Explanation:
Explanation
This is the minimal permission a user would need to start and attach to an already configured cluster. Cluster creation allowed means that the user can create new clusters or start existing clusters that are stopped. "Can Attach To" privileges on the required cluster means that the user can attach notebooks or libraries to that cluster and run commands on it. Verified References: Databricks Certified Data Engineer Professional, under
"Security & Governance" section; Databricks Documentation, under "Cluster permissions" section.
NEW QUESTION # 117
A junior data engineer has been asked to develop a streaming data pipeline with a grouped aggregation using DataFrame df. The pipeline needs to calculate the average humidity and average temperature for each non- overlapping five-minute interval. Events are recorded once per minute per device.
df has the following schema: device_id INT, event_time TIMESTAMP, temp FLOAT, humidity FLOAT Code block:
df.withWatermark("event_time", "10 minutes")
.groupBy(
________,
"device_id"
)
.agg(
avg("temp").alias("avg_temp"),
avg("humidity").alias("avg_humidity")
)
.writeStream
.format("delta")
.saveAsTable("sensor_avg")
Which line of code correctly fills in the blank within the code block to complete this task?
Answer: B
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
* Exact extract: "window(timeColumn, windowDuration[, slideDuration]) returns a time window for grouping on event-time."
* Exact extract: "If slideDuration is not specified the windows are non-overlapping (tumbling) with length windowDuration." References: Structured Streaming window aggregations; Watermarking.
NEW QUESTION # 118
Which of the following array functions takes input column return unique list of values in an array?
Answer: A
Explanation:
Explanation
Table Description automatically generated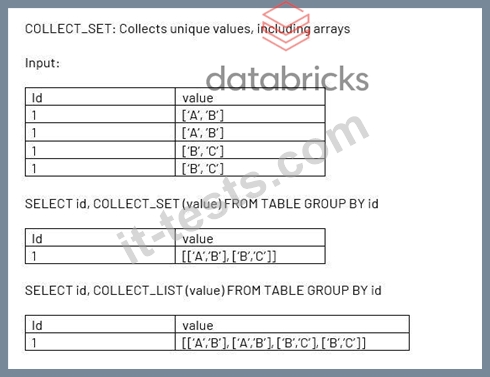
NEW QUESTION # 119
The viewupdatesrepresents an incremental batch of all newly ingested data to be inserted or updated in the customerstable.
The following logic is used to process these records.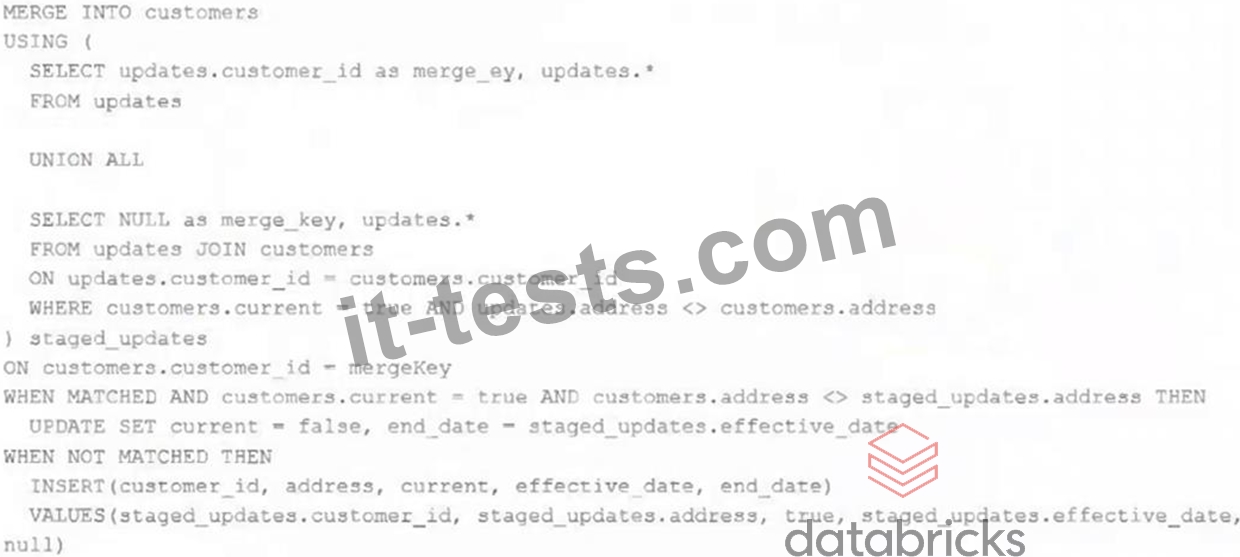
Which statement describes this implementation?
Answer: A
Explanation:
Explanation
The logic uses the MERGE INTO command to merge new records from the view updates into the table customers. The MERGE INTO command takes two arguments: a target table and a source table or view. The command also specifies a condition to match records between the target and the source, and a set of actions to perform when there is a match or not. In this case, the condition is to match records by customer_id, which is the primary key of the customers table. The actions are to update the existing record in the target with the new values from the source, and set the current_flag to false to indicate that the record is no longer current; and to insert a new record in the target with the new values from the source, and set the current_flag to true to indicate that the record is current. This means that old values are maintained but marked as no longer current and new values are inserted, which is the definition of a Type 2 table. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Merge Into (Delta Lake on Databricks)" section.
NEW QUESTION # 120
Given the following PySpark code snippet in a Databricks notebook:
filtered_df = spark.read.format("delta").load("/mnt/data/large_table") \
.filter("event_date > '2024-01-01'")
filtered_df.count()
The data engineer notices from the Query Profiler that the scan operator for filtered_df is reading almost all files, despite the filter being applied.
What is the probable reason for poor data skipping?
Answer: D
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
Delta Lake's data skipping and file pruning optimizations rely on metadata about columns used in partitioning or Z-ordering. If a filter column (e.g., event_date) is not included in the partition or Z-ordering keys, Spark cannot effectively prune files at query time, resulting in full table scans. The Databricks optimization guide states that "File pruning and data skipping are most effective when queries filter on partition or Z-order columns." This explains why the filter was applied but had no impact on the amount of data read. Options A and B are incorrect because Delta automatically applies file pruning when possible; D is less likely, as date columns are fully supported for skipping.
NEW QUESTION # 121
......
In rare cases, if you fail to pass the Databricks Certified Professional Data Engineer Exam Databricks-Certified-Professional-Data-Engineer exam despite using Databricks Certified Professional Data Engineer Exam exam dumps we will return your whole payment without any deduction. Take the best decision of your professional career and start exam preparation with Databricks Certified Professional Data Engineer Exam exam practice questions and become a certified Databricks Certified Professional Data Engineer Exam Databricks-Certified-Professional-Data-Engineer expert.
Exam Databricks-Certified-Professional-Data-Engineer Syllabus: https://www.it-tests.com/Databricks-Certified-Professional-Data-Engineer.html
What's more, part of that It-Tests Databricks-Certified-Professional-Data-Engineer dumps now are free: https://drive.google.com/open?id=1Fy5dgTsXyfLAqegXtSFd2sbmPQ6LUF76