此外,這些VCESoft SPS-C01考試題庫的部分內容現在是免費的:https://drive.google.com/open?id=1qPk8X-e-kVtFzBuP-uid13XPWZed2GYm
VCESoft的產品是為你們參加Snowflake SPS-C01認證考試而準備的。VCESoft提供的培訓資料不僅包括與Snowflake SPS-C01認證考試相關的資訊技術培訓資料,來鞏固專業知識,而且還有準確性很高的關於Snowflake SPS-C01的認證考試的相關考試練習題和答案。可以保證你第一次參加Snowflake SPS-C01的認證考試就以高分順利通過。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Snowpark API and Development | 30% | - Multi-language support
|
| Topic 2: Snowpark Concepts and Architecture | 25% | - Session management and connection
|
| Topic 3: Data Transformations and Operations | 35% | - DataFrame manipulation
|
| Topic 4: Performance and Best Practices | 10% | - Security and governance
|
VCESoft可以為你提供捷徑,給你節約好多時間和精力換。VCESoft會為你的Snowflake SPS-C01認證考試提供很好的培訓工具,有效的幫助你通過Snowflake SPS-C01認證考試。如果你在其他網站也看到了可以提供相關資料,你可以繼續往下看,你會發現其實資料主要來源於VCESoft,而且VCESoft提供的資料最全面,而且更新得最快。
問題 #169
You are developing a Snowpark stored procedure in Python that utilizes the 'requests' library to fetch data from an external API. Your Snowflake account is configured to use Anaconda packages. You encounter an error indicating that the 'requests' library is not found. Which of the following steps are MOST effective in ensuring the 'requests' library is available to your stored procedure?
答案:D
解題說明:
The 'packages' argument in the 'CREATE OR REPLACE PROCEDURE statement is the correct way to specify dependencies on Anaconda packages. Snowflake will automatically resolve and make these packages available to the stored procedure. Option B is incomplete; while Anaconda integration is necessary, it doesn't automatically import the library. Options A, C and E are incorrect and not best practices.
問題 #170
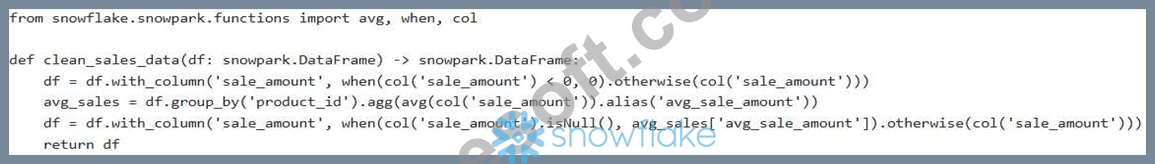
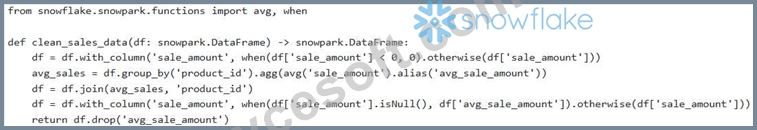
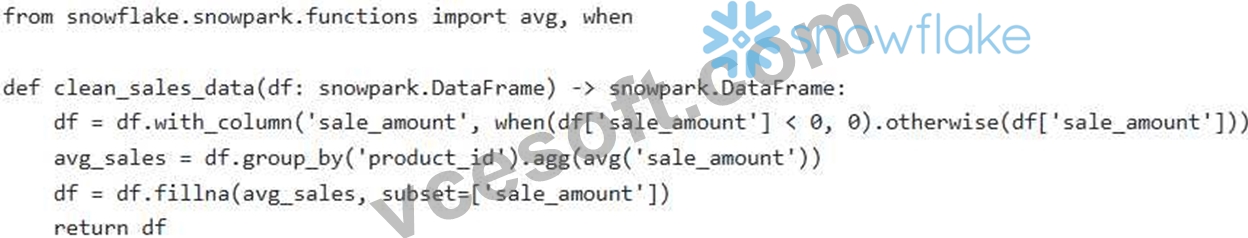
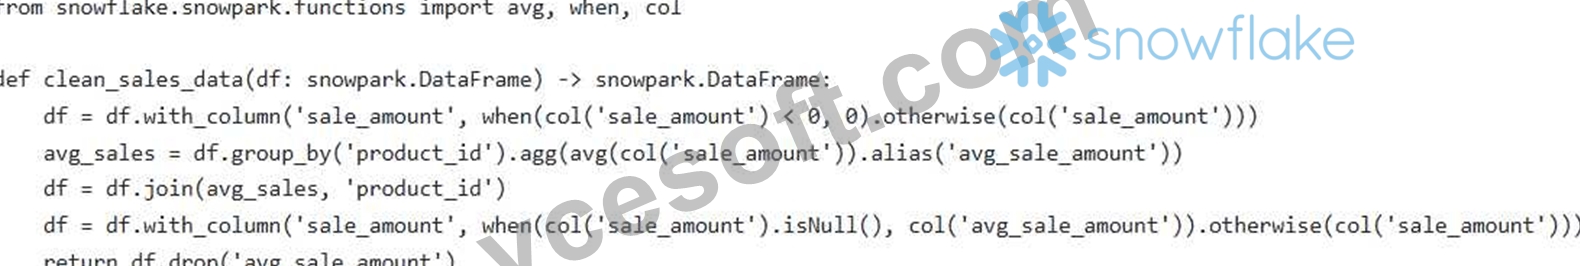
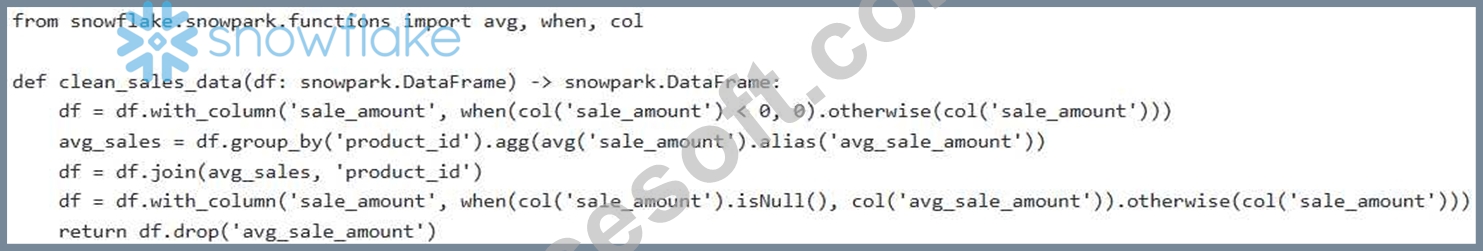
You have a Snowpark DataFrame with columns 'product_id', 'customer_id', and 'sale_amount'. Some values are negative, indicating returns, and others are null. You need to replace negative values with 0 and fill null values with the average 'sale_amount' for each 'product_id'. Which of the following approaches is the MOST efficient and correct way to achieve this using Snowpark?
答案:D
解題說明:
Option E first replaces negative values with 0. Then, it calculates the average sales amount per product and joins it back to the original DataFrame. Finally, it fills null values with the calculated average sales amount and drops the temporary column. This is efficient because it utilizes Snowpark's DataFrame operations. other options does not handle nulls or gives errors.
問題 #171
You have a Snowpark DataFrame 'employees' with columns 'employee_id' (INT), 'name' (STRING), 'department' (STRING), and 'salary' (DOUBLE). You want to create a new DataFrame that contains the top 3 highest-paid employees within each department. Which of the following approaches is the MOST efficient and correct way to achieve this using Snowpark Python?





答案:A,B,D
解題說明:
The most efficient and correct approaches are A, C, and D. These options utilize window functions in Snowpark to efficiently rank employees within each department. Option A uses , which assigns a unique rank to each row within a partition, even if there are ties in salary. Option C uses 'rank()' , which assigns the same rank to rows with equal salary values, resulting in possible gaps in the ranking sequence. Option D uses , which assigns consecutive ranks without gaps, even if there are ties in salary. The most appropriate ranking function will depend on the specific ranking requirement but all three would provide top 3 employees. Option B is incorrect because Snowpark 'apply' does not support groupby operations effectively, resulting in an error. Finally E will only return 2 employees, which would make it incorrect.
問題 #172
You have a Snowpark DataFrame 'df that you want to persist as a Snowflake table. You need to ensure the following requirements are met: 1. The table should be created if it does not exist. 2. If the table exists, the new data should be merged with the existing data based on a 'primary_key' column. 3. If a row with a matching 'primary_key' already exists in the target table, update the existing row with the values from the 'df DataFrame. Otherwise, insert the row from 'df into the target table. Which of the following approaches can achieve this using Snowpark?
答案:C,D
解題說明:
Options C and D are the correct answers. Snowpark's method does not directly support a merge operation. To achieve this, you typically need to use one of the following approaches: Create a stored procedure that executes a Snowflake MERGE statement. This allows you to perform the merge operation server-side within Snowflake using SQL. This stored procedure can then be called from the Snowpark application. Stage your dataframe in to a new table, then create merge statement to handle the rest. Option A is incorrect because Snowpark does not have a option for Option B is possible but very inefficient, it requires reading all of the existing data in the table. Option E is inefficient because converting DataFrame to Pandas will add another performance bottleneck when dealing with large datasets.
問題 #173
You are developing a Snowpark application that uses a UDF written in Python. This UDF requires several third-party Python packages (e.g., 'pandas', 'scikit-learn'). You need to ensure these packages are available in the UDF's execution environment within Snowflake. You have the packages listed in a 'requirements.txt' file. Which of the following methods, alone or in combination, correctly provision these dependencies for the UDF? (Select all that apply)
答案:A,D,E
解題說明:
Options A, C and E are correct. Option A: Directly including packages as strings in the '@udf decorator's "packages' argument is a valid way to specify dependencies when using the Snowflake Anaconda channel. Option C: Using a Conda environment file is the most robust way to manage dependencies, especially for complex projects with specific version requirements. Uploading the environment and referencing it through conda_integratiorü ensures consistent dependency resolution. Option E: Using the 'session.add_packageS method is a viable way to add packages dynamically before UDF registration. Option B is incorrect: you cannot directly import a 'requirements.txt' file using 'imports'. Option D is incorrect: You cannot manually install packages on the Snowflake compute warehouse.
問題 #174
......
我相信不論在哪個行業工作的人都希望自己有很好的職業前景。當然在競爭激烈的IT行業裏面也不例外。在IT行業中工作的專業人士也希望自己有個很好的提升機會和很大的提升空間。很多專業的IT人士都知道Snowflake SPS-C01 認證考試可以幫你滿足這些願望的。而VCESoft是一個能幫助你成功通過Snowflake SPS-C01 的網站。
SPS-C01資料: https://www.vcesoft.com/SPS-C01-pdf.html
P.S. VCESoft在Google Drive上分享了免費的、最新的SPS-C01考試題庫:https://drive.google.com/open?id=1qPk8X-e-kVtFzBuP-uid13XPWZed2GYm