There has been fierce and intensified competition going on in the practice materials market. As the leading commodity of the exam, our AI-200 practice materials have get pressing requirements and steady demand from exam candidates all the time. So our AI-200 practice materials have active demands than others with high passing rate of 98 to 100 percent. We are one of the largest and the most confessional dealer of practice materials. That is why our AI-200 practice materials outreach others greatly among substantial suppliers of the exam.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Develop containerized AI solutions on Azure | 25% | - Monitor and troubleshoot containerized workloads
|
| Topic 2: Integrate backend services and build event-driven architectures | 25% | - Implement messaging and event systems
|
| Topic 3: Secure, monitor, and optimize AI solutions | 20% | - Implement observability and reliability
|
| Topic 4: Develop AI solutions using Azure data services | 30% | - Design and optimize data access and retrieval
|
>> Most AI-200 Reliable Questions <<
To attempt the Microsoft AI-200 exam optimally and ace it on the first attempt, proper exam planning is crucial. Since the Microsoft AI-200 exam demands a lot of time and effort, we designed the Microsoft AI-200 Exam Dumps in such a way that you would not have to go through sleepless study nights or disturb your schedule.
NEW QUESTION # 97
Case Study 2 - Proseware Inc.
Background
Proseware Inc. develops AI-powered knowledge management solutions for enterprise customers.
The company is modernizing its platform to support semantic search, intelligent document retrieval, and real-time partner integrations.
The engineering team uses Python and Azure SDKs. The architecture is being redesigned to support containerized microservices, vector search workloads, and serverless backend processing.
Planned Application Architecture
Microservices are containerized by using Docker.
Code for containerized microservices and Azure Function apps is developed locally but stored in a GitHub repository.
Custom images for containerized microservices are stored in Azure Container Registry (ACR).
Base images are stored in Docker Hub. Custom images must be rebuilt automatically whenever their base images are updated.
Azure Cosmos DB for NoSQL stores documents, metadata, and vector embeddings.
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Azure Container Apps (ACA) apps host backend API services that provide semantic search across Azure Cosmos DB for NoSQL documents. API services process Service Bus messages and update search indexes.
Azure Kubernetes Service (AKS) processes batch vector embedding regeneration for existing Azure Cosmos DB for NoSQL documents (whenever the embedding model is changed).
An extranet-facing containerized webhook allows business partners to submit documents to be processed by internal AI workflows for semantic search and retrieval.
Monitoring
Telemetry generated by Azure resources is sent to Azure Monitor.
A Log Analytics workspace is used to collect ACA apps logs, AKS container logs, and Azure Functions apps logs.
Monitoring of Azure Functions is currently implemented by using Azure Application Insights SDK instrumentation.
Business Requirements
Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Backend API services must scale automatically during business hours.
Cold start delay of backend APIs must be minimized.
Secrets must be stored outside of container images.
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Azure Cosmos DB for NoSQL RU consumption must be minimized.
Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
The partner-facing containerized webhook service must run on Azure App Service.
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
Azure App Service must supply secrets at runtime without relying on external services.
Resources and workloads must be deployed by using Bicep templates through an automated, version-controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Known Issues
RU consumption spikes during vector similarity queries.
Drag and Drop Question
You need to configure event-driven scaling for the backend API services to meet the technical requirements.
Which settings should you use for each element? To answer, move the appropriate settings to the correct elements. You may use each setting once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.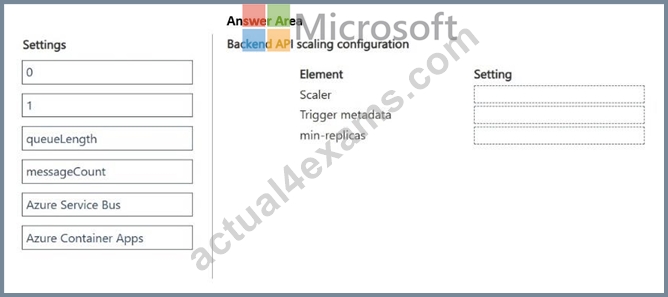
Answer:
Explanation: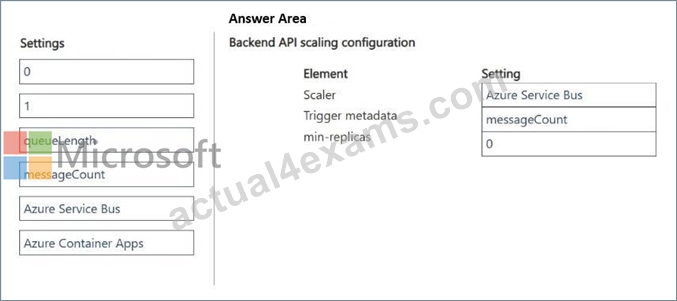
Explanation:
Scenario, technical requirements.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Box 1: Azure Service Bus
Scaler TypeType
Set the scale rule type to custom.
KEDA Scaler Name: Set the type inside the custom specification block to azure-service-bus.
Box 2: messageCount
Trigger Metadata Values
The metadata block dictates how KEDA calculates the required replica count.
Configure the following core metadata parameters:
queueName: The explicit string name of your targeted Azure Service Bus
*-> queue.messageCount: The target integer threshold of concurrent pending messages assigned per replica (e.g., 5 or 10). KEDA uses this value to scale out systematically.
activationMessageCount: Set to 1 or 0. This defines the exact metric floor required to transition the container app out of a dormant state.
namespace: The canonical name of your Service Bus namespace
Box 3: 0
Min-Replicas ConfigurationValue
Set --min-replicas to 0.
Setting this value to zero enables full serverless cost efficiency. KEDA actively handles the background polling, allowing your backend API containers to scale down completely and run zero active replicas when the Service Bus queue contains zero pending messages.
Reference:
https://oneuptime.com/blog/post/2026-02-16-how-to-set-up-keda-based-auto-scaling-with-queue-triggers-in-azure-container-apps/view
NEW QUESTION # 98
You deploy a production Azure Function app that connects to an Azure SQL Database.
The solution must provide the following functionality:
- Prevent secrets from being exposed in source control.
- Support secret rotation without redeploying the function app.
- Avoid downtime during credential updates.
You need to configure secure and maintainable secret management.
What should you configure?
Answer: A
Explanation:
To meet all requirements, you should configure Application settings with Key Vault references.
Source Control Protection: The Function App source code and configuration files only store a reference URI (e.g., @Microsoft.KeyVault(SecretUri=...)) rather than the actual connection string, keeping secrets entirely out of source control.
Seamless Secret Rotation: Azure Key Vault handles secret rotation natively. When a database password changes, you simply update the secret in Key Vault.
Zero Downtime: By using versionless Key Vault references (omitting the specific version GUID from the URI), the Azure Function App will automatically fetch the latest secret version within 24 hours without requiring a code redeployment or app restart.
References:
https://oneuptime.com/blog/post/2026-02-16-how-to-configure-managed-identity-for-azure-app-service-to-access-key-vault-secrets-without-credentials/view
NEW QUESTION # 99
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You are using Azure Monitor Application Insights to investigate a production API. You open the Logs blade and set the time range to Last 24 hours.
An engineer recommends the following query to count requests by result code and sort the results from most frequent to least frequent:
requests
| summarize request_count = count() by resultCode
| order by request_count desc
You need to determine whether the query returns the number of requests grouped by result code and sorted from most to least frequent.
Solution: The query lists every individual request along with its result code.
Does the solution meet the goal?
Answer: A
Explanation:
Correct:
* The query returns one row per unique resultCode value with the number of requests in each group.
The Kusto Query Language (KQL) query uses the summarize operator, which acts as a grouping and aggregation mechanism.
summarize request_count = count() by resultCode
This groups all the individual rows in the requests table by their unique resultCode. It then counts the total number of logs within each group and places that value into a new column called request_count.
order by request_count desc: This sorts those aggregated rows so that the resultCode with the highest number of requests appears at the top.
Incorrect:
* The result codes are sorted alphabetically.
* The query lists every individual request along with its result code.
Reference:
https://learn.microsoft.com/en-us/azure/azure-monitor/reference/tables/apprequests
NEW QUESTION # 100
You are developing an Azure Functions app.
All functions in the app meet the following requirements:
Run until either a successful run or until 10 run attempts occur.
Ensure that there are at least 20 seconds between attempts for up to 15 minutes.
You need to configure the host.json file.
How should you complete the code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.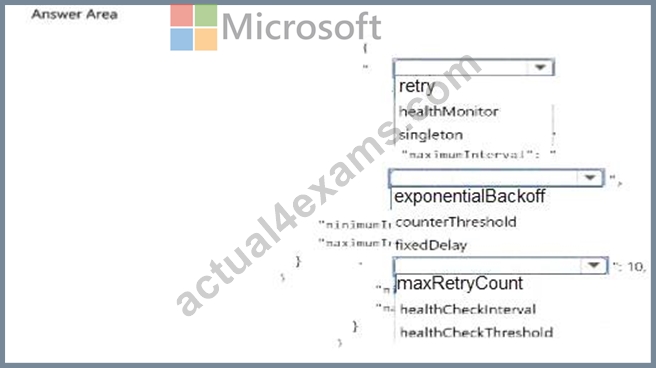
Answer:
Explanation: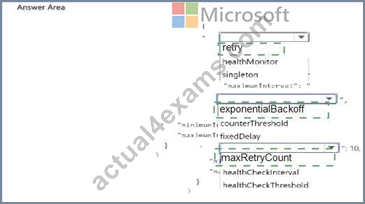
Explanation: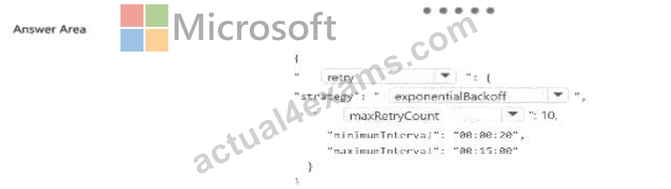
NEW QUESTION # 101
Case Study 2 - Proseware Inc.
Background
Proseware Inc. develops AI-powered knowledge management solutions for enterprise customers.
The company is modernizing its platform to support semantic search, intelligent document retrieval, and real-time partner integrations.
The engineering team uses Python and Azure SDKs. The architecture is being redesigned to support containerized microservices, vector search workloads, and serverless backend processing.
Planned Application Architecture
Microservices are containerized by using Docker.
Code for containerized microservices and Azure Function apps is developed locally but stored in a GitHub repository.
Custom images for containerized microservices are stored in Azure Container Registry (ACR).
Base images are stored in Docker Hub. Custom images must be rebuilt automatically whenever their base images are updated.
Azure Cosmos DB for NoSQL stores documents, metadata, and vector embeddings.
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Azure Container Apps (ACA) apps host backend API services that provide semantic search across Azure Cosmos DB for NoSQL documents. API services process Service Bus messages and update search indexes.
Azure Kubernetes Service (AKS) processes batch vector embedding regeneration for existing Azure Cosmos DB for NoSQL documents (whenever the embedding model is changed).
An extranet-facing containerized webhook allows business partners to submit documents to be processed by internal AI workflows for semantic search and retrieval.
Monitoring
Telemetry generated by Azure resources is sent to Azure Monitor.
A Log Analytics workspace is used to collect ACA apps logs, AKS container logs, and Azure Functions apps logs.
Monitoring of Azure Functions is currently implemented by using Azure Application Insights SDK instrumentation.
Business Requirements
Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Backend API services must scale automatically during business hours.
Cold start delay of backend APIs must be minimized.
Secrets must be stored outside of container images.
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Azure Cosmos DB for NoSQL RU consumption must be minimized.
Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
The partner-facing containerized webhook service must run on Azure App Service.
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
Azure App Service must supply secrets at runtime without relying on external services.
Resources and workloads must be deployed by using Bicep templates through an automated, version-controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Known Issues
RU consumption spikes during vector similarity queries.
You need to deploy Azure Function resources and apps to meet the business and technical requirements. What should you use?
Answer: C
Explanation:
GitHub Actions is the correct tool to use.
Automated Pipeline: It natively automates infrastructure deployment (Bicep) and code compilation through version-controlled workflows.
Eliminates Local Deployments: Workloads are triggered by repository events (like a code merge), removing the need for manual command-line interventions.
Auditability & Repeatability: It keeps a centralized log of every deployment, ensuring a clear audit trail for governance.
Scenario:
Technical Requirements
Resources and workloads must be deployed by using Bicep templates through an automated, version-controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Business Requirements
Development efforts must be minimized.
Reference:
https://github.com/marketplace/actions/azure-functions-action
NEW QUESTION # 102
......
With AI-200 practice test questions you can not only streamline your exam Microsoft AI-200 exam preparation process but also feel confident to pass the challenging AI-200 Exam easily. One of the top features of Microsoft AI-200 valid dumps is their availability in different formats.
AI-200 Valid Test Simulator: https://www.actual4exams.com/AI-200-valid-dump.html