The language in our Databricks-Certified-Data-Engineer-Professional test guide is easy to understand that will make any learner without any learning disabilities, whether you are a student or a in-service staff, whether you are a novice or an experienced staff who has abundant experience for many years. It should be a great wonderful idea to choose our Databricks-Certified-Data-Engineer-Professional Guide Torrent for sailing through the difficult test. On the whole, nothing is unbelievable, to do something meaningful from now, success will not wait for a hesitate person, go and purchase!
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Ingestion & Acquisition | 7% | - Ingest data from diverse sources - Handle incremental and batch data loads - Use Auto Loader and structured streaming |
| Topic 2: Developing Code for Data Processing using Python and SQL | 22% | - Write efficient and maintainable code - Use Databricks-specific libraries and APIs - Implement complex data processing logic |
| Topic 3: Monitoring and Alerting | 10% | - Monitor pipeline performance and health - Track data lineage and metrics - Set up alerts and notifications |
| Topic 4: Data Transformation, Cleansing, and Quality | 10% | - Implement schema evolution and management - Apply data cleansing and validation rules - Enforce data quality standards |
| Topic 5: Data Governance | 7% | - Manage data assets and metadata - Use Unity Catalog for governance - Enforce data policies and standards |
| Topic 6: Ensuring Data Security and Compliance | 10% | - Ensure data privacy and compliance - Implement access control and permissions - Secure data at rest and in transit |
| Topic 7: Data Modelling | 6% | - Design Medallion Architecture - Implement dimensional and relational models - Optimize table design and partitioning |
| Topic 8: Debugging and Deploying | 10% | - Deploy using Asset Bundles, CLI, and APIs - Troubleshoot and debug pipelines - Implement CI/CD and DevOps practices |
| Topic 9: Data Sharing and Federation | 5% | - Implement Lakehouse Federation - Manage cross-platform data access - Use Delta Sharing for secure data sharing |
| Topic 10: Cost & Performance Optimisation | 13% | - Apply cost management best practices - Optimize compute and storage resources - Improve query and pipeline performance |
>> Detailed Databricks-Certified-Data-Engineer-Professional Answers <<
Many people are afraid that after they buy our Databricks-Certified-Data-Engineer-Professional guide torrent they may fail in the exam and the refund procedure will be very complicated. We guarantee to you that the refund process is very simple and only if you provide us the screenshot or the scanning copy of your failure marks we will refund you in full immediately. If you have doubts or problems about our Databricks-Certified-Data-Engineer-Professional Exam Torrent, please contact our online customer service or contact us by mails and we will reply and solve your problem as quickly as we can. We won’t waste your money and your time and if you fail in the exam we will refund you in full immediately at one time. We provide the best Databricks-Certified-Data-Engineer-Professional questions torrent to you and don’t hope to let you feel disappointed.
NEW QUESTION # 126
A data engineer is analyzing a large, partitioned retail dataset in Databricks, where each row represents a sale made by a salesperson. The dataset contains millions of records with the following schema:
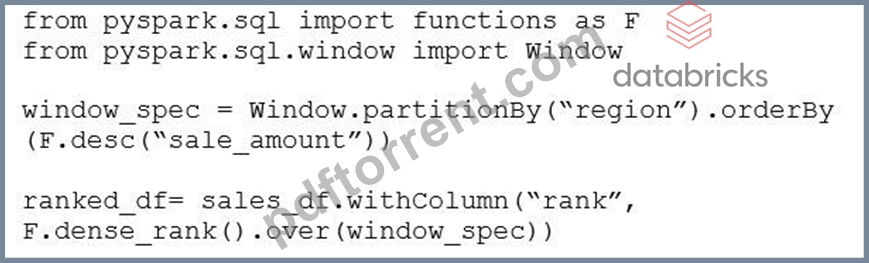
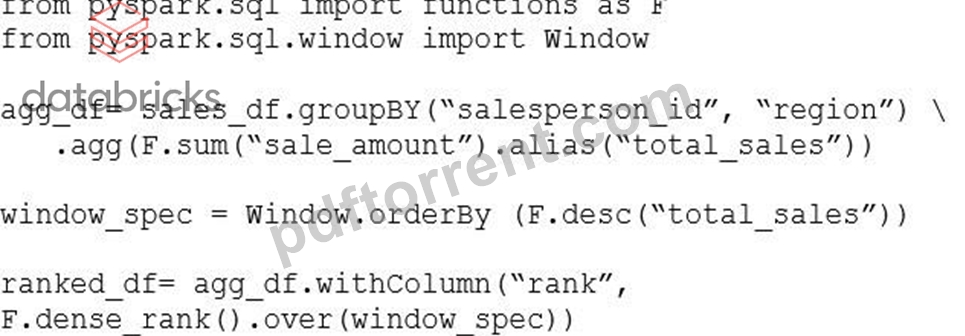
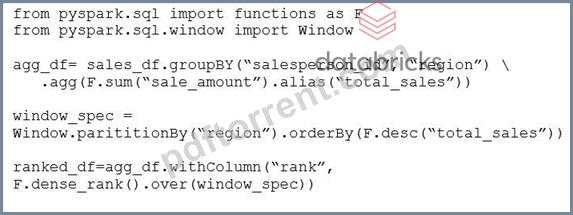
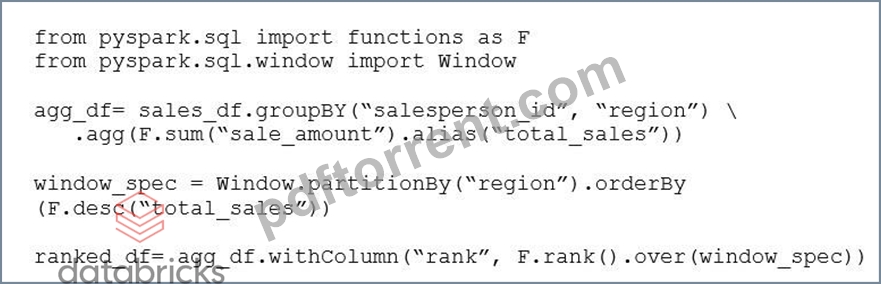
sales_df: [salesperson_id: string, region: string, sale_amount: double, sale_date: date] The data engineer needs to generate a DataFrame that ranks salespeople within each region based on their total cumulative sales, with the highest seller ranked as 1. If multiple salespeople have the same total sales, they should share the same rank.
The data engineer wants to implement this logic using a PySpark window function and the dense_rank () function.
Which code snippet will perform this ranking?
Answer: C
Explanation:
This approach first aggregates sales by salesperson and region to compute total cumulative sales. It then applies a window function partitioned by region and ordered by total sales in descending order, using dense_rank to assign ranks so that salespeople with equal totals share the same rank and the highest total receives rank 1.
NEW QUESTION # 127
A Data Engineer is building a fraud detection pipeline that calls out to Open AI, via a Python library, and needs to include an access token when using the API. Which Databricks CLI command should the Data Engineer use to create the secret?
Answer: B
Explanation:
The Databricks CLI command databricks secrets put-secret <scope> <key> is used to securely store sensitive values such as API access tokens in a secret scope. The secret can then be retrieved at runtime using dbutils.secrets.get(scope, key), ensuring credentials are not hard- coded and remain protected.
NEW QUESTION # 128
The data architect has mandated that all tables in the Lakehouse should be configured as external Delta Lake tables.
Which approach will ensure that this requirement is met?
Answer: C
Explanation:
This is the correct answer because it ensures that this requirement is met. The requirement is that all tables in the Lakehouse should be configured as external Delta Lake tables. An external table is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An external table can be created by using the location keyword to specify the path to an existing directory in a cloud storage system, such as DBFS or S3. By creating external tables, the data engineering team can avoid losing data if they drop or overwrite the table, as well as leverage existing data without moving or copying it.
NEW QUESTION # 129
A data team is implementing an append-only Delta Lake pipeline that processes both batch and streaming data. They want to ensure that schema changes in the source data are automatically incorporated without breaking the pipeline. Which configuration should the team use when writing data to the Delta table?
Answer: D
Explanation:
Setting mergeSchema to true allows Delta Lake to automatically evolve the table schema by incorporating new columns from the source data during writes. This enables append-only pipelines to handle schema changes seamlessly in both batch and streaming workloads without breaking the pipeline.
NEW QUESTION # 130
The data governance team has instituted a requirement that the "user" table containing Personal Identifiable Information (PII) must have the appropriate masking on the SSN column. This means that anyone outside of the HRAdminGroup should see masked social security numbers as ***-**-
****.
The team created a masking function:
What does the data governance team need to do next to achieve this goal?
Answer: D
Explanation:
In Databricks, after creating a masking function, you apply it to a column using ALTER TABLE
<table> ALTER COLUMN <column> SET MASK <mask_function>. The table must already include the column (here, ssn as STRING). This ensures that only users in the HRAdminGroup see the unmasked SSN, while all others see the masked value.
NEW QUESTION # 131
......
Dreaming to be a certified professional in this line? Our Databricks-Certified-Data-Engineer-Professional study materials are befitting choices. We made real test materials in three accessible formats for your inclinations. (PDF, APP, software). Our website is an excellent platform, which provides the questions of these versions of our Databricks-Certified-Data-Engineer-Professional Exam Questions compiled by experts. By browsing this website, all there versions of our Databricks-Certified-Data-Engineer-Professional pratice engine can be chosen according to your taste or preference.
Databricks-Certified-Data-Engineer-Professional Exam Study Guide: https://www.pdftorrent.com/Databricks-Certified-Data-Engineer-Professional-exam-prep-dumps.html