P.S. Free & New SPS-C01 dumps are available on Google Drive shared by Pass4suresVCE: https://drive.google.com/open?id=1v1vEgSVROmymBUrFOeWpGOgl_2uGcjop
The Snowflake SPS-C01 certification exam is one of the top rated career advancement certification exams in the market. This Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam is designed to prove candidates' skills and knowledge levels. By doing this the Snowflake SPS-C01 certificate holders can gain multiple personal and professional benefits. These benefits assist the SPS-C01 Exam holder to pursue a rewarding career in the highly competitive market and achieve their career objectives in a short time period.
| Section | Weight | Objectives |
|---|---|---|
| Data Transformations and DataFrame Operations | 35% | - Persisting transformed data - Filtering, Aggregating, and Joining DataFrames - Window functions - Complex data pipelines - Using built-in functions |
| Snowpark Concepts | 15% | - Snowpark DataFrames and query plans - Snowpark architecture and core concepts - Snowpark Sessions and connection management - Client-side vs. Server-side execution - Stored procedures and conditional logic - Transformations vs. Actions |
| Snowpark API for Python | 30% | - DataFrame creation and manipulation - Establishing connections and session management - Reading and writing data - User-Defined Functions (UDFs) and Stored Procedures - Working with Semi-structured data |
| Performance Optimization and Best Practices | 20% | - Caching strategies - Warehouse sizing for Snowpark - Debugging and explain plans - Query pushdown and optimization - Minimizing data transfer - Vectorized UDFs |
Snowflake SPS-C01 certification exam is very important to every IT people. Getting the certification, you will not be eliminated in our career. What's more, you will get promoted and get more money. Pass4suresVCE Snowflake SPS-C01 dumps are the source of your success. Choosing it, you must arrive at the successful other shore. The reason is simply that Pass4suresVCE Snowflake SPS-C01 Answers Real Questions. SPS-C01 questions are all the latest and the price is the best. Pass4suresVCE Snowflake SPS-C01 certification training suits every IT certification candidates.
NEW QUESTION # 213
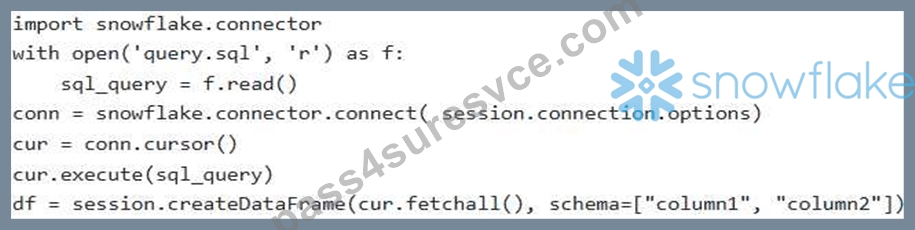
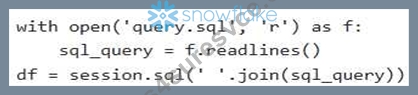
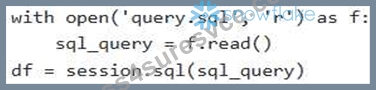
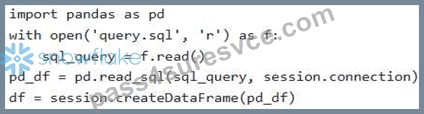
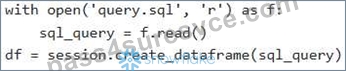
You have a SQL query stored in a file named 'query.sqr which contains several complex analytical calculations. The query depends on a Snowpark 'session' object already established. You want to create a Snowpark DataFrame from the result of this query. Which of the following code snippets achieves this with optimal performance and readability, assuming correct file access permissions?
Answer: C
Explanation:
Option A provides the most straightfomard and efficient approach. It reads the SQL query from the file and directly creates a Snowpark DataFrame using 'session.sql(sql_query)'. Option B introduces Pandas, which is unnecessary and less efficient. Option C uses the Snowflake Connector outside of Snowpark's API, which is generally not the preferred approach. Option D has a non-existent function create_dataframe' , and Option E reads lines separately requiring a join which might be erroneous.
NEW QUESTION # 214
You have written a Snowpark Python function that performs a complex calculation involving user-defined functions (UDFs). When running this function on a large dataset, you encounter a 'PicklingError: Can't pickle ': it's not the same object as main.my function'. What is the MOST likely cause of this error, and how can you resolve it?
Answer: D
Explanation:
Pickling errors in Snowpark often arise when UDFs are defined within local scopes because the serialization process needs to transmit the function to the Snowflake worker nodes. Moving the UDF to the global scope or using 'cloudpickle' allows the function to be correctly serialized. Option B addresses memory issues, C handles dependency problems, D addresses connection issues, and E addresses return type issues, but these are not the MOST likely cause of a PicklingError related to function scope.
NEW QUESTION # 215
You have a Snowpark DataFrame containing sales data with columns 'region' , and 'sales_amount'. You need to calculate the total sales amount for each region and then filter the results to only include regions where the total sales amount is greater than 10000. Which of the following Snowpark code snippets correctly implements this logic?





Answer: B
Explanation:
Option C is correct because it uses the correct Snowpark syntax for grouping by region, summing the sales amount with an alias, and then filtering based on the aliased column. Option A is incorrect as it omits the 'sf.' prefix for 'sum' and 'col' within the 'filter'. Option B uses where' instead of Tilters but correctly aggregates. Option D incorrectly compares a string to a number in the filter. Option E uses a non-standard way of referencing the aggregated column in the 'where' clause.
NEW QUESTION # 216
You are building a Snowpark application to process sensitive data'. To enhance security, you want to leverage ephemeral sessions. Which configurations, passed to 'snowpark.Session.builder.configS , are required and sufficient to create an ephemeral session? Assume your Snowflake environment is properly configured to allow ephemeral sessions.
Answer: B
Explanation:
Ephemeral sessions in Snowflake require that you specify a 'role', 'database', 'schema', and 'warehouse'. These parameters define the context within which the session will operate. Without these parameters, the session cannot be properly established. Although option A set role which is important for setting the context but it is insufficient. Ephemeral sessions are not automatic and require proper configuration.
NEW QUESTION # 217
You have two Snowpark DataFrames, 'dfl' and 'df2', representing customer data'. 'dfl' contains customer IDs and names, while 'df2' contains customer IDs and email addresses. You need to create a new DataFrame that contains all customer IDs, names, and email addresses, including customers present in only one of the DataFrames. Which Snowpark set operation and join type would be most appropriate for achieving this?
Answer: A
Explanation:
Option C is the correct answer. 'UNION' is used to combine the rows from both DataFrames, removing duplicate rows. T-ULL OUTER JOIN' is used to include all rows from both DataFrames, even if there is no matching customer ID in the other DataFrame. The combination of 'UNION' and FULL OUTER JOIN' ensures that all customers and their associated information are included in the resulting DataFrame. The other options would either result in only matching records, missing records, or incorrect combination.
NEW QUESTION # 218
......
We try our best to present you the most useful and efficient SPS-C01 training materials about the test and provide multiple functions and intuitive methods to help the clients learn efficiently. Learning our SPS-C01 useful test guide costs you little time and energy. The passing rate and hit rate are both high thus you will encounter few obstacles to pass the test. You can further understand our SPS-C01 study practice guide after you read the introduction on our web.
SPS-C01 Study Group: https://www.pass4suresvce.com/SPS-C01-pass4sure-vce-dumps.html
DOWNLOAD the newest Pass4suresVCE SPS-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1v1vEgSVROmymBUrFOeWpGOgl_2uGcjop