Die Microsoft AI-103 Zertifizierungsprüfung ist sehr populär in IT-Industrie. Es spielt eine übergreifende Bedeutung für die Leute, die ihre Arbeitsstelle erhöhen wollen. Und es ist auch die Wahl, die Leute klar sehen können. Außerdem dadurch können Sie Ihre Fähigkeit verbessern und mehr verwendbare Technik beherrschen. Damit können Sie Ihre Arbeit besser fertigen und auch anderen Ihre Fähigkeit zeigen.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Implement text analysis and information extraction solutions | 10-15% | - Analyze and extract information
|
| Topic 2: Implement computer vision solutions | 10-15% | - Analyze visual content
|
| Topic 3: Implement agentic solutions | 20-25% | - Manage agent operations
|
| Topic 4: Plan and manage Azure AI solutions | 25-30% | - Manage AI solution lifecycle
|
| Topic 5: Implement generative AI solutions | 25-30% | - Develop generative AI applications
|
Die Microsoft Zertifizierungsprüfung ist jetzt eine sehr populäre Prüfung. Haben Sie diese Microsoft AI-103 Zertifizierung abgelegt? Wenn nein, sollen Sie bitte schneller etwas machen. Es ist sehr wichtig für Sie, diese wichtige Zertifizierung zu besitzen. Wie Microsoft AI-103 Zertifizierungsprüfung hocheffektiv vorzubereiten und nur einmal die Microsoft AI-103 Prüfung zu bestehen spielt heute eine sehr übergreifende Rolle.
58. Frage
You have a Microsoft Foundry project that contains a high-traffic agent.
After a recent update, operational costs increase significantly.
Monitoring confirms that the volume of user traffic to the agent remains unchanged.
You suspect that changes to the request or response characteristics are causing the increase.
You need to identify whether the additional costs are driven by the model input size, the model output size, or expanded tool usage.
Which observability capability should you use?
Antwort: B
Begründung:
The correct capability is token usage . In Microsoft Foundry observability, token consumption is the primary signal for diagnosing model-cost changes when request volume is unchanged. Token usage lets you distinguish whether costs increased because prompts became larger, retrieved or tool-provided context expanded, responses became longer, or agent execution added more model calls. Microsoft Foundry monitoring dashboards track operational metrics such as token consumption, latency, error rates, and quality scores, and the agent monitoring dashboard is specifically intended to help analyze token usage, latency, success rates, and evaluation outcomes for production traffic.
This directly matches the scenario because the issue is not more traffic, but changed request or response characteristics. Input tokens reveal whether the prompt, chat history, grounding data, or tool outputs being sent to the model increased. Output tokens reveal whether the model is generating longer completions.
Expanded tool usage can also increase cost indirectly by adding more tool results, intermediate calls, and context into subsequent model requests; Foundry tracing and observability capture tool usage and token consumption for agent runs.
Evaluation metrics assess response quality and safety, not cost drivers. Latency identifies performance delays, and run success rate measures reliability. Reference topics: Microsoft Foundry observability, agent monitoring dashboard, token consumption, cost analysis, tool usage, and production monitoring.
59. Frage
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have a Microsoft Foundry project that contains an agent. The agent generates summaries from retrieved policy documents.
Users report that some responses omit required regulatory clauses, even when the clauses are present in the retrieved content.
You need to improve response completeness.
Solution: You increase the value of the max_tokens parameter.
Does this meet the goal?
Antwort: B
Begründung:
The solution does not meet the goal. Increasing max_tokens only raises the maximum number of tokens the model is allowed to generate. Microsoft's Azure OpenAI reference defines max_tokens as the maximum number of tokens allowed for the generated answer, and the quota guidance notes that increasing it can help when responses are being truncated.
In this scenario, the problem is not described as output truncation. The required regulatory clauses are already present in the retrieved policy documents, but the agent omits them during summarization. That is a response completeness issue: Microsoft Foundry RAG evaluator guidance defines response completeness as the recall aspect of the response, meaning the response should not miss critical information compared with expected content or ground truth.
A larger token budget might permit a longer answer, but it does not force the model to identify, verify, or include each mandatory clause. It can also increase cost and latency. The appropriate control is a reflection or completeness verification pass that checks the draft against the retrieved policy clauses and regenerates or revises the response when required content is missing. Reference topics: RAG response completeness, model output limits, max_tokens, reflection, and response validation.
60. Frage
You need to recommend a solution to assess the responses generated by Agent1 when the agent uses the product information stored in storage1. The solution must meet the technical requirements.
Antwort: D
Begründung:
A Retrieval Augmented Generation evaluator is required because Agent1 will retrieve product-sheet content and use it as grounding context when generating answers. Foundry RAG evaluators assess both retrieval quality and the quality of the final grounded response. This directly supports Contoso's requirement that answers based on the product sheets be relevant, complete, and accurate.
The appropriate evaluation suite can include groundedness , which determines whether the answer is supported by the retrieved product information without fabrication; relevance , which evaluates whether the answer accurately and completely addresses the customer's question; and response completeness , which measures whether critical expected information is missing. Retrieval evaluators can additionally determine whether the indexing and search pipeline returned context chunks relevant to the query.
A coherence evaluator assesses readability and logical organization but does not establish that claims are supported by storage1. A custom guardrail controls or blocks behavior rather than measuring RAG quality.
Fine-tuning changes model behavior and does not evaluate whether retrieved documentation was selected and used correctly.
The AI-103 Study Guide includes evaluating models and applications for fabrications, relevance, quality, and safety , as well as monitoring grounding quality and retrieval relevance.
61. Frage
Hotspot Question
You are building a model to detect objects in images.
The performance of the model based on training data is shown in the following exhibit.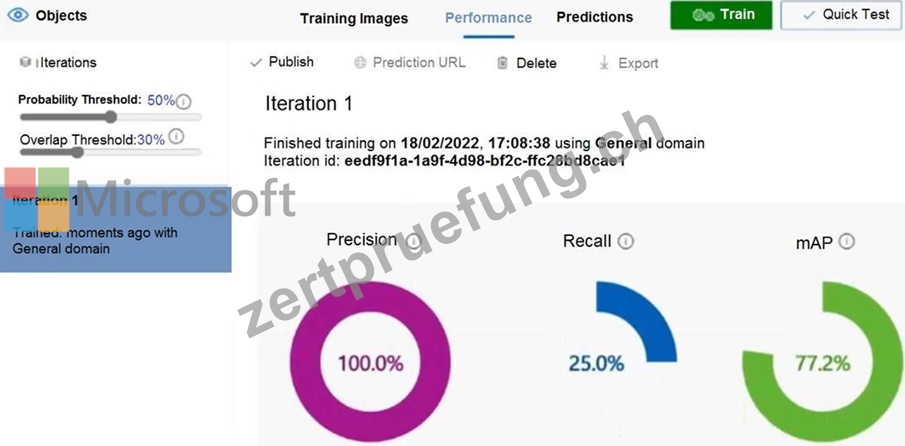
Use the drop-down menus to select the answer choice that completes each statement based on the information presented in the graphic.
NOTE: Each correct selection is worth one point.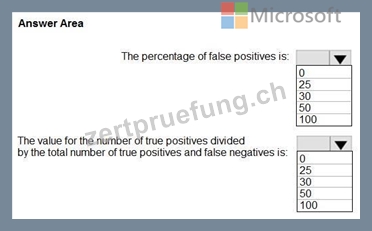
Antwort:
Begründung: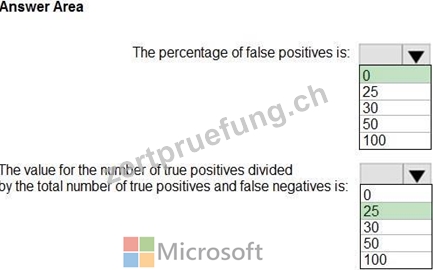
Explanation:
Box 1: 0
The percentage of false positives is 0%.
Because the model made zero incorrect positive predictions, the count and percentage of false positives must be exactly zero.
Box 2: 25
The value for the number of true positives divided by the total number of true positives and false negatives is 25% (or 0.25).
High Precision (100%): Every single object your model detects is correct; it generates zero false alarms.
Low Recall (25%): Your model misses 75% of the actual objects it was supposed to find.
'
Reference:
https://medium.com/grabngoinfo/how-to-evaluate-the-performance-of-a-binary-classification-model-6e7193dcbbf9
62. Frage
You have a custom named entity recognition (NER) project in Azure Language in Foundry Tools for support tickets. The schema for the project contains an entity type named ContactInfo.
In tagged training files, ContactInfo is used for phone numbers, email addresses, and social media handles.
Model evaluation shows low precision for ContactInfo, including false positives in which nearby text is extracted as ContactInfo.
You need to improve the precision of the project.
What should you do before retraining the model?
Antwort: B
Begründung:
To improve the precision of the project before retraining the model, you should replace ContactInfo by using Phone, Email, and SocialMedia entities, and then relabel every matching span.
Reduces Model Confusion: Combining distinct types of data (like phone numbers, emails, and usernames) into a single generic entity (ContactInfo) creates conflicting patterns for the model.
Splitting them allows the model to learn the specific, unique syntax rules of each type.
Eliminates Over-extraction: When an entity is too broad, the model struggles to identify where the entity begins and ends, leading to false positives by grabbing adjacent text. Distinct entities provide sharper, cleaner boundaries.
Reference:
https://learn.microsoft.com/en-us/azure/ai-services/language-service/custom-named-entity-recognition/overview
63. Frage
......
Bereiten Sie jetzt auf Microsoft AI-103 Prüfung? Wenn ja, sind Sie sicherlich ein Mensch mit Ambition. Wir ZertPruefung bemühen uns darum, den Menschen wie Ihnen zu helfen, Ihr Ziel zu erreichen. Die Simulierte-Prüfungssoftware der Microsoft AI-103 von uns enthält große Menge von Prüfungsaufgaben. Wenn Sie unsere Produkte gekauft haben, können Sie noch einjährige kostenlose Aktualisierung der Microsoft AI-103 genießen. Benutzen Sie unsere Software! Dann gibt es gar kein Problem bei des Bestehens der Microsoft AI-103 Prüfung!
AI-103 Fragen Und Antworten: https://www.zertpruefung.ch/AI-103_exam.html