One of the key factors for passing the exam is practice. Candidates must use Databricks Databricks-Certified-Professional-Data-Engineer practice test material to be able to perform at their best on the real exam. This is why Prep4away has developed three formats to assist candidates in their Databricks Databricks-Certified-Professional-Data-Engineer Preparation. These formats include desktop-based Databricks Databricks-Certified-Professional-Data-Engineer practice test software, web-based practice test, and a PDF format.
Databricks Certified Professional Data Engineer (Databricks-Certified-Professional-Data-Engineer) Certification Exam is a highly valued industry certification that validates the skills and expertise of data engineers in using Databricks to build and manage data pipelines. Databricks is a cloud-based data platform that offers a unified analytics engine for big data and machine learning. Databricks Certified Professional Data Engineer Exam certification exam is designed to test the candidate's knowledge of Databricks architecture, data engineering best practices, and data pipeline design and implementation.
Databricks Certified Professional Data Engineer certification exam is intended for data engineers, data architects, and other IT professionals who work with big data technologies. Databricks-Certified-Professional-Data-Engineer Exam covers a wide range of topics, including data ingestion, data transformation, data storage, and data analysis. It also covers the use of Databricks tools and technologies such as Databricks Delta, Databricks Runtime, and Apache Spark.
>> Databricks-Certified-Professional-Data-Engineer Latest Dump <<
In the Desktop Databricks-Certified-Professional-Data-Engineer practice exam software version of Databricks Databricks-Certified-Professional-Data-Engineer practice test is updated and real. The software is useable on Windows-based computers and laptops. There is a demo of the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) practice exam which is totally free. Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) practice test is very customizable and you can adjust its time and number of questions.
Databricks Certified Professional Data Engineer exam is a vendor-neutral certification, meaning it is not specific to any particular technology or product. This makes it an excellent choice for data engineers who work with different big data technologies and want to demonstrate their knowledge of Databricks. Databricks Certified Professional Data Engineer Exam certification exam is recognized globally, and it is highly valued by organizations that use Databricks for their big data processing needs.
NEW QUESTION # 143
What is the main difference between the bronze layer and silver layer in a medallion architecture?
Answer: C
Explanation:
Explanation
Medallion Architecture - Databricks
Exam focus: Please review the below image and understand the role of each layer(bronze, silver, gold) in medallion architecture, you will see varying questions targeting each layer and its purpose.
Sorry I had to add the watermark some people in Udemy are copying my content.
A diagram of a house Description automatically generated with low confidence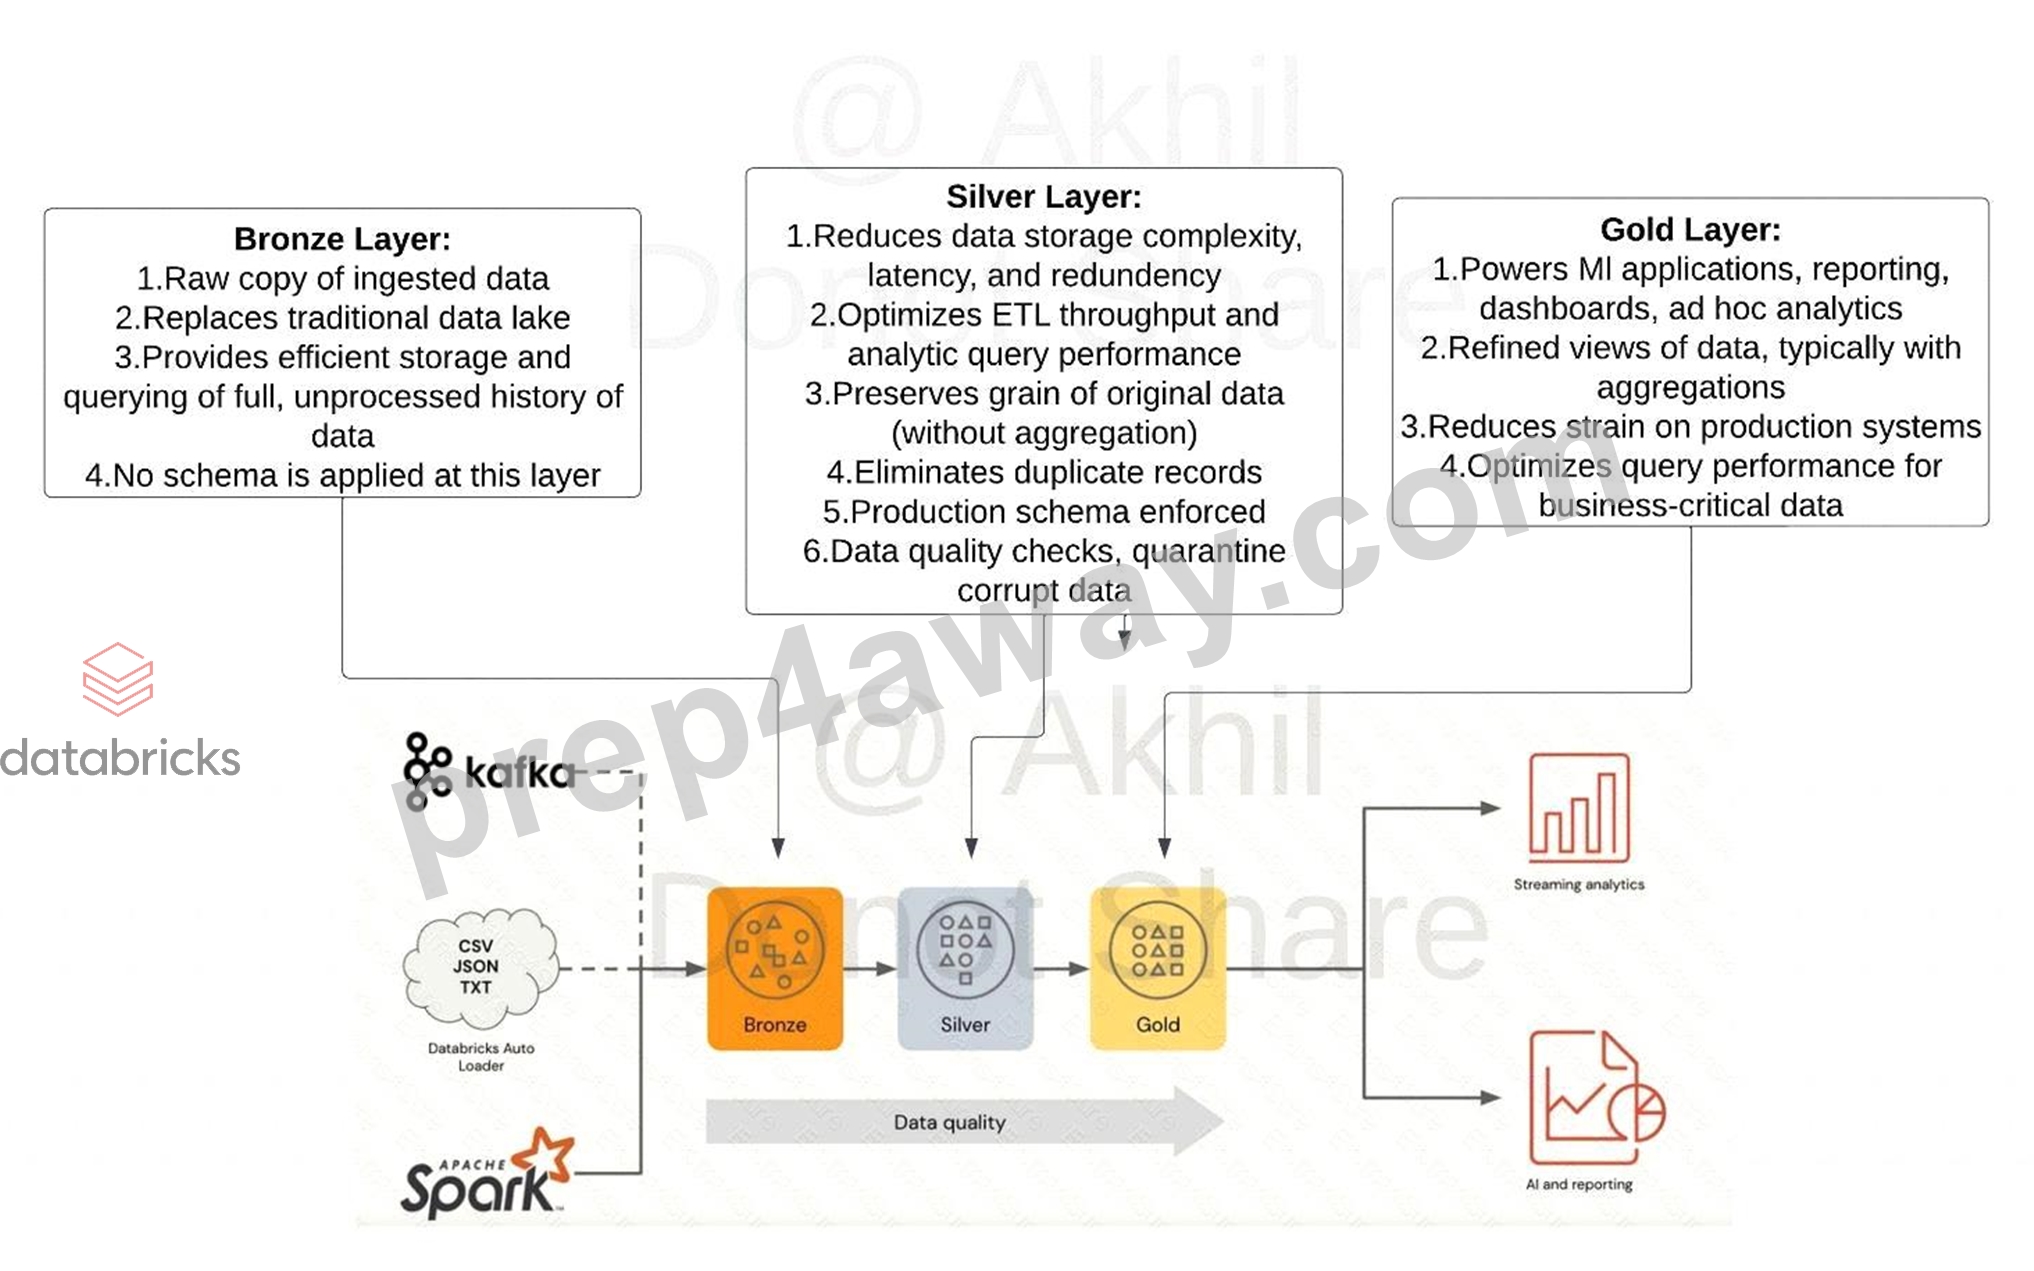
NEW QUESTION # 144
An analytics team wants to run a short-term experiment in Databricks SQL on the customer transactions Delta table (about 20 billion records) created by the data engineering team. Which strategy should the data engineering team use to ensure minimal downtime and no impact on the ongoing ETL processes?
Answer: B
Explanation:
* Exact extract: "A shallow clone creates a copy of the metadata that references the source data files; it is fast and inexpensive."
* Exact extract: "A deep clone copies the data."
References: Delta Lake cloning (shallow vs deep).
NEW QUESTION # 145
A junior data engineer is working to implement logic for a Lakehouse table named silver_device_recordings. The source data contains 100 unique fields in a highly nested JSON structure.
The silver_device_recordings table will be used downstream for highly selective joins on a number of fields, and will also be leveraged by the machine learning team to filter on a handful of relevant fields, in total, 15 fields have been identified that will often be used for filter and join logic.
The data engineer is trying to determine the best approach for dealing with these nested fields before declaring the table schema.
Which of the following accurately presents information about Delta Lake and Databricks that may Impact their decision-making process?
Answer: D
Explanation:
Delta Lake, built on top of Parquet, enhances query performance through data skipping, which is based on the statistics collected for each file in a table. For tables with a large number of columns, Delta Lake by default collects and stores statistics only for the first 32 columns. These statistics include min/max values and null counts, which are used to optimize query execution by skipping irrelevant data files. When dealing with highly nested JSON structures, understanding this behavior is crucial for schema design, especially when determining which fields should be flattened or prioritized in the table structure to leverage data skipping efficiently for performance optimization.
Reference: Databricks documentation on Delta Lake optimization techniques, including data skipping and statistics collection (https://docs.databricks.com/delta/optimizations/index.html).
NEW QUESTION # 146
A data engineer is creating a data ingestion pipeline to understand where customers are taking their rented bicycles during use. The engineer noticed that, over time, data being transmitted from the bicycle sensors fail to include key details like latitude and longitude. Downstream analysts need both the clean records and the quarantined records available for separate processing.
The data engineer already has this code:
import dlt
from pyspark.sql.functions import expr
rules = {
"valid_lat": "(lat IS NOT NULL)",
"valid_long": "(long IS NOT NULL)"
}
quarantine_rules = "NOT({})".format(" AND ".join(rules.values()))
@dlt.view
def raw_trips_data():
return spark.readStream.table("ride_and_go.telemetry.trips")
How should the data engineer meet the requirements to capture good and bad data?
Answer: C
Explanation:
The requirement is that both valid (good) and invalid (bad) records must be captured and available separately for downstream processing. Invalid records should not simply be dropped; they must be quarantined in a dedicated table.
In Databricks Lakeflow Declarative Pipelines (DLT), this is achieved by creating separate output tables:
One table for valid records (Silver table) that pass the expectations.
Another quarantine table that explicitly captures records failing the expectations.
Option A correctly implements this by:
Declaring a DLT table trips_data_quarantine.
Using .filter(expr(quarantine_rules)) to isolate invalid records (records where latitude or longitude is NULL).
This ensures analysts can query both good records (from the main Silver pipeline table) and bad records (from the quarantine table).
Why not the others?
B: Uses @dlt.expect_or_drop, which drops invalid records instead of quarantining them. This violates the requirement that quarantined data should be available.
C: Same as B, but applies expectations in bulk with expect_all_or_drop. Again, bad data is dropped, not quarantined.
D: Adds an is_quarantined flag in the same table. While it marks bad records, it does not separate them into a distinct quarantine table as required by the business use case.
Therefore, Option A is the only solution aligned with Databricks documentation for quarantining invalid data into a dedicated table while keeping valid data in the main pipeline.
NEW QUESTION # 147
The data engineering team has configured a Databricks SQL query and alert to monitor the values in a Delta Lake table. The recent_sensor_recordings table contains an identifying sensor_id alongside the timestamp and temperature for the most recent 5 minutes of recordings.
The below query is used to create the alert: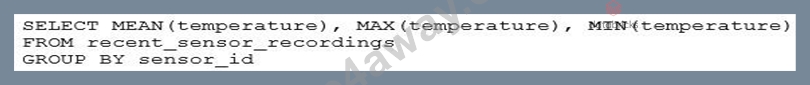
The query is set to refresh each minute and always completes in less than 10 seconds. The alert is set to trigger when mean (temperature) > 120. Notifications are triggered to be sent at most every 1 minute.
If this alert raises notifications for 3 consecutive minutes and then stops, which statement must be true?
Answer: C
Explanation:
This is the correct answer because the query is using a GROUP BY clause on the sensor_id column, which means it will calculate the mean temperature for each sensor separately. The alert will trigger when the mean temperature for any sensor is greater than 120, which means at least one sensor had an average temperature above 120 for three consecutive minutes. The alert will stop when the mean temperature for all sensors drops below 120. Verified Reference: [Databricks Certified Data Engineer Professional], under "SQL Analytics" section; Databricks Documentation, under "Alerts" section.
NEW QUESTION # 148
......
Valid Databricks-Certified-Professional-Data-Engineer Test Materials: https://www.prep4away.com/Databricks-certification/braindumps.Databricks-Certified-Professional-Data-Engineer.ete.file.html