2026 Latest TorrentExam MLA-C01 PDF Dumps and MLA-C01 Exam Engine Free Share: https://drive.google.com/open?id=11RfxKubXM7NE4AZTieyBfocMukQh75o9
Getting the AWS Certified Machine Learning Engineer - Associate (MLA-C01) certification is the way to go if you're planning to get into Amazon or want to start earning money quickly. Success in the AWS Certified Machine Learning Engineer - Associate (MLA-C01) exam of this credential plays an essential role in the validation of your skills so that you can crack an interview or get a promotion in an Amazon company. Many people are attempting the AWS Certified Machine Learning Engineer - Associate (MLA-C01) test nowadays because its importance is growing rapidly. The product of TorrentExam has many different premium features that help you use this product with ease. The study material has been made and updated after consulting with a lot of professionals and getting customers' reviews.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
>> MLA-C01 Valid Braindumps <<
If you are looking to advance in the fast-paced and technological world, TorrentExam is here to help you achieve this aim. TorrentExam provides you with the excellent Amazon MLA-C01 practice exam, which will make your dream come true of passing the AWS Certified Machine Learning Engineer - Associate certification exam on the first attempt.
NEW QUESTION # 144
A machine learning engineer is preparing a data frame for a supervised learning task with the Amazon SageMaker Linear Learner algorithm. The ML engineer notices the target label classes are highly imbalanced and multiple feature columns contain missing values. The proportion of missing values across the entire data frame is less than 5%.
What should the ML engineer do to minimize bias due to missing values?
Answer: D
Explanation:
Use supervised learning to predict missing values based on the values of other features. Different supervised learning approaches might have different performances, but any properly implemented supervised learning approach should provide the same or better approximation than mean or median approximation, as proposed in responses A and C. Supervised learning applied to the imputation of missing values is an active field of research.
NEW QUESTION # 145
Hotspot Question
A company needs to train an ML model that will use historical transaction data to predict customer behavior.
Select the correct AWS service from the following list to perform each task on the data. Each service should be selected one time or not at all. (Select three.)
- Amazon Athena
- AWS Glue
- Amazon Kinesis Data Streams
- Amazon S3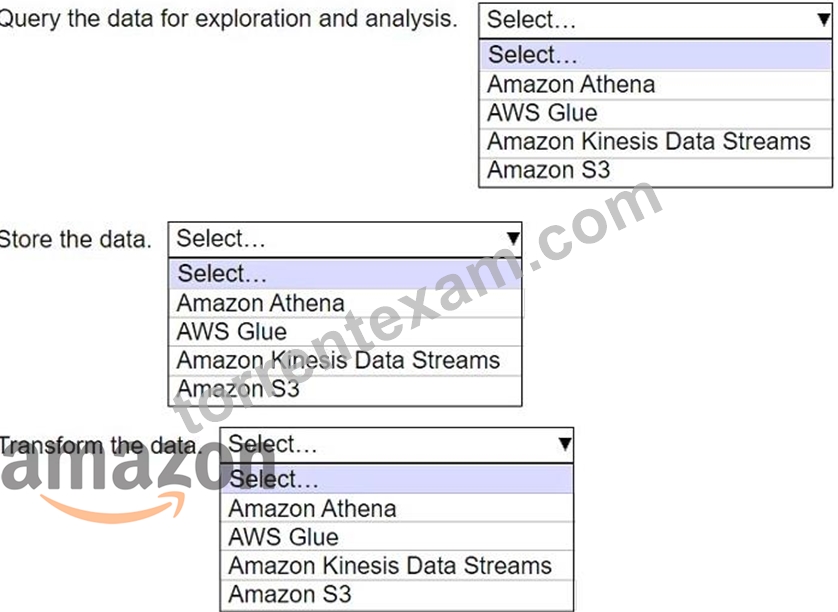
Answer:
Explanation: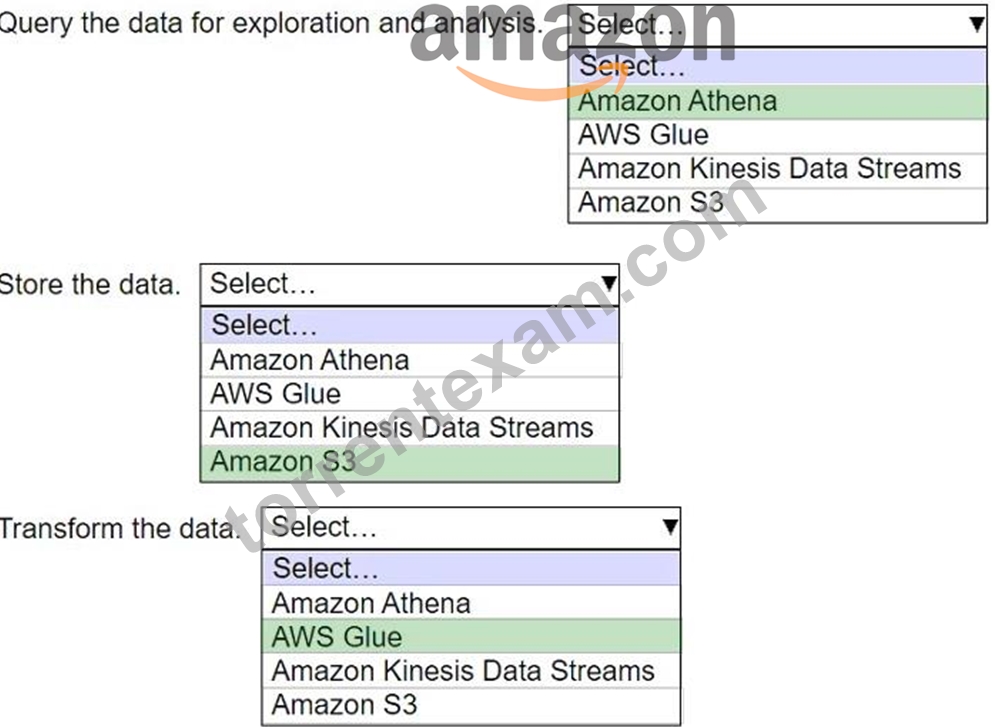
NEW QUESTION # 146
A company has implemented a data ingestion pipeline for sales transactions from its ecommerce website. The company uses Amazon Data Firehose to ingest data into Amazon OpenSearch Service. The buffer interval of the Firehose stream is set for 60 seconds. An OpenSearch linear model generates real-time sales forecasts based on the data and presents the data in an OpenSearch dashboard.
The company needs to optimize the data ingestion pipeline to support sub-second latency for the real-time dashboard.
Which change to the architecture will meet these requirements?
Answer: B
Explanation:
The primary requirement in this scenario is achieving sub-second latency for a real-time analytics dashboard powered by Amazon OpenSearch Service. The current architecture uses Amazon Data Firehose, which buffers incoming records based on time or size before delivering them to the destination. A buffer interval of
60 seconds introduces unavoidable latency, making it unsuitable for near-real-time or sub-second use cases.
According to AWS documentation, reducing or eliminating buffering in Firehose is the correct approach when low-latency ingestion is required. Setting the Firehose buffer interval to zero seconds forces Firehose to deliver records as soon as they are received. Additionally, tuning the PutRecordBatch batch size allows efficient ingestion while minimizing delivery delay. This configuration is explicitly recommended for latency- sensitive analytics pipelines.
Option B is incorrect because AWS DataSync is designed for batch-oriented data transfers between storage systems, not real-time streaming. Enhanced fan-out consumers are a feature of Amazon Kinesis Data Streams, not DataSync, making this option invalid.
Option C directly contradicts the requirement. Increasing the buffer interval from 60 seconds to 120 seconds would further increase latency and degrade real-time performance.
Option D is also incorrect because Amazon SQS is a message queueing service, not a streaming ingestion service optimized for indexing data into OpenSearch with minimal latency. Using SQS would add additional processing layers and would not inherently provide sub-second ingestion into OpenSearch.
Therefore, using zero buffering in the Firehose stream and tuning the PutRecordBatch batch size is the only change that aligns with AWS best practices for achieving sub-second latency in real-time analytics pipelines.
NEW QUESTION # 147
A company has an ML model that is deployed to an Amazon SageMaker AI endpoint for real-time inference.
The company needs to deploy a new model. The company must compare the new model's performance to the currently deployed model's performance before shifting all traffic to the new model.
Which solution will meet these requirements with the LEAST operational effort?
Answer: B
Explanation:
AWS recommends shadow testing to evaluate a new model against a production model with minimal operational overhead. Using production variants on a single SageMaker endpoint allows traffic to be routed to multiple models without managing additional endpoints.
With a shadow variant, the new model receives a copy of live traffic but does not affect production responses.
Performance metrics such as latency, accuracy, and error rates can be compared directly against the current model using Amazon CloudWatch metrics. This approach is natively supported by Amazon SageMaker Endpoints.
Options A, B, and D introduce unnecessary complexity by requiring additional endpoints, traffic routing infrastructure, or custom code.
Therefore, deploying the new model as a shadow variant on the same endpoint is the most efficient solution.
NEW QUESTION # 148
Case Study
An ML engineer is developing a fraud detection model on AWS. The training dataset includes transaction logs, customer profiles, and tables from an on-premises MySQL database. The transaction logs and customer profiles are stored in Amazon S3.
The dataset has a class imbalance that affects the learning of the model's algorithm. Additionally, many of the features have interdependencies. The algorithm is not capturing all the desired underlying patterns in the data.
The training dataset includes categorical data and numerical data. The ML engineer must prepare the training dataset to maximize the accuracy of the model.
Which action will meet this requirement with the LEAST operational overhead?
Answer: B
NEW QUESTION # 149
......
The Amazon MLA-C01 exam questions are designed and verified by experienced and qualified Amazon MLA-C01 exam trainers. They work together and share their expertise to maintain the top standard of Amazon MLA-C01 Exam Practice test. So you can get trust on Amazon MLA-C01 exam questions and start preparing today.
MLA-C01 Practice Tests: https://www.torrentexam.com/MLA-C01-exam-latest-torrent.html
BTW, DOWNLOAD part of TorrentExam MLA-C01 dumps from Cloud Storage: https://drive.google.com/open?id=11RfxKubXM7NE4AZTieyBfocMukQh75o9