Databricks Databricks-Certified-Data-Analyst-Associate인증시험대비덤프공부, Databricks-Certified-Data-Analyst-Associate Vce
참고: ITDumpsKR에서 Google Drive로 공유하는 무료, 최신 Databricks-Certified-Data-Analyst-Associate 시험 문제집이 있습니다: https://drive.google.com/open?id=1S6CwycQNLa-1jxl4IY9U3wUItrTX_n5z
IT업계에 종사하는 분이라면 국제적으로 인정받는 IT인증시험에 도전하여 자격증을 취득하셔야 합니다. ITDumpsKR의 Databricks인증 Databricks-Certified-Data-Analyst-Associate덤프는 이 시험에 참가한 IT인사들의 검증을 받은 최신 시험대비 공부자료입니다. ITDumpsKR의 Databricks인증 Databricks-Certified-Data-Analyst-Associate덤프로 시험을 쉽게 패스하여 자격증을 취득하면 승진이나 연봉인상에 많은 편리를 가져다드립니다. 저희는 항상 여러분들의 곁을 지켜줄것입니다.
Databricks Databricks-Certified-Data-Analyst-Associate Exam Overview:
| Certification Vendor: | Databricks |
|---|
| Exam Name: | Databricks Certified Data Analyst Associate Exam |
|---|
| Exam Number: | Databricks-Certified-Data-Analyst-Associate |
|---|
| Related Certifications: | Databricks Certified Machine Learning Associate
Databricks Certified Data Engineer Associate |
|---|
| Certificate Validity Period: | 2 years |
|---|
| Real Exam Qty: | 45 |
|---|
| Exam Format: | Multiple Choice |
|---|
| Exam Duration: | 90 minutes |
|---|
| Passing Score: | 70% |
|---|
| Exam Price: | $200 USD |
|---|
| Available Languages: | English |
|---|
| Sample Questions: | Databricks Databricks-Certified-Data-Analyst-Associate Sample Questions |
|---|
| Exam Way: | Online proctored or test center proctored |
|---|
| Pre Condition: | No formal prerequisites. Databricks recommends 6+ months of hands-on experience with data analysis and Databricks SQL. |
|---|
| Official Syllabus URL: | https://www.databricks.com/learn/certification/data-analyst-associate |
|---|
>> Databricks Databricks-Certified-Data-Analyst-Associate인증시험대비 덤프공부 <<
최신버전 Databricks-Certified-Data-Analyst-Associate인증시험대비 덤프공부 시험덤프자료
ITDumpsKR의 높은 적중율을 보장하는 최고품질의Databricks Databricks-Certified-Data-Analyst-Associate덤프는 최근Databricks Databricks-Certified-Data-Analyst-Associate실제인증시험에 대비하여 제작된것으로 엘리트한 전문가들이 실제시험문제를 분석하여 답을 작성한 만큼 시험문제 적중율이 아주 높습니다. ITDumpsKR의 Databricks Databricks-Certified-Data-Analyst-Associate 덤프는Databricks Databricks-Certified-Data-Analyst-Associate시험을 패스하는데 가장 좋은 선택이기도 하고Databricks Databricks-Certified-Data-Analyst-Associate인증시험을 패스하기 위한 가장 힘이 되어드리는 자료입니다.
Databricks Databricks-Certified-Data-Analyst-Associate 시험요강:
| 주제 | 소개 |
|---|
| 주제 1 | - Data Visualization and Dashboarding: Sub-topics of this topic are about of describing how notifications are sent, how to configure and troubleshoot a basic alert, how to configure a refresh schedule, the pros and cons of sharing dashboards, how query parameters change the output, and how to change the colors of all of the visualizations. It also discusses customized data visualizations, visualization formatting, Query Based Dropdown List, and the method for sharing a dashboard.
|
| 주제 2 | - Data Management: The topic describes Delta Lake as a tool for managing data files, Delta Lake manages table metadata, benefits of Delta Lake within the Lakehouse, tables on Databricks, a table owner’s responsibilities, and the persistence of data. It also identifies management of a table, usage of Data Explorer by a table owner, and organization-specific considerations of PII data. Lastly, the topic it explains how the LOCATION keyword changes, usage of Data Explorer to secure data.
|
| 주제 3 | - SQL in the Lakehouse: It identifies a query that retrieves data from the database, the output of a SELECT query, a benefit of having ANSI SQL, access, and clean silver-level data. It also compares and contrasts MERGE INTO, INSERT TABLE, and COPY INTO. Lastly, this topic focuses on creating and applying UDFs in common scaling scenarios.
|
| 주제 4 | - Databricks SQL: This topic discusses key and side audiences, users, Databricks SQL benefits, complementing a basic Databricks SQL query, schema browser, Databricks SQL dashboards, and the purpose of Databricks SQL endpoints
- warehouses. Furthermore, the delves into Serverless Databricks SQL endpoint
- warehouses, trade-off between cluster size and cost for Databricks SQL endpoints
- warehouses, and Partner Connect. Lastly it discusses small-file upload, connecting Databricks SQL to visualization tools, the medallion architecture, the gold layer, and the benefits of working with streaming data.
|
| 주제 5 | - Analytics applications: It describes key moments of statistical distributions, data enhancement, and the blending of data between two source applications. Moroever, the topic also explains last-mile ETL, a scenario in which data blending would be beneficial, key statistical measures, descriptive statistics, and discrete and continuous statistics.
|
최신 Data Analyst Databricks-Certified-Data-Analyst-Associate 무료샘플문제 (Q48-Q53):
질문 # 48
A data analyst runs the following command:
INSERT INTO stakeholders.suppliers TABLE stakeholders.new_suppliers;
What is the result of running this command?
- A. The suppliers table now contains the data from the new suppliers table, and the new suppliers table now contains the data from the suppliers table.
- B. The suppliers table now contains both the data it had before the command was run and the data from the new suppliers table, and any duplicate data is deleted.
- C. The suppliers table now contains only the data from the new suppliers table.
- D. The command fails because it is written incorrectly.
- E. The suppliers table now contains both the data it had before the command was run and the data from the new suppliers table, including any duplicate data.
정답:D
설명:
The command INSERT INTO stakeholders.suppliers TABLE stakeholders.new_suppliers is not a valid syntax for inserting data into a table in Databricks SQL. According to the documentation12, the correct syntax for inserting data into a table is either:
* INSERT { OVERWRITE | INTO } [ TABLE ] table_name [ PARTITION clause ] [ ( column_name [,
...] ) | BY NAME ] query
* INSERT INTO [ TABLE ] table_name REPLACE WHERE predicate query
The command in the question is missing the OVERWRITE or INTO keyword, and the query part that specifies the source of the data to be inserted. The TABLE keyword is optional and can be omitted.
The PARTITION clause and the column list are also optional and depend on the table schema and the data source. Therefore, the command in the question will fail with a syntax error.
INSERT | Databricks on AWS
INSERT - Azure Databricks - Databricks SQL | Microsoft Learn
질문 # 49
Data professionals with varying responsibilities use the Databricks Lakehouse Platform Which role in the Databricks Lakehouse Platform use Databricks SQL as their primary service?
- A. Data engineer
- B. Business analyst
- C. Platform architect
- D. Data scientist
정답:B
설명:
In the Databricks Lakehouse Platform, business analysts primarily utilize Databricks SQL as their main service. Databricks SQL provides an environment tailored for executing SQL queries, creating visualizations, and developing dashboards, which aligns with the typical responsibilities of business analysts who focus on interpreting data to inform business decisions. While data scientists and data engineers also interact with the Databricks platform, their primary tools and services differ; data scientists often engage with machine learning frameworks and notebooks, whereas data engineers focus on data pipelines and ETL processes. Platform architects are involved in designing and overseeing the infrastructure and architecture of the platform. Therefore, among the roles listed, business analysts are the primary users of Databricks SQL.
질문 # 50
Which of the following statements describes descriptive statistics?
- A. A branch of statistics that uses summary statistics to quantitatively describe and summarize data.
- B. A branch of statistics that uses a variety of data analysis techniques to infer properties of an underlying distribution of probability.
- C. A branch of statistics that uses summary statistics to categorically describe and summarize data.
- D. A branch of statistics that uses quantitative variables that must take on a finite or countably infinite set of values.
- E. A branch of statistics that uses quantitative variables that must take on an uncountable set of values.
정답:A
설명:
Descriptive statistics is a branch of statistics that uses summary statistics, such as mean, median, mode, standard deviation, range, frequency, or correlation, to quantitatively describe and summarize data. Descriptive statistics can help data analysts understand the main features of a data set, such as its central tendency, variability, or distribution. Descriptive statistics can also help data analysts visualize data using charts, graphs, or tables. Descriptive statistics do not make any inferences or predictions about the data, unlike inferential statistics, which use data analysis techniques to infer properties of an underlying population or probability distribution from a sample of data. Reference: Databricks - Descriptive Statistics, Databricks - Data Analysis with Databricks SQL
질문 # 51
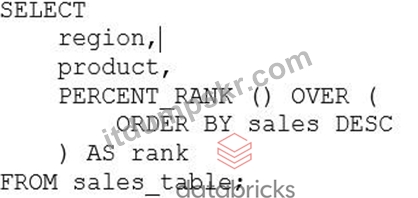
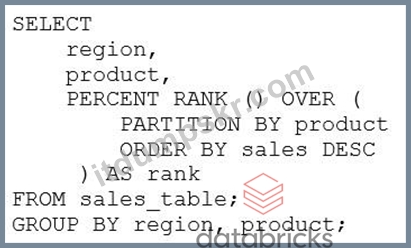
A data analyst has been asked to use the below table sales_table to get the percentage rank of products within region by the sales:
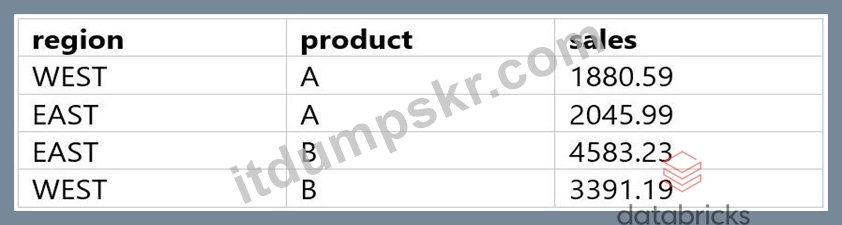
The result of the query should look like this:
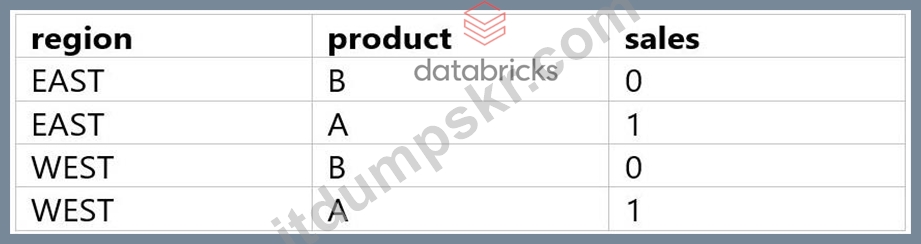
Which of the following queries will accomplish this task?
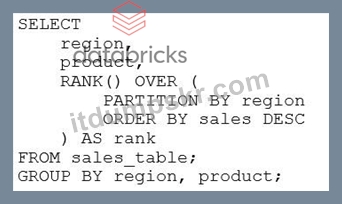
A)
B)
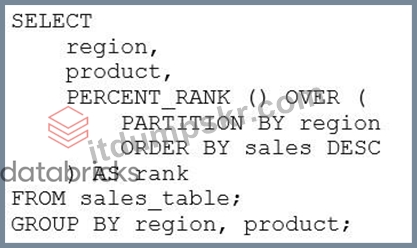
C)
- A. Option B
- B. Option A
- C. Option D
- D. Option C
정답:A
설명:
The correct query to get the percentage rank of products within region by the sales is option B. This query uses the PERCENT_RANK() window function to calculate the relative rank of each product within each region based on the sales amount. The window function is partitioned by region and ordered by sales in descending order. The result is aliased as rank and displayed along with the region and product columns. The other options are incorrect because:
A) Option A uses the RANK() window function instead of the PERCENT_RANK() function. The RANK() function returns the rank of each row within the partition, but not the percentage rank. Also, the query does not have a GROUP BY clause, which is required for aggregate functions like SUM().
C) Option C uses the DENSE_RANK() window function instead of the PERCENT_RANK() function. The DENSE_RANK() function returns the rank of each row within the partition, but not the percentage rank. Also, the query does not have a GROUP BY clause, which is required for aggregate functions like SUM().
D) Option D uses the ROW_NUMBER() window function instead of the PERCENT_RANK() function. The ROW_NUMBER() function returns the sequential number of each row within the partition, but not the percentage rank. Also, the query does not have a GROUP BY clause, which is required for aggregate functions like SUM(). Reference:
1: PERCENT_RANK (Transact-SQL)
2: Window functions in Databricks SQL
3: Databricks Certified Data Analyst Associate Exam Guide
질문 # 52
The stakeholders.customers table has 15 columns and 3,000 rows of data. The following command is run:
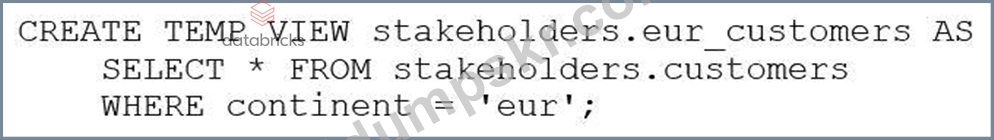
After running SELECT * FROM stakeholders.eur_customers, 15 rows are returned. After the command executes completely, the user logs out of Databricks.
After logging back in two days later, what is the status of the stakeholders.eur_customers view?
- A. The view has been dropped.
- B. The view remains available but attempting to SELECT from it results in an empty result set because data in views are automatically deleted after logging out.
- C. The view has been converted into a table.
- D. The view remains available and SELECT * FROM stakeholders.eur_customers will execute correctly.
- E. The view is not available in the metastore, but the underlying data can be accessed with SELECT * FROM delta. `stakeholders.eur_customers`.
정답:D
설명:
In Databricks, a view is a saved SQL query definition that references existing tables or other views. Once created, a view remains persisted in the metastore (such as Unity Catalog or Hive Metastore) until it is explicitly dropped.
Key points:
* Views do not store data themselves but reference data from underlying tables.
* Logging out or being inactive does not delete or alter views.
* Unless a user or admin explicitly drops the view or the underlying data/table is deleted, the view continues to function as expected.
* Therefore, after logging back in-even days later-a user can still run SELECT * FROM stakeholders.
eur_customers, and it will return the same data (provided the underlying table hasn't changed).
Reference: Views - Databricks Documentation
질문 # 53
......
Databricks-Certified-Data-Analyst-Associate Vce: https://www.itdumpskr.com/Databricks-Certified-Data-Analyst-Associate-exam.html
- Databricks-Certified-Data-Analyst-Associate인증시험대비 덤프공부 덤프공부자료 🥥 ➽ www.itdumpskr.com 🢪에서➽ Databricks-Certified-Data-Analyst-Associate 🢪를 검색하고 무료로 다운로드하세요Databricks-Certified-Data-Analyst-Associate 100%시험패스 자료
- Databricks-Certified-Data-Analyst-Associate시험패스 가능한 인증덤프자료 📠 Databricks-Certified-Data-Analyst-Associate최신덤프 🌒 Databricks-Certified-Data-Analyst-Associate공부자료 🚨 오픈 웹 사이트⇛ www.itdumpskr.com ⇚검색➡ Databricks-Certified-Data-Analyst-Associate ️⬅️무료 다운로드Databricks-Certified-Data-Analyst-Associate합격보장 가능 시험
- Databricks-Certified-Data-Analyst-Associate최신 업데이트 덤프문제 🍕 Databricks-Certified-Data-Analyst-Associate최신 시험 최신 덤프자료 🐤 Databricks-Certified-Data-Analyst-Associate예상문제 🍙 [ kr.fast2test.com ]을(를) 열고▛ Databricks-Certified-Data-Analyst-Associate ▟를 입력하고 무료 다운로드를 받으십시오Databricks-Certified-Data-Analyst-Associate최신 업데이트 덤프문제
- Databricks-Certified-Data-Analyst-Associate최신덤프 🍚 Databricks-Certified-Data-Analyst-Associate시험패스 가능한 인증덤프자료 ⬛ Databricks-Certified-Data-Analyst-Associate최신 덤프자료 🗯 무료로 쉽게 다운로드하려면「 www.itdumpskr.com 」에서➠ Databricks-Certified-Data-Analyst-Associate 🠰를 검색하세요Databricks-Certified-Data-Analyst-Associate최신버전 시험대비 공부자료
- Databricks-Certified-Data-Analyst-Associate높은 통과율 인기 덤프문제 👟 Databricks-Certified-Data-Analyst-Associate 100%시험패스 자료 🧁 Databricks-Certified-Data-Analyst-Associate최신버전 시험대비 공부자료 👣 오픈 웹 사이트➥ www.itdumpskr.com 🡄검색“ Databricks-Certified-Data-Analyst-Associate ”무료 다운로드Databricks-Certified-Data-Analyst-Associate공부자료
- Databricks-Certified-Data-Analyst-Associate인증시험덤프 🐾 Databricks-Certified-Data-Analyst-Associate합격보장 가능 덤프공부 🌶 Databricks-Certified-Data-Analyst-Associate예상문제 🍑 시험 자료를 무료로 다운로드하려면▷ www.itdumpskr.com ◁을 통해《 Databricks-Certified-Data-Analyst-Associate 》를 검색하십시오Databricks-Certified-Data-Analyst-Associate완벽한 덤프
- 인기자격증 Databricks-Certified-Data-Analyst-Associate인증시험대비 덤프공부 덤프문제 🏇 ▶ Databricks-Certified-Data-Analyst-Associate ◀를 무료로 다운로드하려면☀ www.dumptop.com ️☀️웹사이트를 입력하세요Databricks-Certified-Data-Analyst-Associate최신 덤프자료
- Databricks-Certified-Data-Analyst-Associate최신 시험 최신 덤프자료 🧁 Databricks-Certified-Data-Analyst-Associate최고품질 덤프공부자료 ↕ Databricks-Certified-Data-Analyst-Associate 100%시험패스 자료 🎏 무료로 쉽게 다운로드하려면【 www.itdumpskr.com 】에서「 Databricks-Certified-Data-Analyst-Associate 」를 검색하세요Databricks-Certified-Data-Analyst-Associate인증시험덤프
- Databricks-Certified-Data-Analyst-Associate퍼펙트 인증공부 🕚 Databricks-Certified-Data-Analyst-Associate적중율 높은 시험대비덤프 🔜 Databricks-Certified-Data-Analyst-Associate시험패스 가능한 인증덤프자료 ✔️ 지금《 www.itdumpskr.com 》에서➡ Databricks-Certified-Data-Analyst-Associate ️⬅️를 검색하고 무료로 다운로드하세요Databricks-Certified-Data-Analyst-Associate완벽한 덤프
- Databricks-Certified-Data-Analyst-Associate적중율 높은 시험대비덤프 🤏 Databricks-Certified-Data-Analyst-Associate적중율 높은 시험대비덤프 🧝 Databricks-Certified-Data-Analyst-Associate최고품질 덤프공부자료 ☕ “ www.itdumpskr.com ”을(를) 열고⏩ Databricks-Certified-Data-Analyst-Associate ⏪를 입력하고 무료 다운로드를 받으십시오Databricks-Certified-Data-Analyst-Associate적중율 높은 시험대비덤프
- Databricks-Certified-Data-Analyst-Associate인증시험대비 덤프공부 시험준비에 가장 좋은 시험대비 덤프공부자료 🐾 검색만 하면✔ www.itdumpskr.com ️✔️에서▶ Databricks-Certified-Data-Analyst-Associate ◀무료 다운로드Databricks-Certified-Data-Analyst-Associate합격보장 가능 시험
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
BONUS!!! ITDumpsKR Databricks-Certified-Data-Analyst-Associate 시험 문제집 전체 버전을 무료로 다운로드하세요: https://drive.google.com/open?id=1S6CwycQNLa-1jxl4IY9U3wUItrTX_n5z